|
|
@@ -2,68 +2,41 @@
|
|
|
|
|
|
Run Stable Diffusion on your machine with a nice UI without any hassle!
|
|
|
|
|
|
-
|
|
|
## Setup & Usage
|
|
|
|
|
|
Visit the wiki for [Setup](https://github.com/AbdBarho/stable-diffusion-webui-docker/wiki/Setup) and [Usage](https://github.com/AbdBarho/stable-diffusion-webui-docker/wiki/Usage) instructions, checkout the [FAQ](https://github.com/AbdBarho/stable-diffusion-webui-docker/wiki/FAQ) page if you face any problems, or create a new issue!
|
|
|
|
|
|
-
|
|
|
-## Contributing
|
|
|
-
|
|
|
-Contributions are welcome! **Create a discussion first of what the problem is and what you want to contribute (before you implement anything)**
|
|
|
## Features
|
|
|
|
|
|
This repository provides multiple UIs for you to play around with stable diffusion:
|
|
|
|
|
|
-### AUTOMATIC1111
|
|
|
+### [AUTOMATIC1111](https://github.com/AUTOMATIC1111/stable-diffusion-webui)
|
|
|
|
|
|
-[AUTOMATIC1111's fork](https://github.com/AUTOMATIC1111/stable-diffusion-webui) is imho the most feature rich yet elegant UI:
|
|
|
-
|
|
|
-- Text to image, with many samplers and even negative prompts!
|
|
|
-- Image to image, with masking, cropping, in-painting, out-painting, variations.
|
|
|
-- GFPGAN, RealESRGAN, LDSR, CodeFormer.
|
|
|
-- Loopback, prompt weighting, prompt matrix, X/Y plot
|
|
|
-- Live preview of the generated images.
|
|
|
-- Highly optimized 4GB GPU support, or even CPU only!
|
|
|
-- Textual inversion allows you to use pretrained textual inversion embeddings
|
|
|
-- [Full feature list here](https://github.com/AUTOMATIC1111/stable-diffusion-webui-feature-showcase)
|
|
|
+[Full feature list here](https://github.com/AUTOMATIC1111/stable-diffusion-webui-feature-showcase), Screenshots:
|
|
|
|
|
|
| Text to image | Image to image | Extras |
|
|
|
| ---------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------- |
|
|
|
|  |  | 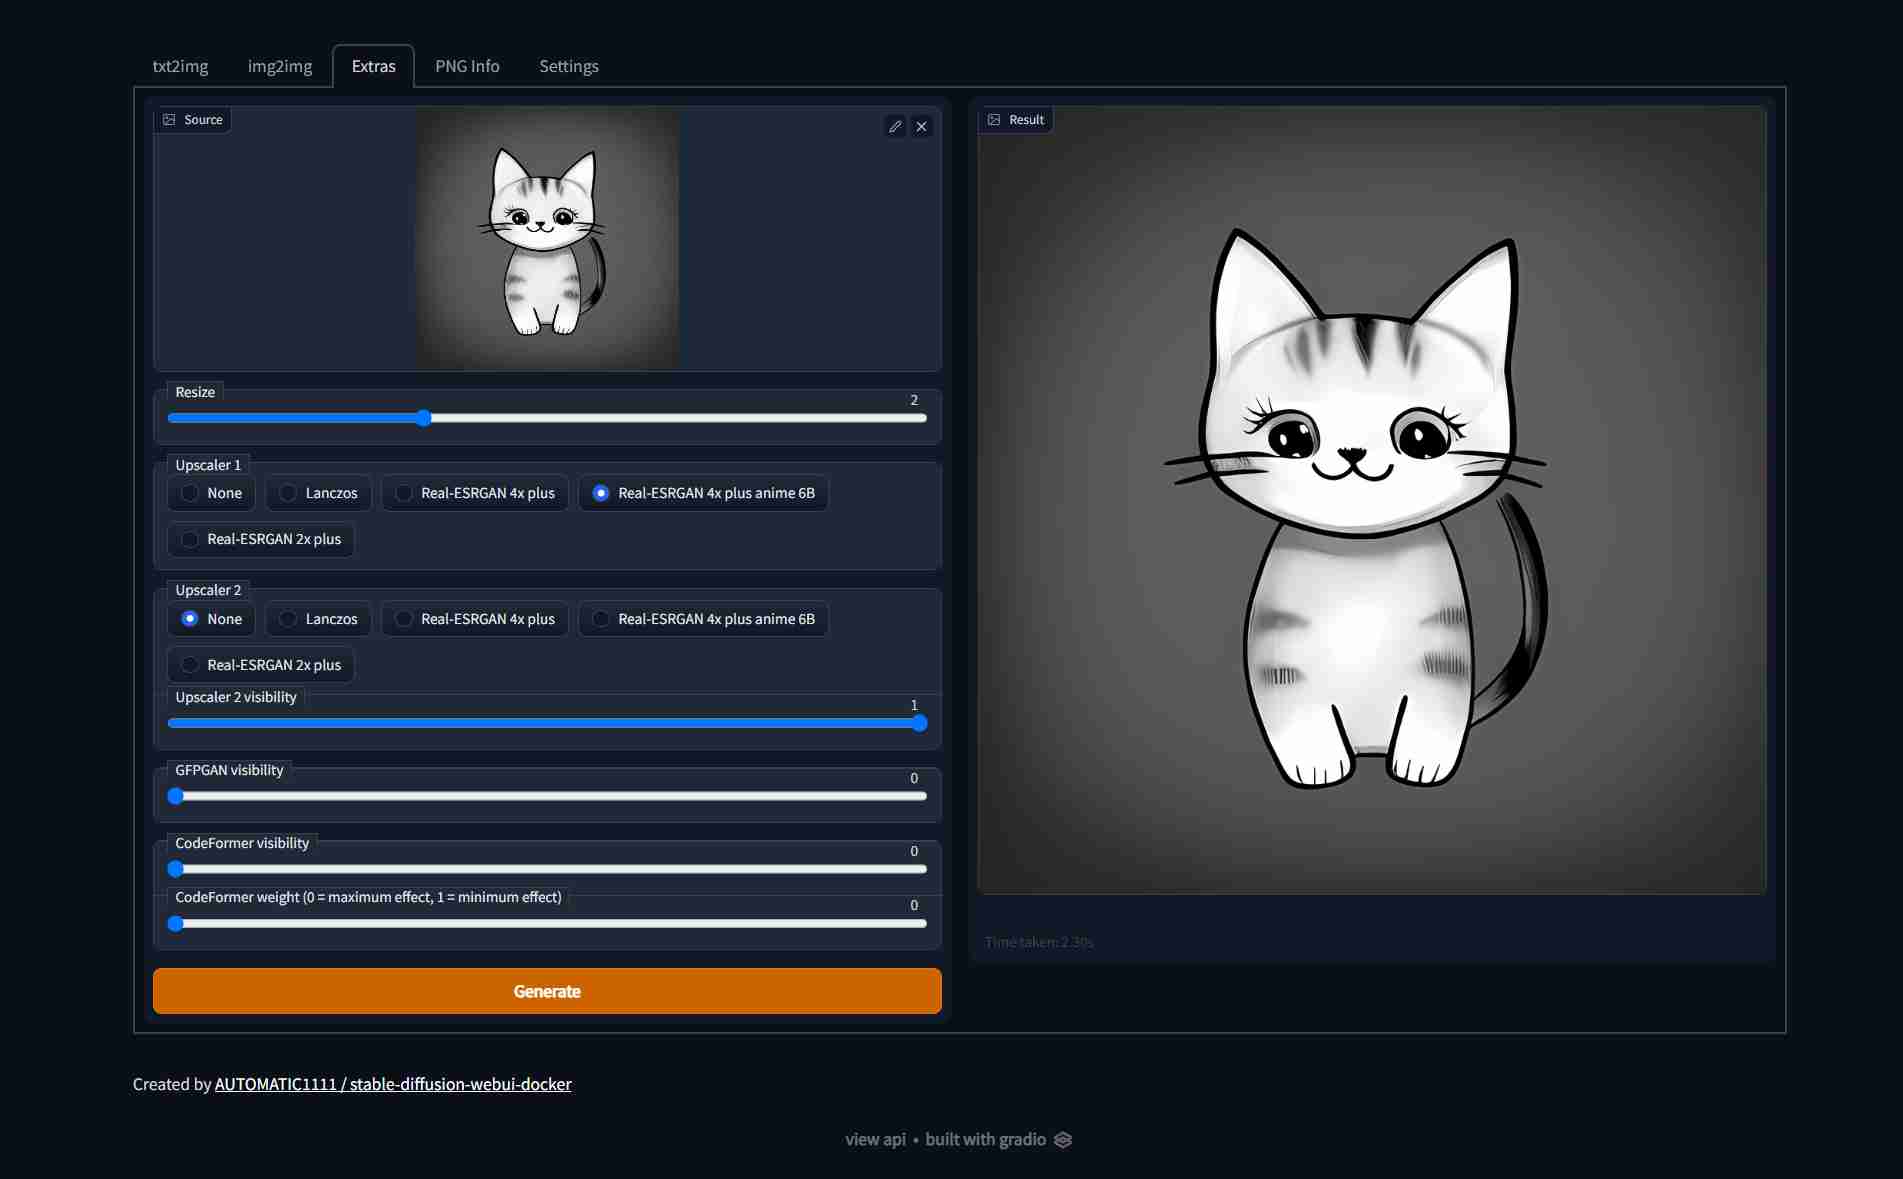 |
|
|
|
|
|
|
-### hlky (sd-webui / sygil-webui)
|
|
|
+### [InvokeAI (lstein)](https://github.com/invoke-ai/InvokeAI)
|
|
|
+
|
|
|
+[Full feature list here](https://github.com/invoke-ai/InvokeAI#features), Screenshots:
|
|
|
|
|
|
-[hlky's fork](https://github.com/Sygil-Dev/sygil-webui) is one of the most popular UIs, with many features:
|
|
|
+| Text to image | Image to image | Extras |
|
|
|
+| ---------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------- |
|
|
|
+|  |  |  |
|
|
|
|
|
|
-- Text to image, with many samplers
|
|
|
-- Image to image, with masking, cropping, in-painting, variations.
|
|
|
-- GFPGAN, RealESRGAN, LDSR, GoBig, GoLatent
|
|
|
-- Loopback, prompt weighting
|
|
|
-- 6GB or even 4GB GPU support!
|
|
|
-- [Full feature list here](https://github.com/Sygil-Dev/sygil-webui/blob/master/README.md)
|
|
|
+### [Sygil (sd-webui / hlky)](https://github.com/Sygil-Dev/sygil-webui)
|
|
|
|
|
|
-Screenshots:
|
|
|
+[Full feature list here](https://github.com/Sygil-Dev/sygil-webui/blob/master/README.md), Screenshots:
|
|
|
|
|
|
| Text to image | Image to image | Image Lab |
|
|
|
| ---------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------- |
|
|
|
|  |  | 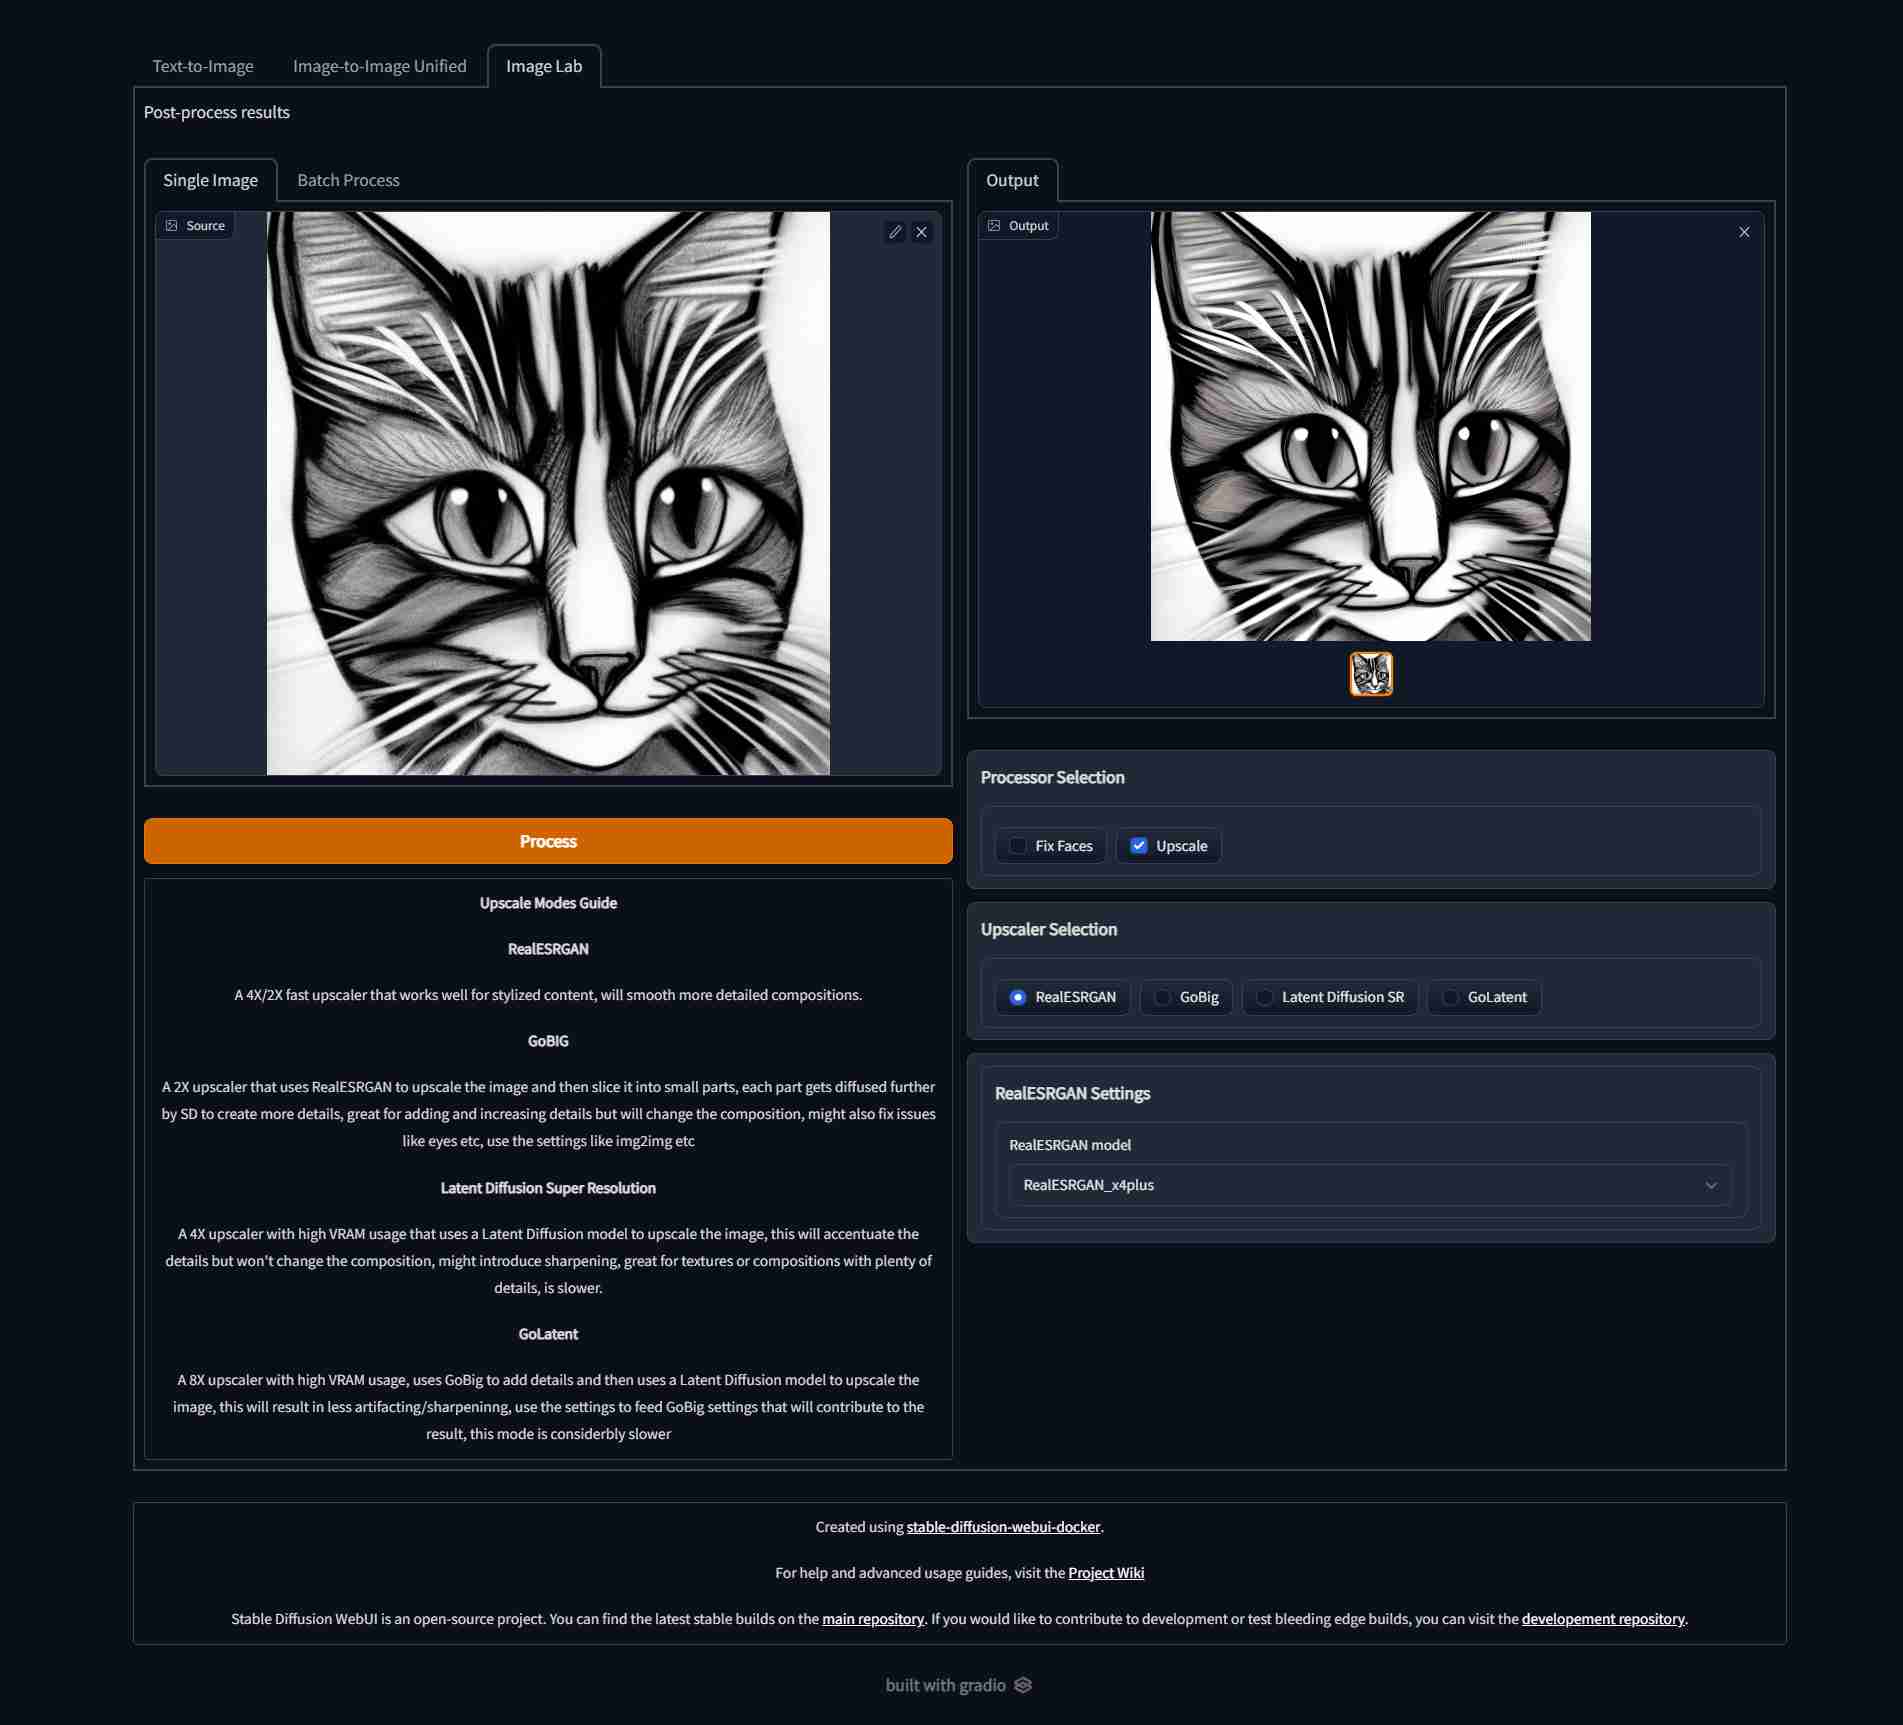 |
|
|
|
|
|
|
+## Contributing
|
|
|
|
|
|
-
|
|
|
-### lstein (InvokeAI)
|
|
|
-
|
|
|
-[lstein's fork](https://github.com/invoke-ai/InvokeAI) is one of the earliest with a wonderful WebUI.
|
|
|
-- Text to image, with many samplers
|
|
|
-- Image to image
|
|
|
-- 4GB GPU support
|
|
|
-- More coming!
|
|
|
-- [Full feature list here](https://github.com/invoke-ai/InvokeAI#features)
|
|
|
-
|
|
|
-| Text to image | Image to image | Extras |
|
|
|
-| ---------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------- |
|
|
|
-|  |  |  |
|
|
|
-
|
|
|
+Contributions are welcome! **Create a discussion first of what the problem is and what you want to contribute (before you implement anything)**
|
|
|
|
|
|
## Disclaimer
|
|
|
|
|
|
@@ -75,10 +48,8 @@ This license of this software forbids you from sharing any content that violates
|
|
|
|
|
|
Special thanks to everyone behind these awesome projects, without them, none of this would have been possible:
|
|
|
|
|
|
-- [hlky/stable-diffusion-webui](https://github.com/hlky/stable-diffusion-webui)
|
|
|
- [AUTOMATIC1111/stable-diffusion-webui](https://github.com/AUTOMATIC1111/stable-diffusion-webui)
|
|
|
-- [lstein/stable-diffusion](https://github.com/lstein/stable-diffusion)
|
|
|
+- [InvokeAI](https://github.com/invoke-ai/InvokeAI)
|
|
|
+- [Sygil-webui](https://github.com/Sygil-Dev/sygil-webui)
|
|
|
- [CompVis/stable-diffusion](https://github.com/CompVis/stable-diffusion)
|
|
|
-- [hlky/sd-enable-textual-inversion](https://github.com/hlky/sd-enable-textual-inversion)
|
|
|
-- [devilismyfriend/latent-diffusion](https://github.com/devilismyfriend/latent-diffusion)
|
|
|
-- [Hafiidz/latent-diffusion](https://github.com/Hafiidz/latent-diffusion)
|
|
|
+- and many many more.
|

 AbdBarho