|
@@ -1,4 +1,23 @@
|
|
|
# Latent Diffusion Models
|
|
# Latent Diffusion Models
|
|
|
|
|
+[arXiv](https://arxiv.org/abs/2112.10752) | [BibTeX](#bibtex)
|
|
|
|
|
+
|
|
|
|
|
+<p align="center">
|
|
|
|
|
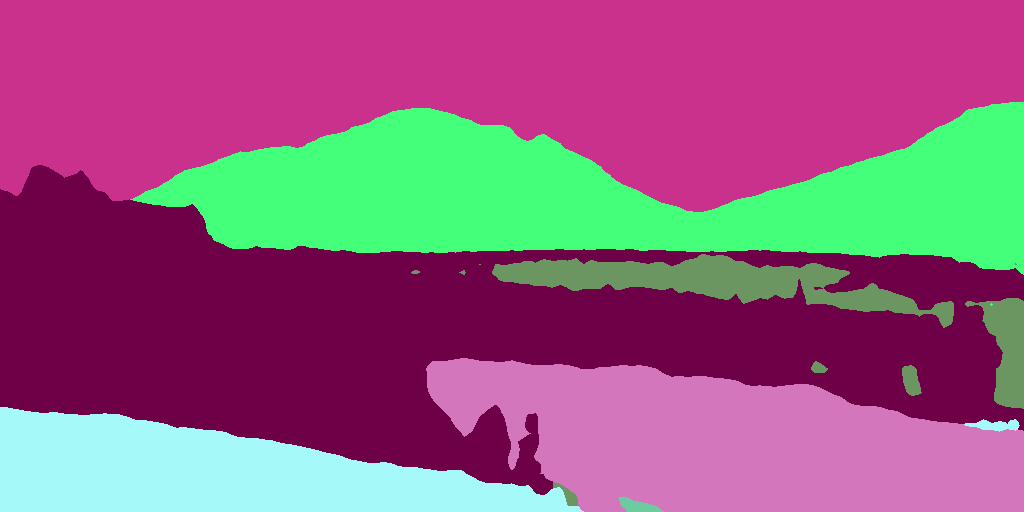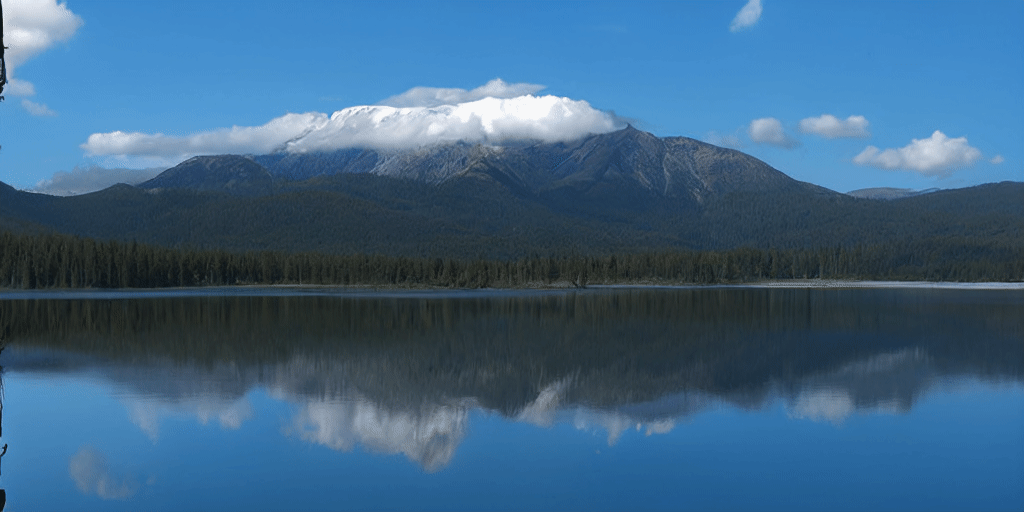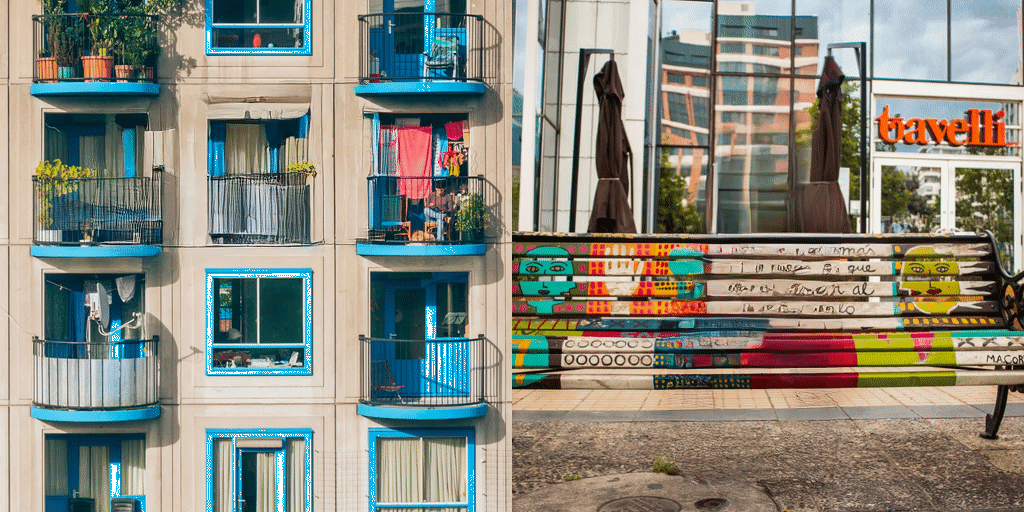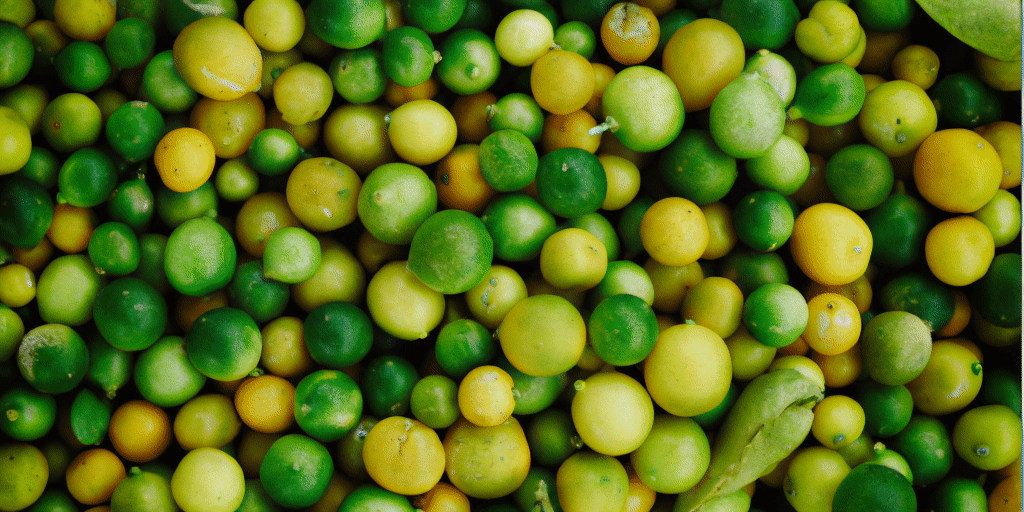
+<img src=assets/results.gif />
|
|
|
|
|
+</p>
|
|
|
|
|
+
|
|
|
|
|
+
|
|
|
|
|
+
|
|
|
|
|
+[**High-Resolution Image Synthesis with Latent Diffusion Models**](https://arxiv.org/abs/2112.10752)<br/>
|
|
|
|
|
+[Robin Rombach](https://github.com/rromb)\*,
|
|
|
|
|
+[Andreas Blattmann](https://github.com/ablattmann)\*,
|
|
|
|
|
+[Dominik Lorenz](https://github.com/qp-qp)\,
|
|
|
|
|
+[Patrick Esser](https://github.com/pesser),
|
|
|
|
|
+[Björn Ommer](https://hci.iwr.uni-heidelberg.de/Staff/bommer)<br/>
|
|
|
|
|
+\* equal contribution
|
|
|
|
|
+
|
|
|
|
|
+<p align="center">
|
|
|
|
|
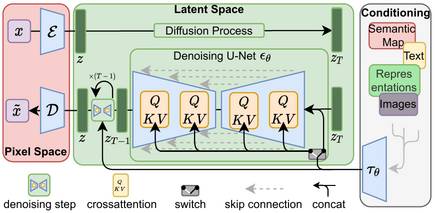
+<img src=assets/modelfigure.png />
|
|
|
|
|
+</p>
|
|
|
|
|
|
|
|
## Requirements
|
|
## Requirements
|
|
|
A suitable [conda](https://conda.io/) environment named `ldm` can be created
|
|
A suitable [conda](https://conda.io/) environment named `ldm` can be created
|
|
@@ -31,12 +50,24 @@ conda activate ldm
|
|
|
### Get the models
|
|
### Get the models
|
|
|
|
|
|
|
|
Running the following script downloads und extracts all available pretrained autoencoding models.
|
|
Running the following script downloads und extracts all available pretrained autoencoding models.
|
|
|
-
|
|
|
|
|
```shell script
|
|
```shell script
|
|
|
bash scripts/download_first_stages.sh
|
|
bash scripts/download_first_stages.sh
|
|
|
```
|
|
```
|
|
|
|
|
|
|
|
The first stage models can then be found in `models/first_stage_models/<model_spec>`
|
|
The first stage models can then be found in `models/first_stage_models/<model_spec>`
|
|
|
|
|
+### Training autoencoder models
|
|
|
|
|
+
|
|
|
|
|
+Configs for training a KL-regularized autoencoder on ImageNet are provided at `configs/autoencoder`.
|
|
|
|
|
+Training can be started by running
|
|
|
|
|
+```
|
|
|
|
|
+CUDA_VISIBLE_DEVICES=<GPU_ID> python main.py --base configs/autoencoder/<config_spec> -t --gpus 0,
|
|
|
|
|
+```
|
|
|
|
|
+where `config_spec` is one of {`autoencoder_kl_8x8x64.yaml`(f=32, d=64), `autoencoder_kl_16x16x16.yaml`(f=16, d=16),
|
|
|
|
|
+`autoencoder_kl_32x32x4`(f=8, d=4), `autoencoder_kl_64x64x3`(f=4, d=3)}.
|
|
|
|
|
+
|
|
|
|
|
+For training VQ-regularized models, see the [taming-transformers](https://github.com/CompVis/taming-transformers)
|
|
|
|
|
+repository.
|
|
|
|
|
+
|
|
|
|
|
|
|
|
## Pretrained LDMs
|
|
## Pretrained LDMs
|
|
|
| Datset | Task | Model | FID | IS | Prec | Recall | Link | Comments
|
|
| Datset | Task | Model | FID | IS | Prec | Recall | Link | Comments
|
|
@@ -102,4 +133,17 @@ Thanks for open-sourcing!
|
|
|
- The implementation of the transformer encoder is from [x-transformers](https://github.com/lucidrains/x-transformers) by [lucidrains](https://github.com/lucidrains?tab=repositories).
|
|
- The implementation of the transformer encoder is from [x-transformers](https://github.com/lucidrains/x-transformers) by [lucidrains](https://github.com/lucidrains?tab=repositories).
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
+## BibTeX
|
|
|
|
|
+
|
|
|
|
|
+```
|
|
|
|
|
+@misc{rombach2021highresolution,
|
|
|
|
|
+ title={High-Resolution Image Synthesis with Latent Diffusion Models},
|
|
|
|
|
+ author={Robin Rombach and Andreas Blattmann and Dominik Lorenz and Patrick Esser and Björn Ommer},
|
|
|
|
|
+ year={2021},
|
|
|
|
|
+ eprint={2112.10752},
|
|
|
|
|
+ archivePrefix={arXiv},
|
|
|
|
|
+ primaryClass={cs.CV}
|
|
|
|
|
+}
|
|
|
|
|
+```
|
|
|
|
|
+
|
|
|
|
|
|