ablattmann před 4 roky
rodič
revize
e66308c7f2
87 změnil soubory, kde provedl 12794 přidání a 3 odebrání
  1. 103 3
      README.md
  2. binární
      assets/inpainting.png
  3. binární
      assets/reconstruction1.png
  4. binární
      assets/reconstruction2.png
  5. 54 0
      configs/autoencoder/autoencoder_kl_16x16x16.yaml
  6. 53 0
      configs/autoencoder/autoencoder_kl_32x32x4.yaml
  7. 54 0
      configs/autoencoder/autoencoder_kl_64x64x3.yaml
  8. 53 0
      configs/autoencoder/autoencoder_kl_8x8x64.yaml
  9. 95 0
      configs/latent-diffusion/lsun_churches_f8-autoencoder-ldm.yaml
  10. binární
      data/DejaVuSans.ttf
  11. binární
      data/example_conditioning/superresolution/sample_0.jpg
  12. 1 0
      data/example_conditioning/text_conditional/sample_0.txt
  13. binární
      data/imagenet_train_hr_indices.p
  14. binární
      data/imagenet_val_hr_indices.p
  15. 1000 0
      data/index_synset.yaml
  16. binární
      data/inpainting_examples/6458524847_2f4c361183_k.png
  17. binární
      data/inpainting_examples/6458524847_2f4c361183_k_mask.png
  18. binární
      data/inpainting_examples/8399166846_f6fb4e4b8e_k.png
  19. binární
      data/inpainting_examples/8399166846_f6fb4e4b8e_k_mask.png
  20. binární
      data/inpainting_examples/alex-iby-G_Pk4D9rMLs.png
  21. binární
      data/inpainting_examples/alex-iby-G_Pk4D9rMLs_mask.png
  22. binární
      data/inpainting_examples/bench2.png
  23. binární
      data/inpainting_examples/bench2_mask.png
  24. binární
      data/inpainting_examples/bertrand-gabioud-CpuFzIsHYJ0.png
  25. binární
      data/inpainting_examples/bertrand-gabioud-CpuFzIsHYJ0_mask.png
  26. binární
      data/inpainting_examples/billow926-12-Wc-Zgx6Y.png
  27. binární
      data/inpainting_examples/billow926-12-Wc-Zgx6Y_mask.png
  28. binární
      data/inpainting_examples/overture-creations-5sI6fQgYIuo.png
  29. binární
      data/inpainting_examples/overture-creations-5sI6fQgYIuo_mask.png
  30. binární
      data/inpainting_examples/photo-1583445095369-9c651e7e5d34.png
  31. binární
      data/inpainting_examples/photo-1583445095369-9c651e7e5d34_mask.png
  32. 27 0
      environment.yaml
  33. 0 0
      ldm/data/__init__.py
  34. 23 0
      ldm/data/base.py
  35. 394 0
      ldm/data/imagenet.py
  36. 92 0
      ldm/data/lsun.py
  37. 98 0
      ldm/lr_scheduler.py
  38. 443 0
      ldm/models/autoencoder.py
  39. 0 0
      ldm/models/diffusion/__init__.py
  40. 267 0
      ldm/models/diffusion/classifier.py
  41. 186 0
      ldm/models/diffusion/ddim.py
  42. 1430 0
      ldm/models/diffusion/ddpm.py
  43. 261 0
      ldm/modules/attention.py
  44. 0 0
      ldm/modules/diffusionmodules/__init__.py
  45. 835 0
      ldm/modules/diffusionmodules/model.py
  46. 936 0
      ldm/modules/diffusionmodules/openaimodel.py
  47. 261 0
      ldm/modules/diffusionmodules/util.py
  48. 0 0
      ldm/modules/distributions/__init__.py
  49. 92 0
      ldm/modules/distributions/distributions.py
  50. 76 0
      ldm/modules/ema.py
  51. 0 0
      ldm/modules/encoders/__init__.py
  52. 131 0
      ldm/modules/encoders/modules.py
  53. 2 0
      ldm/modules/image_degradation/__init__.py
  54. 730 0
      ldm/modules/image_degradation/bsrgan.py
  55. 650 0
      ldm/modules/image_degradation/bsrgan_light.py
  56. binární
      ldm/modules/image_degradation/utils/test.png
  57. 916 0
      ldm/modules/image_degradation/utils_image.py
  58. 1 0
      ldm/modules/losses/__init__.py
  59. 111 0
      ldm/modules/losses/contperceptual.py
  60. 641 0
      ldm/modules/x_transformer.py
  61. 86 0
      ldm/util.py
  62. 738 0
      main.py
  63. 44 0
      models/first_stage_models/kl-f16/config.yaml
  64. 46 0
      models/first_stage_models/kl-f32/config.yaml
  65. 41 0
      models/first_stage_models/kl-f4/config.yaml
  66. 42 0
      models/first_stage_models/kl-f8/config.yaml
  67. 49 0
      models/first_stage_models/vq-f16/config.yaml
  68. 46 0
      models/first_stage_models/vq-f4-noattn/config.yaml
  69. 45 0
      models/first_stage_models/vq-f4/config.yaml
  70. 48 0
      models/first_stage_models/vq-f8-n256/config.yaml
  71. 48 0
      models/first_stage_models/vq-f8/config.yaml
  72. 80 0
      models/ldm/bsr_sr/config.yaml
  73. 70 0
      models/ldm/celeba256/config.yaml
  74. 80 0
      models/ldm/cin256/config.yaml
  75. 70 0
      models/ldm/ffhq256/config.yaml
  76. 67 0
      models/ldm/inpainting_big/config.yaml
  77. 81 0
      models/ldm/layout2img-openimages256/config.yaml
  78. 70 0
      models/ldm/lsun_beds256/config.yaml
  79. 92 0
      models/ldm/lsun_churches256/config.yaml
  80. 78 0
      models/ldm/semantic_synthesis512/config.yaml
  81. 77 0
      models/ldm/text2img256/config.yaml
  82. 270 0
      notebook_helpers.py
  83. 41 0
      scripts/download_first_stages.sh
  84. 45 0
      scripts/download_models.sh
  85. 98 0
      scripts/inpaint.py
  86. 313 0
      scripts/sample_diffusion.py
  87. 13 0
      setup.py

+ 103 - 3
README.md

@@ -1,4 +1,104 @@
-# latent-diffusion
-High-Resolution Image Synthesis with Latent Diffusion Models
+# Latent Diffusion Models
+
+## Requirements
+A suitable [conda](https://conda.io/) environment named `ldm` can be created
+and activated with:
+
+```
+conda env create -f environment.yaml
+conda activate ldm
+```
+
+# Model Zoo 
+
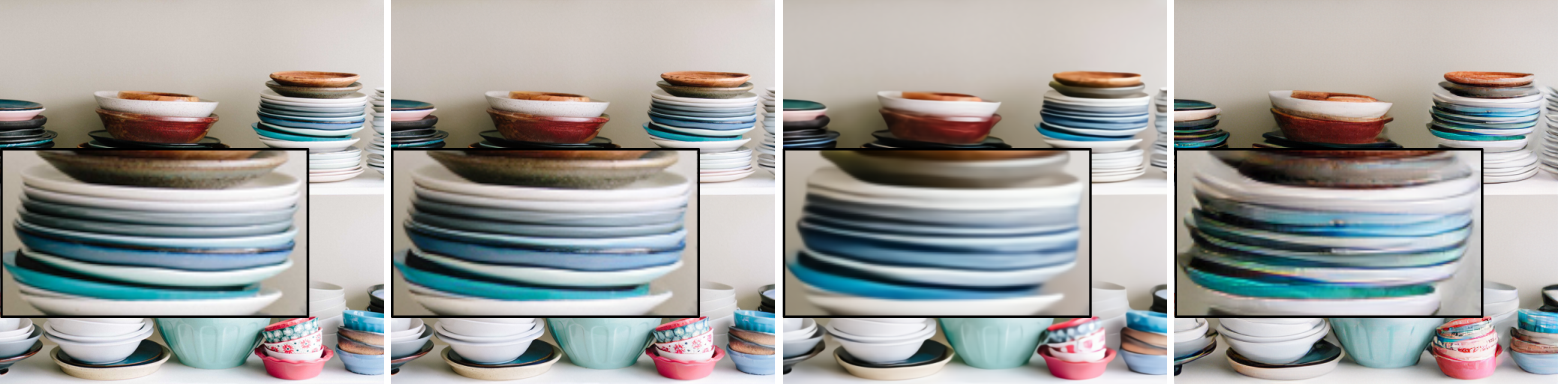
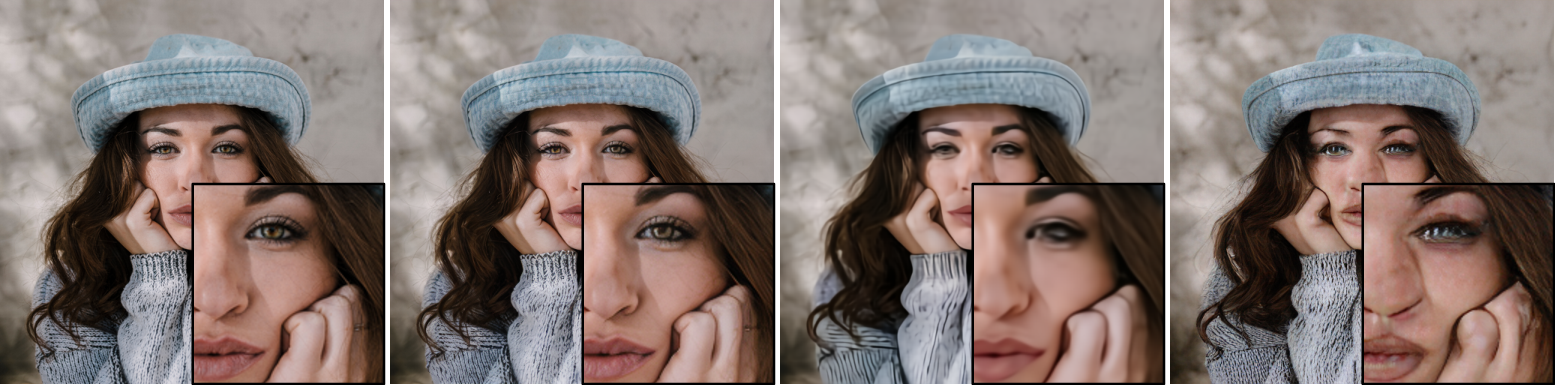
+## Pretrained Autoencoding Models
+![rec2](assets/reconstruction2.png)
+
+
+| Model                   | FID vs val | PSNR           | PSIM          | Link                                                                                                                                                  | Comments              
+|-------------------------|------------|----------------|---------------|-------------------------------------------------------------------------------------------------------------------------------------------------------|-----------------------|
+| f=4, VQ (Z=8192, d=3)   | 0.58       | 27.43  +/- 4.26 | 0.53 +/- 0.21 |     https://ommer-lab.com/files/latent-diffusion/vq-f4.zip                   |  |
+| f=4, VQ (Z=8192, d=3)   | 1.06       | 25.21 +/-  4.17 | 0.72 +/- 0.26 | https://heibox.uni-heidelberg.de/f/9c6681f64bb94338a069/?dl=1  | no attention          |
+| f=8, VQ (Z=16384, d=4)  | 1.14       | 23.07 +/- 3.99 | 1.17 +/- 0.36 |       https://ommer-lab.com/files/latent-diffusion/vq-f8.zip                     |                       |
+| f=8, VQ (Z=256, d=4)    | 1.49       | 22.35 +/- 3.81 | 1.26 +/- 0.37 |   https://ommer-lab.com/files/latent-diffusion/vq-f8-n256.zip |  
+| f=16, VQ (Z=16384, d=8) | 5.15       | 20.83 +/- 3.61 | 1.73 +/- 0.43 |             https://heibox.uni-heidelberg.de/f/0e42b04e2e904890a9b6/?dl=1                        |                       |
+|                         |            |                |               |                                                                                                                                                    |                       |
+| f=4, KL                 | 0.27       | 27.53 +/- 4.54 | 0.55 +/- 0.24 |     https://ommer-lab.com/files/latent-diffusion/kl-f4.zip                                   |                       |
+| f=8, KL                 | 0.90       | 24.19 +/- 4.19 | 1.02 +/- 0.35 |             https://ommer-lab.com/files/latent-diffusion/kl-f8.zip                            |                       |
+| f=16, KL     (d=16)     | 0.87       | 24.08 +/- 4.22 | 1.07 +/- 0.36 |      https://ommer-lab.com/files/latent-diffusion/kl-f16.zip                                  |                       |
+ | f=32, KL     (d=64)     | 2.04       | 22.27 +/- 3.93 | 1.41 +/- 0.40 |             https://ommer-lab.com/files/latent-diffusion/kl-f32.zip                            |                       |
+
+### Get the models
+
+Running the following script downloads und extracts all available pretrained autoencoding models.   
+
+```shell script
+bash scripts/download_first_stages.sh
+```
+
+The first stage models can then be found in `models/first_stage_models/<model_spec>`
+
+## Pretrained LDMs
+| Datset                          |   Task    | Model        | FID           | IS              | Prec | Recall | Link                                                                                                                                                                                   | Comments                                        
+|---------------------------------|------|--------------|---------------|-----------------|------|------|----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|-------------------------------------------------|
+| CelebA-HQ                       | Unconditional Image Synthesis    |  LDM-VQ-4 (200 DDIM steps, eta=0)| 5.11 (5.11)          | 3.29            | 0.72    | 0.49 |    https://ommer-lab.com/files/latent-diffusion/celeba.zip     |                                                 |  
+| FFHQ                            | Unconditional Image Synthesis    |  LDM-VQ-4 (200 DDIM steps, eta=1)| 4.98 (4.98)  | 4.50 (4.50)   | 0.73 | 0.50 |              https://ommer-lab.com/files/latent-diffusion/ffhq.zip                                              |                                                 |
+| LSUN-Churches                   | Unconditional Image Synthesis   |  LDM-KL-8 (400 DDIM steps, eta=0)| 4.02 (4.02) | 2.72 | 0.64 | 0.52 |         https://ommer-lab.com/files/latent-diffusion/lsun_churches.zip        |                                                 |  
+| LSUN-Bedrooms                   | Unconditional Image Synthesis   |  LDM-VQ-4 (200 DDIM steps, eta=1)| 2.95 (3.0)          | 2.22 (2.23)| 0.66 | 0.48 | https://ommer-lab.com/files/latent-diffusion/lsun_bedrooms.zip |                                                 |  
+| ImageNet                        | Class-conditional Image Synthesis | LDM-VQ-8 (200 DDIM steps, eta=1) | 7.77(7.76)* /15.82** | 201.56(209.52)* /78.82** | 0.84* / 0.65** | 0.35* / 0.63** |   https://ommer-lab.com/files/latent-diffusion/cin.zip                                                                   | *: w/ guiding, classifier_scale 10  **: w/o guiding, scores in bracket calculated with script provided by [ADM](https://github.com/openai/guided-diffusion) |   
+| Conceptual Captions             |  Text-conditional Image Synthesis | LDM-VQ-f4 (100 DDIM steps, eta=0) | 16.79         | 13.89           | N/A | N/A |              https://ommer-lab.com/files/latent-diffusion/text2img.zip                                | finetuned from LAION                            |   
+| OpenImages                      | Super-resolution   | N/A           | N/A            | N/A               | N/A    | N/A    |                                    https://ommer-lab.com/files/latent-diffusion/sr_bsr.zip                                    | BSR image degradation                           |
+| OpenImages                      | Layout-to-Image Synthesis    | LDM-VQ-4 (200 DDIM steps, eta=0) | 32.02         | 15.92           | N/A    | N/A    |                  https://ommer-lab.com/files/latent-diffusion/layout2img_model.zip                                           |                                                 | 
+| Landscapes      (finetuned 512) |  Semantic Image Synthesis   | LDM-VQ-4 (100 DDIM steps, eta=1) | N/A             | N/A               | N/A    | N/A    |           https://ommer-lab.com/files/latent-diffusion/semantic_synthesis.zip                                    |                                                 |
+
+
+### Get the models
+
+The LDMs listed above can jointly be downloaded and extracted via
+
+```shell script
+bash scripts/download_models.sh
+```
+
+The models can then be found in `models/ldm/<model_spec>`.
+
+### Sampling with unconditional models
+
+We provide a first script for sampling from our unconditional models. Start it via
+
+```shell script
+CUDA_VISIBLE_DEVICES=<GPU_ID> python scripts/sample_diffusion.py -r models/ldm/<model_spec>/model.ckpt -l <logdir> -n <\#samples> --batch_size <batch_size> -c <\#ddim steps> -e <\#eta> 
+```
+
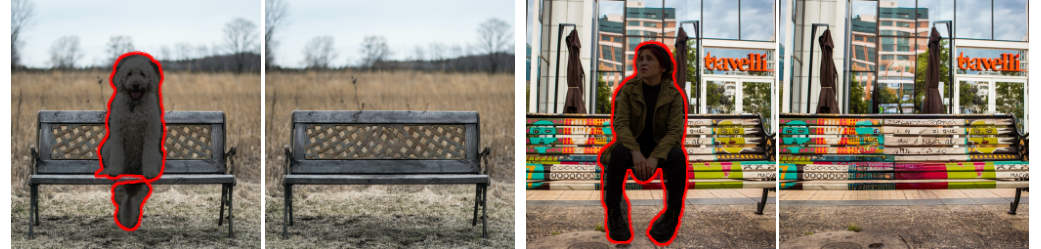
+# Inpainting
+![inpainting](assets/inpainting.png)
+
+Download the pre-trained weights
+```
+wget XXX
+```
+
+and sample with
+```
+python scripts/inpaint.py --indir data/inpainting_examples/ --outdir outputs/inpainting_results
+```
+`indir` should contain images `*.png` and masks `<image_fname>_mask.png` like
+the examples provided in `data/inpainting_examples`.
+
+
+## Comin Soon...
+
+* Code for training LDMs and the corresponding compression models.
+* Inference scripts for conditional LDMs for various conditioning modalities.
+* In the meantime, you can play with our colab notebook https://colab.research.google.com/drive/1xqzUi2iXQXDqXBHQGP9Mqt2YrYW6cx-J?usp=sharing
+* We will also release some further pretrained models.
+## Comments 
+
+- Our codebase for the diffusion models builds heavily on [OpenAI's codebase](https://github.com/openai/guided-diffusion)
+and [https://github.com/lucidrains/denoising-diffusion-pytorch](https://github.com/lucidrains/denoising-diffusion-pytorch). 
+Thanks for open-sourcing!
+
+- The implementation of the transformer encoder is from [x-transformers](https://github.com/lucidrains/x-transformers) by [lucidrains](https://github.com/lucidrains?tab=repositories). 
+
+
 
-...coming soon™

binární
assets/inpainting.png


binární
assets/reconstruction1.png


binární
assets/reconstruction2.png

+ 54 - 0
configs/autoencoder/autoencoder_kl_16x16x16.yaml

@@ -0,0 +1,54 @@
+model:
+  base_learning_rate: 4.5e-6
+  target: ldm.models.autoencoder.AutoencoderKL
+  params:
+    monitor: "val/rec_loss"
+    embed_dim: 16
+    lossconfig:
+      target: ldm.modules.losses.LPIPSWithDiscriminator
+      params:
+        disc_start: 50001
+        kl_weight: 0.000001
+        disc_weight: 0.5
+
+    ddconfig:
+      double_z: True
+      z_channels: 16
+      resolution: 256
+      in_channels: 3
+      out_ch: 3
+      ch: 128
+      ch_mult: [ 1,1,2,2,4]  # num_down = len(ch_mult)-1
+      num_res_blocks: 2
+      attn_resolutions: [16]
+      dropout: 0.0
+
+
+data:
+  target: main.DataModuleFromConfig
+  params:
+    batch_size: 12
+    wrap: True
+    train:
+      target: ldm.data.imagenet.ImageNetSRTrain
+      params:
+        size: 256
+        degradation: pil_nearest
+    validation:
+      target: ldm.data.imagenet.ImageNetSRValidation
+      params:
+        size: 256
+        degradation: pil_nearest
+
+lightning:
+  callbacks:
+    image_logger:
+      target: main.ImageLogger
+      params:
+        batch_frequency: 1000
+        max_images: 8
+        increase_log_steps: True
+
+  trainer:
+    benchmark: True
+    accumulate_grad_batches: 2

+ 53 - 0
configs/autoencoder/autoencoder_kl_32x32x4.yaml

@@ -0,0 +1,53 @@
+model:
+  base_learning_rate: 4.5e-6
+  target: ldm.models.autoencoder.AutoencoderKL
+  params:
+    monitor: "val/rec_loss"
+    embed_dim: 4
+    lossconfig:
+      target: ldm.modules.losses.LPIPSWithDiscriminator
+      params:
+        disc_start: 50001
+        kl_weight: 0.000001
+        disc_weight: 0.5
+
+    ddconfig:
+      double_z: True
+      z_channels: 4
+      resolution: 256
+      in_channels: 3
+      out_ch: 3
+      ch: 128
+      ch_mult: [ 1,2,4,4 ]  # num_down = len(ch_mult)-1
+      num_res_blocks: 2
+      attn_resolutions: [ ]
+      dropout: 0.0
+
+data:
+  target: main.DataModuleFromConfig
+  params:
+    batch_size: 12
+    wrap: True
+    train:
+      target: ldm.data.imagenet.ImageNetSRTrain
+      params:
+        size: 256
+        degradation: pil_nearest
+    validation:
+      target: ldm.data.imagenet.ImageNetSRValidation
+      params:
+        size: 256
+        degradation: pil_nearest
+
+lightning:
+  callbacks:
+    image_logger:
+      target: main.ImageLogger
+      params:
+        batch_frequency: 1000
+        max_images: 8
+        increase_log_steps: True
+
+  trainer:
+    benchmark: True
+    accumulate_grad_batches: 2

+ 54 - 0
configs/autoencoder/autoencoder_kl_64x64x3.yaml

@@ -0,0 +1,54 @@
+model:
+  base_learning_rate: 4.5e-6
+  target: ldm.models.autoencoder.AutoencoderKL
+  params:
+    monitor: "val/rec_loss"
+    embed_dim: 3
+    lossconfig:
+      target: ldm.modules.losses.LPIPSWithDiscriminator
+      params:
+        disc_start: 50001
+        kl_weight: 0.000001
+        disc_weight: 0.5
+
+    ddconfig:
+      double_z: True
+      z_channels: 3
+      resolution: 256
+      in_channels: 3
+      out_ch: 3
+      ch: 128
+      ch_mult: [ 1,2,4 ]  # num_down = len(ch_mult)-1
+      num_res_blocks: 2
+      attn_resolutions: [ ]
+      dropout: 0.0
+
+
+data:
+  target: main.DataModuleFromConfig
+  params:
+    batch_size: 12
+    wrap: True
+    train:
+      target: ldm.data.imagenet.ImageNetSRTrain
+      params:
+        size: 256
+        degradation: pil_nearest
+    validation:
+      target: ldm.data.imagenet.ImageNetSRValidation
+      params:
+        size: 256
+        degradation: pil_nearest
+
+lightning:
+  callbacks:
+    image_logger:
+      target: main.ImageLogger
+      params:
+        batch_frequency: 1000
+        max_images: 8
+        increase_log_steps: True
+
+  trainer:
+    benchmark: True
+    accumulate_grad_batches: 2

+ 53 - 0
configs/autoencoder/autoencoder_kl_8x8x64.yaml

@@ -0,0 +1,53 @@
+model:
+  base_learning_rate: 4.5e-6
+  target: ldm.models.autoencoder.AutoencoderKL
+  params:
+    monitor: "val/rec_loss"
+    embed_dim: 64
+    lossconfig:
+      target: ldm.modules.losses.LPIPSWithDiscriminator
+      params:
+        disc_start: 50001
+        kl_weight: 0.000001
+        disc_weight: 0.5
+
+    ddconfig:
+      double_z: True
+      z_channels: 64
+      resolution: 256
+      in_channels: 3
+      out_ch: 3
+      ch: 128
+      ch_mult: [ 1,1,2,2,4,4]  # num_down = len(ch_mult)-1
+      num_res_blocks: 2
+      attn_resolutions: [16,8]
+      dropout: 0.0
+
+data:
+  target: main.DataModuleFromConfig
+  params:
+    batch_size: 12
+    wrap: True
+    train:
+      target: ldm.data.imagenet.ImageNetSRTrain
+      params:
+        size: 256
+        degradation: pil_nearest
+    validation:
+      target: ldm.data.imagenet.ImageNetSRValidation
+      params:
+        size: 256
+        degradation: pil_nearest
+
+lightning:
+  callbacks:
+    image_logger:
+      target: main.ImageLogger
+      params:
+        batch_frequency: 1000
+        max_images: 8
+        increase_log_steps: True
+
+  trainer:
+    benchmark: True
+    accumulate_grad_batches: 2

+ 95 - 0
configs/latent-diffusion/lsun_churches_f8-autoencoder-ldm.yaml

@@ -0,0 +1,95 @@
+model:
+  base_learning_rate: 5.0e-5   # set to target_lr by starting main.py with '--scale_lr False'
+  target: ldm.models.diffusion.ddpm.LatentDiffusion
+  params:
+    linear_start: 0.0015
+    linear_end: 0.0155
+    num_timesteps_cond: 1
+    log_every_t: 200
+    timesteps: 1000
+    loss_type: l1
+    first_stage_key: "image"
+    cond_stage_key: "image"
+    image_size: 32
+    channels: 4
+    cond_stage_trainable: False
+    concat_mode: False
+    scale_by_std: True
+    monitor: 'val/loss_simple_ema'
+
+    scheduler_config: # 10000 warmup steps
+      target: ldm.lr_scheduler.LambdaLinearScheduler
+      params:
+        warm_up_steps: [10000]
+        cycle_lengths: [10000000000000]
+        f_start: [1.e-6]
+        f_max: [1.]
+        f_min: [ 1.]
+
+    unet_config:
+      target: ldm.modules.diffusionmodules.openaimodel.UNetModel
+      params:
+        image_size: 32
+        in_channels: 4
+        out_channels: 4
+        model_channels: 192
+        attention_resolutions: [ 1, 2, 4, 8 ]   # 32, 16, 8, 4
+        num_res_blocks: 2
+        channel_mult: [ 1,2,2,4,4 ]  # 32, 16, 8, 4, 2
+        num_heads: 8
+        use_scale_shift_norm: True
+        resblock_updown: True
+
+    first_stage_config:
+      target: ldm.models.autoencoder.AutoencoderKL
+      params:
+        embed_dim: 4
+        monitor: "val/rec_loss"
+        ckpt_path: "/export/compvis-nfs/user/ablattma/logs/braket/2021-11-26T11-25-56_lsun_churches-convae-f8-ft_from_oi/checkpoints/step=000180071-fidfrechet_inception_distance=2.335.ckpt"
+        ddconfig:
+          double_z: True
+          z_channels: 4
+          resolution: 256
+          in_channels: 3
+          out_ch: 3
+          ch: 128
+          ch_mult: [ 1,2,4,4 ]  # num_down = len(ch_mult)-1
+          num_res_blocks: 2
+          attn_resolutions: [ ]
+          dropout: 0.0
+        lossconfig:
+          target: torch.nn.Identity
+
+    cond_stage_config: "__is_unconditional__"
+
+data:
+  target: main.DataModuleFromConfig
+  params:
+    batch_size: 24  # TODO: was 96 in our experiments
+    num_workers: 5
+    wrap: False
+    train:
+      target: ldm.data.lsun.LSUNChurchesTrain
+      params:
+        size: 256
+    validation:
+      target: ldm.data.lsun.LSUNChurchesValidation
+      params:
+        size: 256
+
+lightning:
+  callbacks:
+    image_logger:
+      target: main.ImageLogger
+      params:
+        batch_frequency: 1000 # TODO 5000
+        max_images: 8
+        increase_log_steps: False
+
+    metrics_over_trainsteps_checkpoint:
+      target: pytorch_lightning.callbacks.ModelCheckpoint
+      params:
+        every_n_train_steps: 20000
+
+  trainer:
+    benchmark: True

binární
data/DejaVuSans.ttf


binární
data/example_conditioning/superresolution/sample_0.jpg


+ 1 - 0
data/example_conditioning/text_conditional/sample_0.txt

@@ -0,0 +1 @@
+A basket of cerries

binární
data/imagenet_train_hr_indices.p


binární
data/imagenet_val_hr_indices.p


+ 1000 - 0
data/index_synset.yaml

@@ -0,0 +1,1000 @@
+0: n01440764
+1: n01443537
+2: n01484850
+3: n01491361
+4: n01494475
+5: n01496331
+6: n01498041
+7: n01514668
+8: n07646067
+9: n01518878
+10: n01530575
+11: n01531178
+12: n01532829
+13: n01534433
+14: n01537544
+15: n01558993
+16: n01560419
+17: n01580077
+18: n01582220
+19: n01592084
+20: n01601694
+21: n13382471
+22: n01614925
+23: n01616318
+24: n01622779
+25: n01629819
+26: n01630670
+27: n01631663
+28: n01632458
+29: n01632777
+30: n01641577
+31: n01644373
+32: n01644900
+33: n01664065
+34: n01665541
+35: n01667114
+36: n01667778
+37: n01669191
+38: n01675722
+39: n01677366
+40: n01682714
+41: n01685808
+42: n01687978
+43: n01688243
+44: n01689811
+45: n01692333
+46: n01693334
+47: n01694178
+48: n01695060
+49: n01697457
+50: n01698640
+51: n01704323
+52: n01728572
+53: n01728920
+54: n01729322
+55: n01729977
+56: n01734418
+57: n01735189
+58: n01737021
+59: n01739381
+60: n01740131
+61: n01742172
+62: n01744401
+63: n01748264
+64: n01749939
+65: n01751748
+66: n01753488
+67: n01755581
+68: n01756291
+69: n01768244
+70: n01770081
+71: n01770393
+72: n01773157
+73: n01773549
+74: n01773797
+75: n01774384
+76: n01774750
+77: n01775062
+78: n04432308
+79: n01784675
+80: n01795545
+81: n01796340
+82: n01797886
+83: n01798484
+84: n01806143
+85: n07647321
+86: n07647496
+87: n01817953
+88: n01818515
+89: n01819313
+90: n01820546
+91: n01824575
+92: n01828970
+93: n01829413
+94: n01833805
+95: n01843065
+96: n01843383
+97: n01847000
+98: n01855032
+99: n07646821
+100: n01860187
+101: n01871265
+102: n01872772
+103: n01873310
+104: n01877812
+105: n01882714
+106: n01883070
+107: n01910747
+108: n01914609
+109: n01917289
+110: n01924916
+111: n01930112
+112: n01943899
+113: n01944390
+114: n13719102
+115: n01950731
+116: n01955084
+117: n01968897
+118: n01978287
+119: n01978455
+120: n01980166
+121: n01981276
+122: n01983481
+123: n01984695
+124: n01985128
+125: n01986214
+126: n01990800
+127: n02002556
+128: n02002724
+129: n02006656
+130: n02007558
+131: n02009229
+132: n02009912
+133: n02011460
+134: n03126707
+135: n02013706
+136: n02017213
+137: n02018207
+138: n02018795
+139: n02025239
+140: n02027492
+141: n02028035
+142: n02033041
+143: n02037110
+144: n02051845
+145: n02056570
+146: n02058221
+147: n02066245
+148: n02071294
+149: n02074367
+150: n02077923
+151: n08742578
+152: n02085782
+153: n02085936
+154: n02086079
+155: n02086240
+156: n02086646
+157: n02086910
+158: n02087046
+159: n02087394
+160: n02088094
+161: n02088238
+162: n02088364
+163: n02088466
+164: n02088632
+165: n02089078
+166: n02089867
+167: n02089973
+168: n02090379
+169: n02090622
+170: n02090721
+171: n02091032
+172: n02091134
+173: n02091244
+174: n02091467
+175: n02091635
+176: n02091831
+177: n02092002
+178: n02092339
+179: n02093256
+180: n02093428
+181: n02093647
+182: n02093754
+183: n02093859
+184: n02093991
+185: n02094114
+186: n02094258
+187: n02094433
+188: n02095314
+189: n02095570
+190: n02095889
+191: n02096051
+192: n02096177
+193: n02096294
+194: n02096437
+195: n02096585
+196: n02097047
+197: n02097130
+198: n02097209
+199: n02097298
+200: n02097474
+201: n02097658
+202: n02098105
+203: n02098286
+204: n02098413
+205: n02099267
+206: n02099429
+207: n02099601
+208: n02099712
+209: n02099849
+210: n02100236
+211: n02100583
+212: n02100735
+213: n02100877
+214: n02101006
+215: n02101388
+216: n02101556
+217: n02102040
+218: n02102177
+219: n02102318
+220: n02102480
+221: n02102973
+222: n02104029
+223: n02104365
+224: n02105056
+225: n02105162
+226: n02105251
+227: n02105412
+228: n02105505
+229: n02105641
+230: n02105855
+231: n02106030
+232: n02106166
+233: n02106382
+234: n02106550
+235: n02106662
+236: n02107142
+237: n02107312
+238: n02107574
+239: n02107683
+240: n02107908
+241: n02108000
+242: n02108089
+243: n02108422
+244: n02108551
+245: n02108915
+246: n02109047
+247: n02109525
+248: n02109961
+249: n02110063
+250: n02110185
+251: n02110341
+252: n02110627
+253: n02110806
+254: n02110958
+255: n02111129
+256: n02111277
+257: n02111500
+258: n02111889
+259: n02112018
+260: n02112137
+261: n02112350
+262: n02112706
+263: n02113023
+264: n02113186
+265: n02113624
+266: n02113712
+267: n02113799
+268: n02113978
+269: n02114367
+270: n02114548
+271: n02114712
+272: n02114855
+273: n02115641
+274: n02115913
+275: n02116738
+276: n02117135
+277: n02119022
+278: n02119789
+279: n02120079
+280: n02120505
+281: n02123045
+282: n02123159
+283: n02123394
+284: n02123597
+285: n02124075
+286: n02125311
+287: n02127052
+288: n02128385
+289: n02128757
+290: n02128925
+291: n02129165
+292: n02129604
+293: n02130308
+294: n02132136
+295: n02133161
+296: n02134084
+297: n02134418
+298: n02137549
+299: n02138441
+300: n02165105
+301: n02165456
+302: n02167151
+303: n02168699
+304: n02169497
+305: n02172182
+306: n02174001
+307: n02177972
+308: n03373237
+309: n07975909
+310: n02219486
+311: n02226429
+312: n02229544
+313: n02231487
+314: n02233338
+315: n02236044
+316: n02256656
+317: n02259212
+318: n02264363
+319: n02268443
+320: n02268853
+321: n02276258
+322: n02277742
+323: n02279972
+324: n02280649
+325: n02281406
+326: n02281787
+327: n02317335
+328: n02319095
+329: n02321529
+330: n02325366
+331: n02326432
+332: n02328150
+333: n02342885
+334: n02346627
+335: n02356798
+336: n02361337
+337: n05262120
+338: n02364673
+339: n02389026
+340: n02391049
+341: n02395406
+342: n02396427
+343: n02397096
+344: n02398521
+345: n02403003
+346: n02408429
+347: n02410509
+348: n02412080
+349: n02415577
+350: n02417914
+351: n02422106
+352: n02422699
+353: n02423022
+354: n02437312
+355: n02437616
+356: n10771990
+357: n14765497
+358: n02443114
+359: n02443484
+360: n14765785
+361: n02445715
+362: n02447366
+363: n02454379
+364: n02457408
+365: n02480495
+366: n02480855
+367: n02481823
+368: n02483362
+369: n02483708
+370: n02484975
+371: n02486261
+372: n02486410
+373: n02487347
+374: n02488291
+375: n02488702
+376: n02489166
+377: n02490219
+378: n02492035
+379: n02492660
+380: n02493509
+381: n02493793
+382: n02494079
+383: n02497673
+384: n02500267
+385: n02504013
+386: n02504458
+387: n02509815
+388: n02510455
+389: n02514041
+390: n07783967
+391: n02536864
+392: n02606052
+393: n02607072
+394: n02640242
+395: n02641379
+396: n02643566
+397: n02655020
+398: n02666347
+399: n02667093
+400: n02669723
+401: n02672831
+402: n02676566
+403: n02687172
+404: n02690373
+405: n02692877
+406: n02699494
+407: n02701002
+408: n02704792
+409: n02708093
+410: n02727426
+411: n08496334
+412: n02747177
+413: n02749479
+414: n02769748
+415: n02776631
+416: n02777292
+417: n02782329
+418: n02783161
+419: n02786058
+420: n02787622
+421: n02788148
+422: n02790996
+423: n02791124
+424: n02791270
+425: n02793495
+426: n02794156
+427: n02795169
+428: n02797295
+429: n02799071
+430: n02802426
+431: n02804515
+432: n02804610
+433: n02807133
+434: n02808304
+435: n02808440
+436: n02814533
+437: n02814860
+438: n02815834
+439: n02817516
+440: n02823428
+441: n02823750
+442: n02825657
+443: n02834397
+444: n02835271
+445: n02837789
+446: n02840245
+447: n02841315
+448: n02843684
+449: n02859443
+450: n02860847
+451: n02865351
+452: n02869837
+453: n02870880
+454: n02871525
+455: n02877765
+456: n02880308
+457: n02883205
+458: n02892201
+459: n02892767
+460: n02894605
+461: n02895154
+462: n12520864
+463: n02909870
+464: n02910353
+465: n02916936
+466: n02917067
+467: n02927161
+468: n02930766
+469: n02939185
+470: n02948072
+471: n02950826
+472: n02951358
+473: n02951585
+474: n02963159
+475: n02965783
+476: n02966193
+477: n02966687
+478: n02971356
+479: n02974003
+480: n02977058
+481: n02978881
+482: n02979186
+483: n02980441
+484: n02981792
+485: n02988304
+486: n02992211
+487: n02992529
+488: n13652994
+489: n03000134
+490: n03000247
+491: n03000684
+492: n03014705
+493: n03016953
+494: n03017168
+495: n03018349
+496: n03026506
+497: n03028079
+498: n03032252
+499: n03041632
+500: n03042490
+501: n03045698
+502: n03047690
+503: n03062245
+504: n03063599
+505: n03063689
+506: n03065424
+507: n03075370
+508: n03085013
+509: n03089624
+510: n03095699
+511: n03100240
+512: n03109150
+513: n03110669
+514: n03124043
+515: n03124170
+516: n15142452
+517: n03126707
+518: n03127747
+519: n03127925
+520: n03131574
+521: n03133878
+522: n03134739
+523: n03141823
+524: n03146219
+525: n03160309
+526: n03179701
+527: n03180011
+528: n03187595
+529: n03188531
+530: n03196217
+531: n03197337
+532: n03201208
+533: n03207743
+534: n03207941
+535: n03208938
+536: n03216828
+537: n03218198
+538: n13872072
+539: n03223299
+540: n03240683
+541: n03249569
+542: n07647870
+543: n03255030
+544: n03259401
+545: n03271574
+546: n03272010
+547: n03272562
+548: n03290653
+549: n13869788
+550: n03297495
+551: n03314780
+552: n03325584
+553: n03337140
+554: n03344393
+555: n03345487
+556: n03347037
+557: n03355925
+558: n03372029
+559: n03376595
+560: n03379051
+561: n03384352
+562: n03388043
+563: n03388183
+564: n03388549
+565: n03393912
+566: n03394916
+567: n03400231
+568: n03404251
+569: n03417042
+570: n03424325
+571: n03425413
+572: n03443371
+573: n03444034
+574: n03445777
+575: n03445924
+576: n03447447
+577: n03447721
+578: n08286342
+579: n03452741
+580: n03457902
+581: n03459775
+582: n03461385
+583: n03467068
+584: n03476684
+585: n03476991
+586: n03478589
+587: n03482001
+588: n03482405
+589: n03483316
+590: n03485407
+591: n03485794
+592: n03492542
+593: n03494278
+594: n03495570
+595: n10161363
+596: n03498962
+597: n03527565
+598: n03529860
+599: n09218315
+600: n03532672
+601: n03534580
+602: n03535780
+603: n03538406
+604: n03544143
+605: n03584254
+606: n03584829
+607: n03590841
+608: n03594734
+609: n03594945
+610: n03595614
+611: n03598930
+612: n03599486
+613: n03602883
+614: n03617480
+615: n03623198
+616: n15102712
+617: n03630383
+618: n03633091
+619: n03637318
+620: n03642806
+621: n03649909
+622: n03657121
+623: n03658185
+624: n07977870
+625: n03662601
+626: n03666591
+627: n03670208
+628: n03673027
+629: n03676483
+630: n03680355
+631: n03690938
+632: n03691459
+633: n03692522
+634: n03697007
+635: n03706229
+636: n03709823
+637: n03710193
+638: n03710637
+639: n03710721
+640: n03717622
+641: n03720891
+642: n03721384
+643: n03725035
+644: n03729826
+645: n03733131
+646: n03733281
+647: n03733805
+648: n03742115
+649: n03743016
+650: n03759954
+651: n03761084
+652: n03763968
+653: n03764736
+654: n03769881
+655: n03770439
+656: n03770679
+657: n03773504
+658: n03775071
+659: n03775546
+660: n03776460
+661: n03777568
+662: n03777754
+663: n03781244
+664: n03782006
+665: n03785016
+666: n14955889
+667: n03787032
+668: n03788195
+669: n03788365
+670: n03791053
+671: n03792782
+672: n03792972
+673: n03793489
+674: n03794056
+675: n03796401
+676: n03803284
+677: n13652335
+678: n03814639
+679: n03814906
+680: n03825788
+681: n03832673
+682: n03837869
+683: n03838899
+684: n03840681
+685: n03841143
+686: n03843555
+687: n03854065
+688: n03857828
+689: n03866082
+690: n03868242
+691: n03868863
+692: n07281099
+693: n03873416
+694: n03874293
+695: n03874599
+696: n03876231
+697: n03877472
+698: n08053121
+699: n03884397
+700: n03887697
+701: n03888257
+702: n03888605
+703: n03891251
+704: n03891332
+705: n03895866
+706: n03899768
+707: n03902125
+708: n03903868
+709: n03908618
+710: n03908714
+711: n03916031
+712: n03920288
+713: n03924679
+714: n03929660
+715: n03929855
+716: n03930313
+717: n03930630
+718: n03934042
+719: n03935335
+720: n03937543
+721: n03938244
+722: n03942813
+723: n03944341
+724: n03947888
+725: n03950228
+726: n03954731
+727: n03956157
+728: n03958227
+729: n03961711
+730: n03967562
+731: n03970156
+732: n03976467
+733: n08620881
+734: n03977966
+735: n03980874
+736: n03982430
+737: n03983396
+738: n03991062
+739: n03992509
+740: n03995372
+741: n03998194
+742: n04004767
+743: n13937284
+744: n04008634
+745: n04009801
+746: n04019541
+747: n04023962
+748: n13413294
+749: n04033901
+750: n04033995
+751: n04037443
+752: n04039381
+753: n09403211
+754: n04041544
+755: n04044716
+756: n04049303
+757: n04065272
+758: n07056680
+759: n04069434
+760: n04070727
+761: n04074963
+762: n04081281
+763: n04086273
+764: n04090263
+765: n04099969
+766: n04111531
+767: n04116512
+768: n04118538
+769: n04118776
+770: n04120489
+771: n04125116
+772: n04127249
+773: n04131690
+774: n04133789
+775: n04136333
+776: n04141076
+777: n04141327
+778: n04141975
+779: n04146614
+780: n04147291
+781: n04149813
+782: n04152593
+783: n04154340
+784: n07917272
+785: n04162706
+786: n04179913
+787: n04192698
+788: n04200800
+789: n04201297
+790: n04204238
+791: n04204347
+792: n04208427
+793: n04209133
+794: n04209239
+795: n04228054
+796: n04229816
+797: n04235860
+798: n04238763
+799: n04239074
+800: n04243546
+801: n04251144
+802: n04252077
+803: n04252225
+804: n04254120
+805: n04254680
+806: n04254777
+807: n04258138
+808: n04259630
+809: n04263257
+810: n04264628
+811: n04265275
+812: n04266014
+813: n04270147
+814: n04273569
+815: n04275363
+816: n05605498
+817: n04285008
+818: n04286575
+819: n08646566
+820: n04310018
+821: n04311004
+822: n04311174
+823: n04317175
+824: n04325704
+825: n04326547
+826: n04328186
+827: n04330267
+828: n04332243
+829: n04335435
+830: n04337157
+831: n04344873
+832: n04346328
+833: n04347754
+834: n04350905
+835: n04355338
+836: n04355933
+837: n04356056
+838: n04357314
+839: n04366367
+840: n04367480
+841: n04370456
+842: n04371430
+843: n14009946
+844: n04372370
+845: n04376876
+846: n04380533
+847: n04389033
+848: n04392985
+849: n04398044
+850: n04399382
+851: n04404412
+852: n04409515
+853: n04417672
+854: n04418357
+855: n04423845
+856: n04428191
+857: n04429376
+858: n04435653
+859: n04442312
+860: n04443257
+861: n04447861
+862: n04456115
+863: n04458633
+864: n04461696
+865: n04462240
+866: n04465666
+867: n04467665
+868: n04476259
+869: n04479046
+870: n04482393
+871: n04483307
+872: n04485082
+873: n04486054
+874: n04487081
+875: n04487394
+876: n04493381
+877: n04501370
+878: n04505470
+879: n04507155
+880: n04509417
+881: n04515003
+882: n04517823
+883: n04522168
+884: n04523525
+885: n04525038
+886: n04525305
+887: n04532106
+888: n04532670
+889: n04536866
+890: n04540053
+891: n04542943
+892: n04548280
+893: n04548362
+894: n04550184
+895: n04552348
+896: n04553703
+897: n04554684
+898: n04557648
+899: n04560804
+900: n04562935
+901: n04579145
+902: n04579667
+903: n04584207
+904: n04589890
+905: n04590129
+906: n04591157
+907: n04591713
+908: n10782135
+909: n04596742
+910: n04598010
+911: n04599235
+912: n04604644
+913: n14423870
+914: n04612504
+915: n04613696
+916: n06359193
+917: n06596364
+918: n06785654
+919: n06794110
+920: n06874185
+921: n07248320
+922: n07565083
+923: n07657664
+924: n07583066
+925: n07584110
+926: n07590611
+927: n07613480
+928: n07614500
+929: n07615774
+930: n07684084
+931: n07693725
+932: n07695742
+933: n07697313
+934: n07697537
+935: n07711569
+936: n07714571
+937: n07714990
+938: n07715103
+939: n12159804
+940: n12160303
+941: n12160857
+942: n07717556
+943: n07718472
+944: n07718747
+945: n07720875
+946: n07730033
+947: n13001041
+948: n07742313
+949: n12630144
+950: n14991210
+951: n07749582
+952: n07753113
+953: n07753275
+954: n07753592
+955: n07754684
+956: n07760859
+957: n07768694
+958: n07802026
+959: n07831146
+960: n07836838
+961: n07860988
+962: n07871810
+963: n07873807
+964: n07875152
+965: n07880968
+966: n07892512
+967: n07920052
+968: n13904665
+969: n07932039
+970: n09193705
+971: n09229709
+972: n09246464
+973: n09256479
+974: n09288635
+975: n09332890
+976: n09399592
+977: n09421951
+978: n09428293
+979: n09468604
+980: n09472597
+981: n09835506
+982: n10148035
+983: n10565667
+984: n11879895
+985: n11939491
+986: n12057211
+987: n12144580
+988: n12267677
+989: n12620546
+990: n12768682
+991: n12985857
+992: n12998815
+993: n13037406
+994: n13040303
+995: n13044778
+996: n13052670
+997: n13054560
+998: n13133613
+999: n15075141

binární
data/inpainting_examples/6458524847_2f4c361183_k.png


binární
data/inpainting_examples/6458524847_2f4c361183_k_mask.png

binární
data/inpainting_examples/8399166846_f6fb4e4b8e_k.png

binární
data/inpainting_examples/8399166846_f6fb4e4b8e_k_mask.png

binární
data/inpainting_examples/alex-iby-G_Pk4D9rMLs.png

binární
data/inpainting_examples/alex-iby-G_Pk4D9rMLs_mask.png

binární
data/inpainting_examples/bench2.png

binární
data/inpainting_examples/bench2_mask.png

binární
data/inpainting_examples/bertrand-gabioud-CpuFzIsHYJ0.png

binární
data/inpainting_examples/bertrand-gabioud-CpuFzIsHYJ0_mask.png

binární
data/inpainting_examples/billow926-12-Wc-Zgx6Y.png

binární
data/inpainting_examples/billow926-12-Wc-Zgx6Y_mask.png

binární
data/inpainting_examples/overture-creations-5sI6fQgYIuo.png

binární
data/inpainting_examples/overture-creations-5sI6fQgYIuo_mask.png

binární
data/inpainting_examples/photo-1583445095369-9c651e7e5d34.png

binární
data/inpainting_examples/photo-1583445095369-9c651e7e5d34_mask.png

+ 27 - 0
environment.yaml

@@ -0,0 +1,27 @@
+name: ldm
+channels:
+  - pytorch
+  - defaults
+dependencies:
+  - python=3.8.5
+  - pip=20.3
+  - cudatoolkit=11.0
+  - pytorch=1.7.0
+  - torchvision=0.8.1
+  - numpy=1.19.2
+  - pip:
+    - albumentations==0.4.3
+    - opencv-python==4.1.2.30
+    - pudb==2019.2
+    - imageio==2.9.0
+    - imageio-ffmpeg==0.4.2
+    - pytorch-lightning==1.4.2
+    - omegaconf==2.1.1
+    - test-tube>=0.7.5
+    - streamlit>=0.73.1
+    - einops==0.3.0
+    - torch-fidelity==0.3.0
+    - transformers==4.3.1
+    - -e git+https://github.com/CompVis/taming-transformers.git@master#egg=taming-transformers
+    - -e git+https://github.com/openai/CLIP.git@main#egg=clip
+    - -e .

+ 0 - 0
ldm/data/__init__.py


+ 23 - 0
ldm/data/base.py

@@ -0,0 +1,23 @@
+from abc import abstractmethod
+from torch.utils.data import Dataset, ConcatDataset, ChainDataset, IterableDataset
+
+
+class Txt2ImgIterableBaseDataset(IterableDataset):
+    '''
+    Define an interface to make the IterableDatasets for text2img data chainable
+    '''
+    def __init__(self, num_records=0, valid_ids=None, size=256):
+        super().__init__()
+        self.num_records = num_records
+        self.valid_ids = valid_ids
+        self.sample_ids = valid_ids
+        self.size = size
+
+        print(f'{self.__class__.__name__} dataset contains {self.__len__()} examples.')
+
+    def __len__(self):
+        return self.num_records
+
+    @abstractmethod
+    def __iter__(self):
+        pass

+ 394 - 0
ldm/data/imagenet.py

@@ -0,0 +1,394 @@
+import os, yaml, pickle, shutil, tarfile, glob
+import cv2
+import albumentations
+import PIL
+import numpy as np
+import torchvision.transforms.functional as TF
+from omegaconf import OmegaConf
+from functools import partial
+from PIL import Image
+from tqdm import tqdm
+from torch.utils.data import Dataset, Subset
+
+import taming.data.utils as tdu
+from taming.data.imagenet import str_to_indices, give_synsets_from_indices, download, retrieve
+from taming.data.imagenet import ImagePaths
+
+from ldm.modules.image_degradation import degradation_fn_bsr, degradation_fn_bsr_light
+
+
+def synset2idx(path_to_yaml="data/index_synset.yaml"):
+    with open(path_to_yaml) as f:
+        di2s = yaml.load(f)
+    return dict((v,k) for k,v in di2s.items())
+
+
+class ImageNetBase(Dataset):
+    def __init__(self, config=None):
+        self.config = config or OmegaConf.create()
+        if not type(self.config)==dict:
+            self.config = OmegaConf.to_container(self.config)
+        self.keep_orig_class_label = self.config.get("keep_orig_class_label", False)
+        self.process_images = True  # if False we skip loading & processing images and self.data contains filepaths
+        self._prepare()
+        self._prepare_synset_to_human()
+        self._prepare_idx_to_synset()
+        self._prepare_human_to_integer_label()
+        self._load()
+
+    def __len__(self):
+        return len(self.data)
+
+    def __getitem__(self, i):
+        return self.data[i]
+
+    def _prepare(self):
+        raise NotImplementedError()
+
+    def _filter_relpaths(self, relpaths):
+        ignore = set([
+            "n06596364_9591.JPEG",
+        ])
+        relpaths = [rpath for rpath in relpaths if not rpath.split("/")[-1] in ignore]
+        if "sub_indices" in self.config:
+            indices = str_to_indices(self.config["sub_indices"])
+            synsets = give_synsets_from_indices(indices, path_to_yaml=self.idx2syn)  # returns a list of strings
+            self.synset2idx = synset2idx(path_to_yaml=self.idx2syn)
+            files = []
+            for rpath in relpaths:
+                syn = rpath.split("/")[0]
+                if syn in synsets:
+                    files.append(rpath)
+            return files
+        else:
+            return relpaths
+
+    def _prepare_synset_to_human(self):
+        SIZE = 2655750
+        URL = "https://heibox.uni-heidelberg.de/f/9f28e956cd304264bb82/?dl=1"
+        self.human_dict = os.path.join(self.root, "synset_human.txt")
+        if (not os.path.exists(self.human_dict) or
+                not os.path.getsize(self.human_dict)==SIZE):
+            download(URL, self.human_dict)
+
+    def _prepare_idx_to_synset(self):
+        URL = "https://heibox.uni-heidelberg.de/f/d835d5b6ceda4d3aa910/?dl=1"
+        self.idx2syn = os.path.join(self.root, "index_synset.yaml")
+        if (not os.path.exists(self.idx2syn)):
+            download(URL, self.idx2syn)
+
+    def _prepare_human_to_integer_label(self):
+        URL = "https://heibox.uni-heidelberg.de/f/2362b797d5be43b883f6/?dl=1"
+        self.human2integer = os.path.join(self.root, "imagenet1000_clsidx_to_labels.txt")
+        if (not os.path.exists(self.human2integer)):
+            download(URL, self.human2integer)
+        with open(self.human2integer, "r") as f:
+            lines = f.read().splitlines()
+            assert len(lines) == 1000
+            self.human2integer_dict = dict()
+            for line in lines:
+                value, key = line.split(":")
+                self.human2integer_dict[key] = int(value)
+
+    def _load(self):
+        with open(self.txt_filelist, "r") as f:
+            self.relpaths = f.read().splitlines()
+            l1 = len(self.relpaths)
+            self.relpaths = self._filter_relpaths(self.relpaths)
+            print("Removed {} files from filelist during filtering.".format(l1 - len(self.relpaths)))
+
+        self.synsets = [p.split("/")[0] for p in self.relpaths]
+        self.abspaths = [os.path.join(self.datadir, p) for p in self.relpaths]
+
+        unique_synsets = np.unique(self.synsets)
+        class_dict = dict((synset, i) for i, synset in enumerate(unique_synsets))
+        if not self.keep_orig_class_label:
+            self.class_labels = [class_dict[s] for s in self.synsets]
+        else:
+            self.class_labels = [self.synset2idx[s] for s in self.synsets]
+
+        with open(self.human_dict, "r") as f:
+            human_dict = f.read().splitlines()
+            human_dict = dict(line.split(maxsplit=1) for line in human_dict)
+
+        self.human_labels = [human_dict[s] for s in self.synsets]
+
+        labels = {
+            "relpath": np.array(self.relpaths),
+            "synsets": np.array(self.synsets),
+            "class_label": np.array(self.class_labels),
+            "human_label": np.array(self.human_labels),
+        }
+
+        if self.process_images:
+            self.size = retrieve(self.config, "size", default=256)
+            self.data = ImagePaths(self.abspaths,
+                                   labels=labels,
+                                   size=self.size,
+                                   random_crop=self.random_crop,
+                                   )
+        else:
+            self.data = self.abspaths
+
+
+class ImageNetTrain(ImageNetBase):
+    NAME = "ILSVRC2012_train"
+    URL = "http://www.image-net.org/challenges/LSVRC/2012/"
+    AT_HASH = "a306397ccf9c2ead27155983c254227c0fd938e2"
+    FILES = [
+        "ILSVRC2012_img_train.tar",
+    ]
+    SIZES = [
+        147897477120,
+    ]
+
+    def __init__(self, process_images=True, data_root=None, **kwargs):
+        self.process_images = process_images
+        self.data_root = data_root
+        super().__init__(**kwargs)
+
+    def _prepare(self):
+        if self.data_root:
+            self.root = os.path.join(self.data_root, self.NAME)
+        else:
+            cachedir = os.environ.get("XDG_CACHE_HOME", os.path.expanduser("~/.cache"))
+            self.root = os.path.join(cachedir, "autoencoders/data", self.NAME)
+
+        self.datadir = os.path.join(self.root, "data")
+        self.txt_filelist = os.path.join(self.root, "filelist.txt")
+        self.expected_length = 1281167
+        self.random_crop = retrieve(self.config, "ImageNetTrain/random_crop",
+                                    default=True)
+        if not tdu.is_prepared(self.root):
+            # prep
+            print("Preparing dataset {} in {}".format(self.NAME, self.root))
+
+            datadir = self.datadir
+            if not os.path.exists(datadir):
+                path = os.path.join(self.root, self.FILES[0])
+                if not os.path.exists(path) or not os.path.getsize(path)==self.SIZES[0]:
+                    import academictorrents as at
+                    atpath = at.get(self.AT_HASH, datastore=self.root)
+                    assert atpath == path
+
+                print("Extracting {} to {}".format(path, datadir))
+                os.makedirs(datadir, exist_ok=True)
+                with tarfile.open(path, "r:") as tar:
+                    tar.extractall(path=datadir)
+
+                print("Extracting sub-tars.")
+                subpaths = sorted(glob.glob(os.path.join(datadir, "*.tar")))
+                for subpath in tqdm(subpaths):
+                    subdir = subpath[:-len(".tar")]
+                    os.makedirs(subdir, exist_ok=True)
+                    with tarfile.open(subpath, "r:") as tar:
+                        tar.extractall(path=subdir)
+
+            filelist = glob.glob(os.path.join(datadir, "**", "*.JPEG"))
+            filelist = [os.path.relpath(p, start=datadir) for p in filelist]
+            filelist = sorted(filelist)
+            filelist = "\n".join(filelist)+"\n"
+            with open(self.txt_filelist, "w") as f:
+                f.write(filelist)
+
+            tdu.mark_prepared(self.root)
+
+
+class ImageNetValidation(ImageNetBase):
+    NAME = "ILSVRC2012_validation"
+    URL = "http://www.image-net.org/challenges/LSVRC/2012/"
+    AT_HASH = "5d6d0df7ed81efd49ca99ea4737e0ae5e3a5f2e5"
+    VS_URL = "https://heibox.uni-heidelberg.de/f/3e0f6e9c624e45f2bd73/?dl=1"
+    FILES = [
+        "ILSVRC2012_img_val.tar",
+        "validation_synset.txt",
+    ]
+    SIZES = [
+        6744924160,
+        1950000,
+    ]
+
+    def __init__(self, process_images=True, data_root=None, **kwargs):
+        self.data_root = data_root
+        self.process_images = process_images
+        super().__init__(**kwargs)
+
+    def _prepare(self):
+        if self.data_root:
+            self.root = os.path.join(self.data_root, self.NAME)
+        else:
+            cachedir = os.environ.get("XDG_CACHE_HOME", os.path.expanduser("~/.cache"))
+            self.root = os.path.join(cachedir, "autoencoders/data", self.NAME)
+        self.datadir = os.path.join(self.root, "data")
+        self.txt_filelist = os.path.join(self.root, "filelist.txt")
+        self.expected_length = 50000
+        self.random_crop = retrieve(self.config, "ImageNetValidation/random_crop",
+                                    default=False)
+        if not tdu.is_prepared(self.root):
+            # prep
+            print("Preparing dataset {} in {}".format(self.NAME, self.root))
+
+            datadir = self.datadir
+            if not os.path.exists(datadir):
+                path = os.path.join(self.root, self.FILES[0])
+                if not os.path.exists(path) or not os.path.getsize(path)==self.SIZES[0]:
+                    import academictorrents as at
+                    atpath = at.get(self.AT_HASH, datastore=self.root)
+                    assert atpath == path
+
+                print("Extracting {} to {}".format(path, datadir))
+                os.makedirs(datadir, exist_ok=True)
+                with tarfile.open(path, "r:") as tar:
+                    tar.extractall(path=datadir)
+
+                vspath = os.path.join(self.root, self.FILES[1])
+                if not os.path.exists(vspath) or not os.path.getsize(vspath)==self.SIZES[1]:
+                    download(self.VS_URL, vspath)
+
+                with open(vspath, "r") as f:
+                    synset_dict = f.read().splitlines()
+                    synset_dict = dict(line.split() for line in synset_dict)
+
+                print("Reorganizing into synset folders")
+                synsets = np.unique(list(synset_dict.values()))
+                for s in synsets:
+                    os.makedirs(os.path.join(datadir, s), exist_ok=True)
+                for k, v in synset_dict.items():
+                    src = os.path.join(datadir, k)
+                    dst = os.path.join(datadir, v)
+                    shutil.move(src, dst)
+
+            filelist = glob.glob(os.path.join(datadir, "**", "*.JPEG"))
+            filelist = [os.path.relpath(p, start=datadir) for p in filelist]
+            filelist = sorted(filelist)
+            filelist = "\n".join(filelist)+"\n"
+            with open(self.txt_filelist, "w") as f:
+                f.write(filelist)
+
+            tdu.mark_prepared(self.root)
+
+
+
+class ImageNetSR(Dataset):
+    def __init__(self, size=None,
+                 degradation=None, downscale_f=4, min_crop_f=0.5, max_crop_f=1.,
+                 random_crop=True):
+        """
+        Imagenet Superresolution Dataloader
+        Performs following ops in order:
+        1.  crops a crop of size s from image either as random or center crop
+        2.  resizes crop to size with cv2.area_interpolation
+        3.  degrades resized crop with degradation_fn
+
+        :param size: resizing to size after cropping
+        :param degradation: degradation_fn, e.g. cv_bicubic or bsrgan_light
+        :param downscale_f: Low Resolution Downsample factor
+        :param min_crop_f: determines crop size s,
+          where s = c * min_img_side_len with c sampled from interval (min_crop_f, max_crop_f)
+        :param max_crop_f: ""
+        :param data_root:
+        :param random_crop:
+        """
+        self.base = self.get_base()
+        assert size
+        assert (size / downscale_f).is_integer()
+        self.size = size
+        self.LR_size = int(size / downscale_f)
+        self.min_crop_f = min_crop_f
+        self.max_crop_f = max_crop_f
+        assert(max_crop_f <= 1.)
+        self.center_crop = not random_crop
+
+        self.image_rescaler = albumentations.SmallestMaxSize(max_size=size, interpolation=cv2.INTER_AREA)
+
+        self.pil_interpolation = False # gets reset later if incase interp_op is from pillow
+
+        if degradation == "bsrgan":
+            self.degradation_process = partial(degradation_fn_bsr, sf=downscale_f)
+
+        elif degradation == "bsrgan_light":
+            self.degradation_process = partial(degradation_fn_bsr_light, sf=downscale_f)
+
+        else:
+            interpolation_fn = {
+            "cv_nearest": cv2.INTER_NEAREST,
+            "cv_bilinear": cv2.INTER_LINEAR,
+            "cv_bicubic": cv2.INTER_CUBIC,
+            "cv_area": cv2.INTER_AREA,
+            "cv_lanczos": cv2.INTER_LANCZOS4,
+            "pil_nearest": PIL.Image.NEAREST,
+            "pil_bilinear": PIL.Image.BILINEAR,
+            "pil_bicubic": PIL.Image.BICUBIC,
+            "pil_box": PIL.Image.BOX,
+            "pil_hamming": PIL.Image.HAMMING,
+            "pil_lanczos": PIL.Image.LANCZOS,
+            }[degradation]
+
+            self.pil_interpolation = degradation.startswith("pil_")
+
+            if self.pil_interpolation:
+                self.degradation_process = partial(TF.resize, size=self.LR_size, interpolation=interpolation_fn)
+
+            else:
+                self.degradation_process = albumentations.SmallestMaxSize(max_size=self.LR_size,
+                                                                          interpolation=interpolation_fn)
+
+    def __len__(self):
+        return len(self.base)
+
+    def __getitem__(self, i):
+        example = self.base[i]
+        image = Image.open(example["file_path_"])
+
+        if not image.mode == "RGB":
+            image = image.convert("RGB")
+
+        image = np.array(image).astype(np.uint8)
+
+        min_side_len = min(image.shape[:2])
+        crop_side_len = min_side_len * np.random.uniform(self.min_crop_f, self.max_crop_f, size=None)
+        crop_side_len = int(crop_side_len)
+
+        if self.center_crop:
+            self.cropper = albumentations.CenterCrop(height=crop_side_len, width=crop_side_len)
+
+        else:
+            self.cropper = albumentations.RandomCrop(height=crop_side_len, width=crop_side_len)
+
+        image = self.cropper(image=image)["image"]
+        image = self.image_rescaler(image=image)["image"]
+
+        if self.pil_interpolation:
+            image_pil = PIL.Image.fromarray(image)
+            LR_image = self.degradation_process(image_pil)
+            LR_image = np.array(LR_image).astype(np.uint8)
+
+        else:
+            LR_image = self.degradation_process(image=image)["image"]
+
+        example["image"] = (image/127.5 - 1.0).astype(np.float32)
+        example["LR_image"] = (LR_image/127.5 - 1.0).astype(np.float32)
+
+        return example
+
+
+class ImageNetSRTrain(ImageNetSR):
+    def __init__(self, **kwargs):
+        super().__init__(**kwargs)
+
+    def get_base(self):
+        with open("data/imagenet_train_hr_indices.p", "rb") as f:
+            indices = pickle.load(f)
+        dset = ImageNetTrain(process_images=False,)
+        return Subset(dset, indices)
+
+
+class ImageNetSRValidation(ImageNetSR):
+    def __init__(self, **kwargs):
+        super().__init__(**kwargs)
+
+    def get_base(self):
+        with open("data/imagenet_val_hr_indices.p", "rb") as f:
+            indices = pickle.load(f)
+        dset = ImageNetValidation(process_images=False,)
+        return Subset(dset, indices)

+ 92 - 0
ldm/data/lsun.py

@@ -0,0 +1,92 @@
+import os
+import numpy as np
+import PIL
+from PIL import Image
+from torch.utils.data import Dataset
+from torchvision import transforms
+
+
+class LSUNBase(Dataset):
+    def __init__(self,
+                 txt_file,
+                 data_root,
+                 size=None,
+                 interpolation="bicubic",
+                 flip_p=0.5
+                 ):
+        self.data_paths = txt_file
+        self.data_root = data_root
+        with open(self.data_paths, "r") as f:
+            self.image_paths = f.read().splitlines()
+        self._length = len(self.image_paths)
+        self.labels = {
+            "relative_file_path_": [l for l in self.image_paths],
+            "file_path_": [os.path.join(self.data_root, l)
+                           for l in self.image_paths],
+        }
+
+        self.size = size
+        self.interpolation = {"linear": PIL.Image.LINEAR,
+                              "bilinear": PIL.Image.BILINEAR,
+                              "bicubic": PIL.Image.BICUBIC,
+                              "lanczos": PIL.Image.LANCZOS,
+                              }[interpolation]
+        self.flip = transforms.RandomHorizontalFlip(p=flip_p)
+
+    def __len__(self):
+        return self._length
+
+    def __getitem__(self, i):
+        example = dict((k, self.labels[k][i]) for k in self.labels)
+        image = Image.open(example["file_path_"])
+        if not image.mode == "RGB":
+            image = image.convert("RGB")
+
+        # default to score-sde preprocessing
+        img = np.array(image).astype(np.uint8)
+        crop = min(img.shape[0], img.shape[1])
+        h, w, = img.shape[0], img.shape[1]
+        img = img[(h - crop) // 2:(h + crop) // 2,
+              (w - crop) // 2:(w + crop) // 2]
+
+        image = Image.fromarray(img)
+        if self.size is not None:
+            image = image.resize((self.size, self.size), resample=self.interpolation)
+
+        image = self.flip(image)
+        image = np.array(image).astype(np.uint8)
+        example["image"] = (image / 127.5 - 1.0).astype(np.float32)
+        return example
+
+
+class LSUNChurchesTrain(LSUNBase):
+    def __init__(self, **kwargs):
+        super().__init__(txt_file="data/lsun/church_outdoor_train.txt", data_root="data/lsun/churches", **kwargs)
+
+
+class LSUNChurchesValidation(LSUNBase):
+    def __init__(self, flip_p=0., **kwargs):
+        super().__init__(txt_file="data/lsun/church_outdoor_val.txt", data_root="data/lsun/churches",
+                         flip_p=flip_p, **kwargs)
+
+
+class LSUNBedroomsTrain(LSUNBase):
+    def __init__(self, **kwargs):
+        super().__init__(txt_file="data/lsun/bedrooms_train.txt", data_root="data/lsun/bedrooms", **kwargs)
+
+
+class LSUNBedroomsValidation(LSUNBase):
+    def __init__(self, flip_p=0.0, **kwargs):
+        super().__init__(txt_file="data/lsun/bedrooms_val.txt", data_root="data/lsun/bedrooms",
+                         flip_p=flip_p, **kwargs)
+
+
+class LSUNCatsTrain(LSUNBase):
+    def __init__(self, **kwargs):
+        super().__init__(txt_file="data/lsun/cat_train.txt", data_root="data/lsun/cats", **kwargs)
+
+
+class LSUNCatsValidation(LSUNBase):
+    def __init__(self, flip_p=0., **kwargs):
+        super().__init__(txt_file="data/lsun/cat_val.txt", data_root="data/lsun/cats",
+                         flip_p=flip_p, **kwargs)

+ 98 - 0
ldm/lr_scheduler.py

@@ -0,0 +1,98 @@
+import numpy as np
+
+
+class LambdaWarmUpCosineScheduler:
+    """
+    note: use with a base_lr of 1.0
+    """
+    def __init__(self, warm_up_steps, lr_min, lr_max, lr_start, max_decay_steps, verbosity_interval=0):
+        self.lr_warm_up_steps = warm_up_steps
+        self.lr_start = lr_start
+        self.lr_min = lr_min
+        self.lr_max = lr_max
+        self.lr_max_decay_steps = max_decay_steps
+        self.last_lr = 0.
+        self.verbosity_interval = verbosity_interval
+
+    def schedule(self, n, **kwargs):
+        if self.verbosity_interval > 0:
+            if n % self.verbosity_interval == 0: print(f"current step: {n}, recent lr-multiplier: {self.last_lr}")
+        if n < self.lr_warm_up_steps:
+            lr = (self.lr_max - self.lr_start) / self.lr_warm_up_steps * n + self.lr_start
+            self.last_lr = lr
+            return lr
+        else:
+            t = (n - self.lr_warm_up_steps) / (self.lr_max_decay_steps - self.lr_warm_up_steps)
+            t = min(t, 1.0)
+            lr = self.lr_min + 0.5 * (self.lr_max - self.lr_min) * (
+                    1 + np.cos(t * np.pi))
+            self.last_lr = lr
+            return lr
+
+    def __call__(self, n, **kwargs):
+        return self.schedule(n,**kwargs)
+
+
+class LambdaWarmUpCosineScheduler2:
+    """
+    supports repeated iterations, configurable via lists
+    note: use with a base_lr of 1.0.
+    """
+    def __init__(self, warm_up_steps, f_min, f_max, f_start, cycle_lengths, verbosity_interval=0):
+        assert len(warm_up_steps) == len(f_min) == len(f_max) == len(f_start) == len(cycle_lengths)
+        self.lr_warm_up_steps = warm_up_steps
+        self.f_start = f_start
+        self.f_min = f_min
+        self.f_max = f_max
+        self.cycle_lengths = cycle_lengths
+        self.cum_cycles = np.cumsum([0] + list(self.cycle_lengths))
+        self.last_f = 0.
+        self.verbosity_interval = verbosity_interval
+
+    def find_in_interval(self, n):
+        interval = 0
+        for cl in self.cum_cycles[1:]:
+            if n <= cl:
+                return interval
+            interval += 1
+
+    def schedule(self, n, **kwargs):
+        cycle = self.find_in_interval(n)
+        n = n - self.cum_cycles[cycle]
+        if self.verbosity_interval > 0:
+            if n % self.verbosity_interval == 0: print(f"current step: {n}, recent lr-multiplier: {self.last_f}, "
+                                                       f"current cycle {cycle}")
+        if n < self.lr_warm_up_steps[cycle]:
+            f = (self.f_max[cycle] - self.f_start[cycle]) / self.lr_warm_up_steps[cycle] * n + self.f_start[cycle]
+            self.last_f = f
+            return f
+        else:
+            t = (n - self.lr_warm_up_steps[cycle]) / (self.cycle_lengths[cycle] - self.lr_warm_up_steps[cycle])
+            t = min(t, 1.0)
+            f = self.f_min[cycle] + 0.5 * (self.f_max[cycle] - self.f_min[cycle]) * (
+                    1 + np.cos(t * np.pi))
+            self.last_f = f
+            return f
+
+    def __call__(self, n, **kwargs):
+        return self.schedule(n, **kwargs)
+
+
+class LambdaLinearScheduler(LambdaWarmUpCosineScheduler2):
+
+    def schedule(self, n, **kwargs):
+        cycle = self.find_in_interval(n)
+        n = n - self.cum_cycles[cycle]
+        if self.verbosity_interval > 0:
+            if n % self.verbosity_interval == 0: print(f"current step: {n}, recent lr-multiplier: {self.last_f}, "
+                                                       f"current cycle {cycle}")
+
+        if n < self.lr_warm_up_steps[cycle]:
+            f = (self.f_max[cycle] - self.f_start[cycle]) / self.lr_warm_up_steps[cycle] * n + self.f_start[cycle]
+            self.last_f = f
+            return f
+        else:
+            f = self.f_min[cycle] + (self.f_max[cycle] - self.f_min[cycle]) * (self.cycle_lengths[cycle] - n) / (self.cycle_lengths[cycle])
+            self.last_f = f
+            return f
+

+ 443 - 0
ldm/models/autoencoder.py

@@ -0,0 +1,443 @@
+import torch
+import pytorch_lightning as pl
+import torch.nn.functional as F
+from contextlib import contextmanager
+
+from taming.modules.vqvae.quantize import VectorQuantizer2 as VectorQuantizer
+
+from ldm.modules.diffusionmodules.model import Encoder, Decoder
+from ldm.modules.distributions.distributions import DiagonalGaussianDistribution
+
+from ldm.util import instantiate_from_config
+
+
+class VQModel(pl.LightningModule):
+    def __init__(self,
+                 ddconfig,
+                 lossconfig,
+                 n_embed,
+                 embed_dim,
+                 ckpt_path=None,
+                 ignore_keys=[],
+                 image_key="image",
+                 colorize_nlabels=None,
+                 monitor=None,
+                 batch_resize_range=None,
+                 scheduler_config=None,
+                 lr_g_factor=1.0,
+                 remap=None,
+                 sane_index_shape=False, # tell vector quantizer to return indices as bhw
+                 use_ema=False
+                 ):
+        super().__init__()
+        self.embed_dim = embed_dim
+        self.n_embed = n_embed
+        self.image_key = image_key
+        self.encoder = Encoder(**ddconfig)
+        self.decoder = Decoder(**ddconfig)
+        self.loss = instantiate_from_config(lossconfig)
+        self.quantize = VectorQuantizer(n_embed, embed_dim, beta=0.25,
+                                        remap=remap,
+                                        sane_index_shape=sane_index_shape)
+        self.quant_conv = torch.nn.Conv2d(ddconfig["z_channels"], embed_dim, 1)
+        self.post_quant_conv = torch.nn.Conv2d(embed_dim, ddconfig["z_channels"], 1)
+        if colorize_nlabels is not None:
+            assert type(colorize_nlabels)==int
+            self.register_buffer("colorize", torch.randn(3, colorize_nlabels, 1, 1))
+        if monitor is not None:
+            self.monitor = monitor
+        self.batch_resize_range = batch_resize_range
+        if self.batch_resize_range is not None:
+            print(f"{self.__class__.__name__}: Using per-batch resizing in range {batch_resize_range}.")
+
+        self.use_ema = use_ema
+        if self.use_ema:
+            self.model_ema = LitEma(self)
+            print(f"Keeping EMAs of {len(list(self.model_ema.buffers()))}.")
+
+        if ckpt_path is not None:
+            self.init_from_ckpt(ckpt_path, ignore_keys=ignore_keys)
+        self.scheduler_config = scheduler_config
+        self.lr_g_factor = lr_g_factor
+
+    @contextmanager
+    def ema_scope(self, context=None):
+        if self.use_ema:
+            self.model_ema.store(self.parameters())
+            self.model_ema.copy_to(self)
+            if context is not None:
+                print(f"{context}: Switched to EMA weights")
+        try:
+            yield None
+        finally:
+            if self.use_ema:
+                self.model_ema.restore(self.parameters())
+                if context is not None:
+                    print(f"{context}: Restored training weights")
+
+    def init_from_ckpt(self, path, ignore_keys=list()):
+        sd = torch.load(path, map_location="cpu")["state_dict"]
+        keys = list(sd.keys())
+        for k in keys:
+            for ik in ignore_keys:
+                if k.startswith(ik):
+                    print("Deleting key {} from state_dict.".format(k))
+                    del sd[k]
+        missing, unexpected = self.load_state_dict(sd, strict=False)
+        print(f"Restored from {path} with {len(missing)} missing and {len(unexpected)} unexpected keys")
+        if len(missing) > 0:
+            print(f"Missing Keys: {missing}")
+            print(f"Unexpected Keys: {unexpected}")
+
+    def on_train_batch_end(self, *args, **kwargs):
+        if self.use_ema:
+            self.model_ema(self)
+
+    def encode(self, x):
+        h = self.encoder(x)
+        h = self.quant_conv(h)
+        quant, emb_loss, info = self.quantize(h)
+        return quant, emb_loss, info
+
+    def encode_to_prequant(self, x):
+        h = self.encoder(x)
+        h = self.quant_conv(h)
+        return h
+
+    def decode(self, quant):
+        quant = self.post_quant_conv(quant)
+        dec = self.decoder(quant)
+        return dec
+
+    def decode_code(self, code_b):
+        quant_b = self.quantize.embed_code(code_b)
+        dec = self.decode(quant_b)
+        return dec
+
+    def forward(self, input, return_pred_indices=False):
+        quant, diff, (_,_,ind) = self.encode(input)
+        dec = self.decode(quant)
+        if return_pred_indices:
+            return dec, diff, ind
+        return dec, diff
+
+    def get_input(self, batch, k):
+        x = batch[k]
+        if len(x.shape) == 3:
+            x = x[..., None]
+        x = x.permute(0, 3, 1, 2).to(memory_format=torch.contiguous_format).float()
+        if self.batch_resize_range is not None:
+            lower_size = self.batch_resize_range[0]
+            upper_size = self.batch_resize_range[1]
+            if self.global_step <= 4:
+                # do the first few batches with max size to avoid later oom
+                new_resize = upper_size
+            else:
+                new_resize = np.random.choice(np.arange(lower_size, upper_size+16, 16))
+            if new_resize != x.shape[2]:
+                x = F.interpolate(x, size=new_resize, mode="bicubic")
+            x = x.detach()
+        return x
+
+    def training_step(self, batch, batch_idx, optimizer_idx):
+        # https://github.com/pytorch/pytorch/issues/37142
+        # try not to fool the heuristics
+        x = self.get_input(batch, self.image_key)
+        xrec, qloss, ind = self(x, return_pred_indices=True)
+
+        if optimizer_idx == 0:
+            # autoencode
+            aeloss, log_dict_ae = self.loss(qloss, x, xrec, optimizer_idx, self.global_step,
+                                            last_layer=self.get_last_layer(), split="train",
+                                            predicted_indices=ind)
+
+            self.log_dict(log_dict_ae, prog_bar=False, logger=True, on_step=True, on_epoch=True)
+            return aeloss
+
+        if optimizer_idx == 1:
+            # discriminator
+            discloss, log_dict_disc = self.loss(qloss, x, xrec, optimizer_idx, self.global_step,
+                                            last_layer=self.get_last_layer(), split="train")
+            self.log_dict(log_dict_disc, prog_bar=False, logger=True, on_step=True, on_epoch=True)
+            return discloss
+
+    def validation_step(self, batch, batch_idx):
+        log_dict = self._validation_step(batch, batch_idx)
+        with self.ema_scope():
+            log_dict_ema = self._validation_step(batch, batch_idx, suffix="_ema")
+        return log_dict
+
+    def _validation_step(self, batch, batch_idx, suffix=""):
+        x = self.get_input(batch, self.image_key)
+        xrec, qloss, ind = self(x, return_pred_indices=True)
+        aeloss, log_dict_ae = self.loss(qloss, x, xrec, 0,
+                                        self.global_step,
+                                        last_layer=self.get_last_layer(),
+                                        split="val"+suffix,
+                                        predicted_indices=ind
+                                        )
+
+        discloss, log_dict_disc = self.loss(qloss, x, xrec, 1,
+                                            self.global_step,
+                                            last_layer=self.get_last_layer(),
+                                            split="val"+suffix,
+                                            predicted_indices=ind
+                                            )
+        rec_loss = log_dict_ae[f"val{suffix}/rec_loss"]
+        self.log(f"val{suffix}/rec_loss", rec_loss,
+                   prog_bar=True, logger=True, on_step=False, on_epoch=True, sync_dist=True)
+        self.log(f"val{suffix}/aeloss", aeloss,
+                   prog_bar=True, logger=True, on_step=False, on_epoch=True, sync_dist=True)
+        if version.parse(pl.__version__) >= version.parse('1.4.0'):
+            del log_dict_ae[f"val{suffix}/rec_loss"]
+        self.log_dict(log_dict_ae)
+        self.log_dict(log_dict_disc)
+        return self.log_dict
+
+    def configure_optimizers(self):
+        lr_d = self.learning_rate
+        lr_g = self.lr_g_factor*self.learning_rate
+        print("lr_d", lr_d)
+        print("lr_g", lr_g)
+        opt_ae = torch.optim.Adam(list(self.encoder.parameters())+
+                                  list(self.decoder.parameters())+
+                                  list(self.quantize.parameters())+
+                                  list(self.quant_conv.parameters())+
+                                  list(self.post_quant_conv.parameters()),
+                                  lr=lr_g, betas=(0.5, 0.9))
+        opt_disc = torch.optim.Adam(self.loss.discriminator.parameters(),
+                                    lr=lr_d, betas=(0.5, 0.9))
+
+        if self.scheduler_config is not None:
+            scheduler = instantiate_from_config(self.scheduler_config)
+
+            print("Setting up LambdaLR scheduler...")
+            scheduler = [
+                {
+                    'scheduler': LambdaLR(opt_ae, lr_lambda=scheduler.schedule),
+                    'interval': 'step',
+                    'frequency': 1
+                },
+                {
+                    'scheduler': LambdaLR(opt_disc, lr_lambda=scheduler.schedule),
+                    'interval': 'step',
+                    'frequency': 1
+                },
+            ]
+            return [opt_ae, opt_disc], scheduler
+        return [opt_ae, opt_disc], []
+
+    def get_last_layer(self):
+        return self.decoder.conv_out.weight
+
+    def log_images(self, batch, only_inputs=False, plot_ema=False, **kwargs):
+        log = dict()
+        x = self.get_input(batch, self.image_key)
+        x = x.to(self.device)
+        if only_inputs:
+            log["inputs"] = x
+            return log
+        xrec, _ = self(x)
+        if x.shape[1] > 3:
+            # colorize with random projection
+            assert xrec.shape[1] > 3
+            x = self.to_rgb(x)
+            xrec = self.to_rgb(xrec)
+        log["inputs"] = x
+        log["reconstructions"] = xrec
+        if plot_ema:
+            with self.ema_scope():
+                xrec_ema, _ = self(x)
+                if x.shape[1] > 3: xrec_ema = self.to_rgb(xrec_ema)
+                log["reconstructions_ema"] = xrec_ema
+        return log
+
+    def to_rgb(self, x):
+        assert self.image_key == "segmentation"
+        if not hasattr(self, "colorize"):
+            self.register_buffer("colorize", torch.randn(3, x.shape[1], 1, 1).to(x))
+        x = F.conv2d(x, weight=self.colorize)
+        x = 2.*(x-x.min())/(x.max()-x.min()) - 1.
+        return x
+
+
+class VQModelInterface(VQModel):
+    def __init__(self, embed_dim, *args, **kwargs):
+        super().__init__(embed_dim=embed_dim, *args, **kwargs)
+        self.embed_dim = embed_dim
+
+    def encode(self, x):
+        h = self.encoder(x)
+        h = self.quant_conv(h)
+        return h
+
+    def decode(self, h, force_not_quantize=False):
+        # also go through quantization layer
+        if not force_not_quantize:
+            quant, emb_loss, info = self.quantize(h)
+        else:
+            quant = h
+        quant = self.post_quant_conv(quant)
+        dec = self.decoder(quant)
+        return dec
+
+
+class AutoencoderKL(pl.LightningModule):
+    def __init__(self,
+                 ddconfig,
+                 lossconfig,
+                 embed_dim,
+                 ckpt_path=None,
+                 ignore_keys=[],
+                 image_key="image",
+                 colorize_nlabels=None,
+                 monitor=None,
+                 ):
+        super().__init__()
+        self.image_key = image_key
+        self.encoder = Encoder(**ddconfig)
+        self.decoder = Decoder(**ddconfig)
+        self.loss = instantiate_from_config(lossconfig)
+        assert ddconfig["double_z"]
+        self.quant_conv = torch.nn.Conv2d(2*ddconfig["z_channels"], 2*embed_dim, 1)
+        self.post_quant_conv = torch.nn.Conv2d(embed_dim, ddconfig["z_channels"], 1)
+        self.embed_dim = embed_dim
+        if colorize_nlabels is not None:
+            assert type(colorize_nlabels)==int
+            self.register_buffer("colorize", torch.randn(3, colorize_nlabels, 1, 1))
+        if monitor is not None:
+            self.monitor = monitor
+        if ckpt_path is not None:
+            self.init_from_ckpt(ckpt_path, ignore_keys=ignore_keys)
+
+    def init_from_ckpt(self, path, ignore_keys=list()):
+        sd = torch.load(path, map_location="cpu")["state_dict"]
+        keys = list(sd.keys())
+        for k in keys:
+            for ik in ignore_keys:
+                if k.startswith(ik):
+                    print("Deleting key {} from state_dict.".format(k))
+                    del sd[k]
+        self.load_state_dict(sd, strict=False)
+        print(f"Restored from {path}")
+
+    def encode(self, x):
+        h = self.encoder(x)
+        moments = self.quant_conv(h)
+        posterior = DiagonalGaussianDistribution(moments)
+        return posterior
+
+    def decode(self, z):
+        z = self.post_quant_conv(z)
+        dec = self.decoder(z)
+        return dec
+
+    def forward(self, input, sample_posterior=True):
+        posterior = self.encode(input)
+        if sample_posterior:
+            z = posterior.sample()
+        else:
+            z = posterior.mode()
+        dec = self.decode(z)
+        return dec, posterior
+
+    def get_input(self, batch, k):
+        x = batch[k]
+        if len(x.shape) == 3:
+            x = x[..., None]
+        x = x.permute(0, 3, 1, 2).to(memory_format=torch.contiguous_format).float()
+        return x
+
+    def training_step(self, batch, batch_idx, optimizer_idx):
+        inputs = self.get_input(batch, self.image_key)
+        reconstructions, posterior = self(inputs)
+
+        if optimizer_idx == 0:
+            # train encoder+decoder+logvar
+            aeloss, log_dict_ae = self.loss(inputs, reconstructions, posterior, optimizer_idx, self.global_step,
+                                            last_layer=self.get_last_layer(), split="train")
+            self.log("aeloss", aeloss, prog_bar=True, logger=True, on_step=True, on_epoch=True)
+            self.log_dict(log_dict_ae, prog_bar=False, logger=True, on_step=True, on_epoch=False)
+            return aeloss
+
+        if optimizer_idx == 1:
+            # train the discriminator
+            discloss, log_dict_disc = self.loss(inputs, reconstructions, posterior, optimizer_idx, self.global_step,
+                                                last_layer=self.get_last_layer(), split="train")
+
+            self.log("discloss", discloss, prog_bar=True, logger=True, on_step=True, on_epoch=True)
+            self.log_dict(log_dict_disc, prog_bar=False, logger=True, on_step=True, on_epoch=False)
+            return discloss
+
+    def validation_step(self, batch, batch_idx):
+        inputs = self.get_input(batch, self.image_key)
+        reconstructions, posterior = self(inputs)
+        aeloss, log_dict_ae = self.loss(inputs, reconstructions, posterior, 0, self.global_step,
+                                        last_layer=self.get_last_layer(), split="val")
+
+        discloss, log_dict_disc = self.loss(inputs, reconstructions, posterior, 1, self.global_step,
+                                            last_layer=self.get_last_layer(), split="val")
+
+        self.log("val/rec_loss", log_dict_ae["val/rec_loss"])
+        self.log_dict(log_dict_ae)
+        self.log_dict(log_dict_disc)
+        return self.log_dict
+
+    def configure_optimizers(self):
+        lr = self.learning_rate
+        opt_ae = torch.optim.Adam(list(self.encoder.parameters())+
+                                  list(self.decoder.parameters())+
+                                  list(self.quant_conv.parameters())+
+                                  list(self.post_quant_conv.parameters()),
+                                  lr=lr, betas=(0.5, 0.9))
+        opt_disc = torch.optim.Adam(self.loss.discriminator.parameters(),
+                                    lr=lr, betas=(0.5, 0.9))
+        return [opt_ae, opt_disc], []
+
+    def get_last_layer(self):
+        return self.decoder.conv_out.weight
+
+    @torch.no_grad()
+    def log_images(self, batch, only_inputs=False, **kwargs):
+        log = dict()
+        x = self.get_input(batch, self.image_key)
+        x = x.to(self.device)
+        if not only_inputs:
+            xrec, posterior = self(x)
+            if x.shape[1] > 3:
+                # colorize with random projection
+                assert xrec.shape[1] > 3
+                x = self.to_rgb(x)
+                xrec = self.to_rgb(xrec)
+            log["samples"] = self.decode(torch.randn_like(posterior.sample()))
+            log["reconstructions"] = xrec
+        log["inputs"] = x
+        return log
+
+    def to_rgb(self, x):
+        assert self.image_key == "segmentation"
+        if not hasattr(self, "colorize"):
+            self.register_buffer("colorize", torch.randn(3, x.shape[1], 1, 1).to(x))
+        x = F.conv2d(x, weight=self.colorize)
+        x = 2.*(x-x.min())/(x.max()-x.min()) - 1.
+        return x
+
+
+class IdentityFirstStage(torch.nn.Module):
+    def __init__(self, *args, vq_interface=False, **kwargs):
+        self.vq_interface = vq_interface  # TODO: Should be true by default but check to not break older stuff
+        super().__init__()
+
+    def encode(self, x, *args, **kwargs):
+        return x
+
+    def decode(self, x, *args, **kwargs):
+        return x
+
+    def quantize(self, x, *args, **kwargs):
+        if self.vq_interface:
+            return x, None, [None, None, None]
+        return x
+
+    def forward(self, x, *args, **kwargs):
+        return x

+ 0 - 0
ldm/models/diffusion/__init__.py


+ 267 - 0
ldm/models/diffusion/classifier.py

@@ -0,0 +1,267 @@
+import os
+import torch
+import pytorch_lightning as pl
+from omegaconf import OmegaConf
+from torch.nn import functional as F
+from torch.optim import AdamW
+from torch.optim.lr_scheduler import LambdaLR
+from copy import deepcopy
+from einops import rearrange
+from glob import glob
+from natsort import natsorted
+
+from ldm.modules.diffusionmodules.openaimodel import EncoderUNetModel, UNetModel
+from ldm.util import log_txt_as_img, default, ismap, instantiate_from_config
+
+__models__ = {
+    'class_label': EncoderUNetModel,
+    'segmentation': UNetModel
+}
+
+
+def disabled_train(self, mode=True):
+    """Overwrite model.train with this function to make sure train/eval mode
+    does not change anymore."""
+    return self
+
+
+class NoisyLatentImageClassifier(pl.LightningModule):
+
+    def __init__(self,
+                 diffusion_path,
+                 num_classes,
+                 ckpt_path=None,
+                 pool='attention',
+                 label_key=None,
+                 diffusion_ckpt_path=None,
+                 scheduler_config=None,
+                 weight_decay=1.e-2,
+                 log_steps=10,
+                 monitor='val/loss',
+                 *args,
+                 **kwargs):
+        super().__init__(*args, **kwargs)
+        self.num_classes = num_classes
+        # get latest config of diffusion model
+        diffusion_config = natsorted(glob(os.path.join(diffusion_path, 'configs', '*-project.yaml')))[-1]
+        self.diffusion_config = OmegaConf.load(diffusion_config).model
+        self.diffusion_config.params.ckpt_path = diffusion_ckpt_path
+        self.load_diffusion()
+
+        self.monitor = monitor
+        self.numd = self.diffusion_model.first_stage_model.encoder.num_resolutions - 1
+        self.log_time_interval = self.diffusion_model.num_timesteps // log_steps
+        self.log_steps = log_steps
+
+        self.label_key = label_key if not hasattr(self.diffusion_model, 'cond_stage_key') \
+            else self.diffusion_model.cond_stage_key
+
+        assert self.label_key is not None, 'label_key neither in diffusion model nor in model.params'
+
+        if self.label_key not in __models__:
+            raise NotImplementedError()
+
+        self.load_classifier(ckpt_path, pool)
+
+        self.scheduler_config = scheduler_config
+        self.use_scheduler = self.scheduler_config is not None
+        self.weight_decay = weight_decay
+
+    def init_from_ckpt(self, path, ignore_keys=list(), only_model=False):
+        sd = torch.load(path, map_location="cpu")
+        if "state_dict" in list(sd.keys()):
+            sd = sd["state_dict"]
+        keys = list(sd.keys())
+        for k in keys:
+            for ik in ignore_keys:
+                if k.startswith(ik):
+                    print("Deleting key {} from state_dict.".format(k))
+                    del sd[k]
+        missing, unexpected = self.load_state_dict(sd, strict=False) if not only_model else self.model.load_state_dict(
+            sd, strict=False)
+        print(f"Restored from {path} with {len(missing)} missing and {len(unexpected)} unexpected keys")
+        if len(missing) > 0:
+            print(f"Missing Keys: {missing}")
+        if len(unexpected) > 0:
+            print(f"Unexpected Keys: {unexpected}")
+
+    def load_diffusion(self):
+        model = instantiate_from_config(self.diffusion_config)
+        self.diffusion_model = model.eval()
+        self.diffusion_model.train = disabled_train
+        for param in self.diffusion_model.parameters():
+            param.requires_grad = False
+
+    def load_classifier(self, ckpt_path, pool):
+        model_config = deepcopy(self.diffusion_config.params.unet_config.params)
+        model_config.in_channels = self.diffusion_config.params.unet_config.params.out_channels
+        model_config.out_channels = self.num_classes
+        if self.label_key == 'class_label':
+            model_config.pool = pool
+
+        self.model = __models__[self.label_key](**model_config)
+        if ckpt_path is not None:
+            print('#####################################################################')
+            print(f'load from ckpt "{ckpt_path}"')
+            print('#####################################################################')
+            self.init_from_ckpt(ckpt_path)
+
+    @torch.no_grad()
+    def get_x_noisy(self, x, t, noise=None):
+        noise = default(noise, lambda: torch.randn_like(x))
+        continuous_sqrt_alpha_cumprod = None
+        if self.diffusion_model.use_continuous_noise:
+            continuous_sqrt_alpha_cumprod = self.diffusion_model.sample_continuous_noise_level(x.shape[0], t + 1)
+            # todo: make sure t+1 is correct here
+
+        return self.diffusion_model.q_sample(x_start=x, t=t, noise=noise,
+                                             continuous_sqrt_alpha_cumprod=continuous_sqrt_alpha_cumprod)
+
+    def forward(self, x_noisy, t, *args, **kwargs):
+        return self.model(x_noisy, t)
+
+    @torch.no_grad()
+    def get_input(self, batch, k):
+        x = batch[k]
+        if len(x.shape) == 3:
+            x = x[..., None]
+        x = rearrange(x, 'b h w c -> b c h w')
+        x = x.to(memory_format=torch.contiguous_format).float()
+        return x
+
+    @torch.no_grad()
+    def get_conditioning(self, batch, k=None):
+        if k is None:
+            k = self.label_key
+        assert k is not None, 'Needs to provide label key'
+
+        targets = batch[k].to(self.device)
+
+        if self.label_key == 'segmentation':
+            targets = rearrange(targets, 'b h w c -> b c h w')
+            for down in range(self.numd):
+                h, w = targets.shape[-2:]
+                targets = F.interpolate(targets, size=(h // 2, w // 2), mode='nearest')
+
+            # targets = rearrange(targets,'b c h w -> b h w c')
+
+        return targets
+
+    def compute_top_k(self, logits, labels, k, reduction="mean"):
+        _, top_ks = torch.topk(logits, k, dim=1)
+        if reduction == "mean":
+            return (top_ks == labels[:, None]).float().sum(dim=-1).mean().item()
+        elif reduction == "none":
+            return (top_ks == labels[:, None]).float().sum(dim=-1)
+
+    def on_train_epoch_start(self):
+        # save some memory
+        self.diffusion_model.model.to('cpu')
+
+    @torch.no_grad()
+    def write_logs(self, loss, logits, targets):
+        log_prefix = 'train' if self.training else 'val'
+        log = {}
+        log[f"{log_prefix}/loss"] = loss.mean()
+        log[f"{log_prefix}/acc@1"] = self.compute_top_k(
+            logits, targets, k=1, reduction="mean"
+        )
+        log[f"{log_prefix}/acc@5"] = self.compute_top_k(
+            logits, targets, k=5, reduction="mean"
+        )
+
+        self.log_dict(log, prog_bar=False, logger=True, on_step=self.training, on_epoch=True)
+        self.log('loss', log[f"{log_prefix}/loss"], prog_bar=True, logger=False)
+        self.log('global_step', self.global_step, logger=False, on_epoch=False, prog_bar=True)
+        lr = self.optimizers().param_groups[0]['lr']
+        self.log('lr_abs', lr, on_step=True, logger=True, on_epoch=False, prog_bar=True)
+
+    def shared_step(self, batch, t=None):
+        x, *_ = self.diffusion_model.get_input(batch, k=self.diffusion_model.first_stage_key)
+        targets = self.get_conditioning(batch)
+        if targets.dim() == 4:
+            targets = targets.argmax(dim=1)
+        if t is None:
+            t = torch.randint(0, self.diffusion_model.num_timesteps, (x.shape[0],), device=self.device).long()
+        else:
+            t = torch.full(size=(x.shape[0],), fill_value=t, device=self.device).long()
+        x_noisy = self.get_x_noisy(x, t)
+        logits = self(x_noisy, t)
+
+        loss = F.cross_entropy(logits, targets, reduction='none')
+
+        self.write_logs(loss.detach(), logits.detach(), targets.detach())
+
+        loss = loss.mean()
+        return loss, logits, x_noisy, targets
+
+    def training_step(self, batch, batch_idx):
+        loss, *_ = self.shared_step(batch)
+        return loss
+
+    def reset_noise_accs(self):
+        self.noisy_acc = {t: {'acc@1': [], 'acc@5': []} for t in
+                          range(0, self.diffusion_model.num_timesteps, self.diffusion_model.log_every_t)}
+
+    def on_validation_start(self):
+        self.reset_noise_accs()
+
+    @torch.no_grad()
+    def validation_step(self, batch, batch_idx):
+        loss, *_ = self.shared_step(batch)
+
+        for t in self.noisy_acc:
+            _, logits, _, targets = self.shared_step(batch, t)
+            self.noisy_acc[t]['acc@1'].append(self.compute_top_k(logits, targets, k=1, reduction='mean'))
+            self.noisy_acc[t]['acc@5'].append(self.compute_top_k(logits, targets, k=5, reduction='mean'))
+
+        return loss
+
+    def configure_optimizers(self):
+        optimizer = AdamW(self.model.parameters(), lr=self.learning_rate, weight_decay=self.weight_decay)
+
+        if self.use_scheduler:
+            scheduler = instantiate_from_config(self.scheduler_config)
+
+            print("Setting up LambdaLR scheduler...")
+            scheduler = [
+                {
+                    'scheduler': LambdaLR(optimizer, lr_lambda=scheduler.schedule),
+                    'interval': 'step',
+                    'frequency': 1
+                }]
+            return [optimizer], scheduler
+
+        return optimizer
+
+    @torch.no_grad()
+    def log_images(self, batch, N=8, *args, **kwargs):
+        log = dict()
+        x = self.get_input(batch, self.diffusion_model.first_stage_key)
+        log['inputs'] = x
+
+        y = self.get_conditioning(batch)
+
+        if self.label_key == 'class_label':
+            y = log_txt_as_img((x.shape[2], x.shape[3]), batch["human_label"])
+            log['labels'] = y
+
+        if ismap(y):
+            log['labels'] = self.diffusion_model.to_rgb(y)
+
+            for step in range(self.log_steps):
+                current_time = step * self.log_time_interval
+
+                _, logits, x_noisy, _ = self.shared_step(batch, t=current_time)
+
+                log[f'inputs@t{current_time}'] = x_noisy
+
+                pred = F.one_hot(logits.argmax(dim=1), num_classes=self.num_classes)
+                pred = rearrange(pred, 'b h w c -> b c h w')
+
+                log[f'pred@t{current_time}'] = self.diffusion_model.to_rgb(pred)
+
+        for key in log:
+            log[key] = log[key][:N]
+
+        return log

+ 186 - 0
ldm/models/diffusion/ddim.py

@@ -0,0 +1,186 @@
+"""SAMPLING ONLY."""
+
+import torch
+import numpy as np
+from tqdm import tqdm
+from functools import partial
+
+from ldm.models.diffusion.ddpm import noise_like
+from ldm.modules.diffusionmodules.util import make_ddim_sampling_parameters, make_ddim_timesteps
+
+
+class DDIMSampler(object):
+    def __init__(self, model, schedule="linear", **kwargs):
+        super().__init__()
+        self.model = model
+        self.ddpm_num_timesteps = model.num_timesteps
+        self.schedule = schedule
+
+    def register_buffer(self, name, attr):
+        if type(attr) == torch.Tensor:
+            if attr.device != torch.device("cuda"):
+                attr = attr.to(torch.device("cuda"))
+        setattr(self, name, attr)
+
+    def make_schedule(self, ddim_num_steps, ddim_discretize="uniform", ddim_eta=0., verbose=True):
+        self.ddim_timesteps = make_ddim_timesteps(ddim_discr_method=ddim_discretize, num_ddim_timesteps=ddim_num_steps,
+                                                  num_ddpm_timesteps=self.ddpm_num_timesteps,verbose=verbose)
+        alphas_cumprod = self.model.alphas_cumprod
+        assert alphas_cumprod.shape[0] == self.ddpm_num_timesteps, 'alphas have to be defined for each timestep'
+
+        to_torch = partial(torch.tensor, dtype=torch.float32, device=self.model.device)
+
+        self.register_buffer('betas', to_torch(self.model.betas))
+        self.register_buffer('alphas_cumprod', to_torch(alphas_cumprod))
+        self.register_buffer('alphas_cumprod_prev', to_torch(self.model.alphas_cumprod_prev))
+
+        # calculations for diffusion q(x_t | x_{t-1}) and others
+        self.register_buffer('sqrt_alphas_cumprod', to_torch(np.sqrt(alphas_cumprod.cpu())))
+        self.register_buffer('sqrt_one_minus_alphas_cumprod', to_torch(np.sqrt(1. - alphas_cumprod.cpu())))
+        self.register_buffer('log_one_minus_alphas_cumprod', to_torch(np.log(1. - alphas_cumprod.cpu())))
+        self.register_buffer('sqrt_recip_alphas_cumprod', to_torch(np.sqrt(1. / alphas_cumprod.cpu())))
+        self.register_buffer('sqrt_recipm1_alphas_cumprod', to_torch(np.sqrt(1. / alphas_cumprod.cpu() - 1)))
+
+        # ddim sampling parameters
+        ddim_sigmas, ddim_alphas, ddim_alphas_prev = make_ddim_sampling_parameters(alphacums=alphas_cumprod.cpu(),
+                                                                                   ddim_timesteps=self.ddim_timesteps,
+                                                                                   eta=ddim_eta,verbose=verbose)
+        self.register_buffer('ddim_sigmas', ddim_sigmas)
+        self.register_buffer('ddim_alphas', ddim_alphas)
+        self.register_buffer('ddim_alphas_prev', ddim_alphas_prev)
+        self.register_buffer('ddim_sqrt_one_minus_alphas', np.sqrt(1. - ddim_alphas))
+        sigmas_for_original_sampling_steps = ddim_eta * torch.sqrt(
+            (1 - self.alphas_cumprod_prev) / (1 - self.alphas_cumprod) * (
+                        1 - self.alphas_cumprod / self.alphas_cumprod_prev))
+        self.register_buffer('ddim_sigmas_for_original_num_steps', sigmas_for_original_sampling_steps)
+
+    @torch.no_grad()
+    def sample(self,
+               S,
+               batch_size,
+               shape,
+               conditioning=None,
+               callback=None,
+               normals_sequence=None,
+               img_callback=None,
+               quantize_x0=False,
+               eta=0.,
+               mask=None,
+               x0=None,
+               temperature=1.,
+               noise_dropout=0.,
+               score_corrector=None,
+               corrector_kwargs=None,
+               verbose=True,
+               x_T=None,
+               log_every_t=100
+               ):
+        if conditioning is not None:
+            if isinstance(conditioning, dict):
+                cbs = conditioning[list(conditioning.keys())[0]].shape[0]
+                if cbs != batch_size:
+                    print(f"Warning: Got {cbs} conditionings but batch-size is {batch_size}")
+            else:
+                if conditioning.shape[0] != batch_size:
+                    print(f"Warning: Got {conditioning.shape[0]} conditionings but batch-size is {batch_size}")
+
+        self.make_schedule(ddim_num_steps=S, ddim_eta=eta, verbose=verbose)
+        # sampling
+        C, H, W = shape
+        size = (batch_size, C, H, W)
+        print(f'Data shape for DDIM sampling is {size}, eta {eta}')
+
+        samples, intermediates = self.ddim_sampling(conditioning, size,
+                                                    callback=callback,
+                                                    img_callback=img_callback,
+                                                    quantize_denoised=quantize_x0,
+                                                    mask=mask, x0=x0,
+                                                    ddim_use_original_steps=False,
+                                                    noise_dropout=noise_dropout,
+                                                    temperature=temperature,
+                                                    score_corrector=score_corrector,
+                                                    corrector_kwargs=corrector_kwargs,
+                                                    x_T=x_T,
+                                                    log_every_t=log_every_t
+                                                    )
+        return samples, intermediates
+
+    @torch.no_grad()
+    def ddim_sampling(self, cond, shape,
+                      x_T=None, ddim_use_original_steps=False,
+                      callback=None, timesteps=None, quantize_denoised=False,
+                      mask=None, x0=None, img_callback=None, log_every_t=100,
+                      temperature=1., noise_dropout=0., score_corrector=None, corrector_kwargs=None):
+        device = self.model.betas.device
+        b = shape[0]
+        if x_T is None:
+            img = torch.randn(shape, device=device)
+        else:
+            img = x_T
+
+        if timesteps is None:
+            timesteps = self.ddpm_num_timesteps if ddim_use_original_steps else self.ddim_timesteps
+        elif timesteps is not None and not ddim_use_original_steps:
+            subset_end = int(min(timesteps / self.ddim_timesteps.shape[0], 1) * self.ddim_timesteps.shape[0]) - 1
+            timesteps = self.ddim_timesteps[:subset_end]
+
+        intermediates = {'x_inter': [img], 'pred_x0': [img]}
+        time_range = reversed(range(0,timesteps)) if ddim_use_original_steps else np.flip(timesteps)
+        total_steps = timesteps if ddim_use_original_steps else timesteps.shape[0]
+        print(f"Running DDIM Sampling with {total_steps} timesteps")
+
+        iterator = tqdm(time_range, desc='DDIM Sampler', total=total_steps)
+
+        for i, step in enumerate(iterator):
+            index = total_steps - i - 1
+            ts = torch.full((b,), step, device=device, dtype=torch.long)
+
+            if mask is not None:
+                assert x0 is not None
+                img_orig = self.model.q_sample(x0, ts)  # TODO: deterministic forward pass?
+                img = img_orig * mask + (1. - mask) * img
+
+            outs = self.p_sample_ddim(img, cond, ts, index=index, use_original_steps=ddim_use_original_steps,
+                                      quantize_denoised=quantize_denoised, temperature=temperature,
+                                      noise_dropout=noise_dropout, score_corrector=score_corrector,
+                                      corrector_kwargs=corrector_kwargs)
+            img, pred_x0 = outs
+            if callback: callback(i)
+            if img_callback: img_callback(pred_x0, i)
+
+            if index % log_every_t == 0 or index == total_steps - 1:
+                intermediates['x_inter'].append(img)
+                intermediates['pred_x0'].append(pred_x0)
+
+        return img, intermediates
+
+    @torch.no_grad()
+    def p_sample_ddim(self, x, c, t, index, repeat_noise=False, use_original_steps=False, quantize_denoised=False,
+                      temperature=1., noise_dropout=0., score_corrector=None, corrector_kwargs=None):
+        b, *_, device = *x.shape, x.device
+        e_t = self.model.apply_model(x, t, c)
+        if score_corrector is not None:
+            assert self.model.parameterization == "eps"
+            e_t = score_corrector.modify_score(self.model, e_t, x, t, c, **corrector_kwargs)
+
+        alphas = self.model.alphas_cumprod if use_original_steps else self.ddim_alphas
+        alphas_prev = self.model.alphas_cumprod_prev if use_original_steps else self.ddim_alphas_prev
+        sqrt_one_minus_alphas = self.model.sqrt_one_minus_alphas_cumprod if use_original_steps else self.ddim_sqrt_one_minus_alphas
+        sigmas = self.model.ddim_sigmas_for_original_num_steps if use_original_steps else self.ddim_sigmas
+        # select parameters corresponding to the currently considered timestep
+        a_t = torch.full((b, 1, 1, 1), alphas[index], device=device)
+        a_prev = torch.full((b, 1, 1, 1), alphas_prev[index], device=device)
+        sigma_t = torch.full((b, 1, 1, 1), sigmas[index], device=device)
+        sqrt_one_minus_at = torch.full((b, 1, 1, 1), sqrt_one_minus_alphas[index],device=device)
+
+        # current prediction for x_0
+        pred_x0 = (x - sqrt_one_minus_at * e_t) / a_t.sqrt()
+        if quantize_denoised:
+            pred_x0, _, *_ = self.model.first_stage_model.quantize(pred_x0)
+        # direction pointing to x_t
+        dir_xt = (1. - a_prev - sigma_t**2).sqrt() * e_t
+        noise = sigma_t * noise_like(x.shape, device, repeat_noise) * temperature
+        if noise_dropout > 0.:
+            noise = torch.nn.functional.dropout(noise, p=noise_dropout)
+        x_prev = a_prev.sqrt() * pred_x0 + dir_xt + noise
+        return x_prev, pred_x0

+ 1430 - 0
ldm/models/diffusion/ddpm.py

@@ -0,0 +1,1430 @@
+"""
+wild mixture of
+https://github.com/lucidrains/denoising-diffusion-pytorch/blob/7706bdfc6f527f58d33f84b7b522e61e6e3164b3/denoising_diffusion_pytorch/denoising_diffusion_pytorch.py
+https://github.com/openai/improved-diffusion/blob/e94489283bb876ac1477d5dd7709bbbd2d9902ce/improved_diffusion/gaussian_diffusion.py
+https://github.com/CompVis/taming-transformers
+-- merci
+"""
+
+import torch
+import torch.nn as nn
+import numpy as np
+import pytorch_lightning as pl
+from torch.optim.lr_scheduler import LambdaLR
+from einops import rearrange, repeat
+from contextlib import contextmanager
+from functools import partial
+from tqdm import tqdm
+from torchvision.utils import make_grid
+from PIL import Image
+from pytorch_lightning.utilities.distributed import rank_zero_only
+
+from ldm.util import log_txt_as_img, exists, default, ismap, isimage, mean_flat, count_params, instantiate_from_config
+from ldm.modules.ema import LitEma
+from ldm.modules.distributions.distributions import normal_kl, DiagonalGaussianDistribution
+from ldm.models.autoencoder import VQModelInterface, IdentityFirstStage, AutoencoderKL
+from ldm.modules.diffusionmodules.util import make_beta_schedule, extract_into_tensor
+
+
+__conditioning_keys__ = {'concat': 'c_concat',
+                         'crossattn': 'c_crossattn',
+                         'adm': 'y'}
+
+
+def disabled_train(self, mode=True):
+    """Overwrite model.train with this function to make sure train/eval mode
+    does not change anymore."""
+    return self
+
+
+def noise_like(shape, device, repeat=False):
+    repeat_noise = lambda: torch.randn((1, *shape[1:]), device=device).repeat(shape[0], *((1,) * (len(shape) - 1)))
+    noise = lambda: torch.randn(shape, device=device)
+    return repeat_noise() if repeat else noise()
+
+
+def uniform_on_device(r1, r2, shape, device):
+    return (r1 - r2) * torch.rand(*shape, device=device) + r2
+
+
+class DDPM(pl.LightningModule):
+    # classic DDPM with Gaussian diffusion, in image space
+    def __init__(self,
+                 unet_config,
+                 timesteps=1000,
+                 beta_schedule="linear",
+                 loss_type="l2",
+                 ckpt_path=None,
+                 ignore_keys=[],
+                 load_only_unet=False,
+                 monitor="val/loss",
+                 use_ema=True,
+                 first_stage_key="image",
+                 image_size=256,
+                 channels=3,
+                 log_every_t=100,
+                 clip_denoised=True,
+                 linear_start=1e-4,
+                 linear_end=2e-2,
+                 cosine_s=8e-3,
+                 given_betas=None,
+                 original_elbo_weight=0.,
+                 v_posterior=0.,  # weight for choosing posterior variance as sigma = (1-v) * beta_tilde + v * beta
+                 l_simple_weight=1.,
+                 conditioning_key=None,
+                 parameterization="eps",  # all assuming fixed variance schedules
+                 scheduler_config=None,
+                 use_positional_encodings=False,
+                 learn_logvar=False,
+                 logvar_init=0.,
+                 ):
+        super().__init__()
+        assert parameterization in ["eps", "x0"], 'currently only supporting "eps" and "x0"'
+        self.parameterization = parameterization
+        print(f"{self.__class__.__name__}: Running in {self.parameterization}-prediction mode")
+        self.cond_stage_model = None
+        self.clip_denoised = clip_denoised
+        self.log_every_t = log_every_t
+        self.first_stage_key = first_stage_key
+        self.image_size = image_size  # try conv?
+        self.channels = channels
+        self.use_positional_encodings = use_positional_encodings
+        self.model = DiffusionWrapper(unet_config, conditioning_key)
+        count_params(self.model, verbose=True)
+        self.use_ema = use_ema
+        if self.use_ema:
+            self.model_ema = LitEma(self.model)
+            print(f"Keeping EMAs of {len(list(self.model_ema.buffers()))}.")
+
+        self.use_scheduler = scheduler_config is not None
+        if self.use_scheduler:
+            self.scheduler_config = scheduler_config
+
+        self.v_posterior = v_posterior
+        self.original_elbo_weight = original_elbo_weight
+        self.l_simple_weight = l_simple_weight
+
+        if monitor is not None:
+            self.monitor = monitor
+        if ckpt_path is not None:
+            self.init_from_ckpt(ckpt_path, ignore_keys=ignore_keys, only_model=load_only_unet)
+
+        self.register_schedule(given_betas=given_betas, beta_schedule=beta_schedule, timesteps=timesteps,
+                               linear_start=linear_start, linear_end=linear_end, cosine_s=cosine_s)
+
+        self.loss_type = loss_type
+
+        self.learn_logvar = learn_logvar
+        self.logvar = torch.full(fill_value=logvar_init, size=(self.num_timesteps,))
+        if self.learn_logvar:
+            self.logvar = nn.Parameter(self.logvar, requires_grad=True)
+
+    def register_schedule(self, given_betas=None, beta_schedule="linear", timesteps=1000,
+                          linear_start=1e-4, linear_end=2e-2, cosine_s=8e-3):
+        if exists(given_betas):
+            betas = given_betas
+        else:
+            betas = make_beta_schedule(beta_schedule, timesteps, linear_start=linear_start, linear_end=linear_end,
+                                       cosine_s=cosine_s)
+        alphas = 1. - betas
+        alphas_cumprod = np.cumprod(alphas, axis=0)
+        alphas_cumprod_prev = np.append(1., alphas_cumprod[:-1])
+
+        timesteps, = betas.shape
+        self.num_timesteps = int(timesteps)
+        self.linear_start = linear_start
+        self.linear_end = linear_end
+        assert alphas_cumprod.shape[0] == self.num_timesteps, 'alphas have to be defined for each timestep'
+
+        to_torch = partial(torch.tensor, dtype=torch.float32)
+
+        self.register_buffer('betas', to_torch(betas))
+        self.register_buffer('alphas_cumprod', to_torch(alphas_cumprod))
+        self.register_buffer('alphas_cumprod_prev', to_torch(alphas_cumprod_prev))
+
+        # calculations for diffusion q(x_t | x_{t-1}) and others
+        self.register_buffer('sqrt_alphas_cumprod', to_torch(np.sqrt(alphas_cumprod)))
+        self.register_buffer('sqrt_one_minus_alphas_cumprod', to_torch(np.sqrt(1. - alphas_cumprod)))
+        self.register_buffer('log_one_minus_alphas_cumprod', to_torch(np.log(1. - alphas_cumprod)))
+        self.register_buffer('sqrt_recip_alphas_cumprod', to_torch(np.sqrt(1. / alphas_cumprod)))
+        self.register_buffer('sqrt_recipm1_alphas_cumprod', to_torch(np.sqrt(1. / alphas_cumprod - 1)))
+
+        # calculations for posterior q(x_{t-1} | x_t, x_0)
+        posterior_variance = (1 - self.v_posterior) * betas * (1. - alphas_cumprod_prev) / (
+                    1. - alphas_cumprod) + self.v_posterior * betas
+        # above: equal to 1. / (1. / (1. - alpha_cumprod_tm1) + alpha_t / beta_t)
+        self.register_buffer('posterior_variance', to_torch(posterior_variance))
+        # below: log calculation clipped because the posterior variance is 0 at the beginning of the diffusion chain
+        self.register_buffer('posterior_log_variance_clipped', to_torch(np.log(np.maximum(posterior_variance, 1e-20))))
+        self.register_buffer('posterior_mean_coef1', to_torch(
+            betas * np.sqrt(alphas_cumprod_prev) / (1. - alphas_cumprod)))
+        self.register_buffer('posterior_mean_coef2', to_torch(
+            (1. - alphas_cumprod_prev) * np.sqrt(alphas) / (1. - alphas_cumprod)))
+
+        if self.parameterization == "eps":
+            lvlb_weights = self.betas ** 2 / (
+                        2 * self.posterior_variance * to_torch(alphas) * (1 - self.alphas_cumprod))
+        elif self.parameterization == "x0":
+            lvlb_weights = 0.5 * np.sqrt(torch.Tensor(alphas_cumprod)) / (2. * 1 - torch.Tensor(alphas_cumprod))
+        else:
+            raise NotImplementedError("mu not supported")
+        # TODO how to choose this term
+        lvlb_weights[0] = lvlb_weights[1]
+        self.register_buffer('lvlb_weights', lvlb_weights, persistent=False)
+        assert not torch.isnan(self.lvlb_weights).all()
+
+    @contextmanager
+    def ema_scope(self, context=None):
+        if self.use_ema:
+            self.model_ema.store(self.model.parameters())
+            self.model_ema.copy_to(self.model)
+            if context is not None:
+                print(f"{context}: Switched to EMA weights")
+        try:
+            yield None
+        finally:
+            if self.use_ema:
+                self.model_ema.restore(self.model.parameters())
+                if context is not None:
+                    print(f"{context}: Restored training weights")
+
+    def init_from_ckpt(self, path, ignore_keys=list(), only_model=False):
+        sd = torch.load(path, map_location="cpu")
+        if "state_dict" in list(sd.keys()):
+            sd = sd["state_dict"]
+        keys = list(sd.keys())
+        for k in keys:
+            for ik in ignore_keys:
+                if k.startswith(ik):
+                    print("Deleting key {} from state_dict.".format(k))
+                    del sd[k]
+        missing, unexpected = self.load_state_dict(sd, strict=False) if not only_model else self.model.load_state_dict(
+            sd, strict=False)
+        print(f"Restored from {path} with {len(missing)} missing and {len(unexpected)} unexpected keys")
+        if len(missing) > 0:
+            print(f"Missing Keys: {missing}")
+        if len(unexpected) > 0:
+            print(f"Unexpected Keys: {unexpected}")
+
+    def q_mean_variance(self, x_start, t):
+        """
+        Get the distribution q(x_t | x_0).
+        :param x_start: the [N x C x ...] tensor of noiseless inputs.
+        :param t: the number of diffusion steps (minus 1). Here, 0 means one step.
+        :return: A tuple (mean, variance, log_variance), all of x_start's shape.
+        """
+        mean = (extract_into_tensor(self.sqrt_alphas_cumprod, t, x_start.shape) * x_start)
+        variance = extract_into_tensor(1.0 - self.alphas_cumprod, t, x_start.shape)
+        log_variance = extract_into_tensor(self.log_one_minus_alphas_cumprod, t, x_start.shape)
+        return mean, variance, log_variance
+
+    def predict_start_from_noise(self, x_t, t, noise):
+        return (
+                extract_into_tensor(self.sqrt_recip_alphas_cumprod, t, x_t.shape) * x_t -
+                extract_into_tensor(self.sqrt_recipm1_alphas_cumprod, t, x_t.shape) * noise
+        )
+
+    def q_posterior(self, x_start, x_t, t):
+        posterior_mean = (
+                extract_into_tensor(self.posterior_mean_coef1, t, x_t.shape) * x_start +
+                extract_into_tensor(self.posterior_mean_coef2, t, x_t.shape) * x_t
+        )
+        posterior_variance = extract_into_tensor(self.posterior_variance, t, x_t.shape)
+        posterior_log_variance_clipped = extract_into_tensor(self.posterior_log_variance_clipped, t, x_t.shape)
+        return posterior_mean, posterior_variance, posterior_log_variance_clipped
+
+    def p_mean_variance(self, x, t, clip_denoised: bool):
+        model_out = self.model(x, t)
+        if self.parameterization == "eps":
+            x_recon = self.predict_start_from_noise(x, t=t, noise=model_out)
+        elif self.parameterization == "x0":
+            x_recon = model_out
+        if clip_denoised:
+            x_recon.clamp_(-1., 1.)
+
+        model_mean, posterior_variance, posterior_log_variance = self.q_posterior(x_start=x_recon, x_t=x, t=t)
+        return model_mean, posterior_variance, posterior_log_variance
+
+    @torch.no_grad()
+    def p_sample(self, x, t, clip_denoised=True, repeat_noise=False):
+        b, *_, device = *x.shape, x.device
+        model_mean, _, model_log_variance = self.p_mean_variance(x=x, t=t, clip_denoised=clip_denoised)
+        noise = noise_like(x.shape, device, repeat_noise)
+        # no noise when t == 0
+        nonzero_mask = (1 - (t == 0).float()).reshape(b, *((1,) * (len(x.shape) - 1)))
+        return model_mean + nonzero_mask * (0.5 * model_log_variance).exp() * noise
+
+    @torch.no_grad()
+    def p_sample_loop(self, shape, return_intermediates=False):
+        device = self.betas.device
+        b = shape[0]
+        img = torch.randn(shape, device=device)
+        intermediates = [img]
+        for i in tqdm(reversed(range(0, self.num_timesteps)), desc='Sampling t', total=self.num_timesteps):
+            img = self.p_sample(img, torch.full((b,), i, device=device, dtype=torch.long),
+                                clip_denoised=self.clip_denoised)
+            if i % self.log_every_t == 0 or i == self.num_timesteps - 1:
+                intermediates.append(img)
+        if return_intermediates:
+            return img, intermediates
+        return img
+
+    @torch.no_grad()
+    def sample(self, batch_size=16, return_intermediates=False):
+        image_size = self.image_size
+        channels = self.channels
+        return self.p_sample_loop((batch_size, channels, image_size, image_size),
+                                  return_intermediates=return_intermediates)
+
+    def q_sample(self, x_start, t, noise=None):
+        noise = default(noise, lambda: torch.randn_like(x_start))
+        return (extract_into_tensor(self.sqrt_alphas_cumprod, t, x_start.shape) * x_start +
+                extract_into_tensor(self.sqrt_one_minus_alphas_cumprod, t, x_start.shape) * noise)
+
+    def get_loss(self, pred, target, mean=True):
+        if self.loss_type == 'l1':
+            loss = (target - pred).abs()
+            if mean:
+                loss = loss.mean()
+        elif self.loss_type == 'l2':
+            if mean:
+                loss = torch.nn.functional.mse_loss(target, pred)
+            else:
+                loss = torch.nn.functional.mse_loss(target, pred, reduction='none')
+        else:
+            raise NotImplementedError("unknown loss type '{loss_type}'")
+
+        return loss
+
+    def p_losses(self, x_start, t, noise=None):
+        noise = default(noise, lambda: torch.randn_like(x_start))
+        x_noisy = self.q_sample(x_start=x_start, t=t, noise=noise)
+        model_out = self.model(x_noisy, t)
+
+        loss_dict = {}
+        if self.parameterization == "eps":
+            target = noise
+        elif self.parameterization == "x0":
+            target = x_start
+        else:
+            raise NotImplementedError(f"Paramterization {self.parameterization} not yet supported")
+
+        loss = self.get_loss(model_out, target, mean=False).mean(dim=[1, 2, 3])
+
+        log_prefix = 'train' if self.training else 'val'
+
+        loss_dict.update({f'{log_prefix}/loss_simple': loss.mean()})
+        loss_simple = loss.mean() * self.l_simple_weight
+
+        loss_vlb = (self.lvlb_weights[t] * loss).mean()
+        loss_dict.update({f'{log_prefix}/loss_vlb': loss_vlb})
+
+        loss = loss_simple + self.original_elbo_weight * loss_vlb
+
+        loss_dict.update({f'{log_prefix}/loss': loss})
+
+        return loss, loss_dict
+
+    def forward(self, x, *args, **kwargs):
+        # b, c, h, w, device, img_size, = *x.shape, x.device, self.image_size
+        # assert h == img_size and w == img_size, f'height and width of image must be {img_size}'
+        t = torch.randint(0, self.num_timesteps, (x.shape[0],), device=self.device).long()
+        return self.p_losses(x, t, *args, **kwargs)
+
+    def get_input(self, batch, k):
+        x = batch[k]
+        if len(x.shape) == 3:
+            x = x[..., None]
+        x = rearrange(x, 'b h w c -> b c h w')
+        x = x.to(memory_format=torch.contiguous_format).float()
+        return x
+
+    def shared_step(self, batch):
+        x = self.get_input(batch, self.first_stage_key)
+        loss, loss_dict = self(x)
+        return loss, loss_dict
+
+    def training_step(self, batch, batch_idx):
+        loss, loss_dict = self.shared_step(batch)
+
+        self.log_dict(loss_dict, prog_bar=True,
+                      logger=True, on_step=True, on_epoch=True)
+
+        self.log("global_step", self.global_step,
+                 prog_bar=True, logger=True, on_step=True, on_epoch=False)
+
+        if self.use_scheduler:
+            lr = self.optimizers().param_groups[0]['lr']
+            self.log('lr_abs', lr, prog_bar=True, logger=True, on_step=True, on_epoch=False)
+
+        return loss
+
+    @torch.no_grad()
+    def validation_step(self, batch, batch_idx):
+        _, loss_dict_no_ema = self.shared_step(batch)
+        with self.ema_scope():
+            _, loss_dict_ema = self.shared_step(batch)
+            loss_dict_ema = {key + '_ema': loss_dict_ema[key] for key in loss_dict_ema}
+        self.log_dict(loss_dict_no_ema, prog_bar=False, logger=True, on_step=False, on_epoch=True)
+        self.log_dict(loss_dict_ema, prog_bar=False, logger=True, on_step=False, on_epoch=True)
+
+    def on_train_batch_end(self, *args, **kwargs):
+        if self.use_ema:
+            self.model_ema(self.model)
+
+    def _get_rows_from_list(self, samples):
+        n_imgs_per_row = len(samples)
+        denoise_grid = rearrange(samples, 'n b c h w -> b n c h w')
+        denoise_grid = rearrange(denoise_grid, 'b n c h w -> (b n) c h w')
+        denoise_grid = make_grid(denoise_grid, nrow=n_imgs_per_row)
+        return denoise_grid
+
+    @torch.no_grad()
+    def log_images(self, batch, N=8, n_row=2, sample=True, return_keys=None, **kwargs):
+        log = dict()
+        x = self.get_input(batch, self.first_stage_key)
+        N = min(x.shape[0], N)
+        n_row = min(x.shape[0], n_row)
+        x = x.to(self.device)[:N]
+        log["inputs"] = x
+
+        # get diffusion row
+        diffusion_row = list()
+        x_start = x[:n_row]
+
+        for t in range(self.num_timesteps):
+            if t % self.log_every_t == 0 or t == self.num_timesteps - 1:
+                t = repeat(torch.tensor([t]), '1 -> b', b=n_row)
+                t = t.to(self.device).long()
+                noise = torch.randn_like(x_start)
+                x_noisy = self.q_sample(x_start=x_start, t=t, noise=noise)
+                diffusion_row.append(x_noisy)
+
+        log["diffusion_row"] = self._get_rows_from_list(diffusion_row)
+
+        if sample:
+            # get denoise row
+            with self.ema_scope("Plotting"):
+                samples, denoise_row = self.sample(batch_size=N, return_intermediates=True)
+
+            log["samples"] = samples
+            log["denoise_row"] = self._get_rows_from_list(denoise_row)
+
+        if return_keys:
+            if np.intersect1d(list(log.keys()), return_keys).shape[0] == 0:
+                return log
+            else:
+                return {key: log[key] for key in return_keys}
+        return log
+
+    def configure_optimizers(self):
+        lr = self.learning_rate
+        params = list(self.model.parameters())
+        if self.learn_logvar:
+            params = params + [self.logvar]
+        opt = torch.optim.AdamW(params, lr=lr)
+        return opt
+
+
+class LatentDiffusion(DDPM):
+    """main class"""
+    def __init__(self,
+                 first_stage_config,
+                 cond_stage_config,
+                 num_timesteps_cond=None,
+                 cond_stage_key="image",
+                 cond_stage_trainable=False,
+                 concat_mode=True,
+                 cond_stage_forward=None,
+                 conditioning_key=None,
+                 scale_factor=1.0,
+                 scale_by_std=False,
+                 *args, **kwargs):
+        self.num_timesteps_cond = default(num_timesteps_cond, 1)
+        self.scale_by_std = scale_by_std
+        assert self.num_timesteps_cond <= kwargs['timesteps']
+        # for backwards compatibility after implementation of DiffusionWrapper
+        if conditioning_key is None:
+            conditioning_key = 'concat' if concat_mode else 'crossattn'
+        if cond_stage_config == '__is_unconditional__':
+            conditioning_key = None
+        ckpt_path = kwargs.pop("ckpt_path", None)
+        ignore_keys = kwargs.pop("ignore_keys", [])
+        super().__init__(conditioning_key=conditioning_key, *args, **kwargs)
+        self.concat_mode = concat_mode
+        self.cond_stage_trainable = cond_stage_trainable
+        self.cond_stage_key = cond_stage_key
+        try:
+            self.num_downs = len(first_stage_config.params.ddconfig.ch_mult) - 1
+        except:
+            self.num_downs = 0
+        if not scale_by_std:
+            self.scale_factor = scale_factor
+        else:
+            self.register_buffer('scale_factor', torch.tensor(scale_factor))
+        self.instantiate_first_stage(first_stage_config)
+        self.instantiate_cond_stage(cond_stage_config)
+        self.cond_stage_forward = cond_stage_forward
+        self.clip_denoised = False
+        self.bbox_tokenizer = None  # # TODO: special class?
+
+        self.restarted_from_ckpt = False
+        if ckpt_path is not None:
+            self.init_from_ckpt(ckpt_path, ignore_keys)
+            self.restarted_from_ckpt = True
+
+    def make_cond_schedule(self, ):
+        self.cond_ids = torch.full(size=(self.num_timesteps,), fill_value=self.num_timesteps - 1, dtype=torch.long)
+        ids = torch.round(torch.linspace(0, self.num_timesteps - 1, self.num_timesteps_cond)).long()
+        self.cond_ids[:self.num_timesteps_cond] = ids
+
+    @rank_zero_only
+    @torch.no_grad()
+    def on_train_batch_start(self, batch, batch_idx, dataloader_idx):
+        # only for very first batch
+        if self.scale_by_std and self.current_epoch == 0 and self.global_step == 0 and batch_idx == 0 and not self.restarted_from_ckpt:
+            assert self.scale_factor == 1., 'rather not use custom rescaling and std-rescaling simultaneously'
+            # set rescale weight to 1./std of encodings
+            print("### USING STD-RESCALING ###")
+            x = super().get_input(batch, self.first_stage_key)
+            x = x.to(self.device)
+            encoder_posterior = self.encode_first_stage(x)
+            z = self.get_first_stage_encoding(encoder_posterior).detach()
+            del self.scale_factor
+            self.register_buffer('scale_factor', 1. / z.flatten().std())
+            print(f"setting self.scale_factor to {self.scale_factor}")
+            print("### USING STD-RESCALING ###")
+
+    def register_schedule(self,
+                          given_betas=None, beta_schedule="linear", timesteps=1000,
+                          linear_start=1e-4, linear_end=2e-2, cosine_s=8e-3):
+        super().register_schedule(given_betas, beta_schedule, timesteps, linear_start, linear_end, cosine_s)
+
+        self.shorten_cond_schedule = self.num_timesteps_cond > 1
+        if self.shorten_cond_schedule:
+            self.make_cond_schedule()
+
+    def instantiate_first_stage(self, config):
+        model = instantiate_from_config(config)
+        self.first_stage_model = model.eval()
+        self.first_stage_model.train = disabled_train
+        for param in self.first_stage_model.parameters():
+            param.requires_grad = False
+
+    def instantiate_cond_stage(self, config):
+        if not self.cond_stage_trainable:
+            if config == "__is_first_stage__":
+                print("Using first stage also as cond stage.")
+                self.cond_stage_model = self.first_stage_model
+            elif config == "__is_unconditional__":
+                print(f"Training {self.__class__.__name__} as an unconditional model.")
+                self.cond_stage_model = None
+                # self.be_unconditional = True
+            else:
+                model = instantiate_from_config(config)
+                self.cond_stage_model = model.eval()
+                self.cond_stage_model.train = disabled_train
+                for param in self.cond_stage_model.parameters():
+                    param.requires_grad = False
+        else:
+            assert config != '__is_first_stage__'
+            assert config != '__is_unconditional__'
+            model = instantiate_from_config(config)
+            self.cond_stage_model = model
+
+    def _get_denoise_row_from_list(self, samples, desc='', force_no_decoder_quantization=False):
+        denoise_row = []
+        for zd in tqdm(samples, desc=desc):
+            denoise_row.append(self.decode_first_stage(zd.to(self.device),
+                                                            force_not_quantize=force_no_decoder_quantization))
+        n_imgs_per_row = len(denoise_row)
+        denoise_row = torch.stack(denoise_row)  # n_log_step, n_row, C, H, W
+        denoise_grid = rearrange(denoise_row, 'n b c h w -> b n c h w')
+        denoise_grid = rearrange(denoise_grid, 'b n c h w -> (b n) c h w')
+        denoise_grid = make_grid(denoise_grid, nrow=n_imgs_per_row)
+        return denoise_grid
+
+    def get_first_stage_encoding(self, encoder_posterior):
+        if isinstance(encoder_posterior, DiagonalGaussianDistribution):
+            z = encoder_posterior.sample()
+        elif isinstance(encoder_posterior, torch.Tensor):
+            z = encoder_posterior
+        else:
+            raise NotImplementedError(f"encoder_posterior of type '{type(encoder_posterior)}' not yet implemented")
+        return self.scale_factor * z
+
+    def get_learned_conditioning(self, c):
+        if self.cond_stage_forward is None:
+            if hasattr(self.cond_stage_model, 'encode') and callable(self.cond_stage_model.encode):
+                c = self.cond_stage_model.encode(c)
+                if isinstance(c, DiagonalGaussianDistribution):
+                    c = c.mode()
+            else:
+                c = self.cond_stage_model(c)
+        else:
+            assert hasattr(self.cond_stage_model, self.cond_stage_forward)
+            c = getattr(self.cond_stage_model, self.cond_stage_forward)(c)
+        return c
+
+    def meshgrid(self, h, w):
+        y = torch.arange(0, h).view(h, 1, 1).repeat(1, w, 1)
+        x = torch.arange(0, w).view(1, w, 1).repeat(h, 1, 1)
+
+        arr = torch.cat([y, x], dim=-1)
+        return arr
+
+    def delta_border(self, h, w):
+        """
+        :param h: height
+        :param w: width
+        :return: normalized distance to image border,
+         wtith min distance = 0 at border and max dist = 0.5 at image center
+        """
+        lower_right_corner = torch.tensor([h - 1, w - 1]).view(1, 1, 2)
+        arr = self.meshgrid(h, w) / lower_right_corner
+        dist_left_up = torch.min(arr, dim=-1, keepdims=True)[0]
+        dist_right_down = torch.min(1 - arr, dim=-1, keepdims=True)[0]
+        edge_dist = torch.min(torch.cat([dist_left_up, dist_right_down], dim=-1), dim=-1)[0]
+        return edge_dist
+
+    def get_weighting(self, h, w, Ly, Lx, device):
+        weighting = self.delta_border(h, w)
+        weighting = torch.clip(weighting, self.split_input_params["clip_min_weight"],
+                               self.split_input_params["clip_max_weight"], )
+        weighting = weighting.view(1, h * w, 1).repeat(1, 1, Ly * Lx).to(device)
+
+        if self.split_input_params["tie_braker"]:
+            L_weighting = self.delta_border(Ly, Lx)
+            L_weighting = torch.clip(L_weighting,
+                                     self.split_input_params["clip_min_tie_weight"],
+                                     self.split_input_params["clip_max_tie_weight"])
+
+            L_weighting = L_weighting.view(1, 1, Ly * Lx).to(device)
+            weighting = weighting * L_weighting
+        return weighting
+
+    def get_fold_unfold(self, x, kernel_size, stride, uf=1, df=1):  # todo load once not every time, shorten code !
+        """
+        :param x: img of size (bs, c, h, w)
+        :return: n img crops of size (n, bs, c, kernel_size[0], kernel_size[1])
+        """
+        bs, nc, h, w = x.shape
+
+        # number of crops in image
+        Ly = (h - kernel_size[0]) // stride[0] + 1
+        Lx = (w - kernel_size[1]) // stride[1] + 1
+
+        if uf == 1 and df == 1:
+            fold_params = dict(kernel_size=kernel_size, dilation=1, padding=0, stride=stride)
+            unfold = torch.nn.Unfold(**fold_params)
+
+            fold = torch.nn.Fold(output_size=x.shape[2:], **fold_params)
+
+            weighting = self.get_weighting(kernel_size[0], kernel_size[1], Ly, Lx, x.device).to(x.dtype)
+            normalization = fold(weighting).view(1, 1, h, w)  # normalizes the overlap
+            weighting = weighting.view((1, 1, kernel_size[0], kernel_size[1], Ly * Lx))
+
+        elif uf > 1 and df == 1:
+            fold_params = dict(kernel_size=kernel_size, dilation=1, padding=0, stride=stride)
+            unfold = torch.nn.Unfold(**fold_params)
+
+            fold_params2 = dict(kernel_size=(kernel_size[0] * uf, kernel_size[0] * uf),
+                                dilation=1, padding=0,
+                                stride=(stride[0] * uf, stride[1] * uf))
+            fold = torch.nn.Fold(output_size=(x.shape[2] * uf, x.shape[3] * uf), **fold_params2)
+
+            weighting = self.get_weighting(kernel_size[0] * uf, kernel_size[1] * uf, Ly, Lx, x.device).to(x.dtype)
+            normalization = fold(weighting).view(1, 1, h * uf, w * uf)  # normalizes the overlap
+            weighting = weighting.view((1, 1, kernel_size[0] * uf, kernel_size[1] * uf, Ly * Lx))
+
+        elif df > 1 and uf == 1:
+            fold_params = dict(kernel_size=kernel_size, dilation=1, padding=0, stride=stride)
+            unfold = torch.nn.Unfold(**fold_params)
+
+            fold_params2 = dict(kernel_size=(kernel_size[0] // df, kernel_size[0] // df),
+                                dilation=1, padding=0,
+                                stride=(stride[0] // df, stride[1] // df))
+            fold = torch.nn.Fold(output_size=(x.shape[2] // df, x.shape[3] // df), **fold_params2)
+
+            weighting = self.get_weighting(kernel_size[0] // df, kernel_size[1] // df, Ly, Lx, x.device).to(x.dtype)
+            normalization = fold(weighting).view(1, 1, h // df, w // df)  # normalizes the overlap
+            weighting = weighting.view((1, 1, kernel_size[0] // df, kernel_size[1] // df, Ly * Lx))
+
+        else:
+            raise NotImplementedError
+
+        return fold, unfold, normalization, weighting
+
+    @torch.no_grad()
+    def get_input(self, batch, k, return_first_stage_outputs=False, force_c_encode=False,
+                  cond_key=None, return_original_cond=False, bs=None):
+        x = super().get_input(batch, k)
+        if bs is not None:
+            x = x[:bs]
+        x = x.to(self.device)
+        encoder_posterior = self.encode_first_stage(x)
+        z = self.get_first_stage_encoding(encoder_posterior).detach()
+
+        if self.model.conditioning_key is not None:
+            if cond_key is None:
+                cond_key = self.cond_stage_key
+            if cond_key != self.first_stage_key:
+                if cond_key in ['caption', 'coordinates_bbox']:
+                    xc = batch[cond_key]
+                elif cond_key == 'class_label':
+                    xc = batch
+                else:
+                    xc = super().get_input(batch, cond_key).to(self.device)
+            else:
+                xc = x
+            if not self.cond_stage_trainable or force_c_encode:
+                if isinstance(xc, dict) or isinstance(xc, list):
+                    # import pudb; pudb.set_trace()
+                    c = self.get_learned_conditioning(xc)
+                else:
+                    c = self.get_learned_conditioning(xc.to(self.device))
+            else:
+                c = xc
+            if bs is not None:
+                c = c[:bs]
+
+            if self.use_positional_encodings:
+                pos_x, pos_y = self.compute_latent_shifts(batch)
+                ckey = __conditioning_keys__[self.model.conditioning_key]
+                c = {ckey: c, 'pos_x': pos_x, 'pos_y': pos_y}
+
+        else:
+            c = None
+            xc = None
+            if self.use_positional_encodings:
+                pos_x, pos_y = self.compute_latent_shifts(batch)
+                c = {'pos_x': pos_x, 'pos_y': pos_y}
+        out = [z, c]
+        if return_first_stage_outputs:
+            xrec = self.decode_first_stage(z)
+            out.extend([x, xrec])
+        if return_original_cond:
+            out.append(xc)
+        return out
+
+    @torch.no_grad()
+    def decode_first_stage(self, z, predict_cids=False, force_not_quantize=False):
+        if predict_cids:
+            if z.dim() == 4:
+                z = torch.argmax(z.exp(), dim=1).long()
+            z = self.first_stage_model.quantize.get_codebook_entry(z, shape=None)
+            z = rearrange(z, 'b h w c -> b c h w').contiguous()
+
+        z = 1. / self.scale_factor * z
+
+        if hasattr(self, "split_input_params"):
+            if self.split_input_params["patch_distributed_vq"]:
+                ks = self.split_input_params["ks"]  # eg. (128, 128)
+                stride = self.split_input_params["stride"]  # eg. (64, 64)
+                uf = self.split_input_params["vqf"]
+                bs, nc, h, w = z.shape
+                if ks[0] > h or ks[1] > w:
+                    ks = (min(ks[0], h), min(ks[1], w))
+                    print("reducing Kernel")
+
+                if stride[0] > h or stride[1] > w:
+                    stride = (min(stride[0], h), min(stride[1], w))
+                    print("reducing stride")
+
+                fold, unfold, normalization, weighting = self.get_fold_unfold(z, ks, stride, uf=uf)
+
+                z = unfold(z)  # (bn, nc * prod(**ks), L)
+                # 1. Reshape to img shape
+                z = z.view((z.shape[0], -1, ks[0], ks[1], z.shape[-1]))  # (bn, nc, ks[0], ks[1], L )
+
+                # 2. apply model loop over last dim
+                if isinstance(self.first_stage_model, VQModelInterface):
+                    output_list = [self.first_stage_model.decode(z[:, :, :, :, i],
+                                                                 force_not_quantize=predict_cids or force_not_quantize)
+                                   for i in range(z.shape[-1])]
+                else:
+
+                    output_list = [self.first_stage_model.decode(z[:, :, :, :, i])
+                                   for i in range(z.shape[-1])]
+
+                o = torch.stack(output_list, axis=-1)  # # (bn, nc, ks[0], ks[1], L)
+                o = o * weighting
+                # Reverse 1. reshape to img shape
+                o = o.view((o.shape[0], -1, o.shape[-1]))  # (bn, nc * ks[0] * ks[1], L)
+                # stitch crops together
+                decoded = fold(o)
+                decoded = decoded / normalization  # norm is shape (1, 1, h, w)
+                return decoded
+            else:
+                if isinstance(self.first_stage_model, VQModelInterface):
+                    return self.first_stage_model.decode(z, force_not_quantize=predict_cids or force_not_quantize)
+                else:
+                    return self.first_stage_model.decode(z)
+
+        else:
+            if isinstance(self.first_stage_model, VQModelInterface):
+                return self.first_stage_model.decode(z, force_not_quantize=predict_cids or force_not_quantize)
+            else:
+                return self.first_stage_model.decode(z)
+
+    # same as above but without decorator
+    def differentiable_decode_first_stage(self, z, predict_cids=False, force_not_quantize=False):
+        if predict_cids:
+            if z.dim() == 4:
+                z = torch.argmax(z.exp(), dim=1).long()
+            z = self.first_stage_model.quantize.get_codebook_entry(z, shape=None)
+            z = rearrange(z, 'b h w c -> b c h w').contiguous()
+
+        z = 1. / self.scale_factor * z
+
+        if hasattr(self, "split_input_params"):
+            if self.split_input_params["patch_distributed_vq"]:
+                ks = self.split_input_params["ks"]  # eg. (128, 128)
+                stride = self.split_input_params["stride"]  # eg. (64, 64)
+                uf = self.split_input_params["vqf"]
+                bs, nc, h, w = z.shape
+                if ks[0] > h or ks[1] > w:
+                    ks = (min(ks[0], h), min(ks[1], w))
+                    print("reducing Kernel")
+
+                if stride[0] > h or stride[1] > w:
+                    stride = (min(stride[0], h), min(stride[1], w))
+                    print("reducing stride")
+
+                fold, unfold, normalization, weighting = self.get_fold_unfold(z, ks, stride, uf=uf)
+
+                z = unfold(z)  # (bn, nc * prod(**ks), L)
+                # 1. Reshape to img shape
+                z = z.view((z.shape[0], -1, ks[0], ks[1], z.shape[-1]))  # (bn, nc, ks[0], ks[1], L )
+
+                # 2. apply model loop over last dim
+                if isinstance(self.first_stage_model, VQModelInterface):  # todo ask what this is
+                    output_list = [self.first_stage_model.decode(z[:, :, :, :, i],
+                                                                 force_not_quantize=predict_cids or force_not_quantize)
+                                   for i in range(z.shape[-1])]
+                else:
+
+                    output_list = [self.first_stage_model.decode(z[:, :, :, :, i])
+                                   for i in range(z.shape[-1])]
+
+                o = torch.stack(output_list, axis=-1)  # # (bn, nc, ks[0], ks[1], L)
+                o = o * weighting
+                # Reverse 1. reshape to img shape
+                o = o.view((o.shape[0], -1, o.shape[-1]))  # (bn, nc * ks[0] * ks[1], L)
+                # stitch crops together
+                decoded = fold(o)
+                decoded = decoded / normalization  # norm is shape (1, 1, h, w)
+                return decoded
+            else:
+                if isinstance(self.first_stage_model, VQModelInterface):
+                    return self.first_stage_model.decode(z, force_not_quantize=predict_cids or force_not_quantize)
+                else:
+                    return self.first_stage_model.decode(z)
+
+        else:
+            if isinstance(self.first_stage_model, VQModelInterface):
+                return self.first_stage_model.decode(z, force_not_quantize=predict_cids or force_not_quantize)
+            else:
+                return self.first_stage_model.decode(z)
+
+    @torch.no_grad()
+    def encode_first_stage(self, x):
+        if hasattr(self, "split_input_params"):
+            if self.split_input_params["patch_distributed_vq"]:
+                ks = self.split_input_params["ks"]  # eg. (128, 128)
+                stride = self.split_input_params["stride"]  # eg. (64, 64)
+                df = self.split_input_params["vqf"]
+                self.split_input_params['original_image_size'] = x.shape[-2:]
+                bs, nc, h, w = x.shape
+                if ks[0] > h or ks[1] > w:
+                    ks = (min(ks[0], h), min(ks[1], w))
+                    print("reducing Kernel")
+
+                if stride[0] > h or stride[1] > w:
+                    stride = (min(stride[0], h), min(stride[1], w))
+                    print("reducing stride")
+
+                fold, unfold, normalization, weighting = self.get_fold_unfold(x, ks, stride, df=df)
+                z = unfold(x)  # (bn, nc * prod(**ks), L)
+                # Reshape to img shape
+                z = z.view((z.shape[0], -1, ks[0], ks[1], z.shape[-1]))  # (bn, nc, ks[0], ks[1], L )
+
+                output_list = [self.first_stage_model.encode(z[:, :, :, :, i])
+                               for i in range(z.shape[-1])]
+
+                o = torch.stack(output_list, axis=-1)
+                o = o * weighting
+
+                # Reverse reshape to img shape
+                o = o.view((o.shape[0], -1, o.shape[-1]))  # (bn, nc * ks[0] * ks[1], L)
+                # stitch crops together
+                decoded = fold(o)
+                decoded = decoded / normalization
+                return decoded
+
+            else:
+                return self.first_stage_model.encode(x)
+        else:
+            return self.first_stage_model.encode(x)
+
+    def shared_step(self, batch, **kwargs):
+        x, c = self.get_input(batch, self.first_stage_key)
+        loss = self(x, c)
+        return loss
+
+    def forward(self, x, c, *args, **kwargs):
+        t = torch.randint(0, self.num_timesteps, (x.shape[0],), device=self.device).long()
+        if self.model.conditioning_key is not None:
+            assert c is not None
+            if self.cond_stage_trainable:
+                c = self.get_learned_conditioning(c)
+            if self.shorten_cond_schedule:  # TODO: drop this option
+                tc = self.cond_ids[t].to(self.device)
+                c = self.q_sample(x_start=c, t=tc, noise=torch.randn_like(c.float()))
+        return self.p_losses(x, c, t, *args, **kwargs)
+
+    def _rescale_annotations(self, bboxes, crop_coordinates):  # TODO: move to dataset
+        def rescale_bbox(bbox):
+            x0 = clamp((bbox[0] - crop_coordinates[0]) / crop_coordinates[2])
+            y0 = clamp((bbox[1] - crop_coordinates[1]) / crop_coordinates[3])
+            w = min(bbox[2] / crop_coordinates[2], 1 - x0)
+            h = min(bbox[3] / crop_coordinates[3], 1 - y0)
+            return x0, y0, w, h
+
+        return [rescale_bbox(b) for b in bboxes]
+
+    def apply_model(self, x_noisy, t, cond, return_ids=False):
+
+        if isinstance(cond, dict):
+            # hybrid case, cond is exptected to be a dict
+            pass
+        else:
+            if not isinstance(cond, list):
+                cond = [cond]
+            key = 'c_concat' if self.model.conditioning_key == 'concat' else 'c_crossattn'
+            cond = {key: cond}
+
+        if hasattr(self, "split_input_params"):
+            assert len(cond) == 1  # todo can only deal with one conditioning atm
+            assert not return_ids  # todo dont know what this is -> I exclude --> Good
+            ks = self.split_input_params["ks"]  # eg. (128, 128)
+            stride = self.split_input_params["stride"]  # eg. (64, 64)
+
+            h, w = x_noisy.shape[-2:]
+
+            fold, unfold, normalization, weighting = self.get_fold_unfold(x_noisy, ks, stride)
+
+            z = unfold(x_noisy)  # (bn, nc * prod(**ks), L)
+            # Reshape to img shape
+            z = z.view((z.shape[0], -1, ks[0], ks[1], z.shape[-1]))  # (bn, nc, ks[0], ks[1], L )
+            z_list = [z[:, :, :, :, i] for i in range(z.shape[-1])]
+
+            if self.cond_stage_key in ["image", "LR_image", "segmentation",
+                                       'bbox_img'] and self.model.conditioning_key:  # todo check for completeness
+                c_key = next(iter(cond.keys()))  # get key
+                c = next(iter(cond.values()))  # get value
+                assert (len(c) == 1)  # todo extend to list with more than one elem
+                c = c[0]  # get element
+
+                c = unfold(c)
+                c = c.view((c.shape[0], -1, ks[0], ks[1], c.shape[-1]))  # (bn, nc, ks[0], ks[1], L )
+
+                cond_list = [{c_key: [c[:, :, :, :, i]]} for i in range(c.shape[-1])]
+
+            elif self.cond_stage_key == 'coordinates_bbox':
+                assert 'original_image_size' in self.split_input_params, 'BoudingBoxRescaling is missing original_image_size'
+
+                # assuming padding of unfold is always 0 and its dilation is always 1
+                n_patches_per_row = int((w - ks[0]) / stride[0] + 1)
+                full_img_h, full_img_w = self.split_input_params['original_image_size']
+                # as we are operating on latents, we need the factor from the original image size to the
+                # spatial latent size to properly rescale the crops for regenerating the bbox annotations
+                num_downs = self.first_stage_model.encoder.num_resolutions - 1
+                rescale_latent = 2 ** (num_downs)
+
+                # get top left postions of patches as conforming for the bbbox tokenizer, therefore we
+                # need to rescale the tl patch coordinates to be in between (0,1)
+                tl_patch_coordinates = [(rescale_latent * stride[0] * (patch_nr % n_patches_per_row) / full_img_w,
+                                         rescale_latent * stride[1] * (patch_nr // n_patches_per_row) / full_img_h)
+                                        for patch_nr in range(z.shape[-1])]
+
+                # patch_limits are tl_coord, width and height coordinates as (x_tl, y_tl, h, w)
+                patch_limits = [(x_tl, y_tl,
+                                 rescale_latent * ks[0] / full_img_w,
+                                 rescale_latent * ks[1] / full_img_h) for x_tl, y_tl in tl_patch_coordinates]
+                # patch_values = [(np.arange(x_tl,min(x_tl+ks, 1.)),np.arange(y_tl,min(y_tl+ks, 1.))) for x_tl, y_tl in tl_patch_coordinates]
+
+                # tokenize crop coordinates for the bounding boxes of the respective patches
+                patch_limits_tknzd = [torch.LongTensor(self.bbox_tokenizer._crop_encoder(bbox))[None].to(self.device)
+                                      for bbox in patch_limits]  # list of length l with tensors of shape (1, 2)
+                print(patch_limits_tknzd[0].shape)
+                # cut tknzd crop position from conditioning
+                assert isinstance(cond, dict), 'cond must be dict to be fed into model'
+                cut_cond = cond['c_crossattn'][0][..., :-2].to(self.device)
+                print(cut_cond.shape)
+
+                adapted_cond = torch.stack([torch.cat([cut_cond, p], dim=1) for p in patch_limits_tknzd])
+                adapted_cond = rearrange(adapted_cond, 'l b n -> (l b) n')
+                print(adapted_cond.shape)
+                adapted_cond = self.get_learned_conditioning(adapted_cond)
+                print(adapted_cond.shape)
+                adapted_cond = rearrange(adapted_cond, '(l b) n d -> l b n d', l=z.shape[-1])
+                print(adapted_cond.shape)
+
+                cond_list = [{'c_crossattn': [e]} for e in adapted_cond]
+
+            else:
+                cond_list = [cond for i in range(z.shape[-1])]  # Todo make this more efficient
+
+            # apply model by loop over crops
+            output_list = [self.model(z_list[i], t, **cond_list[i]) for i in range(z.shape[-1])]
+            assert not isinstance(output_list[0],
+                                  tuple)  # todo cant deal with multiple model outputs check this never happens
+
+            o = torch.stack(output_list, axis=-1)
+            o = o * weighting
+            # Reverse reshape to img shape
+            o = o.view((o.shape[0], -1, o.shape[-1]))  # (bn, nc * ks[0] * ks[1], L)
+            # stitch crops together
+            x_recon = fold(o) / normalization
+
+        else:
+            x_recon = self.model(x_noisy, t, **cond)
+
+        if isinstance(x_recon, tuple) and not return_ids:
+            return x_recon[0]
+        else:
+            return x_recon
+
+    def _predict_eps_from_xstart(self, x_t, t, pred_xstart):
+        return (extract_into_tensor(self.sqrt_recip_alphas_cumprod, t, x_t.shape) * x_t - pred_xstart) / \
+               extract_into_tensor(self.sqrt_recipm1_alphas_cumprod, t, x_t.shape)
+
+    def _prior_bpd(self, x_start):
+        """
+        Get the prior KL term for the variational lower-bound, measured in
+        bits-per-dim.
+        This term can't be optimized, as it only depends on the encoder.
+        :param x_start: the [N x C x ...] tensor of inputs.
+        :return: a batch of [N] KL values (in bits), one per batch element.
+        """
+        batch_size = x_start.shape[0]
+        t = torch.tensor([self.num_timesteps - 1] * batch_size, device=x_start.device)
+        qt_mean, _, qt_log_variance = self.q_mean_variance(x_start, t)
+        kl_prior = normal_kl(mean1=qt_mean, logvar1=qt_log_variance, mean2=0.0, logvar2=0.0)
+        return mean_flat(kl_prior) / np.log(2.0)
+
+    def p_losses(self, x_start, cond, t, noise=None):
+        noise = default(noise, lambda: torch.randn_like(x_start))
+        x_noisy = self.q_sample(x_start=x_start, t=t, noise=noise)
+        model_output = self.apply_model(x_noisy, t, cond)
+
+        loss_dict = {}
+        prefix = 'train' if self.training else 'val'
+
+        if self.parameterization == "x0":
+            target = x_start
+        elif self.parameterization == "eps":
+            target = noise
+        else:
+            raise NotImplementedError()
+
+        loss_simple = self.get_loss(model_output, target, mean=False).mean([1, 2, 3])
+        loss_dict.update({f'{prefix}/loss_simple': loss_simple.mean()})
+
+        logvar_t = self.logvar[t].to(self.device)
+        loss = loss_simple / torch.exp(logvar_t) + logvar_t
+        # loss = loss_simple / torch.exp(self.logvar) + self.logvar
+        if self.learn_logvar:
+            loss_dict.update({f'{prefix}/loss_gamma': loss.mean()})
+            loss_dict.update({'logvar': self.logvar.data.mean()})
+
+        loss = self.l_simple_weight * loss.mean()
+
+        loss_vlb = self.get_loss(model_output, target, mean=False).mean(dim=(1, 2, 3))
+        loss_vlb = (self.lvlb_weights[t] * loss_vlb).mean()
+        loss_dict.update({f'{prefix}/loss_vlb': loss_vlb})
+        loss += (self.original_elbo_weight * loss_vlb)
+        loss_dict.update({f'{prefix}/loss': loss})
+
+        return loss, loss_dict
+
+    def p_mean_variance(self, x, c, t, clip_denoised: bool, return_codebook_ids=False, quantize_denoised=False,
+                        return_x0=False, score_corrector=None, corrector_kwargs=None):
+        t_in = t
+        model_out = self.apply_model(x, t_in, c, return_ids=return_codebook_ids)
+
+        if score_corrector is not None:
+            assert self.parameterization == "eps"
+            model_out = score_corrector.modify_score(self, model_out, x, t, c, **corrector_kwargs)
+
+        if return_codebook_ids:
+            model_out, logits = model_out
+
+        if self.parameterization == "eps":
+            x_recon = self.predict_start_from_noise(x, t=t, noise=model_out)
+        elif self.parameterization == "x0":
+            x_recon = model_out
+        else:
+            raise NotImplementedError()
+
+        if clip_denoised:
+            x_recon.clamp_(-1., 1.)
+        if quantize_denoised:
+            x_recon, _, [_, _, indices] = self.first_stage_model.quantize(x_recon)
+        model_mean, posterior_variance, posterior_log_variance = self.q_posterior(x_start=x_recon, x_t=x, t=t)
+        if return_codebook_ids:
+            return model_mean, posterior_variance, posterior_log_variance, logits
+        elif return_x0:
+            return model_mean, posterior_variance, posterior_log_variance, x_recon
+        else:
+            return model_mean, posterior_variance, posterior_log_variance
+
+    @torch.no_grad()
+    def p_sample(self, x, c, t, clip_denoised=False, repeat_noise=False,
+                 return_codebook_ids=False, quantize_denoised=False, return_x0=False,
+                 temperature=1., noise_dropout=0., score_corrector=None, corrector_kwargs=None):
+        b, *_, device = *x.shape, x.device
+        outputs = self.p_mean_variance(x=x, c=c, t=t, clip_denoised=clip_denoised,
+                                       return_codebook_ids=return_codebook_ids,
+                                       quantize_denoised=quantize_denoised,
+                                       return_x0=return_x0,
+                                       score_corrector=score_corrector, corrector_kwargs=corrector_kwargs)
+        if return_codebook_ids:
+            raise DeprecationWarning("Support dropped.")
+            model_mean, _, model_log_variance, logits = outputs
+        elif return_x0:
+            model_mean, _, model_log_variance, x0 = outputs
+        else:
+            model_mean, _, model_log_variance = outputs
+
+        noise = noise_like(x.shape, device, repeat_noise) * temperature
+        if noise_dropout > 0.:
+            noise = torch.nn.functional.dropout(noise, p=noise_dropout)
+        # no noise when t == 0
+        nonzero_mask = (1 - (t == 0).float()).reshape(b, *((1,) * (len(x.shape) - 1)))
+
+        if return_codebook_ids:
+            return model_mean + nonzero_mask * (0.5 * model_log_variance).exp() * noise, logits.argmax(dim=1)
+        if return_x0:
+            return model_mean + nonzero_mask * (0.5 * model_log_variance).exp() * noise, x0
+        else:
+            return model_mean + nonzero_mask * (0.5 * model_log_variance).exp() * noise
+
+    @torch.no_grad()
+    def progressive_denoising(self, cond, shape, verbose=True, callback=None, quantize_denoised=False,
+                              img_callback=None, mask=None, x0=None, temperature=1., noise_dropout=0.,
+                              score_corrector=None, corrector_kwargs=None, batch_size=None, x_T=None, start_T=None,
+                              log_every_t=None):
+        if not log_every_t:
+            log_every_t = self.log_every_t
+        timesteps = self.num_timesteps
+        if batch_size is not None:
+            b = batch_size if batch_size is not None else shape[0]
+            shape = [batch_size] + list(shape)
+        else:
+            b = batch_size = shape[0]
+        if x_T is None:
+            img = torch.randn(shape, device=self.device)
+        else:
+            img = x_T
+        intermediates = []
+        if cond is not None:
+            if isinstance(cond, dict):
+                cond = {key: cond[key][:batch_size] if not isinstance(cond[key], list) else
+                list(map(lambda x: x[:batch_size], cond[key])) for key in cond}
+            else:
+                cond = [c[:batch_size] for c in cond] if isinstance(cond, list) else cond[:batch_size]
+
+        if start_T is not None:
+            timesteps = min(timesteps, start_T)
+        iterator = tqdm(reversed(range(0, timesteps)), desc='Progressive Generation',
+                        total=timesteps) if verbose else reversed(
+            range(0, timesteps))
+        if type(temperature) == float:
+            temperature = [temperature] * timesteps
+
+        for i in iterator:
+            ts = torch.full((b,), i, device=self.device, dtype=torch.long)
+            if self.shorten_cond_schedule:
+                assert self.model.conditioning_key != 'hybrid'
+                tc = self.cond_ids[ts].to(cond.device)
+                cond = self.q_sample(x_start=cond, t=tc, noise=torch.randn_like(cond))
+
+            img, x0_partial = self.p_sample(img, cond, ts,
+                                            clip_denoised=self.clip_denoised,
+                                            quantize_denoised=quantize_denoised, return_x0=True,
+                                            temperature=temperature[i], noise_dropout=noise_dropout,
+                                            score_corrector=score_corrector, corrector_kwargs=corrector_kwargs)
+            if mask is not None:
+                assert x0 is not None
+                img_orig = self.q_sample(x0, ts)
+                img = img_orig * mask + (1. - mask) * img
+
+            if i % log_every_t == 0 or i == timesteps - 1:
+                intermediates.append(x0_partial)
+            if callback: callback(i)
+            if img_callback: img_callback(img, i)
+        return img, intermediates
+
+    @torch.no_grad()
+    def p_sample_loop(self, cond, shape, return_intermediates=False,
+                      x_T=None, verbose=True, callback=None, timesteps=None, quantize_denoised=False,
+                      mask=None, x0=None, img_callback=None, start_T=None,
+                      log_every_t=None):
+
+        if not log_every_t:
+            log_every_t = self.log_every_t
+        device = self.betas.device
+        b = shape[0]
+        if x_T is None:
+            img = torch.randn(shape, device=device)
+        else:
+            img = x_T
+
+        intermediates = [img]
+        if timesteps is None:
+            timesteps = self.num_timesteps
+
+        if start_T is not None:
+            timesteps = min(timesteps, start_T)
+        print(timesteps, start_T)
+        iterator = tqdm(reversed(range(0, timesteps)), desc='Sampling t', total=timesteps) if verbose else reversed(
+            range(0, timesteps))
+
+        if mask is not None:
+            assert x0 is not None
+            assert x0.shape[2:3] == mask.shape[2:3]  # spatial size has to match
+
+        for i in iterator:
+            ts = torch.full((b,), i, device=device, dtype=torch.long)
+            if self.shorten_cond_schedule:
+                assert self.model.conditioning_key != 'hybrid'
+                tc = self.cond_ids[ts].to(cond.device)
+                cond = self.q_sample(x_start=cond, t=tc, noise=torch.randn_like(cond))
+
+            img = self.p_sample(img, cond, ts,
+                                clip_denoised=self.clip_denoised,
+                                quantize_denoised=quantize_denoised)
+            if mask is not None:
+                img_orig = self.q_sample(x0, ts)
+                img = img_orig * mask + (1. - mask) * img
+
+            if i % log_every_t == 0 or i == timesteps - 1:
+                intermediates.append(img)
+            if callback: callback(i)
+            if img_callback: img_callback(img, i)
+
+        if return_intermediates:
+            return img, intermediates
+        return img
+
+    @torch.no_grad()
+    def sample(self, cond, batch_size=16, return_intermediates=False, x_T=None,
+               verbose=True, timesteps=None, quantize_denoised=False,
+               mask=None, x0=None, shape=None):
+        if shape is None:
+            shape = (batch_size, self.channels, self.image_size, self.image_size)
+        if cond is not None:
+            if isinstance(cond, dict):
+                cond = {key: cond[key][:batch_size] if not isinstance(cond[key], list) else
+                list(map(lambda x: x[:batch_size], cond[key])) for key in cond}
+            else:
+                cond = [c[:batch_size] for c in cond] if isinstance(cond, list) else cond[:batch_size]
+        return self.p_sample_loop(cond,
+                                  shape,
+                                  return_intermediates=return_intermediates, x_T=x_T,
+                                  verbose=verbose, timesteps=timesteps, quantize_denoised=quantize_denoised,
+                                  mask=mask, x0=x0)
+
+    @torch.no_grad()
+    def log_images(self, batch, N=8, n_row=4, sample=True, sample_ddim=False, return_keys=None,
+                   quantize_denoised=True, inpaint=True, plot_denoise_rows=False, plot_progressive_rows=True,
+                   plot_diffusion_rows=True, **kwargs):
+        # TODO: maybe add option for ddim sampling via DDIMSampler class
+        log = dict()
+        z, c, x, xrec, xc = self.get_input(batch, self.first_stage_key,
+                                           return_first_stage_outputs=True,
+                                           force_c_encode=True,
+                                           return_original_cond=True,
+                                           bs=N)
+        N = min(x.shape[0], N)
+        n_row = min(x.shape[0], n_row)
+        log["inputs"] = x
+        log["reconstruction"] = xrec
+        if self.model.conditioning_key is not None:
+            if hasattr(self.cond_stage_model, "decode"):
+                xc = self.cond_stage_model.decode(c)
+                log["conditioning"] = xc
+            elif self.cond_stage_key in ["caption"]:
+                xc = log_txt_as_img((x.shape[2], x.shape[3]), batch["caption"])
+                log["conditioning"] = xc
+            elif self.cond_stage_key == 'class_label':
+                xc = log_txt_as_img((x.shape[2], x.shape[3]), batch["human_label"])
+                log['conditioning'] = xc
+            elif isimage(xc):
+                log["conditioning"] = xc
+            if ismap(xc):
+                log["original_conditioning"] = self.to_rgb(xc)
+
+        if plot_diffusion_rows:
+            # get diffusion row
+            diffusion_row = list()
+            z_start = z[:n_row]
+            for t in range(self.num_timesteps):
+                if t % self.log_every_t == 0 or t == self.num_timesteps - 1:
+                    t = repeat(torch.tensor([t]), '1 -> b', b=n_row)
+                    t = t.to(self.device).long()
+                    noise = torch.randn_like(z_start)
+                    z_noisy = self.q_sample(x_start=z_start, t=t, noise=noise)
+                    diffusion_row.append(self.decode_first_stage(z_noisy))
+
+            diffusion_row = torch.stack(diffusion_row)  # n_log_step, n_row, C, H, W
+            diffusion_grid = rearrange(diffusion_row, 'n b c h w -> b n c h w')
+            diffusion_grid = rearrange(diffusion_grid, 'b n c h w -> (b n) c h w')
+            diffusion_grid = make_grid(diffusion_grid, nrow=diffusion_row.shape[0])
+            log["diffusion_row"] = diffusion_grid
+
+        if sample:
+            # get denoise row
+            with self.ema_scope("Plotting"):
+                samples, z_denoise_row = self.sample(cond=c, batch_size=N, return_intermediates=True)
+            x_samples = self.decode_first_stage(samples)
+            log["samples"] = x_samples
+            if plot_denoise_rows:
+                denoise_grid = self._get_denoise_row_from_list(z_denoise_row)
+                log["denoise_row"] = denoise_grid
+
+            if quantize_denoised and not isinstance(self.first_stage_model, AutoencoderKL) and not isinstance(
+                    self.first_stage_model, IdentityFirstStage):
+                # also display when quantizing x0 while sampling
+                with self.ema_scope("Plotting Quantized Denoised"):
+                    samples, z_denoise_row = self.sample(cond=c, batch_size=N, return_intermediates=True,
+                                                         quantize_denoised=True)
+                x_samples = self.decode_first_stage(samples.to(self.device))
+                log["samples_x0_quantized"] = x_samples
+
+            if inpaint:
+                # make a simple center square
+                b, h, w = z.shape[0], z.shape[2], z.shape[3]
+                mask = torch.ones(N, h, w).to(self.device)
+                # zeros will be filled in
+                mask[:, h // 4:3 * h // 4, w // 4:3 * w // 4] = 0.
+                mask = mask[:, None, ...]
+                with self.ema_scope("Plotting Inpaint"):
+                    samples, z_denoise_row = self.sample(cond=c, batch_size=N, return_intermediates=True,
+                                                         quantize_denoised=False, x0=z[:N], mask=mask)
+                x_samples = self.decode_first_stage(samples.to(self.device))
+                log["samples_inpainting"] = x_samples
+                log["mask"] = mask
+                if plot_denoise_rows:
+                    denoise_grid = self._get_denoise_row_from_list(z_denoise_row)
+                    log["denoise_row_inpainting"] = denoise_grid
+
+                # outpaint
+                with self.ema_scope("Plotting Outpaint"):
+                    samples = self.sample(cond=c, batch_size=N, return_intermediates=False,
+                                          quantize_denoised=False, x0=z[:N], mask=1. - mask)
+                x_samples = self.decode_first_stage(samples.to(self.device))
+                log["samples_outpainting"] = x_samples
+
+        if plot_progressive_rows:
+            with self.ema_scope("Plotting Progressives"):
+                img, progressives = self.progressive_denoising(c,
+                                                               shape=(self.channels, self.image_size, self.image_size),
+                                                               batch_size=N)
+            prog_row = self._get_denoise_row_from_list(progressives, desc="Progressive Generation")
+            log["progressive_row"] = prog_row
+
+        if return_keys:
+            if np.intersect1d(list(log.keys()), return_keys).shape[0] == 0:
+                return log
+            else:
+                return {key: log[key] for key in return_keys}
+        return log
+
+    def configure_optimizers(self):
+        lr = self.learning_rate
+        params = list(self.model.parameters())
+        if self.cond_stage_trainable:
+            print(f"{self.__class__.__name__}: Also optimizing conditioner params!")
+            params = params + list(self.cond_stage_model.parameters())
+        if self.learn_logvar:
+            print('Diffusion model optimizing logvar')
+            params.append(self.logvar)
+        opt = torch.optim.AdamW(params, lr=lr)
+        if self.use_scheduler:
+            assert 'target' in self.scheduler_config
+            scheduler = instantiate_from_config(self.scheduler_config)
+
+            print("Setting up LambdaLR scheduler...")
+            scheduler = [
+                {
+                    'scheduler': LambdaLR(opt, lr_lambda=scheduler.schedule),
+                    'interval': 'step',
+                    'frequency': 1
+                }]
+            return [opt], scheduler
+        return opt
+
+    @torch.no_grad()
+    def to_rgb(self, x):
+        x = x.float()
+        if not hasattr(self, "colorize"):
+            self.colorize = torch.randn(3, x.shape[1], 1, 1).to(x)
+        x = nn.functional.conv2d(x, weight=self.colorize)
+        x = 2. * (x - x.min()) / (x.max() - x.min()) - 1.
+        return x
+
+
+class DiffusionWrapper(pl.LightningModule):
+    def __init__(self, diff_model_config, conditioning_key):
+        super().__init__()
+        self.diffusion_model = instantiate_from_config(diff_model_config)
+        self.conditioning_key = conditioning_key
+        assert self.conditioning_key in [None, 'concat', 'crossattn', 'hybrid', 'adm']
+
+    def forward(self, x, t, c_concat: list = None, c_crossattn: list = None):
+        if self.conditioning_key is None:
+            out = self.diffusion_model(x, t)
+        elif self.conditioning_key == 'concat':
+            xc = torch.cat([x] + c_concat, dim=1)
+            out = self.diffusion_model(xc, t)
+        elif self.conditioning_key == 'crossattn':
+            cc = torch.cat(c_crossattn, 1)
+            out = self.diffusion_model(x, t, context=cc)
+        elif self.conditioning_key == 'hybrid':
+            xc = torch.cat([x] + c_concat, dim=1)
+            cc = torch.cat(c_crossattn, 1)
+            out = self.diffusion_model(xc, t, context=cc)
+        elif self.conditioning_key == 'adm':
+            cc = c_crossattn[0]
+            out = self.diffusion_model(x, t, y=cc)
+        else:
+            raise NotImplementedError()
+
+        return out
+
+
+class Layout2ImgDiffusion(LatentDiffusion):
+    # TODO: move all layout-specific hacks to this class
+    def __init__(self, cond_stage_key, *args, **kwargs):
+        assert cond_stage_key == 'coordinates_bbox', 'Layout2ImgDiffusion only for cond_stage_key="coordinates_bbox"'
+        super().__init__(cond_stage_key=cond_stage_key, *args, **kwargs)
+
+    def log_images(self, batch, N=8, *args, **kwargs):
+        logs = super().log_images(batch=batch, N=N, *args, **kwargs)
+
+        key = 'train' if self.training else 'validation'
+        dset = self.trainer.datamodule.datasets[key]
+        mapper = dset.conditional_builders[self.cond_stage_key]
+
+        bbox_imgs = []
+        map_fn = lambda catno: dset.get_textual_label(dset.get_category_id(catno))
+        for tknzd_bbox in batch[self.cond_stage_key][:N]:
+            bboximg = mapper.plot(tknzd_bbox.detach().cpu(), map_fn, (256, 256))
+            bbox_imgs.append(bboximg)
+
+        cond_img = torch.stack(bbox_imgs, dim=0)
+        logs['bbox_image'] = cond_img
+        return logs

+ 261 - 0
ldm/modules/attention.py

@@ -0,0 +1,261 @@
+from inspect import isfunction
+import math
+import torch
+import torch.nn.functional as F
+from torch import nn, einsum
+from einops import rearrange, repeat
+
+from ldm.modules.diffusionmodules.util import checkpoint
+
+
+def exists(val):
+    return val is not None
+
+
+def uniq(arr):
+    return{el: True for el in arr}.keys()
+
+
+def default(val, d):
+    if exists(val):
+        return val
+    return d() if isfunction(d) else d
+
+
+def max_neg_value(t):
+    return -torch.finfo(t.dtype).max
+
+
+def init_(tensor):
+    dim = tensor.shape[-1]
+    std = 1 / math.sqrt(dim)
+    tensor.uniform_(-std, std)
+    return tensor
+
+
+# feedforward
+class GEGLU(nn.Module):
+    def __init__(self, dim_in, dim_out):
+        super().__init__()
+        self.proj = nn.Linear(dim_in, dim_out * 2)
+
+    def forward(self, x):
+        x, gate = self.proj(x).chunk(2, dim=-1)
+        return x * F.gelu(gate)
+
+
+class FeedForward(nn.Module):
+    def __init__(self, dim, dim_out=None, mult=4, glu=False, dropout=0.):
+        super().__init__()
+        inner_dim = int(dim * mult)
+        dim_out = default(dim_out, dim)
+        project_in = nn.Sequential(
+            nn.Linear(dim, inner_dim),
+            nn.GELU()
+        ) if not glu else GEGLU(dim, inner_dim)
+
+        self.net = nn.Sequential(
+            project_in,
+            nn.Dropout(dropout),
+            nn.Linear(inner_dim, dim_out)
+        )
+
+    def forward(self, x):
+        return self.net(x)
+
+
+def zero_module(module):
+    """
+    Zero out the parameters of a module and return it.
+    """
+    for p in module.parameters():
+        p.detach().zero_()
+    return module
+
+
+def Normalize(in_channels):
+    return torch.nn.GroupNorm(num_groups=32, num_channels=in_channels, eps=1e-6, affine=True)
+
+
+class LinearAttention(nn.Module):
+    def __init__(self, dim, heads=4, dim_head=32):
+        super().__init__()
+        self.heads = heads
+        hidden_dim = dim_head * heads
+        self.to_qkv = nn.Conv2d(dim, hidden_dim * 3, 1, bias = False)
+        self.to_out = nn.Conv2d(hidden_dim, dim, 1)
+
+    def forward(self, x):
+        b, c, h, w = x.shape
+        qkv = self.to_qkv(x)
+        q, k, v = rearrange(qkv, 'b (qkv heads c) h w -> qkv b heads c (h w)', heads = self.heads, qkv=3)
+        k = k.softmax(dim=-1)  
+        context = torch.einsum('bhdn,bhen->bhde', k, v)
+        out = torch.einsum('bhde,bhdn->bhen', context, q)
+        out = rearrange(out, 'b heads c (h w) -> b (heads c) h w', heads=self.heads, h=h, w=w)
+        return self.to_out(out)
+
+
+class SpatialSelfAttention(nn.Module):
+    def __init__(self, in_channels):
+        super().__init__()
+        self.in_channels = in_channels
+
+        self.norm = Normalize(in_channels)
+        self.q = torch.nn.Conv2d(in_channels,
+                                 in_channels,
+                                 kernel_size=1,
+                                 stride=1,
+                                 padding=0)
+        self.k = torch.nn.Conv2d(in_channels,
+                                 in_channels,
+                                 kernel_size=1,
+                                 stride=1,
+                                 padding=0)
+        self.v = torch.nn.Conv2d(in_channels,
+                                 in_channels,
+                                 kernel_size=1,
+                                 stride=1,
+                                 padding=0)
+        self.proj_out = torch.nn.Conv2d(in_channels,
+                                        in_channels,
+                                        kernel_size=1,
+                                        stride=1,
+                                        padding=0)
+
+    def forward(self, x):
+        h_ = x
+        h_ = self.norm(h_)
+        q = self.q(h_)
+        k = self.k(h_)
+        v = self.v(h_)
+
+        # compute attention
+        b,c,h,w = q.shape
+        q = rearrange(q, 'b c h w -> b (h w) c')
+        k = rearrange(k, 'b c h w -> b c (h w)')
+        w_ = torch.einsum('bij,bjk->bik', q, k)
+
+        w_ = w_ * (int(c)**(-0.5))
+        w_ = torch.nn.functional.softmax(w_, dim=2)
+
+        # attend to values
+        v = rearrange(v, 'b c h w -> b c (h w)')
+        w_ = rearrange(w_, 'b i j -> b j i')
+        h_ = torch.einsum('bij,bjk->bik', v, w_)
+        h_ = rearrange(h_, 'b c (h w) -> b c h w', h=h)
+        h_ = self.proj_out(h_)
+
+        return x+h_
+
+
+class CrossAttention(nn.Module):
+    def __init__(self, query_dim, context_dim=None, heads=8, dim_head=64, dropout=0.):
+        super().__init__()
+        inner_dim = dim_head * heads
+        context_dim = default(context_dim, query_dim)
+
+        self.scale = dim_head ** -0.5
+        self.heads = heads
+
+        self.to_q = nn.Linear(query_dim, inner_dim, bias=False)
+        self.to_k = nn.Linear(context_dim, inner_dim, bias=False)
+        self.to_v = nn.Linear(context_dim, inner_dim, bias=False)
+
+        self.to_out = nn.Sequential(
+            nn.Linear(inner_dim, query_dim),
+            nn.Dropout(dropout)
+        )
+
+    def forward(self, x, context=None, mask=None):
+        h = self.heads
+
+        q = self.to_q(x)
+        context = default(context, x)
+        k = self.to_k(context)
+        v = self.to_v(context)
+
+        q, k, v = map(lambda t: rearrange(t, 'b n (h d) -> (b h) n d', h=h), (q, k, v))
+
+        sim = einsum('b i d, b j d -> b i j', q, k) * self.scale
+
+        if exists(mask):
+            mask = rearrange(mask, 'b ... -> b (...)')
+            max_neg_value = -torch.finfo(sim.dtype).max
+            mask = repeat(mask, 'b j -> (b h) () j', h=h)
+            sim.masked_fill_(~mask, max_neg_value)
+
+        # attention, what we cannot get enough of
+        attn = sim.softmax(dim=-1)
+
+        out = einsum('b i j, b j d -> b i d', attn, v)
+        out = rearrange(out, '(b h) n d -> b n (h d)', h=h)
+        return self.to_out(out)
+
+
+class BasicTransformerBlock(nn.Module):
+    def __init__(self, dim, n_heads, d_head, dropout=0., context_dim=None, gated_ff=True, checkpoint=True):
+        super().__init__()
+        self.attn1 = CrossAttention(query_dim=dim, heads=n_heads, dim_head=d_head, dropout=dropout)  # is a self-attention
+        self.ff = FeedForward(dim, dropout=dropout, glu=gated_ff)
+        self.attn2 = CrossAttention(query_dim=dim, context_dim=context_dim,
+                                    heads=n_heads, dim_head=d_head, dropout=dropout)  # is self-attn if context is none
+        self.norm1 = nn.LayerNorm(dim)
+        self.norm2 = nn.LayerNorm(dim)
+        self.norm3 = nn.LayerNorm(dim)
+        self.checkpoint = checkpoint
+
+    def forward(self, x, context=None):
+        return checkpoint(self._forward, (x, context), self.parameters(), self.checkpoint)
+
+    def _forward(self, x, context=None):
+        x = self.attn1(self.norm1(x)) + x
+        x = self.attn2(self.norm2(x), context=context) + x
+        x = self.ff(self.norm3(x)) + x
+        return x
+
+
+class SpatialTransformer(nn.Module):
+    """
+    Transformer block for image-like data.
+    First, project the input (aka embedding)
+    and reshape to b, t, d.
+    Then apply standard transformer action.
+    Finally, reshape to image
+    """
+    def __init__(self, in_channels, n_heads, d_head,
+                 depth=1, dropout=0., context_dim=None):
+        super().__init__()
+        self.in_channels = in_channels
+        inner_dim = n_heads * d_head
+        self.norm = Normalize(in_channels)
+
+        self.proj_in = nn.Conv2d(in_channels,
+                                 inner_dim,
+                                 kernel_size=1,
+                                 stride=1,
+                                 padding=0)
+
+        self.transformer_blocks = nn.ModuleList(
+            [BasicTransformerBlock(inner_dim, n_heads, d_head, dropout=dropout, context_dim=context_dim)
+                for d in range(depth)]
+        )
+
+        self.proj_out = zero_module(nn.Conv2d(inner_dim,
+                                              in_channels,
+                                              kernel_size=1,
+                                              stride=1,
+                                              padding=0))
+
+    def forward(self, x, context=None):
+        # note: if no context is given, cross-attention defaults to self-attention
+        b, c, h, w = x.shape
+        x_in = x
+        x = self.norm(x)
+        x = self.proj_in(x)
+        x = rearrange(x, 'b c h w -> b (h w) c')
+        for block in self.transformer_blocks:
+            x = block(x, context=context)
+        x = rearrange(x, 'b (h w) c -> b c h w', h=h, w=w)
+        x = self.proj_out(x)
+        return x + x_in

+ 0 - 0
ldm/modules/diffusionmodules/__init__.py


+ 835 - 0
ldm/modules/diffusionmodules/model.py

@@ -0,0 +1,835 @@
+# pytorch_diffusion + derived encoder decoder
+import math
+import torch
+import torch.nn as nn
+import numpy as np
+from einops import rearrange
+
+from ldm.util import instantiate_from_config
+from ldm.modules.attention import LinearAttention
+
+
+def get_timestep_embedding(timesteps, embedding_dim):
+    """
+    This matches the implementation in Denoising Diffusion Probabilistic Models:
+    From Fairseq.
+    Build sinusoidal embeddings.
+    This matches the implementation in tensor2tensor, but differs slightly
+    from the description in Section 3.5 of "Attention Is All You Need".
+    """
+    assert len(timesteps.shape) == 1
+
+    half_dim = embedding_dim // 2
+    emb = math.log(10000) / (half_dim - 1)
+    emb = torch.exp(torch.arange(half_dim, dtype=torch.float32) * -emb)
+    emb = emb.to(device=timesteps.device)
+    emb = timesteps.float()[:, None] * emb[None, :]
+    emb = torch.cat([torch.sin(emb), torch.cos(emb)], dim=1)
+    if embedding_dim % 2 == 1:  # zero pad
+        emb = torch.nn.functional.pad(emb, (0,1,0,0))
+    return emb
+
+
+def nonlinearity(x):
+    # swish
+    return x*torch.sigmoid(x)
+
+
+def Normalize(in_channels, num_groups=32):
+    return torch.nn.GroupNorm(num_groups=num_groups, num_channels=in_channels, eps=1e-6, affine=True)
+
+
+class Upsample(nn.Module):
+    def __init__(self, in_channels, with_conv):
+        super().__init__()
+        self.with_conv = with_conv
+        if self.with_conv:
+            self.conv = torch.nn.Conv2d(in_channels,
+                                        in_channels,
+                                        kernel_size=3,
+                                        stride=1,
+                                        padding=1)
+
+    def forward(self, x):
+        x = torch.nn.functional.interpolate(x, scale_factor=2.0, mode="nearest")
+        if self.with_conv:
+            x = self.conv(x)
+        return x
+
+
+class Downsample(nn.Module):
+    def __init__(self, in_channels, with_conv):
+        super().__init__()
+        self.with_conv = with_conv
+        if self.with_conv:
+            # no asymmetric padding in torch conv, must do it ourselves
+            self.conv = torch.nn.Conv2d(in_channels,
+                                        in_channels,
+                                        kernel_size=3,
+                                        stride=2,
+                                        padding=0)
+
+    def forward(self, x):
+        if self.with_conv:
+            pad = (0,1,0,1)
+            x = torch.nn.functional.pad(x, pad, mode="constant", value=0)
+            x = self.conv(x)
+        else:
+            x = torch.nn.functional.avg_pool2d(x, kernel_size=2, stride=2)
+        return x
+
+
+class ResnetBlock(nn.Module):
+    def __init__(self, *, in_channels, out_channels=None, conv_shortcut=False,
+                 dropout, temb_channels=512):
+        super().__init__()
+        self.in_channels = in_channels
+        out_channels = in_channels if out_channels is None else out_channels
+        self.out_channels = out_channels
+        self.use_conv_shortcut = conv_shortcut
+
+        self.norm1 = Normalize(in_channels)
+        self.conv1 = torch.nn.Conv2d(in_channels,
+                                     out_channels,
+                                     kernel_size=3,
+                                     stride=1,
+                                     padding=1)
+        if temb_channels > 0:
+            self.temb_proj = torch.nn.Linear(temb_channels,
+                                             out_channels)
+        self.norm2 = Normalize(out_channels)
+        self.dropout = torch.nn.Dropout(dropout)
+        self.conv2 = torch.nn.Conv2d(out_channels,
+                                     out_channels,
+                                     kernel_size=3,
+                                     stride=1,
+                                     padding=1)
+        if self.in_channels != self.out_channels:
+            if self.use_conv_shortcut:
+                self.conv_shortcut = torch.nn.Conv2d(in_channels,
+                                                     out_channels,
+                                                     kernel_size=3,
+                                                     stride=1,
+                                                     padding=1)
+            else:
+                self.nin_shortcut = torch.nn.Conv2d(in_channels,
+                                                    out_channels,
+                                                    kernel_size=1,
+                                                    stride=1,
+                                                    padding=0)
+
+    def forward(self, x, temb):
+        h = x
+        h = self.norm1(h)
+        h = nonlinearity(h)
+        h = self.conv1(h)
+
+        if temb is not None:
+            h = h + self.temb_proj(nonlinearity(temb))[:,:,None,None]
+
+        h = self.norm2(h)
+        h = nonlinearity(h)
+        h = self.dropout(h)
+        h = self.conv2(h)
+
+        if self.in_channels != self.out_channels:
+            if self.use_conv_shortcut:
+                x = self.conv_shortcut(x)
+            else:
+                x = self.nin_shortcut(x)
+
+        return x+h
+
+
+class LinAttnBlock(LinearAttention):
+    """to match AttnBlock usage"""
+    def __init__(self, in_channels):
+        super().__init__(dim=in_channels, heads=1, dim_head=in_channels)
+
+
+class AttnBlock(nn.Module):
+    def __init__(self, in_channels):
+        super().__init__()
+        self.in_channels = in_channels
+
+        self.norm = Normalize(in_channels)
+        self.q = torch.nn.Conv2d(in_channels,
+                                 in_channels,
+                                 kernel_size=1,
+                                 stride=1,
+                                 padding=0)
+        self.k = torch.nn.Conv2d(in_channels,
+                                 in_channels,
+                                 kernel_size=1,
+                                 stride=1,
+                                 padding=0)
+        self.v = torch.nn.Conv2d(in_channels,
+                                 in_channels,
+                                 kernel_size=1,
+                                 stride=1,
+                                 padding=0)
+        self.proj_out = torch.nn.Conv2d(in_channels,
+                                        in_channels,
+                                        kernel_size=1,
+                                        stride=1,
+                                        padding=0)
+
+
+    def forward(self, x):
+        h_ = x
+        h_ = self.norm(h_)
+        q = self.q(h_)
+        k = self.k(h_)
+        v = self.v(h_)
+
+        # compute attention
+        b,c,h,w = q.shape
+        q = q.reshape(b,c,h*w)
+        q = q.permute(0,2,1)   # b,hw,c
+        k = k.reshape(b,c,h*w) # b,c,hw
+        w_ = torch.bmm(q,k)     # b,hw,hw    w[b,i,j]=sum_c q[b,i,c]k[b,c,j]
+        w_ = w_ * (int(c)**(-0.5))
+        w_ = torch.nn.functional.softmax(w_, dim=2)
+
+        # attend to values
+        v = v.reshape(b,c,h*w)
+        w_ = w_.permute(0,2,1)   # b,hw,hw (first hw of k, second of q)
+        h_ = torch.bmm(v,w_)     # b, c,hw (hw of q) h_[b,c,j] = sum_i v[b,c,i] w_[b,i,j]
+        h_ = h_.reshape(b,c,h,w)
+
+        h_ = self.proj_out(h_)
+
+        return x+h_
+
+
+def make_attn(in_channels, attn_type="vanilla"):
+    assert attn_type in ["vanilla", "linear", "none"], f'attn_type {attn_type} unknown'
+    print(f"making attention of type '{attn_type}' with {in_channels} in_channels")
+    if attn_type == "vanilla":
+        return AttnBlock(in_channels)
+    elif attn_type == "none":
+        return nn.Identity(in_channels)
+    else:
+        return LinAttnBlock(in_channels)
+
+
+class Model(nn.Module):
+    def __init__(self, *, ch, out_ch, ch_mult=(1,2,4,8), num_res_blocks,
+                 attn_resolutions, dropout=0.0, resamp_with_conv=True, in_channels,
+                 resolution, use_timestep=True, use_linear_attn=False, attn_type="vanilla"):
+        super().__init__()
+        if use_linear_attn: attn_type = "linear"
+        self.ch = ch
+        self.temb_ch = self.ch*4
+        self.num_resolutions = len(ch_mult)
+        self.num_res_blocks = num_res_blocks
+        self.resolution = resolution
+        self.in_channels = in_channels
+
+        self.use_timestep = use_timestep
+        if self.use_timestep:
+            # timestep embedding
+            self.temb = nn.Module()
+            self.temb.dense = nn.ModuleList([
+                torch.nn.Linear(self.ch,
+                                self.temb_ch),
+                torch.nn.Linear(self.temb_ch,
+                                self.temb_ch),
+            ])
+
+        # downsampling
+        self.conv_in = torch.nn.Conv2d(in_channels,
+                                       self.ch,
+                                       kernel_size=3,
+                                       stride=1,
+                                       padding=1)
+
+        curr_res = resolution
+        in_ch_mult = (1,)+tuple(ch_mult)
+        self.down = nn.ModuleList()
+        for i_level in range(self.num_resolutions):
+            block = nn.ModuleList()
+            attn = nn.ModuleList()
+            block_in = ch*in_ch_mult[i_level]
+            block_out = ch*ch_mult[i_level]
+            for i_block in range(self.num_res_blocks):
+                block.append(ResnetBlock(in_channels=block_in,
+                                         out_channels=block_out,
+                                         temb_channels=self.temb_ch,
+                                         dropout=dropout))
+                block_in = block_out
+                if curr_res in attn_resolutions:
+                    attn.append(make_attn(block_in, attn_type=attn_type))
+            down = nn.Module()
+            down.block = block
+            down.attn = attn
+            if i_level != self.num_resolutions-1:
+                down.downsample = Downsample(block_in, resamp_with_conv)
+                curr_res = curr_res // 2
+            self.down.append(down)
+
+        # middle
+        self.mid = nn.Module()
+        self.mid.block_1 = ResnetBlock(in_channels=block_in,
+                                       out_channels=block_in,
+                                       temb_channels=self.temb_ch,
+                                       dropout=dropout)
+        self.mid.attn_1 = make_attn(block_in, attn_type=attn_type)
+        self.mid.block_2 = ResnetBlock(in_channels=block_in,
+                                       out_channels=block_in,
+                                       temb_channels=self.temb_ch,
+                                       dropout=dropout)
+
+        # upsampling
+        self.up = nn.ModuleList()
+        for i_level in reversed(range(self.num_resolutions)):
+            block = nn.ModuleList()
+            attn = nn.ModuleList()
+            block_out = ch*ch_mult[i_level]
+            skip_in = ch*ch_mult[i_level]
+            for i_block in range(self.num_res_blocks+1):
+                if i_block == self.num_res_blocks:
+                    skip_in = ch*in_ch_mult[i_level]
+                block.append(ResnetBlock(in_channels=block_in+skip_in,
+                                         out_channels=block_out,
+                                         temb_channels=self.temb_ch,
+                                         dropout=dropout))
+                block_in = block_out
+                if curr_res in attn_resolutions:
+                    attn.append(make_attn(block_in, attn_type=attn_type))
+            up = nn.Module()
+            up.block = block
+            up.attn = attn
+            if i_level != 0:
+                up.upsample = Upsample(block_in, resamp_with_conv)
+                curr_res = curr_res * 2
+            self.up.insert(0, up) # prepend to get consistent order
+
+        # end
+        self.norm_out = Normalize(block_in)
+        self.conv_out = torch.nn.Conv2d(block_in,
+                                        out_ch,
+                                        kernel_size=3,
+                                        stride=1,
+                                        padding=1)
+
+    def forward(self, x, t=None, context=None):
+        #assert x.shape[2] == x.shape[3] == self.resolution
+        if context is not None:
+            # assume aligned context, cat along channel axis
+            x = torch.cat((x, context), dim=1)
+        if self.use_timestep:
+            # timestep embedding
+            assert t is not None
+            temb = get_timestep_embedding(t, self.ch)
+            temb = self.temb.dense[0](temb)
+            temb = nonlinearity(temb)
+            temb = self.temb.dense[1](temb)
+        else:
+            temb = None
+
+        # downsampling
+        hs = [self.conv_in(x)]
+        for i_level in range(self.num_resolutions):
+            for i_block in range(self.num_res_blocks):
+                h = self.down[i_level].block[i_block](hs[-1], temb)
+                if len(self.down[i_level].attn) > 0:
+                    h = self.down[i_level].attn[i_block](h)
+                hs.append(h)
+            if i_level != self.num_resolutions-1:
+                hs.append(self.down[i_level].downsample(hs[-1]))
+
+        # middle
+        h = hs[-1]
+        h = self.mid.block_1(h, temb)
+        h = self.mid.attn_1(h)
+        h = self.mid.block_2(h, temb)
+
+        # upsampling
+        for i_level in reversed(range(self.num_resolutions)):
+            for i_block in range(self.num_res_blocks+1):
+                h = self.up[i_level].block[i_block](
+                    torch.cat([h, hs.pop()], dim=1), temb)
+                if len(self.up[i_level].attn) > 0:
+                    h = self.up[i_level].attn[i_block](h)
+            if i_level != 0:
+                h = self.up[i_level].upsample(h)
+
+        # end
+        h = self.norm_out(h)
+        h = nonlinearity(h)
+        h = self.conv_out(h)
+        return h
+
+    def get_last_layer(self):
+        return self.conv_out.weight
+
+
+class Encoder(nn.Module):
+    def __init__(self, *, ch, out_ch, ch_mult=(1,2,4,8), num_res_blocks,
+                 attn_resolutions, dropout=0.0, resamp_with_conv=True, in_channels,
+                 resolution, z_channels, double_z=True, use_linear_attn=False, attn_type="vanilla",
+                 **ignore_kwargs):
+        super().__init__()
+        if use_linear_attn: attn_type = "linear"
+        self.ch = ch
+        self.temb_ch = 0
+        self.num_resolutions = len(ch_mult)
+        self.num_res_blocks = num_res_blocks
+        self.resolution = resolution
+        self.in_channels = in_channels
+
+        # downsampling
+        self.conv_in = torch.nn.Conv2d(in_channels,
+                                       self.ch,
+                                       kernel_size=3,
+                                       stride=1,
+                                       padding=1)
+
+        curr_res = resolution
+        in_ch_mult = (1,)+tuple(ch_mult)
+        self.in_ch_mult = in_ch_mult
+        self.down = nn.ModuleList()
+        for i_level in range(self.num_resolutions):
+            block = nn.ModuleList()
+            attn = nn.ModuleList()
+            block_in = ch*in_ch_mult[i_level]
+            block_out = ch*ch_mult[i_level]
+            for i_block in range(self.num_res_blocks):
+                block.append(ResnetBlock(in_channels=block_in,
+                                         out_channels=block_out,
+                                         temb_channels=self.temb_ch,
+                                         dropout=dropout))
+                block_in = block_out
+                if curr_res in attn_resolutions:
+                    attn.append(make_attn(block_in, attn_type=attn_type))
+            down = nn.Module()
+            down.block = block
+            down.attn = attn
+            if i_level != self.num_resolutions-1:
+                down.downsample = Downsample(block_in, resamp_with_conv)
+                curr_res = curr_res // 2
+            self.down.append(down)
+
+        # middle
+        self.mid = nn.Module()
+        self.mid.block_1 = ResnetBlock(in_channels=block_in,
+                                       out_channels=block_in,
+                                       temb_channels=self.temb_ch,
+                                       dropout=dropout)
+        self.mid.attn_1 = make_attn(block_in, attn_type=attn_type)
+        self.mid.block_2 = ResnetBlock(in_channels=block_in,
+                                       out_channels=block_in,
+                                       temb_channels=self.temb_ch,
+                                       dropout=dropout)
+
+        # end
+        self.norm_out = Normalize(block_in)
+        self.conv_out = torch.nn.Conv2d(block_in,
+                                        2*z_channels if double_z else z_channels,
+                                        kernel_size=3,
+                                        stride=1,
+                                        padding=1)
+
+    def forward(self, x):
+        # timestep embedding
+        temb = None
+
+        # downsampling
+        hs = [self.conv_in(x)]
+        for i_level in range(self.num_resolutions):
+            for i_block in range(self.num_res_blocks):
+                h = self.down[i_level].block[i_block](hs[-1], temb)
+                if len(self.down[i_level].attn) > 0:
+                    h = self.down[i_level].attn[i_block](h)
+                hs.append(h)
+            if i_level != self.num_resolutions-1:
+                hs.append(self.down[i_level].downsample(hs[-1]))
+
+        # middle
+        h = hs[-1]
+        h = self.mid.block_1(h, temb)
+        h = self.mid.attn_1(h)
+        h = self.mid.block_2(h, temb)
+
+        # end
+        h = self.norm_out(h)
+        h = nonlinearity(h)
+        h = self.conv_out(h)
+        return h
+
+
+class Decoder(nn.Module):
+    def __init__(self, *, ch, out_ch, ch_mult=(1,2,4,8), num_res_blocks,
+                 attn_resolutions, dropout=0.0, resamp_with_conv=True, in_channels,
+                 resolution, z_channels, give_pre_end=False, tanh_out=False, use_linear_attn=False,
+                 attn_type="vanilla", **ignorekwargs):
+        super().__init__()
+        if use_linear_attn: attn_type = "linear"
+        self.ch = ch
+        self.temb_ch = 0
+        self.num_resolutions = len(ch_mult)
+        self.num_res_blocks = num_res_blocks
+        self.resolution = resolution
+        self.in_channels = in_channels
+        self.give_pre_end = give_pre_end
+        self.tanh_out = tanh_out
+
+        # compute in_ch_mult, block_in and curr_res at lowest res
+        in_ch_mult = (1,)+tuple(ch_mult)
+        block_in = ch*ch_mult[self.num_resolutions-1]
+        curr_res = resolution // 2**(self.num_resolutions-1)
+        self.z_shape = (1,z_channels,curr_res,curr_res)
+        print("Working with z of shape {} = {} dimensions.".format(
+            self.z_shape, np.prod(self.z_shape)))
+
+        # z to block_in
+        self.conv_in = torch.nn.Conv2d(z_channels,
+                                       block_in,
+                                       kernel_size=3,
+                                       stride=1,
+                                       padding=1)
+
+        # middle
+        self.mid = nn.Module()
+        self.mid.block_1 = ResnetBlock(in_channels=block_in,
+                                       out_channels=block_in,
+                                       temb_channels=self.temb_ch,
+                                       dropout=dropout)
+        self.mid.attn_1 = make_attn(block_in, attn_type=attn_type)
+        self.mid.block_2 = ResnetBlock(in_channels=block_in,
+                                       out_channels=block_in,
+                                       temb_channels=self.temb_ch,
+                                       dropout=dropout)
+
+        # upsampling
+        self.up = nn.ModuleList()
+        for i_level in reversed(range(self.num_resolutions)):
+            block = nn.ModuleList()
+            attn = nn.ModuleList()
+            block_out = ch*ch_mult[i_level]
+            for i_block in range(self.num_res_blocks+1):
+                block.append(ResnetBlock(in_channels=block_in,
+                                         out_channels=block_out,
+                                         temb_channels=self.temb_ch,
+                                         dropout=dropout))
+                block_in = block_out
+                if curr_res in attn_resolutions:
+                    attn.append(make_attn(block_in, attn_type=attn_type))
+            up = nn.Module()
+            up.block = block
+            up.attn = attn
+            if i_level != 0:
+                up.upsample = Upsample(block_in, resamp_with_conv)
+                curr_res = curr_res * 2
+            self.up.insert(0, up) # prepend to get consistent order
+
+        # end
+        self.norm_out = Normalize(block_in)
+        self.conv_out = torch.nn.Conv2d(block_in,
+                                        out_ch,
+                                        kernel_size=3,
+                                        stride=1,
+                                        padding=1)
+
+    def forward(self, z):
+        #assert z.shape[1:] == self.z_shape[1:]
+        self.last_z_shape = z.shape
+
+        # timestep embedding
+        temb = None
+
+        # z to block_in
+        h = self.conv_in(z)
+
+        # middle
+        h = self.mid.block_1(h, temb)
+        h = self.mid.attn_1(h)
+        h = self.mid.block_2(h, temb)
+
+        # upsampling
+        for i_level in reversed(range(self.num_resolutions)):
+            for i_block in range(self.num_res_blocks+1):
+                h = self.up[i_level].block[i_block](h, temb)
+                if len(self.up[i_level].attn) > 0:
+                    h = self.up[i_level].attn[i_block](h)
+            if i_level != 0:
+                h = self.up[i_level].upsample(h)
+
+        # end
+        if self.give_pre_end:
+            return h
+
+        h = self.norm_out(h)
+        h = nonlinearity(h)
+        h = self.conv_out(h)
+        if self.tanh_out:
+            h = torch.tanh(h)
+        return h
+
+
+class SimpleDecoder(nn.Module):
+    def __init__(self, in_channels, out_channels, *args, **kwargs):
+        super().__init__()
+        self.model = nn.ModuleList([nn.Conv2d(in_channels, in_channels, 1),
+                                     ResnetBlock(in_channels=in_channels,
+                                                 out_channels=2 * in_channels,
+                                                 temb_channels=0, dropout=0.0),
+                                     ResnetBlock(in_channels=2 * in_channels,
+                                                out_channels=4 * in_channels,
+                                                temb_channels=0, dropout=0.0),
+                                     ResnetBlock(in_channels=4 * in_channels,
+                                                out_channels=2 * in_channels,
+                                                temb_channels=0, dropout=0.0),
+                                     nn.Conv2d(2*in_channels, in_channels, 1),
+                                     Upsample(in_channels, with_conv=True)])
+        # end
+        self.norm_out = Normalize(in_channels)
+        self.conv_out = torch.nn.Conv2d(in_channels,
+                                        out_channels,
+                                        kernel_size=3,
+                                        stride=1,
+                                        padding=1)
+
+    def forward(self, x):
+        for i, layer in enumerate(self.model):
+            if i in [1,2,3]:
+                x = layer(x, None)
+            else:
+                x = layer(x)
+
+        h = self.norm_out(x)
+        h = nonlinearity(h)
+        x = self.conv_out(h)
+        return x
+
+
+class UpsampleDecoder(nn.Module):
+    def __init__(self, in_channels, out_channels, ch, num_res_blocks, resolution,
+                 ch_mult=(2,2), dropout=0.0):
+        super().__init__()
+        # upsampling
+        self.temb_ch = 0
+        self.num_resolutions = len(ch_mult)
+        self.num_res_blocks = num_res_blocks
+        block_in = in_channels
+        curr_res = resolution // 2 ** (self.num_resolutions - 1)
+        self.res_blocks = nn.ModuleList()
+        self.upsample_blocks = nn.ModuleList()
+        for i_level in range(self.num_resolutions):
+            res_block = []
+            block_out = ch * ch_mult[i_level]
+            for i_block in range(self.num_res_blocks + 1):
+                res_block.append(ResnetBlock(in_channels=block_in,
+                                         out_channels=block_out,
+                                         temb_channels=self.temb_ch,
+                                         dropout=dropout))
+                block_in = block_out
+            self.res_blocks.append(nn.ModuleList(res_block))
+            if i_level != self.num_resolutions - 1:
+                self.upsample_blocks.append(Upsample(block_in, True))
+                curr_res = curr_res * 2
+
+        # end
+        self.norm_out = Normalize(block_in)
+        self.conv_out = torch.nn.Conv2d(block_in,
+                                        out_channels,
+                                        kernel_size=3,
+                                        stride=1,
+                                        padding=1)
+
+    def forward(self, x):
+        # upsampling
+        h = x
+        for k, i_level in enumerate(range(self.num_resolutions)):
+            for i_block in range(self.num_res_blocks + 1):
+                h = self.res_blocks[i_level][i_block](h, None)
+            if i_level != self.num_resolutions - 1:
+                h = self.upsample_blocks[k](h)
+        h = self.norm_out(h)
+        h = nonlinearity(h)
+        h = self.conv_out(h)
+        return h
+
+
+class LatentRescaler(nn.Module):
+    def __init__(self, factor, in_channels, mid_channels, out_channels, depth=2):
+        super().__init__()
+        # residual block, interpolate, residual block
+        self.factor = factor
+        self.conv_in = nn.Conv2d(in_channels,
+                                 mid_channels,
+                                 kernel_size=3,
+                                 stride=1,
+                                 padding=1)
+        self.res_block1 = nn.ModuleList([ResnetBlock(in_channels=mid_channels,
+                                                     out_channels=mid_channels,
+                                                     temb_channels=0,
+                                                     dropout=0.0) for _ in range(depth)])
+        self.attn = AttnBlock(mid_channels)
+        self.res_block2 = nn.ModuleList([ResnetBlock(in_channels=mid_channels,
+                                                     out_channels=mid_channels,
+                                                     temb_channels=0,
+                                                     dropout=0.0) for _ in range(depth)])
+
+        self.conv_out = nn.Conv2d(mid_channels,
+                                  out_channels,
+                                  kernel_size=1,
+                                  )
+
+    def forward(self, x):
+        x = self.conv_in(x)
+        for block in self.res_block1:
+            x = block(x, None)
+        x = torch.nn.functional.interpolate(x, size=(int(round(x.shape[2]*self.factor)), int(round(x.shape[3]*self.factor))))
+        x = self.attn(x)
+        for block in self.res_block2:
+            x = block(x, None)
+        x = self.conv_out(x)
+        return x
+
+
+class MergedRescaleEncoder(nn.Module):
+    def __init__(self, in_channels, ch, resolution, out_ch, num_res_blocks,
+                 attn_resolutions, dropout=0.0, resamp_with_conv=True,
+                 ch_mult=(1,2,4,8), rescale_factor=1.0, rescale_module_depth=1):
+        super().__init__()
+        intermediate_chn = ch * ch_mult[-1]
+        self.encoder = Encoder(in_channels=in_channels, num_res_blocks=num_res_blocks, ch=ch, ch_mult=ch_mult,
+                               z_channels=intermediate_chn, double_z=False, resolution=resolution,
+                               attn_resolutions=attn_resolutions, dropout=dropout, resamp_with_conv=resamp_with_conv,
+                               out_ch=None)
+        self.rescaler = LatentRescaler(factor=rescale_factor, in_channels=intermediate_chn,
+                                       mid_channels=intermediate_chn, out_channels=out_ch, depth=rescale_module_depth)
+
+    def forward(self, x):
+        x = self.encoder(x)
+        x = self.rescaler(x)
+        return x
+
+
+class MergedRescaleDecoder(nn.Module):
+    def __init__(self, z_channels, out_ch, resolution, num_res_blocks, attn_resolutions, ch, ch_mult=(1,2,4,8),
+                 dropout=0.0, resamp_with_conv=True, rescale_factor=1.0, rescale_module_depth=1):
+        super().__init__()
+        tmp_chn = z_channels*ch_mult[-1]
+        self.decoder = Decoder(out_ch=out_ch, z_channels=tmp_chn, attn_resolutions=attn_resolutions, dropout=dropout,
+                               resamp_with_conv=resamp_with_conv, in_channels=None, num_res_blocks=num_res_blocks,
+                               ch_mult=ch_mult, resolution=resolution, ch=ch)
+        self.rescaler = LatentRescaler(factor=rescale_factor, in_channels=z_channels, mid_channels=tmp_chn,
+                                       out_channels=tmp_chn, depth=rescale_module_depth)
+
+    def forward(self, x):
+        x = self.rescaler(x)
+        x = self.decoder(x)
+        return x
+
+
+class Upsampler(nn.Module):
+    def __init__(self, in_size, out_size, in_channels, out_channels, ch_mult=2):
+        super().__init__()
+        assert out_size >= in_size
+        num_blocks = int(np.log2(out_size//in_size))+1
+        factor_up = 1.+ (out_size % in_size)
+        print(f"Building {self.__class__.__name__} with in_size: {in_size} --> out_size {out_size} and factor {factor_up}")
+        self.rescaler = LatentRescaler(factor=factor_up, in_channels=in_channels, mid_channels=2*in_channels,
+                                       out_channels=in_channels)
+        self.decoder = Decoder(out_ch=out_channels, resolution=out_size, z_channels=in_channels, num_res_blocks=2,
+                               attn_resolutions=[], in_channels=None, ch=in_channels,
+                               ch_mult=[ch_mult for _ in range(num_blocks)])
+
+    def forward(self, x):
+        x = self.rescaler(x)
+        x = self.decoder(x)
+        return x
+
+
+class Resize(nn.Module):
+    def __init__(self, in_channels=None, learned=False, mode="bilinear"):
+        super().__init__()
+        self.with_conv = learned
+        self.mode = mode
+        if self.with_conv:
+            print(f"Note: {self.__class__.__name} uses learned downsampling and will ignore the fixed {mode} mode")
+            raise NotImplementedError()
+            assert in_channels is not None
+            # no asymmetric padding in torch conv, must do it ourselves
+            self.conv = torch.nn.Conv2d(in_channels,
+                                        in_channels,
+                                        kernel_size=4,
+                                        stride=2,
+                                        padding=1)
+
+    def forward(self, x, scale_factor=1.0):
+        if scale_factor==1.0:
+            return x
+        else:
+            x = torch.nn.functional.interpolate(x, mode=self.mode, align_corners=False, scale_factor=scale_factor)
+        return x
+
+class FirstStagePostProcessor(nn.Module):
+
+    def __init__(self, ch_mult:list, in_channels,
+                 pretrained_model:nn.Module=None,
+                 reshape=False,
+                 n_channels=None,
+                 dropout=0.,
+                 pretrained_config=None):
+        super().__init__()
+        if pretrained_config is None:
+            assert pretrained_model is not None, 'Either "pretrained_model" or "pretrained_config" must not be None'
+            self.pretrained_model = pretrained_model
+        else:
+            assert pretrained_config is not None, 'Either "pretrained_model" or "pretrained_config" must not be None'
+            self.instantiate_pretrained(pretrained_config)
+
+        self.do_reshape = reshape
+
+        if n_channels is None:
+            n_channels = self.pretrained_model.encoder.ch
+
+        self.proj_norm = Normalize(in_channels,num_groups=in_channels//2)
+        self.proj = nn.Conv2d(in_channels,n_channels,kernel_size=3,
+                            stride=1,padding=1)
+
+        blocks = []
+        downs = []
+        ch_in = n_channels
+        for m in ch_mult:
+            blocks.append(ResnetBlock(in_channels=ch_in,out_channels=m*n_channels,dropout=dropout))
+            ch_in = m * n_channels
+            downs.append(Downsample(ch_in, with_conv=False))
+
+        self.model = nn.ModuleList(blocks)
+        self.downsampler = nn.ModuleList(downs)
+
+
+    def instantiate_pretrained(self, config):
+        model = instantiate_from_config(config)
+        self.pretrained_model = model.eval()
+        # self.pretrained_model.train = False
+        for param in self.pretrained_model.parameters():
+            param.requires_grad = False
+
+
+    @torch.no_grad()
+    def encode_with_pretrained(self,x):
+        c = self.pretrained_model.encode(x)
+        if isinstance(c, DiagonalGaussianDistribution):
+            c = c.mode()
+        return  c
+
+    def forward(self,x):
+        z_fs = self.encode_with_pretrained(x)
+        z = self.proj_norm(z_fs)
+        z = self.proj(z)
+        z = nonlinearity(z)
+
+        for submodel, downmodel in zip(self.model,self.downsampler):
+            z = submodel(z,temb=None)
+            z = downmodel(z)
+
+        if self.do_reshape:
+            z = rearrange(z,'b c h w -> b (h w) c')
+        return z
+

+ 936 - 0
ldm/modules/diffusionmodules/openaimodel.py

@@ -0,0 +1,936 @@
+from abc import abstractmethod
+from functools import partial
+import math
+from typing import Iterable
+
+import numpy as np
+import torch as th
+import torch.nn as nn
+import torch.nn.functional as F
+
+from ldm.modules.diffusionmodules.util import (
+    checkpoint,
+    conv_nd,
+    linear,
+    avg_pool_nd,
+    zero_module,
+    normalization,
+    timestep_embedding,
+)
+from ldm.modules.attention import SpatialTransformer
+
+
+# dummy replace
+def convert_module_to_f16(x):
+    pass
+
+def convert_module_to_f32(x):
+    pass
+
+
+## go
+class AttentionPool2d(nn.Module):
+    """
+    Adapted from CLIP: https://github.com/openai/CLIP/blob/main/clip/model.py
+    """
+
+    def __init__(
+        self,
+        spacial_dim: int,
+        embed_dim: int,
+        num_heads_channels: int,
+        output_dim: int = None,
+    ):
+        super().__init__()
+        self.positional_embedding = nn.Parameter(th.randn(embed_dim, spacial_dim ** 2 + 1) / embed_dim ** 0.5)
+        self.qkv_proj = conv_nd(1, embed_dim, 3 * embed_dim, 1)
+        self.c_proj = conv_nd(1, embed_dim, output_dim or embed_dim, 1)
+        self.num_heads = embed_dim // num_heads_channels
+        self.attention = QKVAttention(self.num_heads)
+
+    def forward(self, x):
+        b, c, *_spatial = x.shape
+        x = x.reshape(b, c, -1)  # NC(HW)
+        x = th.cat([x.mean(dim=-1, keepdim=True), x], dim=-1)  # NC(HW+1)
+        x = x + self.positional_embedding[None, :, :].to(x.dtype)  # NC(HW+1)
+        x = self.qkv_proj(x)
+        x = self.attention(x)
+        x = self.c_proj(x)
+        return x[:, :, 0]
+
+
+class TimestepBlock(nn.Module):
+    """
+    Any module where forward() takes timestep embeddings as a second argument.
+    """
+
+    @abstractmethod
+    def forward(self, x, emb):
+        """
+        Apply the module to `x` given `emb` timestep embeddings.
+        """
+
+
+class TimestepEmbedSequential(nn.Sequential, TimestepBlock):
+    """
+    A sequential module that passes timestep embeddings to the children that
+    support it as an extra input.
+    """
+
+    def forward(self, x, emb, context=None):
+        for layer in self:
+            if isinstance(layer, TimestepBlock):
+                x = layer(x, emb)
+            elif isinstance(layer, SpatialTransformer):
+                x = layer(x, context)
+            else:
+                x = layer(x)
+        return x
+
+
+class Upsample(nn.Module):
+    """
+    An upsampling layer with an optional convolution.
+    :param channels: channels in the inputs and outputs.
+    :param use_conv: a bool determining if a convolution is applied.
+    :param dims: determines if the signal is 1D, 2D, or 3D. If 3D, then
+                 upsampling occurs in the inner-two dimensions.
+    """
+
+    def __init__(self, channels, use_conv, dims=2, out_channels=None, padding=1):
+        super().__init__()
+        self.channels = channels
+        self.out_channels = out_channels or channels
+        self.use_conv = use_conv
+        self.dims = dims
+        if use_conv:
+            self.conv = conv_nd(dims, self.channels, self.out_channels, 3, padding=padding)
+
+    def forward(self, x):
+        assert x.shape[1] == self.channels
+        if self.dims == 3:
+            x = F.interpolate(
+                x, (x.shape[2], x.shape[3] * 2, x.shape[4] * 2), mode="nearest"
+            )
+        else:
+            x = F.interpolate(x, scale_factor=2, mode="nearest")
+        if self.use_conv:
+            x = self.conv(x)
+        return x
+
+class TransposedUpsample(nn.Module):
+    'Learned 2x upsampling without padding'
+    def __init__(self, channels, out_channels=None, ks=5):
+        super().__init__()
+        self.channels = channels
+        self.out_channels = out_channels or channels
+
+        self.up = nn.ConvTranspose2d(self.channels,self.out_channels,kernel_size=ks,stride=2)
+
+    def forward(self,x):
+        return self.up(x)
+
+
+class Downsample(nn.Module):
+    """
+    A downsampling layer with an optional convolution.
+    :param channels: channels in the inputs and outputs.
+    :param use_conv: a bool determining if a convolution is applied.
+    :param dims: determines if the signal is 1D, 2D, or 3D. If 3D, then
+                 downsampling occurs in the inner-two dimensions.
+    """
+
+    def __init__(self, channels, use_conv, dims=2, out_channels=None,padding=1):
+        super().__init__()
+        self.channels = channels
+        self.out_channels = out_channels or channels
+        self.use_conv = use_conv
+        self.dims = dims
+        stride = 2 if dims != 3 else (1, 2, 2)
+        if use_conv:
+            self.op = conv_nd(
+                dims, self.channels, self.out_channels, 3, stride=stride, padding=padding
+            )
+        else:
+            assert self.channels == self.out_channels
+            self.op = avg_pool_nd(dims, kernel_size=stride, stride=stride)
+
+    def forward(self, x):
+        assert x.shape[1] == self.channels
+        return self.op(x)
+
+
+class ResBlock(TimestepBlock):
+    """
+    A residual block that can optionally change the number of channels.
+    :param channels: the number of input channels.
+    :param emb_channels: the number of timestep embedding channels.
+    :param dropout: the rate of dropout.
+    :param out_channels: if specified, the number of out channels.
+    :param use_conv: if True and out_channels is specified, use a spatial
+        convolution instead of a smaller 1x1 convolution to change the
+        channels in the skip connection.
+    :param dims: determines if the signal is 1D, 2D, or 3D.
+    :param use_checkpoint: if True, use gradient checkpointing on this module.
+    :param up: if True, use this block for upsampling.
+    :param down: if True, use this block for downsampling.
+    """
+
+    def __init__(
+        self,
+        channels,
+        emb_channels,
+        dropout,
+        out_channels=None,
+        use_conv=False,
+        use_scale_shift_norm=False,
+        dims=2,
+        use_checkpoint=False,
+        up=False,
+        down=False,
+    ):
+        super().__init__()
+        self.channels = channels
+        self.emb_channels = emb_channels
+        self.dropout = dropout
+        self.out_channels = out_channels or channels
+        self.use_conv = use_conv
+        self.use_checkpoint = use_checkpoint
+        self.use_scale_shift_norm = use_scale_shift_norm
+
+        self.in_layers = nn.Sequential(
+            normalization(channels),
+            nn.SiLU(),
+            conv_nd(dims, channels, self.out_channels, 3, padding=1),
+        )
+
+        self.updown = up or down
+
+        if up:
+            self.h_upd = Upsample(channels, False, dims)
+            self.x_upd = Upsample(channels, False, dims)
+        elif down:
+            self.h_upd = Downsample(channels, False, dims)
+            self.x_upd = Downsample(channels, False, dims)
+        else:
+            self.h_upd = self.x_upd = nn.Identity()
+
+        self.emb_layers = nn.Sequential(
+            nn.SiLU(),
+            linear(
+                emb_channels,
+                2 * self.out_channels if use_scale_shift_norm else self.out_channels,
+            ),
+        )
+        self.out_layers = nn.Sequential(
+            normalization(self.out_channels),
+            nn.SiLU(),
+            nn.Dropout(p=dropout),
+            zero_module(
+                conv_nd(dims, self.out_channels, self.out_channels, 3, padding=1)
+            ),
+        )
+
+        if self.out_channels == channels:
+            self.skip_connection = nn.Identity()
+        elif use_conv:
+            self.skip_connection = conv_nd(
+                dims, channels, self.out_channels, 3, padding=1
+            )
+        else:
+            self.skip_connection = conv_nd(dims, channels, self.out_channels, 1)
+
+    def forward(self, x, emb):
+        """
+        Apply the block to a Tensor, conditioned on a timestep embedding.
+        :param x: an [N x C x ...] Tensor of features.
+        :param emb: an [N x emb_channels] Tensor of timestep embeddings.
+        :return: an [N x C x ...] Tensor of outputs.
+        """
+        return checkpoint(
+            self._forward, (x, emb), self.parameters(), self.use_checkpoint
+        )
+
+
+    def _forward(self, x, emb):
+        if self.updown:
+            in_rest, in_conv = self.in_layers[:-1], self.in_layers[-1]
+            h = in_rest(x)
+            h = self.h_upd(h)
+            x = self.x_upd(x)
+            h = in_conv(h)
+        else:
+            h = self.in_layers(x)
+        emb_out = self.emb_layers(emb).type(h.dtype)
+        while len(emb_out.shape) < len(h.shape):
+            emb_out = emb_out[..., None]
+        if self.use_scale_shift_norm:
+            out_norm, out_rest = self.out_layers[0], self.out_layers[1:]
+            scale, shift = th.chunk(emb_out, 2, dim=1)
+            h = out_norm(h) * (1 + scale) + shift
+            h = out_rest(h)
+        else:
+            h = h + emb_out
+            h = self.out_layers(h)
+        return self.skip_connection(x) + h
+
+
+class AttentionBlock(nn.Module):
+    """
+    An attention block that allows spatial positions to attend to each other.
+    Originally ported from here, but adapted to the N-d case.
+    https://github.com/hojonathanho/diffusion/blob/1e0dceb3b3495bbe19116a5e1b3596cd0706c543/diffusion_tf/models/unet.py#L66.
+    """
+
+    def __init__(
+        self,
+        channels,
+        num_heads=1,
+        num_head_channels=-1,
+        use_checkpoint=False,
+        use_new_attention_order=False,
+    ):
+        super().__init__()
+        self.channels = channels
+        if num_head_channels == -1:
+            self.num_heads = num_heads
+        else:
+            assert (
+                channels % num_head_channels == 0
+            ), f"q,k,v channels {channels} is not divisible by num_head_channels {num_head_channels}"
+            self.num_heads = channels // num_head_channels
+        self.use_checkpoint = use_checkpoint
+        self.norm = normalization(channels)
+        self.qkv = conv_nd(1, channels, channels * 3, 1)
+        if use_new_attention_order:
+            # split qkv before split heads
+            self.attention = QKVAttention(self.num_heads)
+        else:
+            # split heads before split qkv
+            self.attention = QKVAttentionLegacy(self.num_heads)
+
+        self.proj_out = zero_module(conv_nd(1, channels, channels, 1))
+
+    def forward(self, x):
+        return checkpoint(self._forward, (x,), self.parameters(), True)   # TODO: check checkpoint usage, is True # TODO: fix the .half call!!!
+        #return pt_checkpoint(self._forward, x)  # pytorch
+
+    def _forward(self, x):
+        b, c, *spatial = x.shape
+        x = x.reshape(b, c, -1)
+        qkv = self.qkv(self.norm(x))
+        h = self.attention(qkv)
+        h = self.proj_out(h)
+        return (x + h).reshape(b, c, *spatial)
+
+
+def count_flops_attn(model, _x, y):
+    """
+    A counter for the `thop` package to count the operations in an
+    attention operation.
+    Meant to be used like:
+        macs, params = thop.profile(
+            model,
+            inputs=(inputs, timestamps),
+            custom_ops={QKVAttention: QKVAttention.count_flops},
+        )
+    """
+    b, c, *spatial = y[0].shape
+    num_spatial = int(np.prod(spatial))
+    # We perform two matmuls with the same number of ops.
+    # The first computes the weight matrix, the second computes
+    # the combination of the value vectors.
+    matmul_ops = 2 * b * (num_spatial ** 2) * c
+    model.total_ops += th.DoubleTensor([matmul_ops])
+
+
+class QKVAttentionLegacy(nn.Module):
+    """
+    A module which performs QKV attention. Matches legacy QKVAttention + input/ouput heads shaping
+    """
+
+    def __init__(self, n_heads):
+        super().__init__()
+        self.n_heads = n_heads
+
+    def forward(self, qkv):
+        """
+        Apply QKV attention.
+        :param qkv: an [N x (H * 3 * C) x T] tensor of Qs, Ks, and Vs.
+        :return: an [N x (H * C) x T] tensor after attention.
+        """
+        bs, width, length = qkv.shape
+        assert width % (3 * self.n_heads) == 0
+        ch = width // (3 * self.n_heads)
+        q, k, v = qkv.reshape(bs * self.n_heads, ch * 3, length).split(ch, dim=1)
+        scale = 1 / math.sqrt(math.sqrt(ch))
+        weight = th.einsum(
+            "bct,bcs->bts", q * scale, k * scale
+        )  # More stable with f16 than dividing afterwards
+        weight = th.softmax(weight.float(), dim=-1).type(weight.dtype)
+        a = th.einsum("bts,bcs->bct", weight, v)
+        return a.reshape(bs, -1, length)
+
+    @staticmethod
+    def count_flops(model, _x, y):
+        return count_flops_attn(model, _x, y)
+
+
+class QKVAttention(nn.Module):
+    """
+    A module which performs QKV attention and splits in a different order.
+    """
+
+    def __init__(self, n_heads):
+        super().__init__()
+        self.n_heads = n_heads
+
+    def forward(self, qkv):
+        """
+        Apply QKV attention.
+        :param qkv: an [N x (3 * H * C) x T] tensor of Qs, Ks, and Vs.
+        :return: an [N x (H * C) x T] tensor after attention.
+        """
+        bs, width, length = qkv.shape
+        assert width % (3 * self.n_heads) == 0
+        ch = width // (3 * self.n_heads)
+        q, k, v = qkv.chunk(3, dim=1)
+        scale = 1 / math.sqrt(math.sqrt(ch))
+        weight = th.einsum(
+            "bct,bcs->bts",
+            (q * scale).view(bs * self.n_heads, ch, length),
+            (k * scale).view(bs * self.n_heads, ch, length),
+        )  # More stable with f16 than dividing afterwards
+        weight = th.softmax(weight.float(), dim=-1).type(weight.dtype)
+        a = th.einsum("bts,bcs->bct", weight, v.reshape(bs * self.n_heads, ch, length))
+        return a.reshape(bs, -1, length)
+
+    @staticmethod
+    def count_flops(model, _x, y):
+        return count_flops_attn(model, _x, y)
+
+
+class UNetModel(nn.Module):
+    """
+    The full UNet model with attention and timestep embedding.
+    :param in_channels: channels in the input Tensor.
+    :param model_channels: base channel count for the model.
+    :param out_channels: channels in the output Tensor.
+    :param num_res_blocks: number of residual blocks per downsample.
+    :param attention_resolutions: a collection of downsample rates at which
+        attention will take place. May be a set, list, or tuple.
+        For example, if this contains 4, then at 4x downsampling, attention
+        will be used.
+    :param dropout: the dropout probability.
+    :param channel_mult: channel multiplier for each level of the UNet.
+    :param conv_resample: if True, use learned convolutions for upsampling and
+        downsampling.
+    :param dims: determines if the signal is 1D, 2D, or 3D.
+    :param num_classes: if specified (as an int), then this model will be
+        class-conditional with `num_classes` classes.
+    :param use_checkpoint: use gradient checkpointing to reduce memory usage.
+    :param num_heads: the number of attention heads in each attention layer.
+    :param num_heads_channels: if specified, ignore num_heads and instead use
+                               a fixed channel width per attention head.
+    :param num_heads_upsample: works with num_heads to set a different number
+                               of heads for upsampling. Deprecated.
+    :param use_scale_shift_norm: use a FiLM-like conditioning mechanism.
+    :param resblock_updown: use residual blocks for up/downsampling.
+    :param use_new_attention_order: use a different attention pattern for potentially
+                                    increased efficiency.
+    """
+
+    def __init__(
+        self,
+        image_size,
+        in_channels,
+        model_channels,
+        out_channels,
+        num_res_blocks,
+        attention_resolutions,
+        dropout=0,
+        channel_mult=(1, 2, 4, 8),
+        conv_resample=True,
+        dims=2,
+        num_classes=None,
+        use_checkpoint=False,
+        use_fp16=False,
+        num_heads=1,
+        num_head_channels=-1,
+        num_heads_upsample=-1,
+        use_scale_shift_norm=False,
+        resblock_updown=False,
+        use_new_attention_order=False,
+        use_spatial_transformer=False,    # custom transformer support
+        transformer_depth=1,              # custom transformer support
+        context_dim=None,                 # custom transformer support
+        n_embed=None                      # custom support for prediction of discrete ids into codebook of first stage vq model
+    ):
+        super().__init__()
+
+        if use_spatial_transformer:
+            assert context_dim is not None, 'Fool!! You forgot to include the dimension of your cross-attention conditioning...'
+
+        if context_dim is not None:
+            assert use_spatial_transformer, 'Fool!! You forgot to use the spatial transformer for your cross-attention conditioning...'
+
+
+
+        if num_heads_upsample == -1:
+            num_heads_upsample = num_heads
+
+        self.image_size = image_size
+        self.in_channels = in_channels
+        self.model_channels = model_channels
+        self.out_channels = out_channels
+        self.num_res_blocks = num_res_blocks
+        self.attention_resolutions = attention_resolutions
+        self.dropout = dropout
+        self.channel_mult = channel_mult
+        self.conv_resample = conv_resample
+        self.num_classes = num_classes
+        self.use_checkpoint = use_checkpoint
+        self.dtype = th.float16 if use_fp16 else th.float32
+        self.num_heads = num_heads
+        self.num_head_channels = num_head_channels
+        self.num_heads_upsample = num_heads_upsample
+        self.predict_codebook_ids = n_embed is not None
+
+        time_embed_dim = model_channels * 4
+        self.time_embed = nn.Sequential(
+            linear(model_channels, time_embed_dim),
+            nn.SiLU(),
+            linear(time_embed_dim, time_embed_dim),
+        )
+
+        if self.num_classes is not None:
+            self.label_emb = nn.Embedding(num_classes, time_embed_dim)
+
+        self.input_blocks = nn.ModuleList(
+            [
+                TimestepEmbedSequential(
+                    conv_nd(dims, in_channels, model_channels, 3, padding=1)
+                )
+            ]
+        )
+        self._feature_size = model_channels
+        input_block_chans = [model_channels]
+        ch = model_channels
+        ds = 1
+        for level, mult in enumerate(channel_mult):
+            for _ in range(num_res_blocks):
+                layers = [
+                    ResBlock(
+                        ch,
+                        time_embed_dim,
+                        dropout,
+                        out_channels=mult * model_channels,
+                        dims=dims,
+                        use_checkpoint=use_checkpoint,
+                        use_scale_shift_norm=use_scale_shift_norm,
+                    )
+                ]
+                ch = mult * model_channels
+                if ds in attention_resolutions:
+                    dim_head = ch // num_heads
+                    layers.append(
+                        AttentionBlock(
+                            ch,
+                            use_checkpoint=use_checkpoint,
+                            num_heads=num_heads,
+                            num_head_channels=num_head_channels,
+                            use_new_attention_order=use_new_attention_order,
+                        ) if not use_spatial_transformer else SpatialTransformer(
+                            ch, num_heads, dim_head, depth=transformer_depth, context_dim=context_dim
+                        )
+                    )
+                self.input_blocks.append(TimestepEmbedSequential(*layers))
+                self._feature_size += ch
+                input_block_chans.append(ch)
+            if level != len(channel_mult) - 1:
+                out_ch = ch
+                self.input_blocks.append(
+                    TimestepEmbedSequential(
+                        ResBlock(
+                            ch,
+                            time_embed_dim,
+                            dropout,
+                            out_channels=out_ch,
+                            dims=dims,
+                            use_checkpoint=use_checkpoint,
+                            use_scale_shift_norm=use_scale_shift_norm,
+                            down=True,
+                        )
+                        if resblock_updown
+                        else Downsample(
+                            ch, conv_resample, dims=dims, out_channels=out_ch
+                        )
+                    )
+                )
+                ch = out_ch
+                input_block_chans.append(ch)
+                ds *= 2
+                self._feature_size += ch
+
+        dim_head = ch // num_heads
+        self.middle_block = TimestepEmbedSequential(
+            ResBlock(
+                ch,
+                time_embed_dim,
+                dropout,
+                dims=dims,
+                use_checkpoint=use_checkpoint,
+                use_scale_shift_norm=use_scale_shift_norm,
+            ),
+            AttentionBlock(
+                ch,
+                use_checkpoint=use_checkpoint,
+                num_heads=num_heads,
+                num_head_channels=num_head_channels,
+                use_new_attention_order=use_new_attention_order,
+            ) if not use_spatial_transformer else SpatialTransformer(
+                            ch, num_heads, dim_head, depth=transformer_depth, context_dim=context_dim
+                        ),
+            ResBlock(
+                ch,
+                time_embed_dim,
+                dropout,
+                dims=dims,
+                use_checkpoint=use_checkpoint,
+                use_scale_shift_norm=use_scale_shift_norm,
+            ),
+        )
+        self._feature_size += ch
+
+        self.output_blocks = nn.ModuleList([])
+        for level, mult in list(enumerate(channel_mult))[::-1]:
+            for i in range(num_res_blocks + 1):
+                ich = input_block_chans.pop()
+                layers = [
+                    ResBlock(
+                        ch + ich,
+                        time_embed_dim,
+                        dropout,
+                        out_channels=model_channels * mult,
+                        dims=dims,
+                        use_checkpoint=use_checkpoint,
+                        use_scale_shift_norm=use_scale_shift_norm,
+                    )
+                ]
+                ch = model_channels * mult
+                if ds in attention_resolutions:
+                    dim_head = ch // num_heads
+                    layers.append(
+                        AttentionBlock(
+                            ch,
+                            use_checkpoint=use_checkpoint,
+                            num_heads=num_heads_upsample,
+                            num_head_channels=num_head_channels,
+                            use_new_attention_order=use_new_attention_order,
+                        ) if not use_spatial_transformer else SpatialTransformer(
+                            ch, num_heads, dim_head, depth=transformer_depth, context_dim=context_dim
+                        )
+                    )
+                if level and i == num_res_blocks:
+                    out_ch = ch
+                    layers.append(
+                        ResBlock(
+                            ch,
+                            time_embed_dim,
+                            dropout,
+                            out_channels=out_ch,
+                            dims=dims,
+                            use_checkpoint=use_checkpoint,
+                            use_scale_shift_norm=use_scale_shift_norm,
+                            up=True,
+                        )
+                        if resblock_updown
+                        else Upsample(ch, conv_resample, dims=dims, out_channels=out_ch)
+                    )
+                    ds //= 2
+                self.output_blocks.append(TimestepEmbedSequential(*layers))
+                self._feature_size += ch
+
+        self.out = nn.Sequential(
+            normalization(ch),
+            nn.SiLU(),
+            zero_module(conv_nd(dims, model_channels, out_channels, 3, padding=1)),
+        )
+        if self.predict_codebook_ids:
+            self.id_predictor = nn.Sequential(
+            normalization(ch),
+            conv_nd(dims, model_channels, n_embed, 1),
+            #nn.LogSoftmax(dim=1)  # change to cross_entropy and produce non-normalized logits
+        )
+
+    def convert_to_fp16(self):
+        """
+        Convert the torso of the model to float16.
+        """
+        self.input_blocks.apply(convert_module_to_f16)
+        self.middle_block.apply(convert_module_to_f16)
+        self.output_blocks.apply(convert_module_to_f16)
+
+    def convert_to_fp32(self):
+        """
+        Convert the torso of the model to float32.
+        """
+        self.input_blocks.apply(convert_module_to_f32)
+        self.middle_block.apply(convert_module_to_f32)
+        self.output_blocks.apply(convert_module_to_f32)
+
+    def forward(self, x, timesteps=None, context=None, y=None,**kwargs):
+        """
+        Apply the model to an input batch.
+        :param x: an [N x C x ...] Tensor of inputs.
+        :param timesteps: a 1-D batch of timesteps.
+        :param context: conditioning plugged in via crossattn
+        :param y: an [N] Tensor of labels, if class-conditional.
+        :return: an [N x C x ...] Tensor of outputs.
+        """
+        assert (y is not None) == (
+            self.num_classes is not None
+        ), "must specify y if and only if the model is class-conditional"
+        assert timesteps is not None, 'need to implement no-timestep usage'
+        hs = []
+        t_emb = timestep_embedding(timesteps, self.model_channels, repeat_only=False)
+        emb = self.time_embed(t_emb)
+
+        if self.num_classes is not None:
+            assert y.shape == (x.shape[0],)
+            emb = emb + self.label_emb(y)
+
+        h = x.type(self.dtype)
+        for module in self.input_blocks:
+            h = module(h, emb, context)
+            hs.append(h)
+        h = self.middle_block(h, emb, context)
+        for module in self.output_blocks:
+            h = th.cat([h, hs.pop()], dim=1)
+            h = module(h, emb, context)
+        h = h.type(x.dtype)
+        if self.predict_codebook_ids:
+            #return self.out(h), self.id_predictor(h)
+            return self.id_predictor(h)
+        else:
+            return self.out(h)
+
+
+class EncoderUNetModel(nn.Module):
+    # TODO: do we use it ?
+    """
+    The half UNet model with attention and timestep embedding.
+    For usage, see UNet.
+    """
+
+    def __init__(
+        self,
+        image_size,
+        in_channels,
+        model_channels,
+        out_channels,
+        num_res_blocks,
+        attention_resolutions,
+        dropout=0,
+        channel_mult=(1, 2, 4, 8),
+        conv_resample=True,
+        dims=2,
+        use_checkpoint=False,
+        use_fp16=False,
+        num_heads=1,
+        num_head_channels=-1,
+        num_heads_upsample=-1,
+        use_scale_shift_norm=False,
+        resblock_updown=False,
+        use_new_attention_order=False,
+        pool="adaptive",
+        *args,
+        **kwargs
+    ):
+        super().__init__()
+
+        if num_heads_upsample == -1:
+            num_heads_upsample = num_heads
+
+        self.in_channels = in_channels
+        self.model_channels = model_channels
+        self.out_channels = out_channels
+        self.num_res_blocks = num_res_blocks
+        self.attention_resolutions = attention_resolutions
+        self.dropout = dropout
+        self.channel_mult = channel_mult
+        self.conv_resample = conv_resample
+        self.use_checkpoint = use_checkpoint
+        self.dtype = th.float16 if use_fp16 else th.float32
+        self.num_heads = num_heads
+        self.num_head_channels = num_head_channels
+        self.num_heads_upsample = num_heads_upsample
+
+        time_embed_dim = model_channels * 4
+        self.time_embed = nn.Sequential(
+            linear(model_channels, time_embed_dim),
+            nn.SiLU(),
+            linear(time_embed_dim, time_embed_dim),
+        )
+
+        self.input_blocks = nn.ModuleList(
+            [
+                TimestepEmbedSequential(
+                    conv_nd(dims, in_channels, model_channels, 3, padding=1)
+                )
+            ]
+        )
+        self._feature_size = model_channels
+        input_block_chans = [model_channels]
+        ch = model_channels
+        ds = 1
+        for level, mult in enumerate(channel_mult):
+            for _ in range(num_res_blocks):
+                layers = [
+                    ResBlock(
+                        ch,
+                        time_embed_dim,
+                        dropout,
+                        out_channels=mult * model_channels,
+                        dims=dims,
+                        use_checkpoint=use_checkpoint,
+                        use_scale_shift_norm=use_scale_shift_norm,
+                    )
+                ]
+                ch = mult * model_channels
+                if ds in attention_resolutions:
+                    layers.append(
+                        AttentionBlock(
+                            ch,
+                            use_checkpoint=use_checkpoint,
+                            num_heads=num_heads,
+                            num_head_channels=num_head_channels,
+                            use_new_attention_order=use_new_attention_order,
+                        )
+                    )
+                self.input_blocks.append(TimestepEmbedSequential(*layers))
+                self._feature_size += ch
+                input_block_chans.append(ch)
+            if level != len(channel_mult) - 1:
+                out_ch = ch
+                self.input_blocks.append(
+                    TimestepEmbedSequential(
+                        ResBlock(
+                            ch,
+                            time_embed_dim,
+                            dropout,
+                            out_channels=out_ch,
+                            dims=dims,
+                            use_checkpoint=use_checkpoint,
+                            use_scale_shift_norm=use_scale_shift_norm,
+                            down=True,
+                        )
+                        if resblock_updown
+                        else Downsample(
+                            ch, conv_resample, dims=dims, out_channels=out_ch
+                        )
+                    )
+                )
+                ch = out_ch
+                input_block_chans.append(ch)
+                ds *= 2
+                self._feature_size += ch
+
+        self.middle_block = TimestepEmbedSequential(
+            ResBlock(
+                ch,
+                time_embed_dim,
+                dropout,
+                dims=dims,
+                use_checkpoint=use_checkpoint,
+                use_scale_shift_norm=use_scale_shift_norm,
+            ),
+            AttentionBlock(
+                ch,
+                use_checkpoint=use_checkpoint,
+                num_heads=num_heads,
+                num_head_channels=num_head_channels,
+                use_new_attention_order=use_new_attention_order,
+            ),
+            ResBlock(
+                ch,
+                time_embed_dim,
+                dropout,
+                dims=dims,
+                use_checkpoint=use_checkpoint,
+                use_scale_shift_norm=use_scale_shift_norm,
+            ),
+        )
+        self._feature_size += ch
+        self.pool = pool
+        if pool == "adaptive":
+            self.out = nn.Sequential(
+                normalization(ch),
+                nn.SiLU(),
+                nn.AdaptiveAvgPool2d((1, 1)),
+                zero_module(conv_nd(dims, ch, out_channels, 1)),
+                nn.Flatten(),
+            )
+        elif pool == "attention":
+            assert num_head_channels != -1
+            self.out = nn.Sequential(
+                normalization(ch),
+                nn.SiLU(),
+                AttentionPool2d(
+                    (image_size // ds), ch, num_head_channels, out_channels
+                ),
+            )
+        elif pool == "spatial":
+            self.out = nn.Sequential(
+                nn.Linear(self._feature_size, 2048),
+                nn.ReLU(),
+                nn.Linear(2048, self.out_channels),
+            )
+        elif pool == "spatial_v2":
+            self.out = nn.Sequential(
+                nn.Linear(self._feature_size, 2048),
+                normalization(2048),
+                nn.SiLU(),
+                nn.Linear(2048, self.out_channels),
+            )
+        else:
+            raise NotImplementedError(f"Unexpected {pool} pooling")
+
+    def convert_to_fp16(self):
+        """
+        Convert the torso of the model to float16.
+        """
+        self.input_blocks.apply(convert_module_to_f16)
+        self.middle_block.apply(convert_module_to_f16)
+
+    def convert_to_fp32(self):
+        """
+        Convert the torso of the model to float32.
+        """
+        self.input_blocks.apply(convert_module_to_f32)
+        self.middle_block.apply(convert_module_to_f32)
+
+    def forward(self, x, timesteps):
+        """
+        Apply the model to an input batch.
+        :param x: an [N x C x ...] Tensor of inputs.
+        :param timesteps: a 1-D batch of timesteps.
+        :return: an [N x K] Tensor of outputs.
+        """
+        emb = self.time_embed(timestep_embedding(timesteps, self.model_channels))
+
+        results = []
+        h = x.type(self.dtype)
+        for module in self.input_blocks:
+            h = module(h, emb)
+            if self.pool.startswith("spatial"):
+                results.append(h.type(x.dtype).mean(dim=(2, 3)))
+        h = self.middle_block(h, emb)
+        if self.pool.startswith("spatial"):
+            results.append(h.type(x.dtype).mean(dim=(2, 3)))
+            h = th.cat(results, axis=-1)
+            return self.out(h)
+        else:
+            h = h.type(x.dtype)
+            return self.out(h)
+

+ 261 - 0
ldm/modules/diffusionmodules/util.py

@@ -0,0 +1,261 @@
+# adopted from
+# https://github.com/openai/improved-diffusion/blob/main/improved_diffusion/gaussian_diffusion.py
+# and
+# https://github.com/lucidrains/denoising-diffusion-pytorch/blob/7706bdfc6f527f58d33f84b7b522e61e6e3164b3/denoising_diffusion_pytorch/denoising_diffusion_pytorch.py
+# and
+# https://github.com/openai/guided-diffusion/blob/0ba878e517b276c45d1195eb29f6f5f72659a05b/guided_diffusion/nn.py
+#
+# thanks!
+
+
+import os
+import math
+import torch
+import torch.nn as nn
+import numpy as np
+from einops import repeat
+
+from ldm.util import instantiate_from_config
+
+
+def make_beta_schedule(schedule, n_timestep, linear_start=1e-4, linear_end=2e-2, cosine_s=8e-3):
+    if schedule == "linear":
+        betas = (
+                torch.linspace(linear_start ** 0.5, linear_end ** 0.5, n_timestep, dtype=torch.float64) ** 2
+        )
+
+    elif schedule == "cosine":
+        timesteps = (
+                torch.arange(n_timestep + 1, dtype=torch.float64) / n_timestep + cosine_s
+        )
+        alphas = timesteps / (1 + cosine_s) * np.pi / 2
+        alphas = torch.cos(alphas).pow(2)
+        alphas = alphas / alphas[0]
+        betas = 1 - alphas[1:] / alphas[:-1]
+        betas = np.clip(betas, a_min=0, a_max=0.999)
+
+    elif schedule == "sqrt_linear":
+        betas = torch.linspace(linear_start, linear_end, n_timestep, dtype=torch.float64)
+    elif schedule == "sqrt":
+        betas = torch.linspace(linear_start, linear_end, n_timestep, dtype=torch.float64) ** 0.5
+    else:
+        raise ValueError(f"schedule '{schedule}' unknown.")
+    return betas.numpy()
+
+
+def make_ddim_timesteps(ddim_discr_method, num_ddim_timesteps, num_ddpm_timesteps, verbose=True):
+    if ddim_discr_method == 'uniform':
+        c = num_ddpm_timesteps // num_ddim_timesteps
+        ddim_timesteps = np.asarray(list(range(0, num_ddpm_timesteps, c)))
+    elif ddim_discr_method == 'quad':
+        ddim_timesteps = ((np.linspace(0, np.sqrt(num_ddpm_timesteps * .8), num_ddim_timesteps)) ** 2).astype(int)
+    else:
+        raise NotImplementedError(f'There is no ddim discretization method called "{ddim_discr_method}"')
+
+    # assert ddim_timesteps.shape[0] == num_ddim_timesteps
+    # add one to get the final alpha values right (the ones from first scale to data during sampling)
+    steps_out = ddim_timesteps + 1
+    if verbose:
+        print(f'Selected timesteps for ddim sampler: {steps_out}')
+    return steps_out
+
+
+def make_ddim_sampling_parameters(alphacums, ddim_timesteps, eta, verbose=True):
+    # select alphas for computing the variance schedule
+    alphas = alphacums[ddim_timesteps]
+    alphas_prev = np.asarray([alphacums[0]] + alphacums[ddim_timesteps[:-1]].tolist())
+
+    # according the the formula provided in https://arxiv.org/abs/2010.02502
+    sigmas = eta * np.sqrt((1 - alphas_prev) / (1 - alphas) * (1 - alphas / alphas_prev))
+    if verbose:
+        print(f'Selected alphas for ddim sampler: a_t: {alphas}; a_(t-1): {alphas_prev}')
+        print(f'For the chosen value of eta, which is {eta}, '
+              f'this results in the following sigma_t schedule for ddim sampler {sigmas}')
+    return sigmas, alphas, alphas_prev
+
+
+def betas_for_alpha_bar(num_diffusion_timesteps, alpha_bar, max_beta=0.999):
+    """
+    Create a beta schedule that discretizes the given alpha_t_bar function,
+    which defines the cumulative product of (1-beta) over time from t = [0,1].
+    :param num_diffusion_timesteps: the number of betas to produce.
+    :param alpha_bar: a lambda that takes an argument t from 0 to 1 and
+                      produces the cumulative product of (1-beta) up to that
+                      part of the diffusion process.
+    :param max_beta: the maximum beta to use; use values lower than 1 to
+                     prevent singularities.
+    """
+    betas = []
+    for i in range(num_diffusion_timesteps):
+        t1 = i / num_diffusion_timesteps
+        t2 = (i + 1) / num_diffusion_timesteps
+        betas.append(min(1 - alpha_bar(t2) / alpha_bar(t1), max_beta))
+    return np.array(betas)
+
+
+def extract_into_tensor(a, t, x_shape):
+    b, *_ = t.shape
+    out = a.gather(-1, t)
+    return out.reshape(b, *((1,) * (len(x_shape) - 1)))
+
+
+def checkpoint(func, inputs, params, flag):
+    """
+    Evaluate a function without caching intermediate activations, allowing for
+    reduced memory at the expense of extra compute in the backward pass.
+    :param func: the function to evaluate.
+    :param inputs: the argument sequence to pass to `func`.
+    :param params: a sequence of parameters `func` depends on but does not
+                   explicitly take as arguments.
+    :param flag: if False, disable gradient checkpointing.
+    """
+    if flag:
+        args = tuple(inputs) + tuple(params)
+        return CheckpointFunction.apply(func, len(inputs), *args)
+    else:
+        return func(*inputs)
+
+
+class CheckpointFunction(torch.autograd.Function):
+    @staticmethod
+    def forward(ctx, run_function, length, *args):
+        ctx.run_function = run_function
+        ctx.input_tensors = list(args[:length])
+        ctx.input_params = list(args[length:])
+
+        with torch.no_grad():
+            output_tensors = ctx.run_function(*ctx.input_tensors)
+        return output_tensors
+
+    @staticmethod
+    def backward(ctx, *output_grads):
+        ctx.input_tensors = [x.detach().requires_grad_(True) for x in ctx.input_tensors]
+        with torch.enable_grad():
+            # Fixes a bug where the first op in run_function modifies the
+            # Tensor storage in place, which is not allowed for detach()'d
+            # Tensors.
+            shallow_copies = [x.view_as(x) for x in ctx.input_tensors]
+            output_tensors = ctx.run_function(*shallow_copies)
+        input_grads = torch.autograd.grad(
+            output_tensors,
+            ctx.input_tensors + ctx.input_params,
+            output_grads,
+            allow_unused=True,
+        )
+        del ctx.input_tensors
+        del ctx.input_params
+        del output_tensors
+        return (None, None) + input_grads
+
+
+def timestep_embedding(timesteps, dim, max_period=10000, repeat_only=False):
+    """
+    Create sinusoidal timestep embeddings.
+    :param timesteps: a 1-D Tensor of N indices, one per batch element.
+                      These may be fractional.
+    :param dim: the dimension of the output.
+    :param max_period: controls the minimum frequency of the embeddings.
+    :return: an [N x dim] Tensor of positional embeddings.
+    """
+    if not repeat_only:
+        half = dim // 2
+        freqs = torch.exp(
+            -math.log(max_period) * torch.arange(start=0, end=half, dtype=torch.float32) / half
+        ).to(device=timesteps.device)
+        args = timesteps[:, None].float() * freqs[None]
+        embedding = torch.cat([torch.cos(args), torch.sin(args)], dim=-1)
+        if dim % 2:
+            embedding = torch.cat([embedding, torch.zeros_like(embedding[:, :1])], dim=-1)
+    else:
+        embedding = repeat(timesteps, 'b -> b d', d=dim)
+    return embedding
+
+
+def zero_module(module):
+    """
+    Zero out the parameters of a module and return it.
+    """
+    for p in module.parameters():
+        p.detach().zero_()
+    return module
+
+
+def scale_module(module, scale):
+    """
+    Scale the parameters of a module and return it.
+    """
+    for p in module.parameters():
+        p.detach().mul_(scale)
+    return module
+
+
+def mean_flat(tensor):
+    """
+    Take the mean over all non-batch dimensions.
+    """
+    return tensor.mean(dim=list(range(1, len(tensor.shape))))
+
+
+def normalization(channels):
+    """
+    Make a standard normalization layer.
+    :param channels: number of input channels.
+    :return: an nn.Module for normalization.
+    """
+    return GroupNorm32(32, channels)
+
+
+# PyTorch 1.7 has SiLU, but we support PyTorch 1.5.
+class SiLU(nn.Module):
+    def forward(self, x):
+        return x * torch.sigmoid(x)
+
+
+class GroupNorm32(nn.GroupNorm):
+    def forward(self, x):
+        return super().forward(x.float()).type(x.dtype)
+
+def conv_nd(dims, *args, **kwargs):
+    """
+    Create a 1D, 2D, or 3D convolution module.
+    """
+    if dims == 1:
+        return nn.Conv1d(*args, **kwargs)
+    elif dims == 2:
+        return nn.Conv2d(*args, **kwargs)
+    elif dims == 3:
+        return nn.Conv3d(*args, **kwargs)
+    raise ValueError(f"unsupported dimensions: {dims}")
+
+
+def linear(*args, **kwargs):
+    """
+    Create a linear module.
+    """
+    return nn.Linear(*args, **kwargs)
+
+
+def avg_pool_nd(dims, *args, **kwargs):
+    """
+    Create a 1D, 2D, or 3D average pooling module.
+    """
+    if dims == 1:
+        return nn.AvgPool1d(*args, **kwargs)
+    elif dims == 2:
+        return nn.AvgPool2d(*args, **kwargs)
+    elif dims == 3:
+        return nn.AvgPool3d(*args, **kwargs)
+    raise ValueError(f"unsupported dimensions: {dims}")
+
+
+class HybridConditioner(nn.Module):
+
+    def __init__(self, c_concat_config, c_crossattn_config):
+        super().__init__()
+        self.concat_conditioner = instantiate_from_config(c_concat_config)
+        self.crossattn_conditioner = instantiate_from_config(c_crossattn_config)
+
+    def forward(self, c_concat, c_crossattn):
+        c_concat = self.concat_conditioner(c_concat)
+        c_crossattn = self.crossattn_conditioner(c_crossattn)
+        return {'c_concat': [c_concat], 'c_crossattn': [c_crossattn]}

+ 0 - 0
ldm/modules/distributions/__init__.py


+ 92 - 0
ldm/modules/distributions/distributions.py

@@ -0,0 +1,92 @@
+import torch
+import numpy as np
+
+
+class AbstractDistribution:
+    def sample(self):
+        raise NotImplementedError()
+
+    def mode(self):
+        raise NotImplementedError()
+
+
+class DiracDistribution(AbstractDistribution):
+    def __init__(self, value):
+        self.value = value
+
+    def sample(self):
+        return self.value
+
+    def mode(self):
+        return self.value
+
+
+class DiagonalGaussianDistribution(object):
+    def __init__(self, parameters, deterministic=False):
+        self.parameters = parameters
+        self.mean, self.logvar = torch.chunk(parameters, 2, dim=1)
+        self.logvar = torch.clamp(self.logvar, -30.0, 20.0)
+        self.deterministic = deterministic
+        self.std = torch.exp(0.5 * self.logvar)
+        self.var = torch.exp(self.logvar)
+        if self.deterministic:
+            self.var = self.std = torch.zeros_like(self.mean).to(device=self.parameters.device)
+
+    def sample(self):
+        x = self.mean + self.std * torch.randn(self.mean.shape).to(device=self.parameters.device)
+        return x
+
+    def kl(self, other=None):
+        if self.deterministic:
+            return torch.Tensor([0.])
+        else:
+            if other is None:
+                return 0.5 * torch.sum(torch.pow(self.mean, 2)
+                                       + self.var - 1.0 - self.logvar,
+                                       dim=[1, 2, 3])
+            else:
+                return 0.5 * torch.sum(
+                    torch.pow(self.mean - other.mean, 2) / other.var
+                    + self.var / other.var - 1.0 - self.logvar + other.logvar,
+                    dim=[1, 2, 3])
+
+    def nll(self, sample, dims=[1,2,3]):
+        if self.deterministic:
+            return torch.Tensor([0.])
+        logtwopi = np.log(2.0 * np.pi)
+        return 0.5 * torch.sum(
+            logtwopi + self.logvar + torch.pow(sample - self.mean, 2) / self.var,
+            dim=dims)
+
+    def mode(self):
+        return self.mean
+
+
+def normal_kl(mean1, logvar1, mean2, logvar2):
+    """
+    source: https://github.com/openai/guided-diffusion/blob/27c20a8fab9cb472df5d6bdd6c8d11c8f430b924/guided_diffusion/losses.py#L12
+    Compute the KL divergence between two gaussians.
+    Shapes are automatically broadcasted, so batches can be compared to
+    scalars, among other use cases.
+    """
+    tensor = None
+    for obj in (mean1, logvar1, mean2, logvar2):
+        if isinstance(obj, torch.Tensor):
+            tensor = obj
+            break
+    assert tensor is not None, "at least one argument must be a Tensor"
+
+    # Force variances to be Tensors. Broadcasting helps convert scalars to
+    # Tensors, but it does not work for torch.exp().
+    logvar1, logvar2 = [
+        x if isinstance(x, torch.Tensor) else torch.tensor(x).to(tensor)
+        for x in (logvar1, logvar2)
+    ]
+
+    return 0.5 * (
+        -1.0
+        + logvar2
+        - logvar1
+        + torch.exp(logvar1 - logvar2)
+        + ((mean1 - mean2) ** 2) * torch.exp(-logvar2)
+    )

+ 76 - 0
ldm/modules/ema.py

@@ -0,0 +1,76 @@
+import torch
+from torch import nn
+
+
+class LitEma(nn.Module):
+    def __init__(self, model, decay=0.9999, use_num_upates=True):
+        super().__init__()
+        if decay < 0.0 or decay > 1.0:
+            raise ValueError('Decay must be between 0 and 1')
+
+        self.m_name2s_name = {}
+        self.register_buffer('decay', torch.tensor(decay, dtype=torch.float32))
+        self.register_buffer('num_updates', torch.tensor(0,dtype=torch.int) if use_num_upates
+                             else torch.tensor(-1,dtype=torch.int))
+
+        for name, p in model.named_parameters():
+            if p.requires_grad:
+                #remove as '.'-character is not allowed in buffers
+                s_name = name.replace('.','')
+                self.m_name2s_name.update({name:s_name})
+                self.register_buffer(s_name,p.clone().detach().data)
+
+        self.collected_params = []
+
+    def forward(self,model):
+        decay = self.decay
+
+        if self.num_updates >= 0:
+            self.num_updates += 1
+            decay = min(self.decay,(1 + self.num_updates) / (10 + self.num_updates))
+
+        one_minus_decay = 1.0 - decay
+
+        with torch.no_grad():
+            m_param = dict(model.named_parameters())
+            shadow_params = dict(self.named_buffers())
+
+            for key in m_param:
+                if m_param[key].requires_grad:
+                    sname = self.m_name2s_name[key]
+                    shadow_params[sname] = shadow_params[sname].type_as(m_param[key])
+                    shadow_params[sname].sub_(one_minus_decay * (shadow_params[sname] - m_param[key]))
+                else:
+                    assert not key in self.m_name2s_name
+
+    def copy_to(self, model):
+        m_param = dict(model.named_parameters())
+        shadow_params = dict(self.named_buffers())
+        for key in m_param:
+            if m_param[key].requires_grad:
+                m_param[key].data.copy_(shadow_params[self.m_name2s_name[key]].data)
+            else:
+                assert not key in self.m_name2s_name
+
+    def store(self, parameters):
+        """
+        Save the current parameters for restoring later.
+        Args:
+          parameters: Iterable of `torch.nn.Parameter`; the parameters to be
+            temporarily stored.
+        """
+        self.collected_params = [param.clone() for param in parameters]
+
+    def restore(self, parameters):
+        """
+        Restore the parameters stored with the `store` method.
+        Useful to validate the model with EMA parameters without affecting the
+        original optimization process. Store the parameters before the
+        `copy_to` method. After validation (or model saving), use this to
+        restore the former parameters.
+        Args:
+          parameters: Iterable of `torch.nn.Parameter`; the parameters to be
+            updated with the stored parameters.
+        """
+        for c_param, param in zip(self.collected_params, parameters):
+            param.data.copy_(c_param.data)

+ 0 - 0
ldm/modules/encoders/__init__.py


+ 131 - 0
ldm/modules/encoders/modules.py

@@ -0,0 +1,131 @@
+import torch
+import torch.nn as nn
+from functools import partial
+
+from ldm.modules.x_transformer import Encoder, TransformerWrapper  # TODO: can we directly rely on lucidrains code and simply add this as a reuirement? --> test
+
+
+class AbstractEncoder(nn.Module):
+    def __init__(self):
+        super().__init__()
+
+    def encode(self, *args, **kwargs):
+        raise NotImplementedError
+
+
+
+class ClassEmbedder(nn.Module):
+    def __init__(self, embed_dim, n_classes=1000, key='class'):
+        super().__init__()
+        self.key = key
+        self.embedding = nn.Embedding(n_classes, embed_dim)
+
+    def forward(self, batch, key=None):
+        if key is None:
+            key = self.key
+        # this is for use in crossattn
+        c = batch[key][:, None]
+        c = self.embedding(c)
+        return c
+
+
+class TransformerEmbedder(AbstractEncoder):
+    """Some transformer encoder layers"""
+    def __init__(self, n_embed, n_layer, vocab_size, max_seq_len=77, device="cuda"):
+        super().__init__()
+        self.device = device
+        self.transformer = TransformerWrapper(num_tokens=vocab_size, max_seq_len=max_seq_len,
+                                              attn_layers=Encoder(dim=n_embed, depth=n_layer))
+
+    def forward(self, tokens):
+        tokens = tokens.to(self.device)  # meh
+        z = self.transformer(tokens, return_embeddings=True)
+        return z
+
+    def encode(self, x):
+        return self(x)
+
+
+class BERTTokenizer(AbstractEncoder):
+    """ Uses a pretrained BERT tokenizer by huggingface. Vocab size: 30522 (?)"""
+    def __init__(self, device="cuda", vq_interface=True, max_length=77):
+        super().__init__()
+        from transformers import BertTokenizerFast  # TODO: add to reuquirements
+        self.tokenizer = BertTokenizerFast.from_pretrained("bert-base-uncased")
+        self.device = device
+        self.vq_interface = vq_interface
+        self.max_length = max_length
+
+    def forward(self, text):
+        batch_encoding = self.tokenizer(text, truncation=True, max_length=self.max_length, return_length=True,
+                                        return_overflowing_tokens=False, padding="max_length", return_tensors="pt")
+        tokens = batch_encoding["input_ids"].to(self.device)
+        return tokens
+
+    @torch.no_grad()
+    def encode(self, text):
+        tokens = self(text)
+        if not self.vq_interface:
+            return tokens
+        return None, None, [None, None, tokens]
+
+    def decode(self, text):
+        return text
+
+
+class BERTEmbedder(AbstractEncoder):
+    """Uses the BERT tokenizr model and add some transformer encoder layers"""
+    def __init__(self, n_embed, n_layer, vocab_size=30522, max_seq_len=77,
+                 device="cuda",use_tokenizer=True, embedding_dropout=0.0):
+        super().__init__()
+        self.use_tknz_fn = use_tokenizer
+        if self.use_tknz_fn:
+            self.tknz_fn = BERTTokenizer(vq_interface=False, max_length=max_seq_len)
+        self.device = device
+        self.transformer = TransformerWrapper(num_tokens=vocab_size, max_seq_len=max_seq_len,
+                                              attn_layers=Encoder(dim=n_embed, depth=n_layer),
+                                              emb_dropout=embedding_dropout)
+
+    def forward(self, text):
+        if self.use_tknz_fn:
+            tokens = self.tknz_fn(text)#.to(self.device)
+        else:
+            tokens = text
+        z = self.transformer(tokens, return_embeddings=True)
+        return z
+
+    def encode(self, text):
+        # output of length 77
+        return self(text)
+
+
+class SpatialRescaler(nn.Module):
+    def __init__(self,
+                 n_stages=1,
+                 method='bilinear',
+                 multiplier=0.5,
+                 in_channels=3,
+                 out_channels=None,
+                 bias=False):
+        super().__init__()
+        self.n_stages = n_stages
+        assert self.n_stages >= 0
+        assert method in ['nearest','linear','bilinear','trilinear','bicubic','area']
+        self.multiplier = multiplier
+        self.interpolator = partial(torch.nn.functional.interpolate, mode=method)
+        self.remap_output = out_channels is not None
+        if self.remap_output:
+            print(f'Spatial Rescaler mapping from {in_channels} to {out_channels} channels after resizing.')
+            self.channel_mapper = nn.Conv2d(in_channels,out_channels,1,bias=bias)
+
+    def forward(self,x):
+        for stage in range(self.n_stages):
+            x = self.interpolator(x, scale_factor=self.multiplier)
+
+
+        if self.remap_output:
+            x = self.channel_mapper(x)
+        return x
+
+    def encode(self, x):
+        return self(x)

+ 2 - 0
ldm/modules/image_degradation/__init__.py

@@ -0,0 +1,2 @@
+from ldm.modules.image_degradation.bsrgan import degradation_bsrgan_variant as degradation_fn_bsr
+from ldm.modules.image_degradation.bsrgan_light import degradation_bsrgan_variant as degradation_fn_bsr_light

+ 730 - 0
ldm/modules/image_degradation/bsrgan.py

@@ -0,0 +1,730 @@
+# -*- coding: utf-8 -*-
+"""
+# --------------------------------------------
+# Super-Resolution
+# --------------------------------------------
+#
+# Kai Zhang (cskaizhang@gmail.com)
+# https://github.com/cszn
+# From 2019/03--2021/08
+# --------------------------------------------
+"""
+
+import numpy as np
+import cv2
+import torch
+
+from functools import partial
+import random
+from scipy import ndimage
+import scipy
+import scipy.stats as ss
+from scipy.interpolate import interp2d
+from scipy.linalg import orth
+import albumentations
+
+import ldm.modules.image_degradation.utils_image as util
+
+
+def modcrop_np(img, sf):
+    '''
+    Args:
+        img: numpy image, WxH or WxHxC
+        sf: scale factor
+    Return:
+        cropped image
+    '''
+    w, h = img.shape[:2]
+    im = np.copy(img)
+    return im[:w - w % sf, :h - h % sf, ...]
+
+
+"""
+# --------------------------------------------
+# anisotropic Gaussian kernels
+# --------------------------------------------
+"""
+
+
+def analytic_kernel(k):
+    """Calculate the X4 kernel from the X2 kernel (for proof see appendix in paper)"""
+    k_size = k.shape[0]
+    # Calculate the big kernels size
+    big_k = np.zeros((3 * k_size - 2, 3 * k_size - 2))
+    # Loop over the small kernel to fill the big one
+    for r in range(k_size):
+        for c in range(k_size):
+            big_k[2 * r:2 * r + k_size, 2 * c:2 * c + k_size] += k[r, c] * k
+    # Crop the edges of the big kernel to ignore very small values and increase run time of SR
+    crop = k_size // 2
+    cropped_big_k = big_k[crop:-crop, crop:-crop]
+    # Normalize to 1
+    return cropped_big_k / cropped_big_k.sum()
+
+
+def anisotropic_Gaussian(ksize=15, theta=np.pi, l1=6, l2=6):
+    """ generate an anisotropic Gaussian kernel
+    Args:
+        ksize : e.g., 15, kernel size
+        theta : [0,  pi], rotation angle range
+        l1    : [0.1,50], scaling of eigenvalues
+        l2    : [0.1,l1], scaling of eigenvalues
+        If l1 = l2, will get an isotropic Gaussian kernel.
+    Returns:
+        k     : kernel
+    """
+
+    v = np.dot(np.array([[np.cos(theta), -np.sin(theta)], [np.sin(theta), np.cos(theta)]]), np.array([1., 0.]))
+    V = np.array([[v[0], v[1]], [v[1], -v[0]]])
+    D = np.array([[l1, 0], [0, l2]])
+    Sigma = np.dot(np.dot(V, D), np.linalg.inv(V))
+    k = gm_blur_kernel(mean=[0, 0], cov=Sigma, size=ksize)
+
+    return k
+
+
+def gm_blur_kernel(mean, cov, size=15):
+    center = size / 2.0 + 0.5
+    k = np.zeros([size, size])
+    for y in range(size):
+        for x in range(size):
+            cy = y - center + 1
+            cx = x - center + 1
+            k[y, x] = ss.multivariate_normal.pdf([cx, cy], mean=mean, cov=cov)
+
+    k = k / np.sum(k)
+    return k
+
+
+def shift_pixel(x, sf, upper_left=True):
+    """shift pixel for super-resolution with different scale factors
+    Args:
+        x: WxHxC or WxH
+        sf: scale factor
+        upper_left: shift direction
+    """
+    h, w = x.shape[:2]
+    shift = (sf - 1) * 0.5
+    xv, yv = np.arange(0, w, 1.0), np.arange(0, h, 1.0)
+    if upper_left:
+        x1 = xv + shift
+        y1 = yv + shift
+    else:
+        x1 = xv - shift
+        y1 = yv - shift
+
+    x1 = np.clip(x1, 0, w - 1)
+    y1 = np.clip(y1, 0, h - 1)
+
+    if x.ndim == 2:
+        x = interp2d(xv, yv, x)(x1, y1)
+    if x.ndim == 3:
+        for i in range(x.shape[-1]):
+            x[:, :, i] = interp2d(xv, yv, x[:, :, i])(x1, y1)
+
+    return x
+
+
+def blur(x, k):
+    '''
+    x: image, NxcxHxW
+    k: kernel, Nx1xhxw
+    '''
+    n, c = x.shape[:2]
+    p1, p2 = (k.shape[-2] - 1) // 2, (k.shape[-1] - 1) // 2
+    x = torch.nn.functional.pad(x, pad=(p1, p2, p1, p2), mode='replicate')
+    k = k.repeat(1, c, 1, 1)
+    k = k.view(-1, 1, k.shape[2], k.shape[3])
+    x = x.view(1, -1, x.shape[2], x.shape[3])
+    x = torch.nn.functional.conv2d(x, k, bias=None, stride=1, padding=0, groups=n * c)
+    x = x.view(n, c, x.shape[2], x.shape[3])
+
+    return x
+
+
+def gen_kernel(k_size=np.array([15, 15]), scale_factor=np.array([4, 4]), min_var=0.6, max_var=10., noise_level=0):
+    """"
+    # modified version of https://github.com/assafshocher/BlindSR_dataset_generator
+    # Kai Zhang
+    # min_var = 0.175 * sf  # variance of the gaussian kernel will be sampled between min_var and max_var
+    # max_var = 2.5 * sf
+    """
+    # Set random eigen-vals (lambdas) and angle (theta) for COV matrix
+    lambda_1 = min_var + np.random.rand() * (max_var - min_var)
+    lambda_2 = min_var + np.random.rand() * (max_var - min_var)
+    theta = np.random.rand() * np.pi  # random theta
+    noise = -noise_level + np.random.rand(*k_size) * noise_level * 2
+
+    # Set COV matrix using Lambdas and Theta
+    LAMBDA = np.diag([lambda_1, lambda_2])
+    Q = np.array([[np.cos(theta), -np.sin(theta)],
+                  [np.sin(theta), np.cos(theta)]])
+    SIGMA = Q @ LAMBDA @ Q.T
+    INV_SIGMA = np.linalg.inv(SIGMA)[None, None, :, :]
+
+    # Set expectation position (shifting kernel for aligned image)
+    MU = k_size // 2 - 0.5 * (scale_factor - 1)  # - 0.5 * (scale_factor - k_size % 2)
+    MU = MU[None, None, :, None]
+
+    # Create meshgrid for Gaussian
+    [X, Y] = np.meshgrid(range(k_size[0]), range(k_size[1]))
+    Z = np.stack([X, Y], 2)[:, :, :, None]
+
+    # Calcualte Gaussian for every pixel of the kernel
+    ZZ = Z - MU
+    ZZ_t = ZZ.transpose(0, 1, 3, 2)
+    raw_kernel = np.exp(-0.5 * np.squeeze(ZZ_t @ INV_SIGMA @ ZZ)) * (1 + noise)
+
+    # shift the kernel so it will be centered
+    # raw_kernel_centered = kernel_shift(raw_kernel, scale_factor)
+
+    # Normalize the kernel and return
+    # kernel = raw_kernel_centered / np.sum(raw_kernel_centered)
+    kernel = raw_kernel / np.sum(raw_kernel)
+    return kernel
+
+
+def fspecial_gaussian(hsize, sigma):
+    hsize = [hsize, hsize]
+    siz = [(hsize[0] - 1.0) / 2.0, (hsize[1] - 1.0) / 2.0]
+    std = sigma
+    [x, y] = np.meshgrid(np.arange(-siz[1], siz[1] + 1), np.arange(-siz[0], siz[0] + 1))
+    arg = -(x * x + y * y) / (2 * std * std)
+    h = np.exp(arg)
+    h[h < scipy.finfo(float).eps * h.max()] = 0
+    sumh = h.sum()
+    if sumh != 0:
+        h = h / sumh
+    return h
+
+
+def fspecial_laplacian(alpha):
+    alpha = max([0, min([alpha, 1])])
+    h1 = alpha / (alpha + 1)
+    h2 = (1 - alpha) / (alpha + 1)
+    h = [[h1, h2, h1], [h2, -4 / (alpha + 1), h2], [h1, h2, h1]]
+    h = np.array(h)
+    return h
+
+
+def fspecial(filter_type, *args, **kwargs):
+    '''
+    python code from:
+    https://github.com/ronaldosena/imagens-medicas-2/blob/40171a6c259edec7827a6693a93955de2bd39e76/Aulas/aula_2_-_uniform_filter/matlab_fspecial.py
+    '''
+    if filter_type == 'gaussian':
+        return fspecial_gaussian(*args, **kwargs)
+    if filter_type == 'laplacian':
+        return fspecial_laplacian(*args, **kwargs)
+
+
+"""
+# --------------------------------------------
+# degradation models
+# --------------------------------------------
+"""
+
+
+def bicubic_degradation(x, sf=3):
+    '''
+    Args:
+        x: HxWxC image, [0, 1]
+        sf: down-scale factor
+    Return:
+        bicubicly downsampled LR image
+    '''
+    x = util.imresize_np(x, scale=1 / sf)
+    return x
+
+
+def srmd_degradation(x, k, sf=3):
+    ''' blur + bicubic downsampling
+    Args:
+        x: HxWxC image, [0, 1]
+        k: hxw, double
+        sf: down-scale factor
+    Return:
+        downsampled LR image
+    Reference:
+        @inproceedings{zhang2018learning,
+          title={Learning a single convolutional super-resolution network for multiple degradations},
+          author={Zhang, Kai and Zuo, Wangmeng and Zhang, Lei},
+          booktitle={IEEE Conference on Computer Vision and Pattern Recognition},
+          pages={3262--3271},
+          year={2018}
+        }
+    '''
+    x = ndimage.filters.convolve(x, np.expand_dims(k, axis=2), mode='wrap')  # 'nearest' | 'mirror'
+    x = bicubic_degradation(x, sf=sf)
+    return x
+
+
+def dpsr_degradation(x, k, sf=3):
+    ''' bicubic downsampling + blur
+    Args:
+        x: HxWxC image, [0, 1]
+        k: hxw, double
+        sf: down-scale factor
+    Return:
+        downsampled LR image
+    Reference:
+        @inproceedings{zhang2019deep,
+          title={Deep Plug-and-Play Super-Resolution for Arbitrary Blur Kernels},
+          author={Zhang, Kai and Zuo, Wangmeng and Zhang, Lei},
+          booktitle={IEEE Conference on Computer Vision and Pattern Recognition},
+          pages={1671--1681},
+          year={2019}
+        }
+    '''
+    x = bicubic_degradation(x, sf=sf)
+    x = ndimage.filters.convolve(x, np.expand_dims(k, axis=2), mode='wrap')
+    return x
+
+
+def classical_degradation(x, k, sf=3):
+    ''' blur + downsampling
+    Args:
+        x: HxWxC image, [0, 1]/[0, 255]
+        k: hxw, double
+        sf: down-scale factor
+    Return:
+        downsampled LR image
+    '''
+    x = ndimage.filters.convolve(x, np.expand_dims(k, axis=2), mode='wrap')
+    # x = filters.correlate(x, np.expand_dims(np.flip(k), axis=2))
+    st = 0
+    return x[st::sf, st::sf, ...]
+
+
+def add_sharpening(img, weight=0.5, radius=50, threshold=10):
+    """USM sharpening. borrowed from real-ESRGAN
+    Input image: I; Blurry image: B.
+    1. K = I + weight * (I - B)
+    2. Mask = 1 if abs(I - B) > threshold, else: 0
+    3. Blur mask:
+    4. Out = Mask * K + (1 - Mask) * I
+    Args:
+        img (Numpy array): Input image, HWC, BGR; float32, [0, 1].
+        weight (float): Sharp weight. Default: 1.
+        radius (float): Kernel size of Gaussian blur. Default: 50.
+        threshold (int):
+    """
+    if radius % 2 == 0:
+        radius += 1
+    blur = cv2.GaussianBlur(img, (radius, radius), 0)
+    residual = img - blur
+    mask = np.abs(residual) * 255 > threshold
+    mask = mask.astype('float32')
+    soft_mask = cv2.GaussianBlur(mask, (radius, radius), 0)
+
+    K = img + weight * residual
+    K = np.clip(K, 0, 1)
+    return soft_mask * K + (1 - soft_mask) * img
+
+
+def add_blur(img, sf=4):
+    wd2 = 4.0 + sf
+    wd = 2.0 + 0.2 * sf
+    if random.random() < 0.5:
+        l1 = wd2 * random.random()
+        l2 = wd2 * random.random()
+        k = anisotropic_Gaussian(ksize=2 * random.randint(2, 11) + 3, theta=random.random() * np.pi, l1=l1, l2=l2)
+    else:
+        k = fspecial('gaussian', 2 * random.randint(2, 11) + 3, wd * random.random())
+    img = ndimage.filters.convolve(img, np.expand_dims(k, axis=2), mode='mirror')
+
+    return img
+
+
+def add_resize(img, sf=4):
+    rnum = np.random.rand()
+    if rnum > 0.8:  # up
+        sf1 = random.uniform(1, 2)
+    elif rnum < 0.7:  # down
+        sf1 = random.uniform(0.5 / sf, 1)
+    else:
+        sf1 = 1.0
+    img = cv2.resize(img, (int(sf1 * img.shape[1]), int(sf1 * img.shape[0])), interpolation=random.choice([1, 2, 3]))
+    img = np.clip(img, 0.0, 1.0)
+
+    return img
+
+
+# def add_Gaussian_noise(img, noise_level1=2, noise_level2=25):
+#     noise_level = random.randint(noise_level1, noise_level2)
+#     rnum = np.random.rand()
+#     if rnum > 0.6:  # add color Gaussian noise
+#         img += np.random.normal(0, noise_level / 255.0, img.shape).astype(np.float32)
+#     elif rnum < 0.4:  # add grayscale Gaussian noise
+#         img += np.random.normal(0, noise_level / 255.0, (*img.shape[:2], 1)).astype(np.float32)
+#     else:  # add  noise
+#         L = noise_level2 / 255.
+#         D = np.diag(np.random.rand(3))
+#         U = orth(np.random.rand(3, 3))
+#         conv = np.dot(np.dot(np.transpose(U), D), U)
+#         img += np.random.multivariate_normal([0, 0, 0], np.abs(L ** 2 * conv), img.shape[:2]).astype(np.float32)
+#     img = np.clip(img, 0.0, 1.0)
+#     return img
+
+def add_Gaussian_noise(img, noise_level1=2, noise_level2=25):
+    noise_level = random.randint(noise_level1, noise_level2)
+    rnum = np.random.rand()
+    if rnum > 0.6:  # add color Gaussian noise
+        img = img + np.random.normal(0, noise_level / 255.0, img.shape).astype(np.float32)
+    elif rnum < 0.4:  # add grayscale Gaussian noise
+        img = img + np.random.normal(0, noise_level / 255.0, (*img.shape[:2], 1)).astype(np.float32)
+    else:  # add  noise
+        L = noise_level2 / 255.
+        D = np.diag(np.random.rand(3))
+        U = orth(np.random.rand(3, 3))
+        conv = np.dot(np.dot(np.transpose(U), D), U)
+        img = img + np.random.multivariate_normal([0, 0, 0], np.abs(L ** 2 * conv), img.shape[:2]).astype(np.float32)
+    img = np.clip(img, 0.0, 1.0)
+    return img
+
+
+def add_speckle_noise(img, noise_level1=2, noise_level2=25):
+    noise_level = random.randint(noise_level1, noise_level2)
+    img = np.clip(img, 0.0, 1.0)
+    rnum = random.random()
+    if rnum > 0.6:
+        img += img * np.random.normal(0, noise_level / 255.0, img.shape).astype(np.float32)
+    elif rnum < 0.4:
+        img += img * np.random.normal(0, noise_level / 255.0, (*img.shape[:2], 1)).astype(np.float32)
+    else:
+        L = noise_level2 / 255.
+        D = np.diag(np.random.rand(3))
+        U = orth(np.random.rand(3, 3))
+        conv = np.dot(np.dot(np.transpose(U), D), U)
+        img += img * np.random.multivariate_normal([0, 0, 0], np.abs(L ** 2 * conv), img.shape[:2]).astype(np.float32)
+    img = np.clip(img, 0.0, 1.0)
+    return img
+
+
+def add_Poisson_noise(img):
+    img = np.clip((img * 255.0).round(), 0, 255) / 255.
+    vals = 10 ** (2 * random.random() + 2.0)  # [2, 4]
+    if random.random() < 0.5:
+        img = np.random.poisson(img * vals).astype(np.float32) / vals
+    else:
+        img_gray = np.dot(img[..., :3], [0.299, 0.587, 0.114])
+        img_gray = np.clip((img_gray * 255.0).round(), 0, 255) / 255.
+        noise_gray = np.random.poisson(img_gray * vals).astype(np.float32) / vals - img_gray
+        img += noise_gray[:, :, np.newaxis]
+    img = np.clip(img, 0.0, 1.0)
+    return img
+
+
+def add_JPEG_noise(img):
+    quality_factor = random.randint(30, 95)
+    img = cv2.cvtColor(util.single2uint(img), cv2.COLOR_RGB2BGR)
+    result, encimg = cv2.imencode('.jpg', img, [int(cv2.IMWRITE_JPEG_QUALITY), quality_factor])
+    img = cv2.imdecode(encimg, 1)
+    img = cv2.cvtColor(util.uint2single(img), cv2.COLOR_BGR2RGB)
+    return img
+
+
+def random_crop(lq, hq, sf=4, lq_patchsize=64):
+    h, w = lq.shape[:2]
+    rnd_h = random.randint(0, h - lq_patchsize)
+    rnd_w = random.randint(0, w - lq_patchsize)
+    lq = lq[rnd_h:rnd_h + lq_patchsize, rnd_w:rnd_w + lq_patchsize, :]
+
+    rnd_h_H, rnd_w_H = int(rnd_h * sf), int(rnd_w * sf)
+    hq = hq[rnd_h_H:rnd_h_H + lq_patchsize * sf, rnd_w_H:rnd_w_H + lq_patchsize * sf, :]
+    return lq, hq
+
+
+def degradation_bsrgan(img, sf=4, lq_patchsize=72, isp_model=None):
+    """
+    This is the degradation model of BSRGAN from the paper
+    "Designing a Practical Degradation Model for Deep Blind Image Super-Resolution"
+    ----------
+    img: HXWXC, [0, 1], its size should be large than (lq_patchsizexsf)x(lq_patchsizexsf)
+    sf: scale factor
+    isp_model: camera ISP model
+    Returns
+    -------
+    img: low-quality patch, size: lq_patchsizeXlq_patchsizeXC, range: [0, 1]
+    hq: corresponding high-quality patch, size: (lq_patchsizexsf)X(lq_patchsizexsf)XC, range: [0, 1]
+    """
+    isp_prob, jpeg_prob, scale2_prob = 0.25, 0.9, 0.25
+    sf_ori = sf
+
+    h1, w1 = img.shape[:2]
+    img = img.copy()[:w1 - w1 % sf, :h1 - h1 % sf, ...]  # mod crop
+    h, w = img.shape[:2]
+
+    if h < lq_patchsize * sf or w < lq_patchsize * sf:
+        raise ValueError(f'img size ({h1}X{w1}) is too small!')
+
+    hq = img.copy()
+
+    if sf == 4 and random.random() < scale2_prob:  # downsample1
+        if np.random.rand() < 0.5:
+            img = cv2.resize(img, (int(1 / 2 * img.shape[1]), int(1 / 2 * img.shape[0])),
+                             interpolation=random.choice([1, 2, 3]))
+        else:
+            img = util.imresize_np(img, 1 / 2, True)
+        img = np.clip(img, 0.0, 1.0)
+        sf = 2
+
+    shuffle_order = random.sample(range(7), 7)
+    idx1, idx2 = shuffle_order.index(2), shuffle_order.index(3)
+    if idx1 > idx2:  # keep downsample3 last
+        shuffle_order[idx1], shuffle_order[idx2] = shuffle_order[idx2], shuffle_order[idx1]
+
+    for i in shuffle_order:
+
+        if i == 0:
+            img = add_blur(img, sf=sf)
+
+        elif i == 1:
+            img = add_blur(img, sf=sf)
+
+        elif i == 2:
+            a, b = img.shape[1], img.shape[0]
+            # downsample2
+            if random.random() < 0.75:
+                sf1 = random.uniform(1, 2 * sf)
+                img = cv2.resize(img, (int(1 / sf1 * img.shape[1]), int(1 / sf1 * img.shape[0])),
+                                 interpolation=random.choice([1, 2, 3]))
+            else:
+                k = fspecial('gaussian', 25, random.uniform(0.1, 0.6 * sf))
+                k_shifted = shift_pixel(k, sf)
+                k_shifted = k_shifted / k_shifted.sum()  # blur with shifted kernel
+                img = ndimage.filters.convolve(img, np.expand_dims(k_shifted, axis=2), mode='mirror')
+                img = img[0::sf, 0::sf, ...]  # nearest downsampling
+            img = np.clip(img, 0.0, 1.0)
+
+        elif i == 3:
+            # downsample3
+            img = cv2.resize(img, (int(1 / sf * a), int(1 / sf * b)), interpolation=random.choice([1, 2, 3]))
+            img = np.clip(img, 0.0, 1.0)
+
+        elif i == 4:
+            # add Gaussian noise
+            img = add_Gaussian_noise(img, noise_level1=2, noise_level2=25)
+
+        elif i == 5:
+            # add JPEG noise
+            if random.random() < jpeg_prob:
+                img = add_JPEG_noise(img)
+
+        elif i == 6:
+            # add processed camera sensor noise
+            if random.random() < isp_prob and isp_model is not None:
+                with torch.no_grad():
+                    img, hq = isp_model.forward(img.copy(), hq)
+
+    # add final JPEG compression noise
+    img = add_JPEG_noise(img)
+
+    # random crop
+    img, hq = random_crop(img, hq, sf_ori, lq_patchsize)
+
+    return img, hq
+
+
+# todo no isp_model?
+def degradation_bsrgan_variant(image, sf=4, isp_model=None):
+    """
+    This is the degradation model of BSRGAN from the paper
+    "Designing a Practical Degradation Model for Deep Blind Image Super-Resolution"
+    ----------
+    sf: scale factor
+    isp_model: camera ISP model
+    Returns
+    -------
+    img: low-quality patch, size: lq_patchsizeXlq_patchsizeXC, range: [0, 1]
+    hq: corresponding high-quality patch, size: (lq_patchsizexsf)X(lq_patchsizexsf)XC, range: [0, 1]
+    """
+    image = util.uint2single(image)
+    isp_prob, jpeg_prob, scale2_prob = 0.25, 0.9, 0.25
+    sf_ori = sf
+
+    h1, w1 = image.shape[:2]
+    image = image.copy()[:w1 - w1 % sf, :h1 - h1 % sf, ...]  # mod crop
+    h, w = image.shape[:2]
+
+    hq = image.copy()
+
+    if sf == 4 and random.random() < scale2_prob:  # downsample1
+        if np.random.rand() < 0.5:
+            image = cv2.resize(image, (int(1 / 2 * image.shape[1]), int(1 / 2 * image.shape[0])),
+                               interpolation=random.choice([1, 2, 3]))
+        else:
+            image = util.imresize_np(image, 1 / 2, True)
+        image = np.clip(image, 0.0, 1.0)
+        sf = 2
+
+    shuffle_order = random.sample(range(7), 7)
+    idx1, idx2 = shuffle_order.index(2), shuffle_order.index(3)
+    if idx1 > idx2:  # keep downsample3 last
+        shuffle_order[idx1], shuffle_order[idx2] = shuffle_order[idx2], shuffle_order[idx1]
+
+    for i in shuffle_order:
+
+        if i == 0:
+            image = add_blur(image, sf=sf)
+
+        elif i == 1:
+            image = add_blur(image, sf=sf)
+
+        elif i == 2:
+            a, b = image.shape[1], image.shape[0]
+            # downsample2
+            if random.random() < 0.75:
+                sf1 = random.uniform(1, 2 * sf)
+                image = cv2.resize(image, (int(1 / sf1 * image.shape[1]), int(1 / sf1 * image.shape[0])),
+                                   interpolation=random.choice([1, 2, 3]))
+            else:
+                k = fspecial('gaussian', 25, random.uniform(0.1, 0.6 * sf))
+                k_shifted = shift_pixel(k, sf)
+                k_shifted = k_shifted / k_shifted.sum()  # blur with shifted kernel
+                image = ndimage.filters.convolve(image, np.expand_dims(k_shifted, axis=2), mode='mirror')
+                image = image[0::sf, 0::sf, ...]  # nearest downsampling
+            image = np.clip(image, 0.0, 1.0)
+
+        elif i == 3:
+            # downsample3
+            image = cv2.resize(image, (int(1 / sf * a), int(1 / sf * b)), interpolation=random.choice([1, 2, 3]))
+            image = np.clip(image, 0.0, 1.0)
+
+        elif i == 4:
+            # add Gaussian noise
+            image = add_Gaussian_noise(image, noise_level1=2, noise_level2=25)
+
+        elif i == 5:
+            # add JPEG noise
+            if random.random() < jpeg_prob:
+                image = add_JPEG_noise(image)
+
+        # elif i == 6:
+        #     # add processed camera sensor noise
+        #     if random.random() < isp_prob and isp_model is not None:
+        #         with torch.no_grad():
+        #             img, hq = isp_model.forward(img.copy(), hq)
+
+    # add final JPEG compression noise
+    image = add_JPEG_noise(image)
+    image = util.single2uint(image)
+    example = {"image":image}
+    return example
+
+
+# TODO incase there is a pickle error one needs to replace a += x with a = a + x in add_speckle_noise etc...
+def degradation_bsrgan_plus(img, sf=4, shuffle_prob=0.5, use_sharp=True, lq_patchsize=64, isp_model=None):
+    """
+    This is an extended degradation model by combining
+    the degradation models of BSRGAN and Real-ESRGAN
+    ----------
+    img: HXWXC, [0, 1], its size should be large than (lq_patchsizexsf)x(lq_patchsizexsf)
+    sf: scale factor
+    use_shuffle: the degradation shuffle
+    use_sharp: sharpening the img
+    Returns
+    -------
+    img: low-quality patch, size: lq_patchsizeXlq_patchsizeXC, range: [0, 1]
+    hq: corresponding high-quality patch, size: (lq_patchsizexsf)X(lq_patchsizexsf)XC, range: [0, 1]
+    """
+
+    h1, w1 = img.shape[:2]
+    img = img.copy()[:w1 - w1 % sf, :h1 - h1 % sf, ...]  # mod crop
+    h, w = img.shape[:2]
+
+    if h < lq_patchsize * sf or w < lq_patchsize * sf:
+        raise ValueError(f'img size ({h1}X{w1}) is too small!')
+
+    if use_sharp:
+        img = add_sharpening(img)
+    hq = img.copy()
+
+    if random.random() < shuffle_prob:
+        shuffle_order = random.sample(range(13), 13)
+    else:
+        shuffle_order = list(range(13))
+        # local shuffle for noise, JPEG is always the last one
+        shuffle_order[2:6] = random.sample(shuffle_order[2:6], len(range(2, 6)))
+        shuffle_order[9:13] = random.sample(shuffle_order[9:13], len(range(9, 13)))
+
+    poisson_prob, speckle_prob, isp_prob = 0.1, 0.1, 0.1
+
+    for i in shuffle_order:
+        if i == 0:
+            img = add_blur(img, sf=sf)
+        elif i == 1:
+            img = add_resize(img, sf=sf)
+        elif i == 2:
+            img = add_Gaussian_noise(img, noise_level1=2, noise_level2=25)
+        elif i == 3:
+            if random.random() < poisson_prob:
+                img = add_Poisson_noise(img)
+        elif i == 4:
+            if random.random() < speckle_prob:
+                img = add_speckle_noise(img)
+        elif i == 5:
+            if random.random() < isp_prob and isp_model is not None:
+                with torch.no_grad():
+                    img, hq = isp_model.forward(img.copy(), hq)
+        elif i == 6:
+            img = add_JPEG_noise(img)
+        elif i == 7:
+            img = add_blur(img, sf=sf)
+        elif i == 8:
+            img = add_resize(img, sf=sf)
+        elif i == 9:
+            img = add_Gaussian_noise(img, noise_level1=2, noise_level2=25)
+        elif i == 10:
+            if random.random() < poisson_prob:
+                img = add_Poisson_noise(img)
+        elif i == 11:
+            if random.random() < speckle_prob:
+                img = add_speckle_noise(img)
+        elif i == 12:
+            if random.random() < isp_prob and isp_model is not None:
+                with torch.no_grad():
+                    img, hq = isp_model.forward(img.copy(), hq)
+        else:
+            print('check the shuffle!')
+
+    # resize to desired size
+    img = cv2.resize(img, (int(1 / sf * hq.shape[1]), int(1 / sf * hq.shape[0])),
+                     interpolation=random.choice([1, 2, 3]))
+
+    # add final JPEG compression noise
+    img = add_JPEG_noise(img)
+
+    # random crop
+    img, hq = random_crop(img, hq, sf, lq_patchsize)
+
+    return img, hq
+
+
+if __name__ == '__main__':
+	print("hey")
+	img = util.imread_uint('utils/test.png', 3)
+	print(img)
+	img = util.uint2single(img)
+	print(img)
+	img = img[:448, :448]
+	h = img.shape[0] // 4
+	print("resizing to", h)
+	sf = 4
+	deg_fn = partial(degradation_bsrgan_variant, sf=sf)
+	for i in range(20):
+		print(i)
+		img_lq = deg_fn(img)
+		print(img_lq)
+		img_lq_bicubic = albumentations.SmallestMaxSize(max_size=h, interpolation=cv2.INTER_CUBIC)(image=img)["image"]
+		print(img_lq.shape)
+		print("bicubic", img_lq_bicubic.shape)
+		print(img_hq.shape)
+		lq_nearest = cv2.resize(util.single2uint(img_lq), (int(sf * img_lq.shape[1]), int(sf * img_lq.shape[0])),
+		                        interpolation=0)
+		lq_bicubic_nearest = cv2.resize(util.single2uint(img_lq_bicubic), (int(sf * img_lq.shape[1]), int(sf * img_lq.shape[0])),
+		                        interpolation=0)
+		img_concat = np.concatenate([lq_bicubic_nearest, lq_nearest, util.single2uint(img_hq)], axis=1)
+		util.imsave(img_concat, str(i) + '.png')
+
+

+ 650 - 0
ldm/modules/image_degradation/bsrgan_light.py

@@ -0,0 +1,650 @@
+# -*- coding: utf-8 -*-
+import numpy as np
+import cv2
+import torch
+
+from functools import partial
+import random
+from scipy import ndimage
+import scipy
+import scipy.stats as ss
+from scipy.interpolate import interp2d
+from scipy.linalg import orth
+import albumentations
+
+import ldm.modules.image_degradation.utils_image as util
+
+"""
+# --------------------------------------------
+# Super-Resolution
+# --------------------------------------------
+#
+# Kai Zhang (cskaizhang@gmail.com)
+# https://github.com/cszn
+# From 2019/03--2021/08
+# --------------------------------------------
+"""
+
+
+def modcrop_np(img, sf):
+    '''
+    Args:
+        img: numpy image, WxH or WxHxC
+        sf: scale factor
+    Return:
+        cropped image
+    '''
+    w, h = img.shape[:2]
+    im = np.copy(img)
+    return im[:w - w % sf, :h - h % sf, ...]
+
+
+"""
+# --------------------------------------------
+# anisotropic Gaussian kernels
+# --------------------------------------------
+"""
+
+
+def analytic_kernel(k):
+    """Calculate the X4 kernel from the X2 kernel (for proof see appendix in paper)"""
+    k_size = k.shape[0]
+    # Calculate the big kernels size
+    big_k = np.zeros((3 * k_size - 2, 3 * k_size - 2))
+    # Loop over the small kernel to fill the big one
+    for r in range(k_size):
+        for c in range(k_size):
+            big_k[2 * r:2 * r + k_size, 2 * c:2 * c + k_size] += k[r, c] * k
+    # Crop the edges of the big kernel to ignore very small values and increase run time of SR
+    crop = k_size // 2
+    cropped_big_k = big_k[crop:-crop, crop:-crop]
+    # Normalize to 1
+    return cropped_big_k / cropped_big_k.sum()
+
+
+def anisotropic_Gaussian(ksize=15, theta=np.pi, l1=6, l2=6):
+    """ generate an anisotropic Gaussian kernel
+    Args:
+        ksize : e.g., 15, kernel size
+        theta : [0,  pi], rotation angle range
+        l1    : [0.1,50], scaling of eigenvalues
+        l2    : [0.1,l1], scaling of eigenvalues
+        If l1 = l2, will get an isotropic Gaussian kernel.
+    Returns:
+        k     : kernel
+    """
+
+    v = np.dot(np.array([[np.cos(theta), -np.sin(theta)], [np.sin(theta), np.cos(theta)]]), np.array([1., 0.]))
+    V = np.array([[v[0], v[1]], [v[1], -v[0]]])
+    D = np.array([[l1, 0], [0, l2]])
+    Sigma = np.dot(np.dot(V, D), np.linalg.inv(V))
+    k = gm_blur_kernel(mean=[0, 0], cov=Sigma, size=ksize)
+
+    return k
+
+
+def gm_blur_kernel(mean, cov, size=15):
+    center = size / 2.0 + 0.5
+    k = np.zeros([size, size])
+    for y in range(size):
+        for x in range(size):
+            cy = y - center + 1
+            cx = x - center + 1
+            k[y, x] = ss.multivariate_normal.pdf([cx, cy], mean=mean, cov=cov)
+
+    k = k / np.sum(k)
+    return k
+
+
+def shift_pixel(x, sf, upper_left=True):
+    """shift pixel for super-resolution with different scale factors
+    Args:
+        x: WxHxC or WxH
+        sf: scale factor
+        upper_left: shift direction
+    """
+    h, w = x.shape[:2]
+    shift = (sf - 1) * 0.5
+    xv, yv = np.arange(0, w, 1.0), np.arange(0, h, 1.0)
+    if upper_left:
+        x1 = xv + shift
+        y1 = yv + shift
+    else:
+        x1 = xv - shift
+        y1 = yv - shift
+
+    x1 = np.clip(x1, 0, w - 1)
+    y1 = np.clip(y1, 0, h - 1)
+
+    if x.ndim == 2:
+        x = interp2d(xv, yv, x)(x1, y1)
+    if x.ndim == 3:
+        for i in range(x.shape[-1]):
+            x[:, :, i] = interp2d(xv, yv, x[:, :, i])(x1, y1)
+
+    return x
+
+
+def blur(x, k):
+    '''
+    x: image, NxcxHxW
+    k: kernel, Nx1xhxw
+    '''
+    n, c = x.shape[:2]
+    p1, p2 = (k.shape[-2] - 1) // 2, (k.shape[-1] - 1) // 2
+    x = torch.nn.functional.pad(x, pad=(p1, p2, p1, p2), mode='replicate')
+    k = k.repeat(1, c, 1, 1)
+    k = k.view(-1, 1, k.shape[2], k.shape[3])
+    x = x.view(1, -1, x.shape[2], x.shape[3])
+    x = torch.nn.functional.conv2d(x, k, bias=None, stride=1, padding=0, groups=n * c)
+    x = x.view(n, c, x.shape[2], x.shape[3])
+
+    return x
+
+
+def gen_kernel(k_size=np.array([15, 15]), scale_factor=np.array([4, 4]), min_var=0.6, max_var=10., noise_level=0):
+    """"
+    # modified version of https://github.com/assafshocher/BlindSR_dataset_generator
+    # Kai Zhang
+    # min_var = 0.175 * sf  # variance of the gaussian kernel will be sampled between min_var and max_var
+    # max_var = 2.5 * sf
+    """
+    # Set random eigen-vals (lambdas) and angle (theta) for COV matrix
+    lambda_1 = min_var + np.random.rand() * (max_var - min_var)
+    lambda_2 = min_var + np.random.rand() * (max_var - min_var)
+    theta = np.random.rand() * np.pi  # random theta
+    noise = -noise_level + np.random.rand(*k_size) * noise_level * 2
+
+    # Set COV matrix using Lambdas and Theta
+    LAMBDA = np.diag([lambda_1, lambda_2])
+    Q = np.array([[np.cos(theta), -np.sin(theta)],
+                  [np.sin(theta), np.cos(theta)]])
+    SIGMA = Q @ LAMBDA @ Q.T
+    INV_SIGMA = np.linalg.inv(SIGMA)[None, None, :, :]
+
+    # Set expectation position (shifting kernel for aligned image)
+    MU = k_size // 2 - 0.5 * (scale_factor - 1)  # - 0.5 * (scale_factor - k_size % 2)
+    MU = MU[None, None, :, None]
+
+    # Create meshgrid for Gaussian
+    [X, Y] = np.meshgrid(range(k_size[0]), range(k_size[1]))
+    Z = np.stack([X, Y], 2)[:, :, :, None]
+
+    # Calcualte Gaussian for every pixel of the kernel
+    ZZ = Z - MU
+    ZZ_t = ZZ.transpose(0, 1, 3, 2)
+    raw_kernel = np.exp(-0.5 * np.squeeze(ZZ_t @ INV_SIGMA @ ZZ)) * (1 + noise)
+
+    # shift the kernel so it will be centered
+    # raw_kernel_centered = kernel_shift(raw_kernel, scale_factor)
+
+    # Normalize the kernel and return
+    # kernel = raw_kernel_centered / np.sum(raw_kernel_centered)
+    kernel = raw_kernel / np.sum(raw_kernel)
+    return kernel
+
+
+def fspecial_gaussian(hsize, sigma):
+    hsize = [hsize, hsize]
+    siz = [(hsize[0] - 1.0) / 2.0, (hsize[1] - 1.0) / 2.0]
+    std = sigma
+    [x, y] = np.meshgrid(np.arange(-siz[1], siz[1] + 1), np.arange(-siz[0], siz[0] + 1))
+    arg = -(x * x + y * y) / (2 * std * std)
+    h = np.exp(arg)
+    h[h < scipy.finfo(float).eps * h.max()] = 0
+    sumh = h.sum()
+    if sumh != 0:
+        h = h / sumh
+    return h
+
+
+def fspecial_laplacian(alpha):
+    alpha = max([0, min([alpha, 1])])
+    h1 = alpha / (alpha + 1)
+    h2 = (1 - alpha) / (alpha + 1)
+    h = [[h1, h2, h1], [h2, -4 / (alpha + 1), h2], [h1, h2, h1]]
+    h = np.array(h)
+    return h
+
+
+def fspecial(filter_type, *args, **kwargs):
+    '''
+    python code from:
+    https://github.com/ronaldosena/imagens-medicas-2/blob/40171a6c259edec7827a6693a93955de2bd39e76/Aulas/aula_2_-_uniform_filter/matlab_fspecial.py
+    '''
+    if filter_type == 'gaussian':
+        return fspecial_gaussian(*args, **kwargs)
+    if filter_type == 'laplacian':
+        return fspecial_laplacian(*args, **kwargs)
+
+
+"""
+# --------------------------------------------
+# degradation models
+# --------------------------------------------
+"""
+
+
+def bicubic_degradation(x, sf=3):
+    '''
+    Args:
+        x: HxWxC image, [0, 1]
+        sf: down-scale factor
+    Return:
+        bicubicly downsampled LR image
+    '''
+    x = util.imresize_np(x, scale=1 / sf)
+    return x
+
+
+def srmd_degradation(x, k, sf=3):
+    ''' blur + bicubic downsampling
+    Args:
+        x: HxWxC image, [0, 1]
+        k: hxw, double
+        sf: down-scale factor
+    Return:
+        downsampled LR image
+    Reference:
+        @inproceedings{zhang2018learning,
+          title={Learning a single convolutional super-resolution network for multiple degradations},
+          author={Zhang, Kai and Zuo, Wangmeng and Zhang, Lei},
+          booktitle={IEEE Conference on Computer Vision and Pattern Recognition},
+          pages={3262--3271},
+          year={2018}
+        }
+    '''
+    x = ndimage.filters.convolve(x, np.expand_dims(k, axis=2), mode='wrap')  # 'nearest' | 'mirror'
+    x = bicubic_degradation(x, sf=sf)
+    return x
+
+
+def dpsr_degradation(x, k, sf=3):
+    ''' bicubic downsampling + blur
+    Args:
+        x: HxWxC image, [0, 1]
+        k: hxw, double
+        sf: down-scale factor
+    Return:
+        downsampled LR image
+    Reference:
+        @inproceedings{zhang2019deep,
+          title={Deep Plug-and-Play Super-Resolution for Arbitrary Blur Kernels},
+          author={Zhang, Kai and Zuo, Wangmeng and Zhang, Lei},
+          booktitle={IEEE Conference on Computer Vision and Pattern Recognition},
+          pages={1671--1681},
+          year={2019}
+        }
+    '''
+    x = bicubic_degradation(x, sf=sf)
+    x = ndimage.filters.convolve(x, np.expand_dims(k, axis=2), mode='wrap')
+    return x
+
+
+def classical_degradation(x, k, sf=3):
+    ''' blur + downsampling
+    Args:
+        x: HxWxC image, [0, 1]/[0, 255]
+        k: hxw, double
+        sf: down-scale factor
+    Return:
+        downsampled LR image
+    '''
+    x = ndimage.filters.convolve(x, np.expand_dims(k, axis=2), mode='wrap')
+    # x = filters.correlate(x, np.expand_dims(np.flip(k), axis=2))
+    st = 0
+    return x[st::sf, st::sf, ...]
+
+
+def add_sharpening(img, weight=0.5, radius=50, threshold=10):
+    """USM sharpening. borrowed from real-ESRGAN
+    Input image: I; Blurry image: B.
+    1. K = I + weight * (I - B)
+    2. Mask = 1 if abs(I - B) > threshold, else: 0
+    3. Blur mask:
+    4. Out = Mask * K + (1 - Mask) * I
+    Args:
+        img (Numpy array): Input image, HWC, BGR; float32, [0, 1].
+        weight (float): Sharp weight. Default: 1.
+        radius (float): Kernel size of Gaussian blur. Default: 50.
+        threshold (int):
+    """
+    if radius % 2 == 0:
+        radius += 1
+    blur = cv2.GaussianBlur(img, (radius, radius), 0)
+    residual = img - blur
+    mask = np.abs(residual) * 255 > threshold
+    mask = mask.astype('float32')
+    soft_mask = cv2.GaussianBlur(mask, (radius, radius), 0)
+
+    K = img + weight * residual
+    K = np.clip(K, 0, 1)
+    return soft_mask * K + (1 - soft_mask) * img
+
+
+def add_blur(img, sf=4):
+    wd2 = 4.0 + sf
+    wd = 2.0 + 0.2 * sf
+
+    wd2 = wd2/4
+    wd = wd/4
+
+    if random.random() < 0.5:
+        l1 = wd2 * random.random()
+        l2 = wd2 * random.random()
+        k = anisotropic_Gaussian(ksize=random.randint(2, 11) + 3, theta=random.random() * np.pi, l1=l1, l2=l2)
+    else:
+        k = fspecial('gaussian', random.randint(2, 4) + 3, wd * random.random())
+    img = ndimage.filters.convolve(img, np.expand_dims(k, axis=2), mode='mirror')
+
+    return img
+
+
+def add_resize(img, sf=4):
+    rnum = np.random.rand()
+    if rnum > 0.8:  # up
+        sf1 = random.uniform(1, 2)
+    elif rnum < 0.7:  # down
+        sf1 = random.uniform(0.5 / sf, 1)
+    else:
+        sf1 = 1.0
+    img = cv2.resize(img, (int(sf1 * img.shape[1]), int(sf1 * img.shape[0])), interpolation=random.choice([1, 2, 3]))
+    img = np.clip(img, 0.0, 1.0)
+
+    return img
+
+
+# def add_Gaussian_noise(img, noise_level1=2, noise_level2=25):
+#     noise_level = random.randint(noise_level1, noise_level2)
+#     rnum = np.random.rand()
+#     if rnum > 0.6:  # add color Gaussian noise
+#         img += np.random.normal(0, noise_level / 255.0, img.shape).astype(np.float32)
+#     elif rnum < 0.4:  # add grayscale Gaussian noise
+#         img += np.random.normal(0, noise_level / 255.0, (*img.shape[:2], 1)).astype(np.float32)
+#     else:  # add  noise
+#         L = noise_level2 / 255.
+#         D = np.diag(np.random.rand(3))
+#         U = orth(np.random.rand(3, 3))
+#         conv = np.dot(np.dot(np.transpose(U), D), U)
+#         img += np.random.multivariate_normal([0, 0, 0], np.abs(L ** 2 * conv), img.shape[:2]).astype(np.float32)
+#     img = np.clip(img, 0.0, 1.0)
+#     return img
+
+def add_Gaussian_noise(img, noise_level1=2, noise_level2=25):
+    noise_level = random.randint(noise_level1, noise_level2)
+    rnum = np.random.rand()
+    if rnum > 0.6:  # add color Gaussian noise
+        img = img + np.random.normal(0, noise_level / 255.0, img.shape).astype(np.float32)
+    elif rnum < 0.4:  # add grayscale Gaussian noise
+        img = img + np.random.normal(0, noise_level / 255.0, (*img.shape[:2], 1)).astype(np.float32)
+    else:  # add  noise
+        L = noise_level2 / 255.
+        D = np.diag(np.random.rand(3))
+        U = orth(np.random.rand(3, 3))
+        conv = np.dot(np.dot(np.transpose(U), D), U)
+        img = img + np.random.multivariate_normal([0, 0, 0], np.abs(L ** 2 * conv), img.shape[:2]).astype(np.float32)
+    img = np.clip(img, 0.0, 1.0)
+    return img
+
+
+def add_speckle_noise(img, noise_level1=2, noise_level2=25):
+    noise_level = random.randint(noise_level1, noise_level2)
+    img = np.clip(img, 0.0, 1.0)
+    rnum = random.random()
+    if rnum > 0.6:
+        img += img * np.random.normal(0, noise_level / 255.0, img.shape).astype(np.float32)
+    elif rnum < 0.4:
+        img += img * np.random.normal(0, noise_level / 255.0, (*img.shape[:2], 1)).astype(np.float32)
+    else:
+        L = noise_level2 / 255.
+        D = np.diag(np.random.rand(3))
+        U = orth(np.random.rand(3, 3))
+        conv = np.dot(np.dot(np.transpose(U), D), U)
+        img += img * np.random.multivariate_normal([0, 0, 0], np.abs(L ** 2 * conv), img.shape[:2]).astype(np.float32)
+    img = np.clip(img, 0.0, 1.0)
+    return img
+
+
+def add_Poisson_noise(img):
+    img = np.clip((img * 255.0).round(), 0, 255) / 255.
+    vals = 10 ** (2 * random.random() + 2.0)  # [2, 4]
+    if random.random() < 0.5:
+        img = np.random.poisson(img * vals).astype(np.float32) / vals
+    else:
+        img_gray = np.dot(img[..., :3], [0.299, 0.587, 0.114])
+        img_gray = np.clip((img_gray * 255.0).round(), 0, 255) / 255.
+        noise_gray = np.random.poisson(img_gray * vals).astype(np.float32) / vals - img_gray
+        img += noise_gray[:, :, np.newaxis]
+    img = np.clip(img, 0.0, 1.0)
+    return img
+
+
+def add_JPEG_noise(img):
+    quality_factor = random.randint(80, 95)
+    img = cv2.cvtColor(util.single2uint(img), cv2.COLOR_RGB2BGR)
+    result, encimg = cv2.imencode('.jpg', img, [int(cv2.IMWRITE_JPEG_QUALITY), quality_factor])
+    img = cv2.imdecode(encimg, 1)
+    img = cv2.cvtColor(util.uint2single(img), cv2.COLOR_BGR2RGB)
+    return img
+
+
+def random_crop(lq, hq, sf=4, lq_patchsize=64):
+    h, w = lq.shape[:2]
+    rnd_h = random.randint(0, h - lq_patchsize)
+    rnd_w = random.randint(0, w - lq_patchsize)
+    lq = lq[rnd_h:rnd_h + lq_patchsize, rnd_w:rnd_w + lq_patchsize, :]
+
+    rnd_h_H, rnd_w_H = int(rnd_h * sf), int(rnd_w * sf)
+    hq = hq[rnd_h_H:rnd_h_H + lq_patchsize * sf, rnd_w_H:rnd_w_H + lq_patchsize * sf, :]
+    return lq, hq
+
+
+def degradation_bsrgan(img, sf=4, lq_patchsize=72, isp_model=None):
+    """
+    This is the degradation model of BSRGAN from the paper
+    "Designing a Practical Degradation Model for Deep Blind Image Super-Resolution"
+    ----------
+    img: HXWXC, [0, 1], its size should be large than (lq_patchsizexsf)x(lq_patchsizexsf)
+    sf: scale factor
+    isp_model: camera ISP model
+    Returns
+    -------
+    img: low-quality patch, size: lq_patchsizeXlq_patchsizeXC, range: [0, 1]
+    hq: corresponding high-quality patch, size: (lq_patchsizexsf)X(lq_patchsizexsf)XC, range: [0, 1]
+    """
+    isp_prob, jpeg_prob, scale2_prob = 0.25, 0.9, 0.25
+    sf_ori = sf
+
+    h1, w1 = img.shape[:2]
+    img = img.copy()[:w1 - w1 % sf, :h1 - h1 % sf, ...]  # mod crop
+    h, w = img.shape[:2]
+
+    if h < lq_patchsize * sf or w < lq_patchsize * sf:
+        raise ValueError(f'img size ({h1}X{w1}) is too small!')
+
+    hq = img.copy()
+
+    if sf == 4 and random.random() < scale2_prob:  # downsample1
+        if np.random.rand() < 0.5:
+            img = cv2.resize(img, (int(1 / 2 * img.shape[1]), int(1 / 2 * img.shape[0])),
+                             interpolation=random.choice([1, 2, 3]))
+        else:
+            img = util.imresize_np(img, 1 / 2, True)
+        img = np.clip(img, 0.0, 1.0)
+        sf = 2
+
+    shuffle_order = random.sample(range(7), 7)
+    idx1, idx2 = shuffle_order.index(2), shuffle_order.index(3)
+    if idx1 > idx2:  # keep downsample3 last
+        shuffle_order[idx1], shuffle_order[idx2] = shuffle_order[idx2], shuffle_order[idx1]
+
+    for i in shuffle_order:
+
+        if i == 0:
+            img = add_blur(img, sf=sf)
+
+        elif i == 1:
+            img = add_blur(img, sf=sf)
+
+        elif i == 2:
+            a, b = img.shape[1], img.shape[0]
+            # downsample2
+            if random.random() < 0.75:
+                sf1 = random.uniform(1, 2 * sf)
+                img = cv2.resize(img, (int(1 / sf1 * img.shape[1]), int(1 / sf1 * img.shape[0])),
+                                 interpolation=random.choice([1, 2, 3]))
+            else:
+                k = fspecial('gaussian', 25, random.uniform(0.1, 0.6 * sf))
+                k_shifted = shift_pixel(k, sf)
+                k_shifted = k_shifted / k_shifted.sum()  # blur with shifted kernel
+                img = ndimage.filters.convolve(img, np.expand_dims(k_shifted, axis=2), mode='mirror')
+                img = img[0::sf, 0::sf, ...]  # nearest downsampling
+            img = np.clip(img, 0.0, 1.0)
+
+        elif i == 3:
+            # downsample3
+            img = cv2.resize(img, (int(1 / sf * a), int(1 / sf * b)), interpolation=random.choice([1, 2, 3]))
+            img = np.clip(img, 0.0, 1.0)
+
+        elif i == 4:
+            # add Gaussian noise
+            img = add_Gaussian_noise(img, noise_level1=2, noise_level2=8)
+
+        elif i == 5:
+            # add JPEG noise
+            if random.random() < jpeg_prob:
+                img = add_JPEG_noise(img)
+
+        elif i == 6:
+            # add processed camera sensor noise
+            if random.random() < isp_prob and isp_model is not None:
+                with torch.no_grad():
+                    img, hq = isp_model.forward(img.copy(), hq)
+
+    # add final JPEG compression noise
+    img = add_JPEG_noise(img)
+
+    # random crop
+    img, hq = random_crop(img, hq, sf_ori, lq_patchsize)
+
+    return img, hq
+
+
+# todo no isp_model?
+def degradation_bsrgan_variant(image, sf=4, isp_model=None):
+    """
+    This is the degradation model of BSRGAN from the paper
+    "Designing a Practical Degradation Model for Deep Blind Image Super-Resolution"
+    ----------
+    sf: scale factor
+    isp_model: camera ISP model
+    Returns
+    -------
+    img: low-quality patch, size: lq_patchsizeXlq_patchsizeXC, range: [0, 1]
+    hq: corresponding high-quality patch, size: (lq_patchsizexsf)X(lq_patchsizexsf)XC, range: [0, 1]
+    """
+    image = util.uint2single(image)
+    isp_prob, jpeg_prob, scale2_prob = 0.25, 0.9, 0.25
+    sf_ori = sf
+
+    h1, w1 = image.shape[:2]
+    image = image.copy()[:w1 - w1 % sf, :h1 - h1 % sf, ...]  # mod crop
+    h, w = image.shape[:2]
+
+    hq = image.copy()
+
+    if sf == 4 and random.random() < scale2_prob:  # downsample1
+        if np.random.rand() < 0.5:
+            image = cv2.resize(image, (int(1 / 2 * image.shape[1]), int(1 / 2 * image.shape[0])),
+                               interpolation=random.choice([1, 2, 3]))
+        else:
+            image = util.imresize_np(image, 1 / 2, True)
+        image = np.clip(image, 0.0, 1.0)
+        sf = 2
+
+    shuffle_order = random.sample(range(7), 7)
+    idx1, idx2 = shuffle_order.index(2), shuffle_order.index(3)
+    if idx1 > idx2:  # keep downsample3 last
+        shuffle_order[idx1], shuffle_order[idx2] = shuffle_order[idx2], shuffle_order[idx1]
+
+    for i in shuffle_order:
+
+        if i == 0:
+            image = add_blur(image, sf=sf)
+
+        # elif i == 1:
+        #     image = add_blur(image, sf=sf)
+
+        if i == 0:
+            pass
+
+        elif i == 2:
+            a, b = image.shape[1], image.shape[0]
+            # downsample2
+            if random.random() < 0.8:
+                sf1 = random.uniform(1, 2 * sf)
+                image = cv2.resize(image, (int(1 / sf1 * image.shape[1]), int(1 / sf1 * image.shape[0])),
+                                   interpolation=random.choice([1, 2, 3]))
+            else:
+                k = fspecial('gaussian', 25, random.uniform(0.1, 0.6 * sf))
+                k_shifted = shift_pixel(k, sf)
+                k_shifted = k_shifted / k_shifted.sum()  # blur with shifted kernel
+                image = ndimage.filters.convolve(image, np.expand_dims(k_shifted, axis=2), mode='mirror')
+                image = image[0::sf, 0::sf, ...]  # nearest downsampling
+
+            image = np.clip(image, 0.0, 1.0)
+
+        elif i == 3:
+            # downsample3
+            image = cv2.resize(image, (int(1 / sf * a), int(1 / sf * b)), interpolation=random.choice([1, 2, 3]))
+            image = np.clip(image, 0.0, 1.0)
+
+        elif i == 4:
+            # add Gaussian noise
+            image = add_Gaussian_noise(image, noise_level1=1, noise_level2=2)
+
+        elif i == 5:
+            # add JPEG noise
+            if random.random() < jpeg_prob:
+                image = add_JPEG_noise(image)
+        #
+        # elif i == 6:
+        #     # add processed camera sensor noise
+        #     if random.random() < isp_prob and isp_model is not None:
+        #         with torch.no_grad():
+        #             img, hq = isp_model.forward(img.copy(), hq)
+
+    # add final JPEG compression noise
+    image = add_JPEG_noise(image)
+    image = util.single2uint(image)
+    example = {"image": image}
+    return example
+
+
+
+
+if __name__ == '__main__':
+    print("hey")
+    img = util.imread_uint('utils/test.png', 3)
+    img = img[:448, :448]
+    h = img.shape[0] // 4
+    print("resizing to", h)
+    sf = 4
+    deg_fn = partial(degradation_bsrgan_variant, sf=sf)
+    for i in range(20):
+        print(i)
+        img_hq = img
+        img_lq = deg_fn(img)["image"]
+        img_hq, img_lq = util.uint2single(img_hq), util.uint2single(img_lq)
+        print(img_lq)
+        img_lq_bicubic = albumentations.SmallestMaxSize(max_size=h, interpolation=cv2.INTER_CUBIC)(image=img_hq)["image"]
+        print(img_lq.shape)
+        print("bicubic", img_lq_bicubic.shape)
+        print(img_hq.shape)
+        lq_nearest = cv2.resize(util.single2uint(img_lq), (int(sf * img_lq.shape[1]), int(sf * img_lq.shape[0])),
+                                interpolation=0)
+        lq_bicubic_nearest = cv2.resize(util.single2uint(img_lq_bicubic),
+                                        (int(sf * img_lq.shape[1]), int(sf * img_lq.shape[0])),
+                                        interpolation=0)
+        img_concat = np.concatenate([lq_bicubic_nearest, lq_nearest, util.single2uint(img_hq)], axis=1)
+        util.imsave(img_concat, str(i) + '.png')

binární
ldm/modules/image_degradation/utils/test.png


+ 916 - 0
ldm/modules/image_degradation/utils_image.py

@@ -0,0 +1,916 @@
+import os
+import math
+import random
+import numpy as np
+import torch
+import cv2
+from torchvision.utils import make_grid
+from datetime import datetime
+#import matplotlib.pyplot as plt   # TODO: check with Dominik, also bsrgan.py vs bsrgan_light.py
+
+
+os.environ["KMP_DUPLICATE_LIB_OK"]="TRUE"
+
+
+'''
+# --------------------------------------------
+# Kai Zhang (github: https://github.com/cszn)
+# 03/Mar/2019
+# --------------------------------------------
+# https://github.com/twhui/SRGAN-pyTorch
+# https://github.com/xinntao/BasicSR
+# --------------------------------------------
+'''
+
+
+IMG_EXTENSIONS = ['.jpg', '.JPG', '.jpeg', '.JPEG', '.png', '.PNG', '.ppm', '.PPM', '.bmp', '.BMP', '.tif']
+
+
+def is_image_file(filename):
+    return any(filename.endswith(extension) for extension in IMG_EXTENSIONS)
+
+
+def get_timestamp():
+    return datetime.now().strftime('%y%m%d-%H%M%S')
+
+
+def imshow(x, title=None, cbar=False, figsize=None):
+    plt.figure(figsize=figsize)
+    plt.imshow(np.squeeze(x), interpolation='nearest', cmap='gray')
+    if title:
+        plt.title(title)
+    if cbar:
+        plt.colorbar()
+    plt.show()
+
+
+def surf(Z, cmap='rainbow', figsize=None):
+    plt.figure(figsize=figsize)
+    ax3 = plt.axes(projection='3d')
+
+    w, h = Z.shape[:2]
+    xx = np.arange(0,w,1)
+    yy = np.arange(0,h,1)
+    X, Y = np.meshgrid(xx, yy)
+    ax3.plot_surface(X,Y,Z,cmap=cmap)
+    #ax3.contour(X,Y,Z, zdim='z',offset=-2,cmap=cmap)
+    plt.show()
+
+
+'''
+# --------------------------------------------
+# get image pathes
+# --------------------------------------------
+'''
+
+
+def get_image_paths(dataroot):
+    paths = None  # return None if dataroot is None
+    if dataroot is not None:
+        paths = sorted(_get_paths_from_images(dataroot))
+    return paths
+
+
+def _get_paths_from_images(path):
+    assert os.path.isdir(path), '{:s} is not a valid directory'.format(path)
+    images = []
+    for dirpath, _, fnames in sorted(os.walk(path)):
+        for fname in sorted(fnames):
+            if is_image_file(fname):
+                img_path = os.path.join(dirpath, fname)
+                images.append(img_path)
+    assert images, '{:s} has no valid image file'.format(path)
+    return images
+
+
+'''
+# --------------------------------------------
+# split large images into small images 
+# --------------------------------------------
+'''
+
+
+def patches_from_image(img, p_size=512, p_overlap=64, p_max=800):
+    w, h = img.shape[:2]
+    patches = []
+    if w > p_max and h > p_max:
+        w1 = list(np.arange(0, w-p_size, p_size-p_overlap, dtype=np.int))
+        h1 = list(np.arange(0, h-p_size, p_size-p_overlap, dtype=np.int))
+        w1.append(w-p_size)
+        h1.append(h-p_size)
+#        print(w1)
+#        print(h1)
+        for i in w1:
+            for j in h1:
+                patches.append(img[i:i+p_size, j:j+p_size,:])
+    else:
+        patches.append(img)
+
+    return patches
+
+
+def imssave(imgs, img_path):
+    """
+    imgs: list, N images of size WxHxC
+    """
+    img_name, ext = os.path.splitext(os.path.basename(img_path))
+
+    for i, img in enumerate(imgs):
+        if img.ndim == 3:
+            img = img[:, :, [2, 1, 0]]
+        new_path = os.path.join(os.path.dirname(img_path), img_name+str('_s{:04d}'.format(i))+'.png')
+        cv2.imwrite(new_path, img)
+
+
+def split_imageset(original_dataroot, taget_dataroot, n_channels=3, p_size=800, p_overlap=96, p_max=1000):
+    """
+    split the large images from original_dataroot into small overlapped images with size (p_size)x(p_size),
+    and save them into taget_dataroot; only the images with larger size than (p_max)x(p_max)
+    will be splitted.
+    Args:
+        original_dataroot:
+        taget_dataroot:
+        p_size: size of small images
+        p_overlap: patch size in training is a good choice
+        p_max: images with smaller size than (p_max)x(p_max) keep unchanged.
+    """
+    paths = get_image_paths(original_dataroot)
+    for img_path in paths:
+        # img_name, ext = os.path.splitext(os.path.basename(img_path))
+        img = imread_uint(img_path, n_channels=n_channels)
+        patches = patches_from_image(img, p_size, p_overlap, p_max)
+        imssave(patches, os.path.join(taget_dataroot,os.path.basename(img_path)))
+        #if original_dataroot == taget_dataroot:
+        #del img_path
+
+'''
+# --------------------------------------------
+# makedir
+# --------------------------------------------
+'''
+
+
+def mkdir(path):
+    if not os.path.exists(path):
+        os.makedirs(path)
+
+
+def mkdirs(paths):
+    if isinstance(paths, str):
+        mkdir(paths)
+    else:
+        for path in paths:
+            mkdir(path)
+
+
+def mkdir_and_rename(path):
+    if os.path.exists(path):
+        new_name = path + '_archived_' + get_timestamp()
+        print('Path already exists. Rename it to [{:s}]'.format(new_name))
+        os.rename(path, new_name)
+    os.makedirs(path)
+
+
+'''
+# --------------------------------------------
+# read image from path
+# opencv is fast, but read BGR numpy image
+# --------------------------------------------
+'''
+
+
+# --------------------------------------------
+# get uint8 image of size HxWxn_channles (RGB)
+# --------------------------------------------
+def imread_uint(path, n_channels=3):
+    #  input: path
+    # output: HxWx3(RGB or GGG), or HxWx1 (G)
+    if n_channels == 1:
+        img = cv2.imread(path, 0)  # cv2.IMREAD_GRAYSCALE
+        img = np.expand_dims(img, axis=2)  # HxWx1
+    elif n_channels == 3:
+        img = cv2.imread(path, cv2.IMREAD_UNCHANGED)  # BGR or G
+        if img.ndim == 2:
+            img = cv2.cvtColor(img, cv2.COLOR_GRAY2RGB)  # GGG
+        else:
+            img = cv2.cvtColor(img, cv2.COLOR_BGR2RGB)  # RGB
+    return img
+
+
+# --------------------------------------------
+# matlab's imwrite
+# --------------------------------------------
+def imsave(img, img_path):
+    img = np.squeeze(img)
+    if img.ndim == 3:
+        img = img[:, :, [2, 1, 0]]
+    cv2.imwrite(img_path, img)
+
+def imwrite(img, img_path):
+    img = np.squeeze(img)
+    if img.ndim == 3:
+        img = img[:, :, [2, 1, 0]]
+    cv2.imwrite(img_path, img)
+
+
+
+# --------------------------------------------
+# get single image of size HxWxn_channles (BGR)
+# --------------------------------------------
+def read_img(path):
+    # read image by cv2
+    # return: Numpy float32, HWC, BGR, [0,1]
+    img = cv2.imread(path, cv2.IMREAD_UNCHANGED)  # cv2.IMREAD_GRAYSCALE
+    img = img.astype(np.float32) / 255.
+    if img.ndim == 2:
+        img = np.expand_dims(img, axis=2)
+    # some images have 4 channels
+    if img.shape[2] > 3:
+        img = img[:, :, :3]
+    return img
+
+
+'''
+# --------------------------------------------
+# image format conversion
+# --------------------------------------------
+# numpy(single) <--->  numpy(unit)
+# numpy(single) <--->  tensor
+# numpy(unit)   <--->  tensor
+# --------------------------------------------
+'''
+
+
+# --------------------------------------------
+# numpy(single) [0, 1] <--->  numpy(unit)
+# --------------------------------------------
+
+
+def uint2single(img):
+
+    return np.float32(img/255.)
+
+
+def single2uint(img):
+
+    return np.uint8((img.clip(0, 1)*255.).round())
+
+
+def uint162single(img):
+
+    return np.float32(img/65535.)
+
+
+def single2uint16(img):
+
+    return np.uint16((img.clip(0, 1)*65535.).round())
+
+
+# --------------------------------------------
+# numpy(unit) (HxWxC or HxW) <--->  tensor
+# --------------------------------------------
+
+
+# convert uint to 4-dimensional torch tensor
+def uint2tensor4(img):
+    if img.ndim == 2:
+        img = np.expand_dims(img, axis=2)
+    return torch.from_numpy(np.ascontiguousarray(img)).permute(2, 0, 1).float().div(255.).unsqueeze(0)
+
+
+# convert uint to 3-dimensional torch tensor
+def uint2tensor3(img):
+    if img.ndim == 2:
+        img = np.expand_dims(img, axis=2)
+    return torch.from_numpy(np.ascontiguousarray(img)).permute(2, 0, 1).float().div(255.)
+
+
+# convert 2/3/4-dimensional torch tensor to uint
+def tensor2uint(img):
+    img = img.data.squeeze().float().clamp_(0, 1).cpu().numpy()
+    if img.ndim == 3:
+        img = np.transpose(img, (1, 2, 0))
+    return np.uint8((img*255.0).round())
+
+
+# --------------------------------------------
+# numpy(single) (HxWxC) <--->  tensor
+# --------------------------------------------
+
+
+# convert single (HxWxC) to 3-dimensional torch tensor
+def single2tensor3(img):
+    return torch.from_numpy(np.ascontiguousarray(img)).permute(2, 0, 1).float()
+
+
+# convert single (HxWxC) to 4-dimensional torch tensor
+def single2tensor4(img):
+    return torch.from_numpy(np.ascontiguousarray(img)).permute(2, 0, 1).float().unsqueeze(0)
+
+
+# convert torch tensor to single
+def tensor2single(img):
+    img = img.data.squeeze().float().cpu().numpy()
+    if img.ndim == 3:
+        img = np.transpose(img, (1, 2, 0))
+
+    return img
+
+# convert torch tensor to single
+def tensor2single3(img):
+    img = img.data.squeeze().float().cpu().numpy()
+    if img.ndim == 3:
+        img = np.transpose(img, (1, 2, 0))
+    elif img.ndim == 2:
+        img = np.expand_dims(img, axis=2)
+    return img
+
+
+def single2tensor5(img):
+    return torch.from_numpy(np.ascontiguousarray(img)).permute(2, 0, 1, 3).float().unsqueeze(0)
+
+
+def single32tensor5(img):
+    return torch.from_numpy(np.ascontiguousarray(img)).float().unsqueeze(0).unsqueeze(0)
+
+
+def single42tensor4(img):
+    return torch.from_numpy(np.ascontiguousarray(img)).permute(2, 0, 1, 3).float()
+
+
+# from skimage.io import imread, imsave
+def tensor2img(tensor, out_type=np.uint8, min_max=(0, 1)):
+    '''
+    Converts a torch Tensor into an image Numpy array of BGR channel order
+    Input: 4D(B,(3/1),H,W), 3D(C,H,W), or 2D(H,W), any range, RGB channel order
+    Output: 3D(H,W,C) or 2D(H,W), [0,255], np.uint8 (default)
+    '''
+    tensor = tensor.squeeze().float().cpu().clamp_(*min_max)  # squeeze first, then clamp
+    tensor = (tensor - min_max[0]) / (min_max[1] - min_max[0])  # to range [0,1]
+    n_dim = tensor.dim()
+    if n_dim == 4:
+        n_img = len(tensor)
+        img_np = make_grid(tensor, nrow=int(math.sqrt(n_img)), normalize=False).numpy()
+        img_np = np.transpose(img_np[[2, 1, 0], :, :], (1, 2, 0))  # HWC, BGR
+    elif n_dim == 3:
+        img_np = tensor.numpy()
+        img_np = np.transpose(img_np[[2, 1, 0], :, :], (1, 2, 0))  # HWC, BGR
+    elif n_dim == 2:
+        img_np = tensor.numpy()
+    else:
+        raise TypeError(
+            'Only support 4D, 3D and 2D tensor. But received with dimension: {:d}'.format(n_dim))
+    if out_type == np.uint8:
+        img_np = (img_np * 255.0).round()
+        # Important. Unlike matlab, numpy.unit8() WILL NOT round by default.
+    return img_np.astype(out_type)
+
+
+'''
+# --------------------------------------------
+# Augmentation, flipe and/or rotate
+# --------------------------------------------
+# The following two are enough.
+# (1) augmet_img: numpy image of WxHxC or WxH
+# (2) augment_img_tensor4: tensor image 1xCxWxH
+# --------------------------------------------
+'''
+
+
+def augment_img(img, mode=0):
+    '''Kai Zhang (github: https://github.com/cszn)
+    '''
+    if mode == 0:
+        return img
+    elif mode == 1:
+        return np.flipud(np.rot90(img))
+    elif mode == 2:
+        return np.flipud(img)
+    elif mode == 3:
+        return np.rot90(img, k=3)
+    elif mode == 4:
+        return np.flipud(np.rot90(img, k=2))
+    elif mode == 5:
+        return np.rot90(img)
+    elif mode == 6:
+        return np.rot90(img, k=2)
+    elif mode == 7:
+        return np.flipud(np.rot90(img, k=3))
+
+
+def augment_img_tensor4(img, mode=0):
+    '''Kai Zhang (github: https://github.com/cszn)
+    '''
+    if mode == 0:
+        return img
+    elif mode == 1:
+        return img.rot90(1, [2, 3]).flip([2])
+    elif mode == 2:
+        return img.flip([2])
+    elif mode == 3:
+        return img.rot90(3, [2, 3])
+    elif mode == 4:
+        return img.rot90(2, [2, 3]).flip([2])
+    elif mode == 5:
+        return img.rot90(1, [2, 3])
+    elif mode == 6:
+        return img.rot90(2, [2, 3])
+    elif mode == 7:
+        return img.rot90(3, [2, 3]).flip([2])
+
+
+def augment_img_tensor(img, mode=0):
+    '''Kai Zhang (github: https://github.com/cszn)
+    '''
+    img_size = img.size()
+    img_np = img.data.cpu().numpy()
+    if len(img_size) == 3:
+        img_np = np.transpose(img_np, (1, 2, 0))
+    elif len(img_size) == 4:
+        img_np = np.transpose(img_np, (2, 3, 1, 0))
+    img_np = augment_img(img_np, mode=mode)
+    img_tensor = torch.from_numpy(np.ascontiguousarray(img_np))
+    if len(img_size) == 3:
+        img_tensor = img_tensor.permute(2, 0, 1)
+    elif len(img_size) == 4:
+        img_tensor = img_tensor.permute(3, 2, 0, 1)
+
+    return img_tensor.type_as(img)
+
+
+def augment_img_np3(img, mode=0):
+    if mode == 0:
+        return img
+    elif mode == 1:
+        return img.transpose(1, 0, 2)
+    elif mode == 2:
+        return img[::-1, :, :]
+    elif mode == 3:
+        img = img[::-1, :, :]
+        img = img.transpose(1, 0, 2)
+        return img
+    elif mode == 4:
+        return img[:, ::-1, :]
+    elif mode == 5:
+        img = img[:, ::-1, :]
+        img = img.transpose(1, 0, 2)
+        return img
+    elif mode == 6:
+        img = img[:, ::-1, :]
+        img = img[::-1, :, :]
+        return img
+    elif mode == 7:
+        img = img[:, ::-1, :]
+        img = img[::-1, :, :]
+        img = img.transpose(1, 0, 2)
+        return img
+
+
+def augment_imgs(img_list, hflip=True, rot=True):
+    # horizontal flip OR rotate
+    hflip = hflip and random.random() < 0.5
+    vflip = rot and random.random() < 0.5
+    rot90 = rot and random.random() < 0.5
+
+    def _augment(img):
+        if hflip:
+            img = img[:, ::-1, :]
+        if vflip:
+            img = img[::-1, :, :]
+        if rot90:
+            img = img.transpose(1, 0, 2)
+        return img
+
+    return [_augment(img) for img in img_list]
+
+
+'''
+# --------------------------------------------
+# modcrop and shave
+# --------------------------------------------
+'''
+
+
+def modcrop(img_in, scale):
+    # img_in: Numpy, HWC or HW
+    img = np.copy(img_in)
+    if img.ndim == 2:
+        H, W = img.shape
+        H_r, W_r = H % scale, W % scale
+        img = img[:H - H_r, :W - W_r]
+    elif img.ndim == 3:
+        H, W, C = img.shape
+        H_r, W_r = H % scale, W % scale
+        img = img[:H - H_r, :W - W_r, :]
+    else:
+        raise ValueError('Wrong img ndim: [{:d}].'.format(img.ndim))
+    return img
+
+
+def shave(img_in, border=0):
+    # img_in: Numpy, HWC or HW
+    img = np.copy(img_in)
+    h, w = img.shape[:2]
+    img = img[border:h-border, border:w-border]
+    return img
+
+
+'''
+# --------------------------------------------
+# image processing process on numpy image
+# channel_convert(in_c, tar_type, img_list):
+# rgb2ycbcr(img, only_y=True):
+# bgr2ycbcr(img, only_y=True):
+# ycbcr2rgb(img):
+# --------------------------------------------
+'''
+
+
+def rgb2ycbcr(img, only_y=True):
+    '''same as matlab rgb2ycbcr
+    only_y: only return Y channel
+    Input:
+        uint8, [0, 255]
+        float, [0, 1]
+    '''
+    in_img_type = img.dtype
+    img.astype(np.float32)
+    if in_img_type != np.uint8:
+        img *= 255.
+    # convert
+    if only_y:
+        rlt = np.dot(img, [65.481, 128.553, 24.966]) / 255.0 + 16.0
+    else:
+        rlt = np.matmul(img, [[65.481, -37.797, 112.0], [128.553, -74.203, -93.786],
+                              [24.966, 112.0, -18.214]]) / 255.0 + [16, 128, 128]
+    if in_img_type == np.uint8:
+        rlt = rlt.round()
+    else:
+        rlt /= 255.
+    return rlt.astype(in_img_type)
+
+
+def ycbcr2rgb(img):
+    '''same as matlab ycbcr2rgb
+    Input:
+        uint8, [0, 255]
+        float, [0, 1]
+    '''
+    in_img_type = img.dtype
+    img.astype(np.float32)
+    if in_img_type != np.uint8:
+        img *= 255.
+    # convert
+    rlt = np.matmul(img, [[0.00456621, 0.00456621, 0.00456621], [0, -0.00153632, 0.00791071],
+                          [0.00625893, -0.00318811, 0]]) * 255.0 + [-222.921, 135.576, -276.836]
+    if in_img_type == np.uint8:
+        rlt = rlt.round()
+    else:
+        rlt /= 255.
+    return rlt.astype(in_img_type)
+
+
+def bgr2ycbcr(img, only_y=True):
+    '''bgr version of rgb2ycbcr
+    only_y: only return Y channel
+    Input:
+        uint8, [0, 255]
+        float, [0, 1]
+    '''
+    in_img_type = img.dtype
+    img.astype(np.float32)
+    if in_img_type != np.uint8:
+        img *= 255.
+    # convert
+    if only_y:
+        rlt = np.dot(img, [24.966, 128.553, 65.481]) / 255.0 + 16.0
+    else:
+        rlt = np.matmul(img, [[24.966, 112.0, -18.214], [128.553, -74.203, -93.786],
+                              [65.481, -37.797, 112.0]]) / 255.0 + [16, 128, 128]
+    if in_img_type == np.uint8:
+        rlt = rlt.round()
+    else:
+        rlt /= 255.
+    return rlt.astype(in_img_type)
+
+
+def channel_convert(in_c, tar_type, img_list):
+    # conversion among BGR, gray and y
+    if in_c == 3 and tar_type == 'gray':  # BGR to gray
+        gray_list = [cv2.cvtColor(img, cv2.COLOR_BGR2GRAY) for img in img_list]
+        return [np.expand_dims(img, axis=2) for img in gray_list]
+    elif in_c == 3 and tar_type == 'y':  # BGR to y
+        y_list = [bgr2ycbcr(img, only_y=True) for img in img_list]
+        return [np.expand_dims(img, axis=2) for img in y_list]
+    elif in_c == 1 and tar_type == 'RGB':  # gray/y to BGR
+        return [cv2.cvtColor(img, cv2.COLOR_GRAY2BGR) for img in img_list]
+    else:
+        return img_list
+
+
+'''
+# --------------------------------------------
+# metric, PSNR and SSIM
+# --------------------------------------------
+'''
+
+
+# --------------------------------------------
+# PSNR
+# --------------------------------------------
+def calculate_psnr(img1, img2, border=0):
+    # img1 and img2 have range [0, 255]
+    #img1 = img1.squeeze()
+    #img2 = img2.squeeze()
+    if not img1.shape == img2.shape:
+        raise ValueError('Input images must have the same dimensions.')
+    h, w = img1.shape[:2]
+    img1 = img1[border:h-border, border:w-border]
+    img2 = img2[border:h-border, border:w-border]
+
+    img1 = img1.astype(np.float64)
+    img2 = img2.astype(np.float64)
+    mse = np.mean((img1 - img2)**2)
+    if mse == 0:
+        return float('inf')
+    return 20 * math.log10(255.0 / math.sqrt(mse))
+
+
+# --------------------------------------------
+# SSIM
+# --------------------------------------------
+def calculate_ssim(img1, img2, border=0):
+    '''calculate SSIM
+    the same outputs as MATLAB's
+    img1, img2: [0, 255]
+    '''
+    #img1 = img1.squeeze()
+    #img2 = img2.squeeze()
+    if not img1.shape == img2.shape:
+        raise ValueError('Input images must have the same dimensions.')
+    h, w = img1.shape[:2]
+    img1 = img1[border:h-border, border:w-border]
+    img2 = img2[border:h-border, border:w-border]
+
+    if img1.ndim == 2:
+        return ssim(img1, img2)
+    elif img1.ndim == 3:
+        if img1.shape[2] == 3:
+            ssims = []
+            for i in range(3):
+                ssims.append(ssim(img1[:,:,i], img2[:,:,i]))
+            return np.array(ssims).mean()
+        elif img1.shape[2] == 1:
+            return ssim(np.squeeze(img1), np.squeeze(img2))
+    else:
+        raise ValueError('Wrong input image dimensions.')
+
+
+def ssim(img1, img2):
+    C1 = (0.01 * 255)**2
+    C2 = (0.03 * 255)**2
+
+    img1 = img1.astype(np.float64)
+    img2 = img2.astype(np.float64)
+    kernel = cv2.getGaussianKernel(11, 1.5)
+    window = np.outer(kernel, kernel.transpose())
+
+    mu1 = cv2.filter2D(img1, -1, window)[5:-5, 5:-5]  # valid
+    mu2 = cv2.filter2D(img2, -1, window)[5:-5, 5:-5]
+    mu1_sq = mu1**2
+    mu2_sq = mu2**2
+    mu1_mu2 = mu1 * mu2
+    sigma1_sq = cv2.filter2D(img1**2, -1, window)[5:-5, 5:-5] - mu1_sq
+    sigma2_sq = cv2.filter2D(img2**2, -1, window)[5:-5, 5:-5] - mu2_sq
+    sigma12 = cv2.filter2D(img1 * img2, -1, window)[5:-5, 5:-5] - mu1_mu2
+
+    ssim_map = ((2 * mu1_mu2 + C1) * (2 * sigma12 + C2)) / ((mu1_sq + mu2_sq + C1) *
+                                                            (sigma1_sq + sigma2_sq + C2))
+    return ssim_map.mean()
+
+
+'''
+# --------------------------------------------
+# matlab's bicubic imresize (numpy and torch) [0, 1]
+# --------------------------------------------
+'''
+
+
+# matlab 'imresize' function, now only support 'bicubic'
+def cubic(x):
+    absx = torch.abs(x)
+    absx2 = absx**2
+    absx3 = absx**3
+    return (1.5*absx3 - 2.5*absx2 + 1) * ((absx <= 1).type_as(absx)) + \
+        (-0.5*absx3 + 2.5*absx2 - 4*absx + 2) * (((absx > 1)*(absx <= 2)).type_as(absx))
+
+
+def calculate_weights_indices(in_length, out_length, scale, kernel, kernel_width, antialiasing):
+    if (scale < 1) and (antialiasing):
+        # Use a modified kernel to simultaneously interpolate and antialias- larger kernel width
+        kernel_width = kernel_width / scale
+
+    # Output-space coordinates
+    x = torch.linspace(1, out_length, out_length)
+
+    # Input-space coordinates. Calculate the inverse mapping such that 0.5
+    # in output space maps to 0.5 in input space, and 0.5+scale in output
+    # space maps to 1.5 in input space.
+    u = x / scale + 0.5 * (1 - 1 / scale)
+
+    # What is the left-most pixel that can be involved in the computation?
+    left = torch.floor(u - kernel_width / 2)
+
+    # What is the maximum number of pixels that can be involved in the
+    # computation?  Note: it's OK to use an extra pixel here; if the
+    # corresponding weights are all zero, it will be eliminated at the end
+    # of this function.
+    P = math.ceil(kernel_width) + 2
+
+    # The indices of the input pixels involved in computing the k-th output
+    # pixel are in row k of the indices matrix.
+    indices = left.view(out_length, 1).expand(out_length, P) + torch.linspace(0, P - 1, P).view(
+        1, P).expand(out_length, P)
+
+    # The weights used to compute the k-th output pixel are in row k of the
+    # weights matrix.
+    distance_to_center = u.view(out_length, 1).expand(out_length, P) - indices
+    # apply cubic kernel
+    if (scale < 1) and (antialiasing):
+        weights = scale * cubic(distance_to_center * scale)
+    else:
+        weights = cubic(distance_to_center)
+    # Normalize the weights matrix so that each row sums to 1.
+    weights_sum = torch.sum(weights, 1).view(out_length, 1)
+    weights = weights / weights_sum.expand(out_length, P)
+
+    # If a column in weights is all zero, get rid of it. only consider the first and last column.
+    weights_zero_tmp = torch.sum((weights == 0), 0)
+    if not math.isclose(weights_zero_tmp[0], 0, rel_tol=1e-6):
+        indices = indices.narrow(1, 1, P - 2)
+        weights = weights.narrow(1, 1, P - 2)
+    if not math.isclose(weights_zero_tmp[-1], 0, rel_tol=1e-6):
+        indices = indices.narrow(1, 0, P - 2)
+        weights = weights.narrow(1, 0, P - 2)
+    weights = weights.contiguous()
+    indices = indices.contiguous()
+    sym_len_s = -indices.min() + 1
+    sym_len_e = indices.max() - in_length
+    indices = indices + sym_len_s - 1
+    return weights, indices, int(sym_len_s), int(sym_len_e)
+
+
+# --------------------------------------------
+# imresize for tensor image [0, 1]
+# --------------------------------------------
+def imresize(img, scale, antialiasing=True):
+    # Now the scale should be the same for H and W
+    # input: img: pytorch tensor, CHW or HW [0,1]
+    # output: CHW or HW [0,1] w/o round
+    need_squeeze = True if img.dim() == 2 else False
+    if need_squeeze:
+        img.unsqueeze_(0)
+    in_C, in_H, in_W = img.size()
+    out_C, out_H, out_W = in_C, math.ceil(in_H * scale), math.ceil(in_W * scale)
+    kernel_width = 4
+    kernel = 'cubic'
+
+    # Return the desired dimension order for performing the resize.  The
+    # strategy is to perform the resize first along the dimension with the
+    # smallest scale factor.
+    # Now we do not support this.
+
+    # get weights and indices
+    weights_H, indices_H, sym_len_Hs, sym_len_He = calculate_weights_indices(
+        in_H, out_H, scale, kernel, kernel_width, antialiasing)
+    weights_W, indices_W, sym_len_Ws, sym_len_We = calculate_weights_indices(
+        in_W, out_W, scale, kernel, kernel_width, antialiasing)
+    # process H dimension
+    # symmetric copying
+    img_aug = torch.FloatTensor(in_C, in_H + sym_len_Hs + sym_len_He, in_W)
+    img_aug.narrow(1, sym_len_Hs, in_H).copy_(img)
+
+    sym_patch = img[:, :sym_len_Hs, :]
+    inv_idx = torch.arange(sym_patch.size(1) - 1, -1, -1).long()
+    sym_patch_inv = sym_patch.index_select(1, inv_idx)
+    img_aug.narrow(1, 0, sym_len_Hs).copy_(sym_patch_inv)
+
+    sym_patch = img[:, -sym_len_He:, :]
+    inv_idx = torch.arange(sym_patch.size(1) - 1, -1, -1).long()
+    sym_patch_inv = sym_patch.index_select(1, inv_idx)
+    img_aug.narrow(1, sym_len_Hs + in_H, sym_len_He).copy_(sym_patch_inv)
+
+    out_1 = torch.FloatTensor(in_C, out_H, in_W)
+    kernel_width = weights_H.size(1)
+    for i in range(out_H):
+        idx = int(indices_H[i][0])
+        for j in range(out_C):
+            out_1[j, i, :] = img_aug[j, idx:idx + kernel_width, :].transpose(0, 1).mv(weights_H[i])
+
+    # process W dimension
+    # symmetric copying
+    out_1_aug = torch.FloatTensor(in_C, out_H, in_W + sym_len_Ws + sym_len_We)
+    out_1_aug.narrow(2, sym_len_Ws, in_W).copy_(out_1)
+
+    sym_patch = out_1[:, :, :sym_len_Ws]
+    inv_idx = torch.arange(sym_patch.size(2) - 1, -1, -1).long()
+    sym_patch_inv = sym_patch.index_select(2, inv_idx)
+    out_1_aug.narrow(2, 0, sym_len_Ws).copy_(sym_patch_inv)
+
+    sym_patch = out_1[:, :, -sym_len_We:]
+    inv_idx = torch.arange(sym_patch.size(2) - 1, -1, -1).long()
+    sym_patch_inv = sym_patch.index_select(2, inv_idx)
+    out_1_aug.narrow(2, sym_len_Ws + in_W, sym_len_We).copy_(sym_patch_inv)
+
+    out_2 = torch.FloatTensor(in_C, out_H, out_W)
+    kernel_width = weights_W.size(1)
+    for i in range(out_W):
+        idx = int(indices_W[i][0])
+        for j in range(out_C):
+            out_2[j, :, i] = out_1_aug[j, :, idx:idx + kernel_width].mv(weights_W[i])
+    if need_squeeze:
+        out_2.squeeze_()
+    return out_2
+
+
+# --------------------------------------------
+# imresize for numpy image [0, 1]
+# --------------------------------------------
+def imresize_np(img, scale, antialiasing=True):
+    # Now the scale should be the same for H and W
+    # input: img: Numpy, HWC or HW [0,1]
+    # output: HWC or HW [0,1] w/o round
+    img = torch.from_numpy(img)
+    need_squeeze = True if img.dim() == 2 else False
+    if need_squeeze:
+        img.unsqueeze_(2)
+
+    in_H, in_W, in_C = img.size()
+    out_C, out_H, out_W = in_C, math.ceil(in_H * scale), math.ceil(in_W * scale)
+    kernel_width = 4
+    kernel = 'cubic'
+
+    # Return the desired dimension order for performing the resize.  The
+    # strategy is to perform the resize first along the dimension with the
+    # smallest scale factor.
+    # Now we do not support this.
+
+    # get weights and indices
+    weights_H, indices_H, sym_len_Hs, sym_len_He = calculate_weights_indices(
+        in_H, out_H, scale, kernel, kernel_width, antialiasing)
+    weights_W, indices_W, sym_len_Ws, sym_len_We = calculate_weights_indices(
+        in_W, out_W, scale, kernel, kernel_width, antialiasing)
+    # process H dimension
+    # symmetric copying
+    img_aug = torch.FloatTensor(in_H + sym_len_Hs + sym_len_He, in_W, in_C)
+    img_aug.narrow(0, sym_len_Hs, in_H).copy_(img)
+
+    sym_patch = img[:sym_len_Hs, :, :]
+    inv_idx = torch.arange(sym_patch.size(0) - 1, -1, -1).long()
+    sym_patch_inv = sym_patch.index_select(0, inv_idx)
+    img_aug.narrow(0, 0, sym_len_Hs).copy_(sym_patch_inv)
+
+    sym_patch = img[-sym_len_He:, :, :]
+    inv_idx = torch.arange(sym_patch.size(0) - 1, -1, -1).long()
+    sym_patch_inv = sym_patch.index_select(0, inv_idx)
+    img_aug.narrow(0, sym_len_Hs + in_H, sym_len_He).copy_(sym_patch_inv)
+
+    out_1 = torch.FloatTensor(out_H, in_W, in_C)
+    kernel_width = weights_H.size(1)
+    for i in range(out_H):
+        idx = int(indices_H[i][0])
+        for j in range(out_C):
+            out_1[i, :, j] = img_aug[idx:idx + kernel_width, :, j].transpose(0, 1).mv(weights_H[i])
+
+    # process W dimension
+    # symmetric copying
+    out_1_aug = torch.FloatTensor(out_H, in_W + sym_len_Ws + sym_len_We, in_C)
+    out_1_aug.narrow(1, sym_len_Ws, in_W).copy_(out_1)
+
+    sym_patch = out_1[:, :sym_len_Ws, :]
+    inv_idx = torch.arange(sym_patch.size(1) - 1, -1, -1).long()
+    sym_patch_inv = sym_patch.index_select(1, inv_idx)
+    out_1_aug.narrow(1, 0, sym_len_Ws).copy_(sym_patch_inv)
+
+    sym_patch = out_1[:, -sym_len_We:, :]
+    inv_idx = torch.arange(sym_patch.size(1) - 1, -1, -1).long()
+    sym_patch_inv = sym_patch.index_select(1, inv_idx)
+    out_1_aug.narrow(1, sym_len_Ws + in_W, sym_len_We).copy_(sym_patch_inv)
+
+    out_2 = torch.FloatTensor(out_H, out_W, in_C)
+    kernel_width = weights_W.size(1)
+    for i in range(out_W):
+        idx = int(indices_W[i][0])
+        for j in range(out_C):
+            out_2[:, i, j] = out_1_aug[:, idx:idx + kernel_width, j].mv(weights_W[i])
+    if need_squeeze:
+        out_2.squeeze_()
+
+    return out_2.numpy()
+
+
+if __name__ == '__main__':
+    print('---')
+#    img = imread_uint('test.bmp', 3)
+#    img = uint2single(img)
+#    img_bicubic = imresize_np(img, 1/4)

+ 1 - 0
ldm/modules/losses/__init__.py

@@ -0,0 +1 @@
+from ldm.modules.losses.contperceptual import LPIPSWithDiscriminator

+ 111 - 0
ldm/modules/losses/contperceptual.py

@@ -0,0 +1,111 @@
+import torch
+import torch.nn as nn
+
+from taming.modules.losses.vqperceptual import *  # TODO: taming dependency yes/no?
+
+
+class LPIPSWithDiscriminator(nn.Module):
+    def __init__(self, disc_start, logvar_init=0.0, kl_weight=1.0, pixelloss_weight=1.0,
+                 disc_num_layers=3, disc_in_channels=3, disc_factor=1.0, disc_weight=1.0,
+                 perceptual_weight=1.0, use_actnorm=False, disc_conditional=False,
+                 disc_loss="hinge"):
+
+        super().__init__()
+        assert disc_loss in ["hinge", "vanilla"]
+        self.kl_weight = kl_weight
+        self.pixel_weight = pixelloss_weight
+        self.perceptual_loss = LPIPS().eval()
+        self.perceptual_weight = perceptual_weight
+        # output log variance
+        self.logvar = nn.Parameter(torch.ones(size=()) * logvar_init)
+
+        self.discriminator = NLayerDiscriminator(input_nc=disc_in_channels,
+                                                 n_layers=disc_num_layers,
+                                                 use_actnorm=use_actnorm
+                                                 ).apply(weights_init)
+        self.discriminator_iter_start = disc_start
+        self.disc_loss = hinge_d_loss if disc_loss == "hinge" else vanilla_d_loss
+        self.disc_factor = disc_factor
+        self.discriminator_weight = disc_weight
+        self.disc_conditional = disc_conditional
+
+    def calculate_adaptive_weight(self, nll_loss, g_loss, last_layer=None):
+        if last_layer is not None:
+            nll_grads = torch.autograd.grad(nll_loss, last_layer, retain_graph=True)[0]
+            g_grads = torch.autograd.grad(g_loss, last_layer, retain_graph=True)[0]
+        else:
+            nll_grads = torch.autograd.grad(nll_loss, self.last_layer[0], retain_graph=True)[0]
+            g_grads = torch.autograd.grad(g_loss, self.last_layer[0], retain_graph=True)[0]
+
+        d_weight = torch.norm(nll_grads) / (torch.norm(g_grads) + 1e-4)
+        d_weight = torch.clamp(d_weight, 0.0, 1e4).detach()
+        d_weight = d_weight * self.discriminator_weight
+        return d_weight
+
+    def forward(self, inputs, reconstructions, posteriors, optimizer_idx,
+                global_step, last_layer=None, cond=None, split="train",
+                weights=None):
+        rec_loss = torch.abs(inputs.contiguous() - reconstructions.contiguous())
+        if self.perceptual_weight > 0:
+            p_loss = self.perceptual_loss(inputs.contiguous(), reconstructions.contiguous())
+            rec_loss = rec_loss + self.perceptual_weight * p_loss
+
+        nll_loss = rec_loss / torch.exp(self.logvar) + self.logvar
+        weighted_nll_loss = nll_loss
+        if weights is not None:
+            weighted_nll_loss = weights*nll_loss
+        weighted_nll_loss = torch.sum(weighted_nll_loss) / weighted_nll_loss.shape[0]
+        nll_loss = torch.sum(nll_loss) / nll_loss.shape[0]
+        kl_loss = posteriors.kl()
+        kl_loss = torch.sum(kl_loss) / kl_loss.shape[0]
+
+        # now the GAN part
+        if optimizer_idx == 0:
+            # generator update
+            if cond is None:
+                assert not self.disc_conditional
+                logits_fake = self.discriminator(reconstructions.contiguous())
+            else:
+                assert self.disc_conditional
+                logits_fake = self.discriminator(torch.cat((reconstructions.contiguous(), cond), dim=1))
+            g_loss = -torch.mean(logits_fake)
+
+            if self.disc_factor > 0.0:
+                try:
+                    d_weight = self.calculate_adaptive_weight(nll_loss, g_loss, last_layer=last_layer)
+                except RuntimeError:
+                    assert not self.training
+                    d_weight = torch.tensor(0.0)
+            else:
+                d_weight = torch.tensor(0.0)
+
+            disc_factor = adopt_weight(self.disc_factor, global_step, threshold=self.discriminator_iter_start)
+            loss = weighted_nll_loss + self.kl_weight * kl_loss + d_weight * disc_factor * g_loss
+
+            log = {"{}/total_loss".format(split): loss.clone().detach().mean(), "{}/logvar".format(split): self.logvar.detach(),
+                   "{}/kl_loss".format(split): kl_loss.detach().mean(), "{}/nll_loss".format(split): nll_loss.detach().mean(),
+                   "{}/rec_loss".format(split): rec_loss.detach().mean(),
+                   "{}/d_weight".format(split): d_weight.detach(),
+                   "{}/disc_factor".format(split): torch.tensor(disc_factor),
+                   "{}/g_loss".format(split): g_loss.detach().mean(),
+                   }
+            return loss, log
+
+        if optimizer_idx == 1:
+            # second pass for discriminator update
+            if cond is None:
+                logits_real = self.discriminator(inputs.contiguous().detach())
+                logits_fake = self.discriminator(reconstructions.contiguous().detach())
+            else:
+                logits_real = self.discriminator(torch.cat((inputs.contiguous().detach(), cond), dim=1))
+                logits_fake = self.discriminator(torch.cat((reconstructions.contiguous().detach(), cond), dim=1))
+
+            disc_factor = adopt_weight(self.disc_factor, global_step, threshold=self.discriminator_iter_start)
+            d_loss = disc_factor * self.disc_loss(logits_real, logits_fake)
+
+            log = {"{}/disc_loss".format(split): d_loss.clone().detach().mean(),
+                   "{}/logits_real".format(split): logits_real.detach().mean(),
+                   "{}/logits_fake".format(split): logits_fake.detach().mean()
+                   }
+            return d_loss, log
+

+ 641 - 0
ldm/modules/x_transformer.py

@@ -0,0 +1,641 @@
+"""shout-out to https://github.com/lucidrains/x-transformers/tree/main/x_transformers"""
+import torch
+from torch import nn, einsum
+import torch.nn.functional as F
+from functools import partial
+from inspect import isfunction
+from collections import namedtuple
+from einops import rearrange, repeat, reduce
+
+# constants
+
+DEFAULT_DIM_HEAD = 64
+
+Intermediates = namedtuple('Intermediates', [
+    'pre_softmax_attn',
+    'post_softmax_attn'
+])
+
+LayerIntermediates = namedtuple('Intermediates', [
+    'hiddens',
+    'attn_intermediates'
+])
+
+
+class AbsolutePositionalEmbedding(nn.Module):
+    def __init__(self, dim, max_seq_len):
+        super().__init__()
+        self.emb = nn.Embedding(max_seq_len, dim)
+        self.init_()
+
+    def init_(self):
+        nn.init.normal_(self.emb.weight, std=0.02)
+
+    def forward(self, x):
+        n = torch.arange(x.shape[1], device=x.device)
+        return self.emb(n)[None, :, :]
+
+
+class FixedPositionalEmbedding(nn.Module):
+    def __init__(self, dim):
+        super().__init__()
+        inv_freq = 1. / (10000 ** (torch.arange(0, dim, 2).float() / dim))
+        self.register_buffer('inv_freq', inv_freq)
+
+    def forward(self, x, seq_dim=1, offset=0):
+        t = torch.arange(x.shape[seq_dim], device=x.device).type_as(self.inv_freq) + offset
+        sinusoid_inp = torch.einsum('i , j -> i j', t, self.inv_freq)
+        emb = torch.cat((sinusoid_inp.sin(), sinusoid_inp.cos()), dim=-1)
+        return emb[None, :, :]
+
+
+# helpers
+
+def exists(val):
+    return val is not None
+
+
+def default(val, d):
+    if exists(val):
+        return val
+    return d() if isfunction(d) else d
+
+
+def always(val):
+    def inner(*args, **kwargs):
+        return val
+    return inner
+
+
+def not_equals(val):
+    def inner(x):
+        return x != val
+    return inner
+
+
+def equals(val):
+    def inner(x):
+        return x == val
+    return inner
+
+
+def max_neg_value(tensor):
+    return -torch.finfo(tensor.dtype).max
+
+
+# keyword argument helpers
+
+def pick_and_pop(keys, d):
+    values = list(map(lambda key: d.pop(key), keys))
+    return dict(zip(keys, values))
+
+
+def group_dict_by_key(cond, d):
+    return_val = [dict(), dict()]
+    for key in d.keys():
+        match = bool(cond(key))
+        ind = int(not match)
+        return_val[ind][key] = d[key]
+    return (*return_val,)
+
+
+def string_begins_with(prefix, str):
+    return str.startswith(prefix)
+
+
+def group_by_key_prefix(prefix, d):
+    return group_dict_by_key(partial(string_begins_with, prefix), d)
+
+
+def groupby_prefix_and_trim(prefix, d):
+    kwargs_with_prefix, kwargs = group_dict_by_key(partial(string_begins_with, prefix), d)
+    kwargs_without_prefix = dict(map(lambda x: (x[0][len(prefix):], x[1]), tuple(kwargs_with_prefix.items())))
+    return kwargs_without_prefix, kwargs
+
+
+# classes
+class Scale(nn.Module):
+    def __init__(self, value, fn):
+        super().__init__()
+        self.value = value
+        self.fn = fn
+
+    def forward(self, x, **kwargs):
+        x, *rest = self.fn(x, **kwargs)
+        return (x * self.value, *rest)
+
+
+class Rezero(nn.Module):
+    def __init__(self, fn):
+        super().__init__()
+        self.fn = fn
+        self.g = nn.Parameter(torch.zeros(1))
+
+    def forward(self, x, **kwargs):
+        x, *rest = self.fn(x, **kwargs)
+        return (x * self.g, *rest)
+
+
+class ScaleNorm(nn.Module):
+    def __init__(self, dim, eps=1e-5):
+        super().__init__()
+        self.scale = dim ** -0.5
+        self.eps = eps
+        self.g = nn.Parameter(torch.ones(1))
+
+    def forward(self, x):
+        norm = torch.norm(x, dim=-1, keepdim=True) * self.scale
+        return x / norm.clamp(min=self.eps) * self.g
+
+
+class RMSNorm(nn.Module):
+    def __init__(self, dim, eps=1e-8):
+        super().__init__()
+        self.scale = dim ** -0.5
+        self.eps = eps
+        self.g = nn.Parameter(torch.ones(dim))
+
+    def forward(self, x):
+        norm = torch.norm(x, dim=-1, keepdim=True) * self.scale
+        return x / norm.clamp(min=self.eps) * self.g
+
+
+class Residual(nn.Module):
+    def forward(self, x, residual):
+        return x + residual
+
+
+class GRUGating(nn.Module):
+    def __init__(self, dim):
+        super().__init__()
+        self.gru = nn.GRUCell(dim, dim)
+
+    def forward(self, x, residual):
+        gated_output = self.gru(
+            rearrange(x, 'b n d -> (b n) d'),
+            rearrange(residual, 'b n d -> (b n) d')
+        )
+
+        return gated_output.reshape_as(x)
+
+
+# feedforward
+
+class GEGLU(nn.Module):
+    def __init__(self, dim_in, dim_out):
+        super().__init__()
+        self.proj = nn.Linear(dim_in, dim_out * 2)
+
+    def forward(self, x):
+        x, gate = self.proj(x).chunk(2, dim=-1)
+        return x * F.gelu(gate)
+
+
+class FeedForward(nn.Module):
+    def __init__(self, dim, dim_out=None, mult=4, glu=False, dropout=0.):
+        super().__init__()
+        inner_dim = int(dim * mult)
+        dim_out = default(dim_out, dim)
+        project_in = nn.Sequential(
+            nn.Linear(dim, inner_dim),
+            nn.GELU()
+        ) if not glu else GEGLU(dim, inner_dim)
+
+        self.net = nn.Sequential(
+            project_in,
+            nn.Dropout(dropout),
+            nn.Linear(inner_dim, dim_out)
+        )
+
+    def forward(self, x):
+        return self.net(x)
+
+
+# attention.
+class Attention(nn.Module):
+    def __init__(
+            self,
+            dim,
+            dim_head=DEFAULT_DIM_HEAD,
+            heads=8,
+            causal=False,
+            mask=None,
+            talking_heads=False,
+            sparse_topk=None,
+            use_entmax15=False,
+            num_mem_kv=0,
+            dropout=0.,
+            on_attn=False
+    ):
+        super().__init__()
+        if use_entmax15:
+            raise NotImplementedError("Check out entmax activation instead of softmax activation!")
+        self.scale = dim_head ** -0.5
+        self.heads = heads
+        self.causal = causal
+        self.mask = mask
+
+        inner_dim = dim_head * heads
+
+        self.to_q = nn.Linear(dim, inner_dim, bias=False)
+        self.to_k = nn.Linear(dim, inner_dim, bias=False)
+        self.to_v = nn.Linear(dim, inner_dim, bias=False)
+        self.dropout = nn.Dropout(dropout)
+
+        # talking heads
+        self.talking_heads = talking_heads
+        if talking_heads:
+            self.pre_softmax_proj = nn.Parameter(torch.randn(heads, heads))
+            self.post_softmax_proj = nn.Parameter(torch.randn(heads, heads))
+
+        # explicit topk sparse attention
+        self.sparse_topk = sparse_topk
+
+        # entmax
+        #self.attn_fn = entmax15 if use_entmax15 else F.softmax
+        self.attn_fn = F.softmax
+
+        # add memory key / values
+        self.num_mem_kv = num_mem_kv
+        if num_mem_kv > 0:
+            self.mem_k = nn.Parameter(torch.randn(heads, num_mem_kv, dim_head))
+            self.mem_v = nn.Parameter(torch.randn(heads, num_mem_kv, dim_head))
+
+        # attention on attention
+        self.attn_on_attn = on_attn
+        self.to_out = nn.Sequential(nn.Linear(inner_dim, dim * 2), nn.GLU()) if on_attn else nn.Linear(inner_dim, dim)
+
+    def forward(
+            self,
+            x,
+            context=None,
+            mask=None,
+            context_mask=None,
+            rel_pos=None,
+            sinusoidal_emb=None,
+            prev_attn=None,
+            mem=None
+    ):
+        b, n, _, h, talking_heads, device = *x.shape, self.heads, self.talking_heads, x.device
+        kv_input = default(context, x)
+
+        q_input = x
+        k_input = kv_input
+        v_input = kv_input
+
+        if exists(mem):
+            k_input = torch.cat((mem, k_input), dim=-2)
+            v_input = torch.cat((mem, v_input), dim=-2)
+
+        if exists(sinusoidal_emb):
+            # in shortformer, the query would start at a position offset depending on the past cached memory
+            offset = k_input.shape[-2] - q_input.shape[-2]
+            q_input = q_input + sinusoidal_emb(q_input, offset=offset)
+            k_input = k_input + sinusoidal_emb(k_input)
+
+        q = self.to_q(q_input)
+        k = self.to_k(k_input)
+        v = self.to_v(v_input)
+
+        q, k, v = map(lambda t: rearrange(t, 'b n (h d) -> b h n d', h=h), (q, k, v))
+
+        input_mask = None
+        if any(map(exists, (mask, context_mask))):
+            q_mask = default(mask, lambda: torch.ones((b, n), device=device).bool())
+            k_mask = q_mask if not exists(context) else context_mask
+            k_mask = default(k_mask, lambda: torch.ones((b, k.shape[-2]), device=device).bool())
+            q_mask = rearrange(q_mask, 'b i -> b () i ()')
+            k_mask = rearrange(k_mask, 'b j -> b () () j')
+            input_mask = q_mask * k_mask
+
+        if self.num_mem_kv > 0:
+            mem_k, mem_v = map(lambda t: repeat(t, 'h n d -> b h n d', b=b), (self.mem_k, self.mem_v))
+            k = torch.cat((mem_k, k), dim=-2)
+            v = torch.cat((mem_v, v), dim=-2)
+            if exists(input_mask):
+                input_mask = F.pad(input_mask, (self.num_mem_kv, 0), value=True)
+
+        dots = einsum('b h i d, b h j d -> b h i j', q, k) * self.scale
+        mask_value = max_neg_value(dots)
+
+        if exists(prev_attn):
+            dots = dots + prev_attn
+
+        pre_softmax_attn = dots
+
+        if talking_heads:
+            dots = einsum('b h i j, h k -> b k i j', dots, self.pre_softmax_proj).contiguous()
+
+        if exists(rel_pos):
+            dots = rel_pos(dots)
+
+        if exists(input_mask):
+            dots.masked_fill_(~input_mask, mask_value)
+            del input_mask
+
+        if self.causal:
+            i, j = dots.shape[-2:]
+            r = torch.arange(i, device=device)
+            mask = rearrange(r, 'i -> () () i ()') < rearrange(r, 'j -> () () () j')
+            mask = F.pad(mask, (j - i, 0), value=False)
+            dots.masked_fill_(mask, mask_value)
+            del mask
+
+        if exists(self.sparse_topk) and self.sparse_topk < dots.shape[-1]:
+            top, _ = dots.topk(self.sparse_topk, dim=-1)
+            vk = top[..., -1].unsqueeze(-1).expand_as(dots)
+            mask = dots < vk
+            dots.masked_fill_(mask, mask_value)
+            del mask
+
+        attn = self.attn_fn(dots, dim=-1)
+        post_softmax_attn = attn
+
+        attn = self.dropout(attn)
+
+        if talking_heads:
+            attn = einsum('b h i j, h k -> b k i j', attn, self.post_softmax_proj).contiguous()
+
+        out = einsum('b h i j, b h j d -> b h i d', attn, v)
+        out = rearrange(out, 'b h n d -> b n (h d)')
+
+        intermediates = Intermediates(
+            pre_softmax_attn=pre_softmax_attn,
+            post_softmax_attn=post_softmax_attn
+        )
+
+        return self.to_out(out), intermediates
+
+
+class AttentionLayers(nn.Module):
+    def __init__(
+            self,
+            dim,
+            depth,
+            heads=8,
+            causal=False,
+            cross_attend=False,
+            only_cross=False,
+            use_scalenorm=False,
+            use_rmsnorm=False,
+            use_rezero=False,
+            rel_pos_num_buckets=32,
+            rel_pos_max_distance=128,
+            position_infused_attn=False,
+            custom_layers=None,
+            sandwich_coef=None,
+            par_ratio=None,
+            residual_attn=False,
+            cross_residual_attn=False,
+            macaron=False,
+            pre_norm=True,
+            gate_residual=False,
+            **kwargs
+    ):
+        super().__init__()
+        ff_kwargs, kwargs = groupby_prefix_and_trim('ff_', kwargs)
+        attn_kwargs, _ = groupby_prefix_and_trim('attn_', kwargs)
+
+        dim_head = attn_kwargs.get('dim_head', DEFAULT_DIM_HEAD)
+
+        self.dim = dim
+        self.depth = depth
+        self.layers = nn.ModuleList([])
+
+        self.has_pos_emb = position_infused_attn
+        self.pia_pos_emb = FixedPositionalEmbedding(dim) if position_infused_attn else None
+        self.rotary_pos_emb = always(None)
+
+        assert rel_pos_num_buckets <= rel_pos_max_distance, 'number of relative position buckets must be less than the relative position max distance'
+        self.rel_pos = always(None)
+
+        self.pre_norm = pre_norm
+
+        self.residual_attn = residual_attn
+        self.cross_residual_attn = cross_residual_attn
+
+        norm_class = ScaleNorm if use_scalenorm else nn.LayerNorm
+        norm_class = RMSNorm if use_rmsnorm else norm_class
+        norm_fn = partial(norm_class, dim)
+
+        norm_fn = nn.Identity if use_rezero else norm_fn
+        branch_fn = Rezero if use_rezero else None
+
+        if cross_attend and not only_cross:
+            default_block = ('a', 'c', 'f')
+        elif cross_attend and only_cross:
+            default_block = ('c', 'f')
+        else:
+            default_block = ('a', 'f')
+
+        if macaron:
+            default_block = ('f',) + default_block
+
+        if exists(custom_layers):
+            layer_types = custom_layers
+        elif exists(par_ratio):
+            par_depth = depth * len(default_block)
+            assert 1 < par_ratio <= par_depth, 'par ratio out of range'
+            default_block = tuple(filter(not_equals('f'), default_block))
+            par_attn = par_depth // par_ratio
+            depth_cut = par_depth * 2 // 3  # 2 / 3 attention layer cutoff suggested by PAR paper
+            par_width = (depth_cut + depth_cut // par_attn) // par_attn
+            assert len(default_block) <= par_width, 'default block is too large for par_ratio'
+            par_block = default_block + ('f',) * (par_width - len(default_block))
+            par_head = par_block * par_attn
+            layer_types = par_head + ('f',) * (par_depth - len(par_head))
+        elif exists(sandwich_coef):
+            assert sandwich_coef > 0 and sandwich_coef <= depth, 'sandwich coefficient should be less than the depth'
+            layer_types = ('a',) * sandwich_coef + default_block * (depth - sandwich_coef) + ('f',) * sandwich_coef
+        else:
+            layer_types = default_block * depth
+
+        self.layer_types = layer_types
+        self.num_attn_layers = len(list(filter(equals('a'), layer_types)))
+
+        for layer_type in self.layer_types:
+            if layer_type == 'a':
+                layer = Attention(dim, heads=heads, causal=causal, **attn_kwargs)
+            elif layer_type == 'c':
+                layer = Attention(dim, heads=heads, **attn_kwargs)
+            elif layer_type == 'f':
+                layer = FeedForward(dim, **ff_kwargs)
+                layer = layer if not macaron else Scale(0.5, layer)
+            else:
+                raise Exception(f'invalid layer type {layer_type}')
+
+            if isinstance(layer, Attention) and exists(branch_fn):
+                layer = branch_fn(layer)
+
+            if gate_residual:
+                residual_fn = GRUGating(dim)
+            else:
+                residual_fn = Residual()
+
+            self.layers.append(nn.ModuleList([
+                norm_fn(),
+                layer,
+                residual_fn
+            ]))
+
+    def forward(
+            self,
+            x,
+            context=None,
+            mask=None,
+            context_mask=None,
+            mems=None,
+            return_hiddens=False
+    ):
+        hiddens = []
+        intermediates = []
+        prev_attn = None
+        prev_cross_attn = None
+
+        mems = mems.copy() if exists(mems) else [None] * self.num_attn_layers
+
+        for ind, (layer_type, (norm, block, residual_fn)) in enumerate(zip(self.layer_types, self.layers)):
+            is_last = ind == (len(self.layers) - 1)
+
+            if layer_type == 'a':
+                hiddens.append(x)
+                layer_mem = mems.pop(0)
+
+            residual = x
+
+            if self.pre_norm:
+                x = norm(x)
+
+            if layer_type == 'a':
+                out, inter = block(x, mask=mask, sinusoidal_emb=self.pia_pos_emb, rel_pos=self.rel_pos,
+                                   prev_attn=prev_attn, mem=layer_mem)
+            elif layer_type == 'c':
+                out, inter = block(x, context=context, mask=mask, context_mask=context_mask, prev_attn=prev_cross_attn)
+            elif layer_type == 'f':
+                out = block(x)
+
+            x = residual_fn(out, residual)
+
+            if layer_type in ('a', 'c'):
+                intermediates.append(inter)
+
+            if layer_type == 'a' and self.residual_attn:
+                prev_attn = inter.pre_softmax_attn
+            elif layer_type == 'c' and self.cross_residual_attn:
+                prev_cross_attn = inter.pre_softmax_attn
+
+            if not self.pre_norm and not is_last:
+                x = norm(x)
+
+        if return_hiddens:
+            intermediates = LayerIntermediates(
+                hiddens=hiddens,
+                attn_intermediates=intermediates
+            )
+
+            return x, intermediates
+
+        return x
+
+
+class Encoder(AttentionLayers):
+    def __init__(self, **kwargs):
+        assert 'causal' not in kwargs, 'cannot set causality on encoder'
+        super().__init__(causal=False, **kwargs)
+
+
+
+class TransformerWrapper(nn.Module):
+    def __init__(
+            self,
+            *,
+            num_tokens,
+            max_seq_len,
+            attn_layers,
+            emb_dim=None,
+            max_mem_len=0.,
+            emb_dropout=0.,
+            num_memory_tokens=None,
+            tie_embedding=False,
+            use_pos_emb=True
+    ):
+        super().__init__()
+        assert isinstance(attn_layers, AttentionLayers), 'attention layers must be one of Encoder or Decoder'
+
+        dim = attn_layers.dim
+        emb_dim = default(emb_dim, dim)
+
+        self.max_seq_len = max_seq_len
+        self.max_mem_len = max_mem_len
+        self.num_tokens = num_tokens
+
+        self.token_emb = nn.Embedding(num_tokens, emb_dim)
+        self.pos_emb = AbsolutePositionalEmbedding(emb_dim, max_seq_len) if (
+                    use_pos_emb and not attn_layers.has_pos_emb) else always(0)
+        self.emb_dropout = nn.Dropout(emb_dropout)
+
+        self.project_emb = nn.Linear(emb_dim, dim) if emb_dim != dim else nn.Identity()
+        self.attn_layers = attn_layers
+        self.norm = nn.LayerNorm(dim)
+
+        self.init_()
+
+        self.to_logits = nn.Linear(dim, num_tokens) if not tie_embedding else lambda t: t @ self.token_emb.weight.t()
+
+        # memory tokens (like [cls]) from Memory Transformers paper
+        num_memory_tokens = default(num_memory_tokens, 0)
+        self.num_memory_tokens = num_memory_tokens
+        if num_memory_tokens > 0:
+            self.memory_tokens = nn.Parameter(torch.randn(num_memory_tokens, dim))
+
+            # let funnel encoder know number of memory tokens, if specified
+            if hasattr(attn_layers, 'num_memory_tokens'):
+                attn_layers.num_memory_tokens = num_memory_tokens
+
+    def init_(self):
+        nn.init.normal_(self.token_emb.weight, std=0.02)
+
+    def forward(
+            self,
+            x,
+            return_embeddings=False,
+            mask=None,
+            return_mems=False,
+            return_attn=False,
+            mems=None,
+            **kwargs
+    ):
+        b, n, device, num_mem = *x.shape, x.device, self.num_memory_tokens
+        x = self.token_emb(x)
+        x += self.pos_emb(x)
+        x = self.emb_dropout(x)
+
+        x = self.project_emb(x)
+
+        if num_mem > 0:
+            mem = repeat(self.memory_tokens, 'n d -> b n d', b=b)
+            x = torch.cat((mem, x), dim=1)
+
+            # auto-handle masking after appending memory tokens
+            if exists(mask):
+                mask = F.pad(mask, (num_mem, 0), value=True)
+
+        x, intermediates = self.attn_layers(x, mask=mask, mems=mems, return_hiddens=True, **kwargs)
+        x = self.norm(x)
+
+        mem, x = x[:, :num_mem], x[:, num_mem:]
+
+        out = self.to_logits(x) if not return_embeddings else x
+
+        if return_mems:
+            hiddens = intermediates.hiddens
+            new_mems = list(map(lambda pair: torch.cat(pair, dim=-2), zip(mems, hiddens))) if exists(mems) else hiddens
+            new_mems = list(map(lambda t: t[..., -self.max_mem_len:, :].detach(), new_mems))
+            return out, new_mems
+
+        if return_attn:
+            attn_maps = list(map(lambda t: t.post_softmax_attn, intermediates.attn_intermediates))
+            return out, attn_maps
+
+        return out
+

+ 86 - 0
ldm/util.py

@@ -0,0 +1,86 @@
+import importlib
+
+import torch
+import numpy as np
+
+from inspect import isfunction
+from PIL import Image, ImageDraw, ImageFont
+
+
+def log_txt_as_img(wh, xc, size=10):
+    # wh a tuple of (width, height)
+    # xc a list of captions to plot
+    b = len(xc)
+    txts = list()
+    for bi in range(b):
+        txt = Image.new("RGB", wh, color="white")
+        draw = ImageDraw.Draw(txt)
+        font = ImageFont.truetype('data/DejaVuSans.ttf', size=size)
+        nc = int(40 * (wh[0] / 256))
+        lines = "\n".join(xc[bi][start:start + nc] for start in range(0, len(xc[bi]), nc))
+
+        try:
+            draw.text((0, 0), lines, fill="black", font=font)
+        except UnicodeEncodeError:
+            print("Cant encode string for logging. Skipping.")
+
+        txt = np.array(txt).transpose(2, 0, 1) / 127.5 - 1.0
+        txts.append(txt)
+    txts = np.stack(txts)
+    txts = torch.tensor(txts)
+    return txts
+
+
+def ismap(x):
+    if not isinstance(x, torch.Tensor):
+        return False
+    return (len(x.shape) == 4) and (x.shape[1] > 3)
+
+
+def isimage(x):
+    if not isinstance(x,torch.Tensor):
+        return False
+    return (len(x.shape) == 4) and (x.shape[1] == 3 or x.shape[1] == 1)
+
+
+def exists(x):
+    return x is not None
+
+
+def default(val, d):
+    if exists(val):
+        return val
+    return d() if isfunction(d) else d
+
+
+def mean_flat(tensor):
+    """
+    https://github.com/openai/guided-diffusion/blob/27c20a8fab9cb472df5d6bdd6c8d11c8f430b924/guided_diffusion/nn.py#L86
+    Take the mean over all non-batch dimensions.
+    """
+    return tensor.mean(dim=list(range(1, len(tensor.shape))))
+
+
+def count_params(model, verbose=False):
+    total_params = sum(p.numel() for p in model.parameters())
+    if verbose:
+        print(f"{model.__class__.__name__} has {total_params*1.e-6:.2f} M params.")
+    return total_params
+
+
+def instantiate_from_config(config):
+    if not "target" in config:
+        if config == '__is_first_stage__':
+            return None
+        elif config == "__is_unconditional__":
+            return None
+        raise KeyError("Expected key `target` to instantiate.")
+    return get_obj_from_str(config["target"])(**config.get("params", dict()))
+
+
+def get_obj_from_str(string, reload=False):
+    module, cls = string.rsplit(".", 1)
+    if reload:
+        module_imp = importlib.import_module(module)
+        importlib.reload(module_imp)
+    return getattr(importlib.import_module(module, package=None), cls)

+ 738 - 0
main.py

@@ -0,0 +1,738 @@
+import argparse, os, sys, datetime, glob, importlib, csv
+import numpy as np
+import time
+import torch
+import torchvision
+import pytorch_lightning as pl
+
+from packaging import version
+from omegaconf import OmegaConf
+from torch.utils.data import random_split, DataLoader, Dataset, Subset
+from functools import partial
+from PIL import Image
+
+from pytorch_lightning import seed_everything
+from pytorch_lightning.trainer import Trainer
+from pytorch_lightning.callbacks import ModelCheckpoint, Callback, LearningRateMonitor
+from pytorch_lightning.utilities.distributed import rank_zero_only
+from pytorch_lightning.utilities import rank_zero_info
+
+from ldm.data.base import Txt2ImgIterableBaseDataset
+from ldm.util import instantiate_from_config
+
+
+def get_parser(**parser_kwargs):
+    def str2bool(v):
+        if isinstance(v, bool):
+            return v
+        if v.lower() in ("yes", "true", "t", "y", "1"):
+            return True
+        elif v.lower() in ("no", "false", "f", "n", "0"):
+            return False
+        else:
+            raise argparse.ArgumentTypeError("Boolean value expected.")
+
+    parser = argparse.ArgumentParser(**parser_kwargs)
+    parser.add_argument(
+        "-n",
+        "--name",
+        type=str,
+        const=True,
+        default="",
+        nargs="?",
+        help="postfix for logdir",
+    )
+    parser.add_argument(
+        "-r",
+        "--resume",
+        type=str,
+        const=True,
+        default="",
+        nargs="?",
+        help="resume from logdir or checkpoint in logdir",
+    )
+    parser.add_argument(
+        "-b",
+        "--base",
+        nargs="*",
+        metavar="base_config.yaml",
+        help="paths to base configs. Loaded from left-to-right. "
+             "Parameters can be overwritten or added with command-line options of the form `--key value`.",
+        default=list(),
+    )
+    parser.add_argument(
+        "-t",
+        "--train",
+        type=str2bool,
+        const=True,
+        default=False,
+        nargs="?",
+        help="train",
+    )
+    parser.add_argument(
+        "--no-test",
+        type=str2bool,
+        const=True,
+        default=False,
+        nargs="?",
+        help="disable test",
+    )
+    parser.add_argument(
+        "-p",
+        "--project",
+        help="name of new or path to existing project"
+    )
+    parser.add_argument(
+        "-d",
+        "--debug",
+        type=str2bool,
+        nargs="?",
+        const=True,
+        default=False,
+        help="enable post-mortem debugging",
+    )
+    parser.add_argument(
+        "-s",
+        "--seed",
+        type=int,
+        default=23,
+        help="seed for seed_everything",
+    )
+    parser.add_argument(
+        "-f",
+        "--postfix",
+        type=str,
+        default="",
+        help="post-postfix for default name",
+    )
+    parser.add_argument(
+        "-l",
+        "--logdir",
+        type=str,
+        default="logs",
+        help="directory for logging dat shit",
+    )
+    parser.add_argument(
+        "--scale_lr",
+        type=str2bool,
+        nargs="?",
+        const=True,
+        default=True,
+        help="scale base-lr by ngpu * batch_size * n_accumulate",
+    )
+    return parser
+
+
+def nondefault_trainer_args(opt):
+    parser = argparse.ArgumentParser()
+    parser = Trainer.add_argparse_args(parser)
+    args = parser.parse_args([])
+    return sorted(k for k in vars(args) if getattr(opt, k) != getattr(args, k))
+
+
+class WrappedDataset(Dataset):
+    """Wraps an arbitrary object with __len__ and __getitem__ into a pytorch dataset"""
+
+    def __init__(self, dataset):
+        self.data = dataset
+
+    def __len__(self):
+        return len(self.data)
+
+    def __getitem__(self, idx):
+        return self.data[idx]
+
+
+def worker_init_fn(_):
+    worker_info = torch.utils.data.get_worker_info()
+
+    dataset = worker_info.dataset
+    worker_id = worker_info.id
+
+    if isinstance(dataset, Txt2ImgIterableBaseDataset):
+        split_size = dataset.num_records // worker_info.num_workers
+        # reset num_records to the true number to retain reliable length information
+        dataset.sample_ids = dataset.valid_ids[worker_id * split_size:(worker_id + 1) * split_size]
+        current_id = np.random.choice(len(np.random.get_state()[1]), 1)
+        return np.random.seed(np.random.get_state()[1][current_id] + worker_id)
+    else:
+        return np.random.seed(np.random.get_state()[1][0] + worker_id)
+
+
+class DataModuleFromConfig(pl.LightningDataModule):
+    def __init__(self, batch_size, train=None, validation=None, test=None, predict=None,
+                 wrap=False, num_workers=None, shuffle_test_loader=False, use_worker_init_fn=False,
+                 shuffle_val_dataloader=False):
+        super().__init__()
+        self.batch_size = batch_size
+        self.dataset_configs = dict()
+        self.num_workers = num_workers if num_workers is not None else batch_size * 2
+        self.use_worker_init_fn = use_worker_init_fn
+        if train is not None:
+            self.dataset_configs["train"] = train
+            self.train_dataloader = self._train_dataloader
+        if validation is not None:
+            self.dataset_configs["validation"] = validation
+            self.val_dataloader = partial(self._val_dataloader, shuffle=shuffle_val_dataloader)
+        if test is not None:
+            self.dataset_configs["test"] = test
+            self.test_dataloader = partial(self._test_dataloader, shuffle=shuffle_test_loader)
+        if predict is not None:
+            self.dataset_configs["predict"] = predict
+            self.predict_dataloader = self._predict_dataloader
+        self.wrap = wrap
+
+    def prepare_data(self):
+        for data_cfg in self.dataset_configs.values():
+            instantiate_from_config(data_cfg)
+
+    def setup(self, stage=None):
+        self.datasets = dict(
+            (k, instantiate_from_config(self.dataset_configs[k]))
+            for k in self.dataset_configs)
+        if self.wrap:
+            for k in self.datasets:
+                self.datasets[k] = WrappedDataset(self.datasets[k])
+
+    def _train_dataloader(self):
+        is_iterable_dataset = isinstance(self.datasets['train'], Txt2ImgIterableBaseDataset)
+        if is_iterable_dataset or self.use_worker_init_fn:
+            init_fn = worker_init_fn
+        else:
+            init_fn = None
+        return DataLoader(self.datasets["train"], batch_size=self.batch_size,
+                          num_workers=self.num_workers, shuffle=False if is_iterable_dataset else True,
+                          worker_init_fn=init_fn)
+
+    def _val_dataloader(self, shuffle=False):
+        if isinstance(self.datasets['validation'], Txt2ImgIterableBaseDataset) or self.use_worker_init_fn:
+            init_fn = worker_init_fn
+        else:
+            init_fn = None
+        return DataLoader(self.datasets["validation"],
+                          batch_size=self.batch_size,
+                          num_workers=self.num_workers,
+                          worker_init_fn=init_fn,
+                          shuffle=shuffle)
+
+    def _test_dataloader(self, shuffle=False):
+        is_iterable_dataset = isinstance(self.datasets['train'], Txt2ImgIterableBaseDataset)
+        if is_iterable_dataset or self.use_worker_init_fn:
+            init_fn = worker_init_fn
+        else:
+            init_fn = None
+
+        # do not shuffle dataloader for iterable dataset
+        shuffle = shuffle and (not is_iterable_dataset)
+
+        return DataLoader(self.datasets["test"], batch_size=self.batch_size,
+                          num_workers=self.num_workers, worker_init_fn=init_fn, shuffle=shuffle)
+
+    def _predict_dataloader(self, shuffle=False):
+        if isinstance(self.datasets['predict'], Txt2ImgIterableBaseDataset) or self.use_worker_init_fn:
+            init_fn = worker_init_fn
+        else:
+            init_fn = None
+        return DataLoader(self.datasets["predict"], batch_size=self.batch_size,
+                          num_workers=self.num_workers, worker_init_fn=init_fn)
+
+
+class SetupCallback(Callback):
+    def __init__(self, resume, now, logdir, ckptdir, cfgdir, config, lightning_config):
+        super().__init__()
+        self.resume = resume
+        self.now = now
+        self.logdir = logdir
+        self.ckptdir = ckptdir
+        self.cfgdir = cfgdir
+        self.config = config
+        self.lightning_config = lightning_config
+
+    def on_keyboard_interrupt(self, trainer, pl_module):
+        if trainer.global_rank == 0:
+            print("Summoning checkpoint.")
+            ckpt_path = os.path.join(self.ckptdir, "last.ckpt")
+            trainer.save_checkpoint(ckpt_path)
+
+    def on_pretrain_routine_start(self, trainer, pl_module):
+        if trainer.global_rank == 0:
+            # Create logdirs and save configs
+            os.makedirs(self.logdir, exist_ok=True)
+            os.makedirs(self.ckptdir, exist_ok=True)
+            os.makedirs(self.cfgdir, exist_ok=True)
+
+            if "callbacks" in self.lightning_config:
+                if 'metrics_over_trainsteps_checkpoint' in self.lightning_config['callbacks']:
+                    os.makedirs(os.path.join(self.ckptdir, 'trainstep_checkpoints'), exist_ok=True)
+            print("Project config")
+            print(OmegaConf.to_yaml(self.config))
+            OmegaConf.save(self.config,
+                           os.path.join(self.cfgdir, "{}-project.yaml".format(self.now)))
+
+            print("Lightning config")
+            print(OmegaConf.to_yaml(self.lightning_config))
+            OmegaConf.save(OmegaConf.create({"lightning": self.lightning_config}),
+                           os.path.join(self.cfgdir, "{}-lightning.yaml".format(self.now)))
+
+        else:
+            # ModelCheckpoint callback created log directory --- remove it
+            if not self.resume and os.path.exists(self.logdir):
+                dst, name = os.path.split(self.logdir)
+                dst = os.path.join(dst, "child_runs", name)
+                os.makedirs(os.path.split(dst)[0], exist_ok=True)
+                try:
+                    os.rename(self.logdir, dst)
+                except FileNotFoundError:
+                    pass
+
+
+class ImageLogger(Callback):
+    def __init__(self, batch_frequency, max_images, clamp=True, increase_log_steps=True,
+                 rescale=True, disabled=False, log_on_batch_idx=False, log_first_step=False,
+                 log_images_kwargs=None):
+        super().__init__()
+        self.rescale = rescale
+        self.batch_freq = batch_frequency
+        self.max_images = max_images
+        self.logger_log_images = {
+            pl.loggers.TestTubeLogger: self._testtube,
+        }
+        self.log_steps = [2 ** n for n in range(int(np.log2(self.batch_freq)) + 1)]
+        if not increase_log_steps:
+            self.log_steps = [self.batch_freq]
+        self.clamp = clamp
+        self.disabled = disabled
+        self.log_on_batch_idx = log_on_batch_idx
+        self.log_images_kwargs = log_images_kwargs if log_images_kwargs else {}
+        self.log_first_step = log_first_step
+
+    @rank_zero_only
+    def _testtube(self, pl_module, images, batch_idx, split):
+        for k in images:
+            grid = torchvision.utils.make_grid(images[k])
+            grid = (grid + 1.0) / 2.0  # -1,1 -> 0,1; c,h,w
+
+            tag = f"{split}/{k}"
+            pl_module.logger.experiment.add_image(
+                tag, grid,
+                global_step=pl_module.global_step)
+
+    @rank_zero_only
+    def log_local(self, save_dir, split, images,
+                  global_step, current_epoch, batch_idx):
+        root = os.path.join(save_dir, "images", split)
+        for k in images:
+            grid = torchvision.utils.make_grid(images[k], nrow=4)
+            if self.rescale:
+                grid = (grid + 1.0) / 2.0  # -1,1 -> 0,1; c,h,w
+            grid = grid.transpose(0, 1).transpose(1, 2).squeeze(-1)
+            grid = grid.numpy()
+            grid = (grid * 255).astype(np.uint8)
+            filename = "{}_gs-{:06}_e-{:06}_b-{:06}.png".format(
+                k,
+                global_step,
+                current_epoch,
+                batch_idx)
+            path = os.path.join(root, filename)
+            os.makedirs(os.path.split(path)[0], exist_ok=True)
+            Image.fromarray(grid).save(path)
+
+    def log_img(self, pl_module, batch, batch_idx, split="train"):
+        check_idx = batch_idx if self.log_on_batch_idx else pl_module.global_step
+        if (self.check_frequency(check_idx) and  # batch_idx % self.batch_freq == 0
+                hasattr(pl_module, "log_images") and
+                callable(pl_module.log_images) and
+                self.max_images > 0):
+            logger = type(pl_module.logger)
+
+            is_train = pl_module.training
+            if is_train:
+                pl_module.eval()
+
+            with torch.no_grad():
+                images = pl_module.log_images(batch, split=split, **self.log_images_kwargs)
+
+            for k in images:
+                N = min(images[k].shape[0], self.max_images)
+                images[k] = images[k][:N]
+                if isinstance(images[k], torch.Tensor):
+                    images[k] = images[k].detach().cpu()
+                    if self.clamp:
+                        images[k] = torch.clamp(images[k], -1., 1.)
+
+            self.log_local(pl_module.logger.save_dir, split, images,
+                           pl_module.global_step, pl_module.current_epoch, batch_idx)
+
+            logger_log_images = self.logger_log_images.get(logger, lambda *args, **kwargs: None)
+            logger_log_images(pl_module, images, pl_module.global_step, split)
+
+            if is_train:
+                pl_module.train()
+
+    def check_frequency(self, check_idx):
+        if ((check_idx % self.batch_freq) == 0 or (check_idx in self.log_steps)) and (
+                check_idx > 0 or self.log_first_step):
+            try:
+                self.log_steps.pop(0)
+            except IndexError as e:
+                print(e)
+                pass
+            return True
+        return False
+
+    def on_train_batch_end(self, trainer, pl_module, outputs, batch, batch_idx, dataloader_idx):
+        if not self.disabled and (pl_module.global_step > 0 or self.log_first_step):
+            self.log_img(pl_module, batch, batch_idx, split="train")
+
+    def on_validation_batch_end(self, trainer, pl_module, outputs, batch, batch_idx, dataloader_idx):
+        if not self.disabled and pl_module.global_step > 0:
+            self.log_img(pl_module, batch, batch_idx, split="val")
+        if hasattr(pl_module, 'calibrate_grad_norm'):
+            if (pl_module.calibrate_grad_norm and batch_idx % 25 == 0) and batch_idx > 0:
+                self.log_gradients(trainer, pl_module, batch_idx=batch_idx)
+
+
+class CUDACallback(Callback):
+    # see https://github.com/SeanNaren/minGPT/blob/master/mingpt/callback.py
+    def on_train_epoch_start(self, trainer, pl_module):
+        # Reset the memory use counter
+        torch.cuda.reset_peak_memory_stats(trainer.root_gpu)
+        torch.cuda.synchronize(trainer.root_gpu)
+        self.start_time = time.time()
+
+    def on_train_epoch_end(self, trainer, pl_module, outputs):
+        torch.cuda.synchronize(trainer.root_gpu)
+        max_memory = torch.cuda.max_memory_allocated(trainer.root_gpu) / 2 ** 20
+        epoch_time = time.time() - self.start_time
+
+        try:
+            max_memory = trainer.training_type_plugin.reduce(max_memory)
+            epoch_time = trainer.training_type_plugin.reduce(epoch_time)
+
+            rank_zero_info(f"Average Epoch time: {epoch_time:.2f} seconds")
+            rank_zero_info(f"Average Peak memory {max_memory:.2f}MiB")
+        except AttributeError:
+            pass
+
+
+if __name__ == "__main__":
+    # custom parser to specify config files, train, test and debug mode,
+    # postfix, resume.
+    # `--key value` arguments are interpreted as arguments to the trainer.
+    # `nested.key=value` arguments are interpreted as config parameters.
+    # configs are merged from left-to-right followed by command line parameters.
+
+    # model:
+    #   base_learning_rate: float
+    #   target: path to lightning module
+    #   params:
+    #       key: value
+    # data:
+    #   target: main.DataModuleFromConfig
+    #   params:
+    #      batch_size: int
+    #      wrap: bool
+    #      train:
+    #          target: path to train dataset
+    #          params:
+    #              key: value
+    #      validation:
+    #          target: path to validation dataset
+    #          params:
+    #              key: value
+    #      test:
+    #          target: path to test dataset
+    #          params:
+    #              key: value
+    # lightning: (optional, has sane defaults and can be specified on cmdline)
+    #   trainer:
+    #       additional arguments to trainer
+    #   logger:
+    #       logger to instantiate
+    #   modelcheckpoint:
+    #       modelcheckpoint to instantiate
+    #   callbacks:
+    #       callback1:
+    #           target: importpath
+    #           params:
+    #               key: value
+
+    now = datetime.datetime.now().strftime("%Y-%m-%dT%H-%M-%S")
+
+    # add cwd for convenience and to make classes in this file available when
+    # running as `python main.py`
+    # (in particular `main.DataModuleFromConfig`)
+    sys.path.append(os.getcwd())
+
+    parser = get_parser()
+    parser = Trainer.add_argparse_args(parser)
+
+    opt, unknown = parser.parse_known_args()
+    if opt.name and opt.resume:
+        raise ValueError(
+            "-n/--name and -r/--resume cannot be specified both."
+            "If you want to resume training in a new log folder, "
+            "use -n/--name in combination with --resume_from_checkpoint"
+        )
+    if opt.resume:
+        if not os.path.exists(opt.resume):
+            raise ValueError("Cannot find {}".format(opt.resume))
+        if os.path.isfile(opt.resume):
+            paths = opt.resume.split("/")
+            # idx = len(paths)-paths[::-1].index("logs")+1
+            # logdir = "/".join(paths[:idx])
+            logdir = "/".join(paths[:-2])
+            ckpt = opt.resume
+        else:
+            assert os.path.isdir(opt.resume), opt.resume
+            logdir = opt.resume.rstrip("/")
+            ckpt = os.path.join(logdir, "checkpoints", "last.ckpt")
+
+        opt.resume_from_checkpoint = ckpt
+        base_configs = sorted(glob.glob(os.path.join(logdir, "configs/*.yaml")))
+        opt.base = base_configs + opt.base
+        _tmp = logdir.split("/")
+        nowname = _tmp[-1]
+    else:
+        if opt.name:
+            name = "_" + opt.name
+        elif opt.base:
+            cfg_fname = os.path.split(opt.base[0])[-1]
+            cfg_name = os.path.splitext(cfg_fname)[0]
+            name = "_" + cfg_name
+        else:
+            name = ""
+        nowname = now + name + opt.postfix
+        logdir = os.path.join(opt.logdir, nowname)
+
+    ckptdir = os.path.join(logdir, "checkpoints")
+    cfgdir = os.path.join(logdir, "configs")
+    seed_everything(opt.seed)
+
+    try:
+        # init and save configs
+        configs = [OmegaConf.load(cfg) for cfg in opt.base]
+        cli = OmegaConf.from_dotlist(unknown)
+        config = OmegaConf.merge(*configs, cli)
+        lightning_config = config.pop("lightning", OmegaConf.create())
+        # merge trainer cli with config
+        trainer_config = lightning_config.get("trainer", OmegaConf.create())
+        # default to ddp
+        trainer_config["accelerator"] = "ddp"
+        for k in nondefault_trainer_args(opt):
+            trainer_config[k] = getattr(opt, k)
+        if not "gpus" in trainer_config:
+            del trainer_config["accelerator"]
+            cpu = True
+        else:
+            gpuinfo = trainer_config["gpus"]
+            print(f"Running on GPUs {gpuinfo}")
+            cpu = False
+        trainer_opt = argparse.Namespace(**trainer_config)
+        lightning_config.trainer = trainer_config
+
+        # model
+        model = instantiate_from_config(config.model)
+
+        # trainer and callbacks
+        trainer_kwargs = dict()
+
+        # default logger configs
+        default_logger_cfgs = {
+            "wandb": {
+                "target": "pytorch_lightning.loggers.WandbLogger",
+                "params": {
+                    "name": nowname,
+                    "save_dir": logdir,
+                    "offline": opt.debug,
+                    "id": nowname,
+                }
+            },
+            "testtube": {
+                "target": "pytorch_lightning.loggers.TestTubeLogger",
+                "params": {
+                    "name": "testtube",
+                    "save_dir": logdir,
+                }
+            },
+        }
+        default_logger_cfg = default_logger_cfgs["testtube"]
+        if "logger" in lightning_config:
+            logger_cfg = lightning_config.logger
+        else:
+            logger_cfg = OmegaConf.create()
+        logger_cfg = OmegaConf.merge(default_logger_cfg, logger_cfg)
+        trainer_kwargs["logger"] = instantiate_from_config(logger_cfg)
+
+        # modelcheckpoint - use TrainResult/EvalResult(checkpoint_on=metric) to
+        # specify which metric is used to determine best models
+        default_modelckpt_cfg = {
+            "target": "pytorch_lightning.callbacks.ModelCheckpoint",
+            "params": {
+                "dirpath": ckptdir,
+                "filename": "{epoch:06}",
+                "verbose": True,
+                "save_last": True,
+            }
+        }
+        if hasattr(model, "monitor"):
+            print(f"Monitoring {model.monitor} as checkpoint metric.")
+            default_modelckpt_cfg["params"]["monitor"] = model.monitor
+            default_modelckpt_cfg["params"]["save_top_k"] = 3
+
+        if "modelcheckpoint" in lightning_config:
+            modelckpt_cfg = lightning_config.modelcheckpoint
+        else:
+            modelckpt_cfg =  OmegaConf.create()
+        modelckpt_cfg = OmegaConf.merge(default_modelckpt_cfg, modelckpt_cfg)
+        print(f"Merged modelckpt-cfg: \n{modelckpt_cfg}")
+        if version.parse(pl.__version__) < version.parse('1.4.0'):
+            trainer_kwargs["checkpoint_callback"] = instantiate_from_config(modelckpt_cfg)
+
+        # add callback which sets up log directory
+        default_callbacks_cfg = {
+            "setup_callback": {
+                "target": "main.SetupCallback",
+                "params": {
+                    "resume": opt.resume,
+                    "now": now,
+                    "logdir": logdir,
+                    "ckptdir": ckptdir,
+                    "cfgdir": cfgdir,
+                    "config": config,
+                    "lightning_config": lightning_config,
+                }
+            },
+            "image_logger": {
+                "target": "main.ImageLogger",
+                "params": {
+                    "batch_frequency": 750,
+                    "max_images": 4,
+                    "clamp": True
+                }
+            },
+            "learning_rate_logger": {
+                "target": "main.LearningRateMonitor",
+                "params": {
+                    "logging_interval": "step",
+                    # "log_momentum": True
+                }
+            },
+            "cuda_callback": {
+                "target": "main.CUDACallback"
+            },
+        }
+        if version.parse(pl.__version__) >= version.parse('1.4.0'):
+            default_callbacks_cfg.update({'checkpoint_callback': modelckpt_cfg})
+
+        if "callbacks" in lightning_config:
+            callbacks_cfg = lightning_config.callbacks
+        else:
+            callbacks_cfg = OmegaConf.create()
+
+        if 'metrics_over_trainsteps_checkpoint' in callbacks_cfg:
+            print(
+                'Caution: Saving checkpoints every n train steps without deleting. This might require some free space.')
+            default_metrics_over_trainsteps_ckpt_dict = {
+                'metrics_over_trainsteps_checkpoint':
+                    {"target": 'pytorch_lightning.callbacks.ModelCheckpoint',
+                     'params': {
+                         "dirpath": os.path.join(ckptdir, 'trainstep_checkpoints'),
+                         "filename": "{epoch:06}-{step:09}",
+                         "verbose": True,
+                         'save_top_k': -1,
+                         'every_n_train_steps': 10000,
+                         'save_weights_only': True
+                     }
+                     }
+            }
+            default_callbacks_cfg.update(default_metrics_over_trainsteps_ckpt_dict)
+
+        callbacks_cfg = OmegaConf.merge(default_callbacks_cfg, callbacks_cfg)
+        if 'ignore_keys_callback' in callbacks_cfg and hasattr(trainer_opt, 'resume_from_checkpoint'):
+            callbacks_cfg.ignore_keys_callback.params['ckpt_path'] = trainer_opt.resume_from_checkpoint
+        elif 'ignore_keys_callback' in callbacks_cfg:
+            del callbacks_cfg['ignore_keys_callback']
+
+        trainer_kwargs["callbacks"] = [instantiate_from_config(callbacks_cfg[k]) for k in callbacks_cfg]
+
+        trainer = Trainer.from_argparse_args(trainer_opt, **trainer_kwargs)
+        trainer.logdir = logdir  ###
+
+        # data
+        data = instantiate_from_config(config.data)
+        # NOTE according to https://pytorch-lightning.readthedocs.io/en/latest/datamodules.html
+        # calling these ourselves should not be necessary but it is.
+        # lightning still takes care of proper multiprocessing though
+        data.prepare_data()
+        data.setup()
+        print("#### Data #####")
+        for k in data.datasets:
+            print(f"{k}, {data.datasets[k].__class__.__name__}, {len(data.datasets[k])}")
+
+        # configure learning rate
+        bs, base_lr = config.data.params.batch_size, config.model.base_learning_rate
+        if not cpu:
+            ngpu = len(lightning_config.trainer.gpus.strip(",").split(','))
+        else:
+            ngpu = 1
+        accumulate_grad_batches = lightning_config.trainer.accumulate_grad_batches or 1
+        print(f"accumulate_grad_batches = {accumulate_grad_batches}")
+        lightning_config.trainer.accumulate_grad_batches = accumulate_grad_batches
+        if opt.scale_lr:
+            model.learning_rate = accumulate_grad_batches * ngpu * bs * base_lr
+            print(
+                "Setting learning rate to {:.2e} = {} (accumulate_grad_batches) * {} (num_gpus) * {} (batchsize) * {:.2e} (base_lr)".format(
+                    model.learning_rate, accumulate_grad_batches, ngpu, bs, base_lr))
+        else:
+            model.learning_rate = base_lr
+            print("++++ NOT USING LR SCALING ++++")
+            print(f"Setting learning rate to {model.learning_rate:.2e}")
+
+
+        # allow checkpointing via USR1
+        def melk(*args, **kwargs):
+            # run all checkpoint hooks
+            if trainer.global_rank == 0:
+                print("Summoning checkpoint.")
+                ckpt_path = os.path.join(ckptdir, "last.ckpt")
+                trainer.save_checkpoint(ckpt_path)
+
+
+        def divein(*args, **kwargs):
+            if trainer.global_rank == 0:
+                import pudb;
+                pudb.set_trace()
+
+
+        import signal
+
+        signal.signal(signal.SIGUSR1, melk)
+        signal.signal(signal.SIGUSR2, divein)
+
+        # run
+        if opt.train:
+            try:
+                trainer.fit(model, data)
+            except Exception:
+                melk()
+                raise
+        if not opt.no_test and not trainer.interrupted:
+            trainer.test(model, data)
+    except Exception:
+        if opt.debug and trainer.global_rank == 0:
+            try:
+                import pudb as debugger
+            except ImportError:
+                import pdb as debugger
+            debugger.post_mortem()
+        raise
+    finally:
+        # move newly created debug project to debug_runs
+        if opt.debug and not opt.resume and trainer.global_rank == 0:
+            dst, name = os.path.split(logdir)
+            dst = os.path.join(dst, "debug_runs", name)
+            os.makedirs(os.path.split(dst)[0], exist_ok=True)
+            os.rename(logdir, dst)
+        if trainer.global_rank == 0:
+            print(trainer.profiler.summary())

+ 44 - 0
models/first_stage_models/kl-f16/config.yaml

@@ -0,0 +1,44 @@
+model:
+  base_learning_rate: 4.5e-06
+  target: ldm.models.autoencoder.AutoencoderKL
+  params:
+    monitor: val/rec_loss
+    embed_dim: 16
+    lossconfig:
+      target: ldm.modules.losses.LPIPSWithDiscriminator
+      params:
+        disc_start: 50001
+        kl_weight: 1.0e-06
+        disc_weight: 0.5
+    ddconfig:
+      double_z: true
+      z_channels: 16
+      resolution: 256
+      in_channels: 3
+      out_ch: 3
+      ch: 128
+      ch_mult:
+      - 1
+      - 1
+      - 2
+      - 2
+      - 4
+      num_res_blocks: 2
+      attn_resolutions:
+      - 16
+      dropout: 0.0
+data:
+  target: main.DataModuleFromConfig
+  params:
+    batch_size: 6
+    wrap: true
+    train:
+      target: ldm.data.openimages.FullOpenImagesTrain
+      params:
+        size: 384
+        crop_size: 256
+    validation:
+      target: ldm.data.openimages.FullOpenImagesValidation
+      params:
+        size: 384
+        crop_size: 256

+ 46 - 0
models/first_stage_models/kl-f32/config.yaml

@@ -0,0 +1,46 @@
+model:
+  base_learning_rate: 4.5e-06
+  target: ldm.models.autoencoder.AutoencoderKL
+  params:
+    monitor: val/rec_loss
+    embed_dim: 64
+    lossconfig:
+      target: ldm.modules.losses.LPIPSWithDiscriminator
+      params:
+        disc_start: 50001
+        kl_weight: 1.0e-06
+        disc_weight: 0.5
+    ddconfig:
+      double_z: true
+      z_channels: 64
+      resolution: 256
+      in_channels: 3
+      out_ch: 3
+      ch: 128
+      ch_mult:
+      - 1
+      - 1
+      - 2
+      - 2
+      - 4
+      - 4
+      num_res_blocks: 2
+      attn_resolutions:
+      - 16
+      - 8
+      dropout: 0.0
+data:
+  target: main.DataModuleFromConfig
+  params:
+    batch_size: 6
+    wrap: true
+    train:
+      target: ldm.data.openimages.FullOpenImagesTrain
+      params:
+        size: 384
+        crop_size: 256
+    validation:
+      target: ldm.data.openimages.FullOpenImagesValidation
+      params:
+        size: 384
+        crop_size: 256

+ 41 - 0
models/first_stage_models/kl-f4/config.yaml

@@ -0,0 +1,41 @@
+model:
+  base_learning_rate: 4.5e-06
+  target: ldm.models.autoencoder.AutoencoderKL
+  params:
+    monitor: val/rec_loss
+    embed_dim: 3
+    lossconfig:
+      target: ldm.modules.losses.LPIPSWithDiscriminator
+      params:
+        disc_start: 50001
+        kl_weight: 1.0e-06
+        disc_weight: 0.5
+    ddconfig:
+      double_z: true
+      z_channels: 3
+      resolution: 256
+      in_channels: 3
+      out_ch: 3
+      ch: 128
+      ch_mult:
+      - 1
+      - 2
+      - 4
+      num_res_blocks: 2
+      attn_resolutions: []
+      dropout: 0.0
+data:
+  target: main.DataModuleFromConfig
+  params:
+    batch_size: 10
+    wrap: true
+    train:
+      target: ldm.data.openimages.FullOpenImagesTrain
+      params:
+        size: 384
+        crop_size: 256
+    validation:
+      target: ldm.data.openimages.FullOpenImagesValidation
+      params:
+        size: 384
+        crop_size: 256

+ 42 - 0
models/first_stage_models/kl-f8/config.yaml

@@ -0,0 +1,42 @@
+model:
+  base_learning_rate: 4.5e-06
+  target: ldm.models.autoencoder.AutoencoderKL
+  params:
+    monitor: val/rec_loss
+    embed_dim: 4
+    lossconfig:
+      target: ldm.modules.losses.LPIPSWithDiscriminator
+      params:
+        disc_start: 50001
+        kl_weight: 1.0e-06
+        disc_weight: 0.5
+    ddconfig:
+      double_z: true
+      z_channels: 4
+      resolution: 256
+      in_channels: 3
+      out_ch: 3
+      ch: 128
+      ch_mult:
+      - 1
+      - 2
+      - 4
+      - 4
+      num_res_blocks: 2
+      attn_resolutions: []
+      dropout: 0.0
+data:
+  target: main.DataModuleFromConfig
+  params:
+    batch_size: 4
+    wrap: true
+    train:
+      target: ldm.data.openimages.FullOpenImagesTrain
+      params:
+        size: 384
+        crop_size: 256
+    validation:
+      target: ldm.data.openimages.FullOpenImagesValidation
+      params:
+        size: 384
+        crop_size: 256

+ 49 - 0
models/first_stage_models/vq-f16/config.yaml

@@ -0,0 +1,49 @@
+model:
+  base_learning_rate: 4.5e-06
+  target: ldm.models.autoencoder.VQModel
+  params:
+    embed_dim: 8
+    n_embed: 16384
+    ddconfig:
+      double_z: false
+      z_channels: 8
+      resolution: 256
+      in_channels: 3
+      out_ch: 3
+      ch: 128
+      ch_mult:
+      - 1
+      - 1
+      - 2
+      - 2
+      - 4
+      num_res_blocks: 2
+      attn_resolutions:
+      - 16
+      dropout: 0.0
+    lossconfig:
+      target: taming.modules.losses.vqperceptual.VQLPIPSWithDiscriminator
+      params:
+        disc_conditional: false
+        disc_in_channels: 3
+        disc_start: 250001
+        disc_weight: 0.75
+        disc_num_layers: 2
+        codebook_weight: 1.0
+
+data:
+  target: main.DataModuleFromConfig
+  params:
+    batch_size: 14
+    num_workers: 20
+    wrap: true
+    train:
+      target: ldm.data.openimages.FullOpenImagesTrain
+      params:
+        size: 384
+        crop_size: 256
+    validation:
+      target: ldm.data.openimages.FullOpenImagesValidation
+      params:
+        size: 384
+        crop_size: 256

+ 46 - 0
models/first_stage_models/vq-f4-noattn/config.yaml

@@ -0,0 +1,46 @@
+model:
+  base_learning_rate: 4.5e-06
+  target: ldm.models.autoencoder.VQModel
+  params:
+    embed_dim: 3
+    n_embed: 8192
+    monitor: val/rec_loss
+
+    ddconfig:
+      attn_type: none
+      double_z: false
+      z_channels: 3
+      resolution: 256
+      in_channels: 3
+      out_ch: 3
+      ch: 128
+      ch_mult:
+      - 1
+      - 2
+      - 4
+      num_res_blocks: 2
+      attn_resolutions: []
+      dropout: 0.0
+    lossconfig:
+      target: taming.modules.losses.vqperceptual.VQLPIPSWithDiscriminator
+      params:
+        disc_conditional: false
+        disc_in_channels: 3
+        disc_start: 11
+        disc_weight: 0.75
+        codebook_weight: 1.0
+
+data:
+  target: main.DataModuleFromConfig
+  params:
+    batch_size: 8
+    num_workers: 12
+    wrap: true
+    train:
+      target: ldm.data.openimages.FullOpenImagesTrain
+      params:
+        crop_size: 256
+    validation:
+      target: ldm.data.openimages.FullOpenImagesValidation
+      params:
+        crop_size: 256

+ 45 - 0
models/first_stage_models/vq-f4/config.yaml

@@ -0,0 +1,45 @@
+model:
+  base_learning_rate: 4.5e-06
+  target: ldm.models.autoencoder.VQModel
+  params:
+    embed_dim: 3
+    n_embed: 8192
+    monitor: val/rec_loss
+
+    ddconfig:
+      double_z: false
+      z_channels: 3
+      resolution: 256
+      in_channels: 3
+      out_ch: 3
+      ch: 128
+      ch_mult:
+      - 1
+      - 2
+      - 4
+      num_res_blocks: 2
+      attn_resolutions: []
+      dropout: 0.0
+    lossconfig:
+      target: taming.modules.losses.vqperceptual.VQLPIPSWithDiscriminator
+      params:
+        disc_conditional: false
+        disc_in_channels: 3
+        disc_start: 0
+        disc_weight: 0.75
+        codebook_weight: 1.0
+
+data:
+  target: main.DataModuleFromConfig
+  params:
+    batch_size: 8
+    num_workers: 16
+    wrap: true
+    train:
+      target: ldm.data.openimages.FullOpenImagesTrain
+      params:
+        crop_size: 256
+    validation:
+      target: ldm.data.openimages.FullOpenImagesValidation
+      params:
+        crop_size: 256

+ 48 - 0
models/first_stage_models/vq-f8-n256/config.yaml

@@ -0,0 +1,48 @@
+model:
+  base_learning_rate: 4.5e-06
+  target: ldm.models.autoencoder.VQModel
+  params:
+    embed_dim: 4
+    n_embed: 256
+    monitor: val/rec_loss
+    ddconfig:
+      double_z: false
+      z_channels: 4
+      resolution: 256
+      in_channels: 3
+      out_ch: 3
+      ch: 128
+      ch_mult:
+      - 1
+      - 2
+      - 2
+      - 4
+      num_res_blocks: 2
+      attn_resolutions:
+      - 32
+      dropout: 0.0
+    lossconfig:
+      target: taming.modules.losses.vqperceptual.VQLPIPSWithDiscriminator
+      params:
+        disc_conditional: false
+        disc_in_channels: 3
+        disc_start: 250001
+        disc_weight: 0.75
+        codebook_weight: 1.0
+
+data:
+  target: main.DataModuleFromConfig
+  params:
+    batch_size: 10
+    num_workers: 20
+    wrap: true
+    train:
+      target: ldm.data.openimages.FullOpenImagesTrain
+      params:
+        size: 384
+        crop_size: 256
+    validation:
+      target: ldm.data.openimages.FullOpenImagesValidation
+      params:
+        size: 384
+        crop_size: 256

+ 48 - 0
models/first_stage_models/vq-f8/config.yaml

@@ -0,0 +1,48 @@
+model:
+  base_learning_rate: 4.5e-06
+  target: ldm.models.autoencoder.VQModel
+  params:
+    embed_dim: 4
+    n_embed: 16384
+    monitor: val/rec_loss
+    ddconfig:
+      double_z: false
+      z_channels: 4
+      resolution: 256
+      in_channels: 3
+      out_ch: 3
+      ch: 128
+      ch_mult:
+      - 1
+      - 2
+      - 2
+      - 4
+      num_res_blocks: 2
+      attn_resolutions:
+      - 32
+      dropout: 0.0
+    lossconfig:
+      target: taming.modules.losses.vqperceptual.VQLPIPSWithDiscriminator
+      params:
+        disc_conditional: false
+        disc_in_channels: 3
+        disc_num_layers: 2
+        disc_start: 1
+        disc_weight: 0.6
+        codebook_weight: 1.0
+data:
+  target: main.DataModuleFromConfig
+  params:
+    batch_size: 10
+    num_workers: 20
+    wrap: true
+    train:
+      target: ldm.data.openimages.FullOpenImagesTrain
+      params:
+        size: 384
+        crop_size: 256
+    validation:
+      target: ldm.data.openimages.FullOpenImagesValidation
+      params:
+        size: 384
+        crop_size: 256

+ 80 - 0
models/ldm/bsr_sr/config.yaml

@@ -0,0 +1,80 @@
+model:
+  base_learning_rate: 1.0e-06
+  target: ldm.models.diffusion.ddpm.LatentDiffusion
+  params:
+    linear_start: 0.0015
+    linear_end: 0.0155
+    log_every_t: 100
+    timesteps: 1000
+    loss_type: l2
+    first_stage_key: image
+    cond_stage_key: LR_image
+    image_size: 64
+    channels: 3
+    concat_mode: true
+    cond_stage_trainable: false
+    unet_config:
+      target: ldm.modules.diffusionmodules.openaimodel.UNetModel
+      params:
+        image_size: 64
+        in_channels: 6
+        out_channels: 3
+        model_channels: 160
+        attention_resolutions:
+        - 16
+        - 8
+        num_res_blocks: 2
+        channel_mult:
+        - 1
+        - 2
+        - 2
+        - 4
+        num_head_channels: 32
+    first_stage_config:
+      target: ldm.models.autoencoder.VQModelInterface
+      params:
+        embed_dim: 3
+        n_embed: 8192
+        monitor: val/rec_loss
+        ddconfig:
+          double_z: false
+          z_channels: 3
+          resolution: 256
+          in_channels: 3
+          out_ch: 3
+          ch: 128
+          ch_mult:
+          - 1
+          - 2
+          - 4
+          num_res_blocks: 2
+          attn_resolutions: []
+          dropout: 0.0
+        lossconfig:
+          target: torch.nn.Identity
+    cond_stage_config:
+      target: torch.nn.Identity
+data:
+  target: main.DataModuleFromConfig
+  params:
+    batch_size: 64
+    wrap: false
+    num_workers: 12
+    train:
+      target: ldm.data.openimages.SuperresOpenImagesAdvancedTrain
+      params:
+        size: 256
+        degradation: bsrgan_light
+        downscale_f: 4
+        min_crop_f: 0.5
+        max_crop_f: 1.0
+        random_crop: true
+    validation:
+      target: ldm.data.openimages.SuperresOpenImagesAdvancedValidation
+      params:
+        size: 256
+        degradation: bsrgan_light
+        downscale_f: 4
+        min_crop_f: 0.5
+        max_crop_f: 1.0
+        random_crop: true

+ 70 - 0
models/ldm/celeba256/config.yaml

@@ -0,0 +1,70 @@
+model:
+  base_learning_rate: 2.0e-06
+  target: ldm.models.diffusion.ddpm.LatentDiffusion
+  params:
+    linear_start: 0.0015
+    linear_end: 0.0195
+    num_timesteps_cond: 1
+    log_every_t: 200
+    timesteps: 1000
+    first_stage_key: image
+    cond_stage_key: class_label
+    image_size: 64
+    channels: 3
+    cond_stage_trainable: false
+    concat_mode: false
+    monitor: val/loss
+    unet_config:
+      target: ldm.modules.diffusionmodules.openaimodel.UNetModel
+      params:
+        image_size: 64
+        in_channels: 3
+        out_channels: 3
+        model_channels: 224
+        attention_resolutions:
+        - 8
+        - 4
+        - 2
+        num_res_blocks: 2
+        channel_mult:
+        - 1
+        - 2
+        - 3
+        - 4
+        num_head_channels: 32
+    first_stage_config:
+      target: ldm.models.autoencoder.VQModelInterface
+      params:
+        embed_dim: 3
+        n_embed: 8192
+        ddconfig:
+          double_z: false
+          z_channels: 3
+          resolution: 256
+          in_channels: 3
+          out_ch: 3
+          ch: 128
+          ch_mult:
+          - 1
+          - 2
+          - 4
+          num_res_blocks: 2
+          attn_resolutions: []
+          dropout: 0.0
+        lossconfig:
+          target: torch.nn.Identity
+    cond_stage_config: __is_unconditional__
+data:
+  target: main.DataModuleFromConfig
+  params:
+    batch_size: 48
+    num_workers: 5
+    wrap: false
+    train:
+      target: ldm.data.faceshq.CelebAHQTrain
+      params:
+        size: 256
+    validation:
+      target: ldm.data.faceshq.CelebAHQValidation
+      params:
+        size: 256

+ 80 - 0
models/ldm/cin256/config.yaml

@@ -0,0 +1,80 @@
+model:
+  base_learning_rate: 1.0e-06
+  target: ldm.models.diffusion.ddpm.LatentDiffusion
+  params:
+    linear_start: 0.0015
+    linear_end: 0.0195
+    num_timesteps_cond: 1
+    log_every_t: 200
+    timesteps: 1000
+    first_stage_key: image
+    cond_stage_key: class_label
+    image_size: 32
+    channels: 4
+    cond_stage_trainable: true
+    conditioning_key: crossattn
+    monitor: val/loss_simple_ema
+    unet_config:
+      target: ldm.modules.diffusionmodules.openaimodel.UNetModel
+      params:
+        image_size: 32
+        in_channels: 4
+        out_channels: 4
+        model_channels: 256
+        attention_resolutions:
+        - 4
+        - 2
+        - 1
+        num_res_blocks: 2
+        channel_mult:
+        - 1
+        - 2
+        - 4
+        num_head_channels: 32
+        use_spatial_transformer: true
+        transformer_depth: 1
+        context_dim: 512
+    first_stage_config:
+      target: ldm.models.autoencoder.VQModelInterface
+      params:
+        embed_dim: 4
+        n_embed: 16384
+        ddconfig:
+          double_z: false
+          z_channels: 4
+          resolution: 256
+          in_channels: 3
+          out_ch: 3
+          ch: 128
+          ch_mult:
+          - 1
+          - 2
+          - 2
+          - 4
+          num_res_blocks: 2
+          attn_resolutions:
+          - 32
+          dropout: 0.0
+        lossconfig:
+          target: torch.nn.Identity
+    cond_stage_config:
+      target: ldm.modules.encoders.modules.ClassEmbedder
+      params:
+        embed_dim: 512
+        key: class_label
+data:
+  target: main.DataModuleFromConfig
+  params:
+    batch_size: 64
+    num_workers: 12
+    wrap: false
+    train:
+      target: ldm.data.imagenet.ImageNetTrain
+      params:
+        config:
+          size: 256
+    validation:
+      target: ldm.data.imagenet.ImageNetValidation
+      params:
+        config:
+          size: 256

+ 70 - 0
models/ldm/ffhq256/config.yaml

@@ -0,0 +1,70 @@
+model:
+  base_learning_rate: 2.0e-06
+  target: ldm.models.diffusion.ddpm.LatentDiffusion
+  params:
+    linear_start: 0.0015
+    linear_end: 0.0195
+    num_timesteps_cond: 1
+    log_every_t: 200
+    timesteps: 1000
+    first_stage_key: image
+    cond_stage_key: class_label
+    image_size: 64
+    channels: 3
+    cond_stage_trainable: false
+    concat_mode: false
+    monitor: val/loss
+    unet_config:
+      target: ldm.modules.diffusionmodules.openaimodel.UNetModel
+      params:
+        image_size: 64
+        in_channels: 3
+        out_channels: 3
+        model_channels: 224
+        attention_resolutions:
+        - 8
+        - 4
+        - 2
+        num_res_blocks: 2
+        channel_mult:
+        - 1
+        - 2
+        - 3
+        - 4
+        num_head_channels: 32
+    first_stage_config:
+      target: ldm.models.autoencoder.VQModelInterface
+      params:
+        embed_dim: 3
+        n_embed: 8192
+        ddconfig:
+          double_z: false
+          z_channels: 3
+          resolution: 256
+          in_channels: 3
+          out_ch: 3
+          ch: 128
+          ch_mult:
+          - 1
+          - 2
+          - 4
+          num_res_blocks: 2
+          attn_resolutions: []
+          dropout: 0.0
+        lossconfig:
+          target: torch.nn.Identity
+    cond_stage_config: __is_unconditional__
+data:
+  target: main.DataModuleFromConfig
+  params:
+    batch_size: 42
+    num_workers: 5
+    wrap: false
+    train:
+      target: ldm.data.faceshq.FFHQTrain
+      params:
+        size: 256
+    validation:
+      target: ldm.data.faceshq.FFHQValidation
+      params:
+        size: 256

+ 67 - 0
models/ldm/inpainting_big/config.yaml

@@ -0,0 +1,67 @@
+model:
+  base_learning_rate: 1.0e-06
+  target: ldm.models.diffusion.ddpm.LatentDiffusion
+  params:
+    linear_start: 0.0015
+    linear_end: 0.0205
+    log_every_t: 100
+    timesteps: 1000
+    loss_type: l1
+    first_stage_key: image
+    cond_stage_key: masked_image
+    image_size: 64
+    channels: 3
+    concat_mode: true
+    monitor: val/loss
+    scheduler_config:
+      target: ldm.lr_scheduler.LambdaWarmUpCosineScheduler
+      params:
+        verbosity_interval: 0
+        warm_up_steps: 1000
+        max_decay_steps: 50000
+        lr_start: 0.001
+        lr_max: 0.1
+        lr_min: 0.0001
+    unet_config:
+      target: ldm.modules.diffusionmodules.openaimodel.UNetModel
+      params:
+        image_size: 64
+        in_channels: 7
+        out_channels: 3
+        model_channels: 256
+        attention_resolutions:
+        - 8
+        - 4
+        - 2
+        num_res_blocks: 2
+        channel_mult:
+        - 1
+        - 2
+        - 3
+        - 4
+        num_heads: 8
+        resblock_updown: true
+    first_stage_config:
+      target: ldm.models.autoencoder.VQModelInterface
+      params:
+        embed_dim: 3
+        n_embed: 8192
+        monitor: val/rec_loss
+        ddconfig:
+          attn_type: none
+          double_z: false
+          z_channels: 3
+          resolution: 256
+          in_channels: 3
+          out_ch: 3
+          ch: 128
+          ch_mult:
+          - 1
+          - 2
+          - 4
+          num_res_blocks: 2
+          attn_resolutions: []
+          dropout: 0.0
+        lossconfig:
+          target: ldm.modules.losses.contperceptual.DummyLoss
+    cond_stage_config: __is_first_stage__

+ 81 - 0
models/ldm/layout2img-openimages256/config.yaml

@@ -0,0 +1,81 @@
+model:
+  base_learning_rate: 2.0e-06
+  target: ldm.models.diffusion.ddpm.LatentDiffusion
+  params:
+    linear_start: 0.0015
+    linear_end: 0.0205
+    log_every_t: 100
+    timesteps: 1000
+    loss_type: l1
+    first_stage_key: image
+    cond_stage_key: coordinates_bbox
+    image_size: 64
+    channels: 3
+    conditioning_key: crossattn
+    cond_stage_trainable: true
+    unet_config:
+      target: ldm.modules.diffusionmodules.openaimodel.UNetModel
+      params:
+        image_size: 64
+        in_channels: 3
+        out_channels: 3
+        model_channels: 128
+        attention_resolutions:
+        - 8
+        - 4
+        - 2
+        num_res_blocks: 2
+        channel_mult:
+        - 1
+        - 2
+        - 3
+        - 4
+        num_head_channels: 32
+        use_spatial_transformer: true
+        transformer_depth: 3
+        context_dim: 512
+    first_stage_config:
+      target: ldm.models.autoencoder.VQModelInterface
+      params:
+        embed_dim: 3
+        n_embed: 8192
+        monitor: val/rec_loss
+        ddconfig:
+          double_z: false
+          z_channels: 3
+          resolution: 256
+          in_channels: 3
+          out_ch: 3
+          ch: 128
+          ch_mult:
+          - 1
+          - 2
+          - 4
+          num_res_blocks: 2
+          attn_resolutions: []
+          dropout: 0.0
+        lossconfig:
+          target: torch.nn.Identity
+    cond_stage_config:
+      target: ldm.modules.encoders.modules.BERTEmbedder
+      params:
+        n_embed: 512
+        n_layer: 16
+        vocab_size: 8192
+        max_seq_len: 92
+        use_tokenizer: false
+    monitor: val/loss_simple_ema
+data:
+  target: main.DataModuleFromConfig
+  params:
+    batch_size: 24
+    wrap: false
+    num_workers: 10
+    train:
+      target: ldm.data.openimages.OpenImagesBBoxTrain
+      params:
+        size: 256
+    validation:
+      target: ldm.data.openimages.OpenImagesBBoxValidation
+      params:
+        size: 256

+ 70 - 0
models/ldm/lsun_beds256/config.yaml

@@ -0,0 +1,70 @@
+model:
+  base_learning_rate: 2.0e-06
+  target: ldm.models.diffusion.ddpm.LatentDiffusion
+  params:
+    linear_start: 0.0015
+    linear_end: 0.0195
+    num_timesteps_cond: 1
+    log_every_t: 200
+    timesteps: 1000
+    first_stage_key: image
+    cond_stage_key: class_label
+    image_size: 64
+    channels: 3
+    cond_stage_trainable: false
+    concat_mode: false
+    monitor: val/loss
+    unet_config:
+      target: ldm.modules.diffusionmodules.openaimodel.UNetModel
+      params:
+        image_size: 64
+        in_channels: 3
+        out_channels: 3
+        model_channels: 224
+        attention_resolutions:
+        - 8
+        - 4
+        - 2
+        num_res_blocks: 2
+        channel_mult:
+        - 1
+        - 2
+        - 3
+        - 4
+        num_head_channels: 32
+    first_stage_config:
+      target: ldm.models.autoencoder.VQModelInterface
+      params:
+        embed_dim: 3
+        n_embed: 8192
+        ddconfig:
+          double_z: false
+          z_channels: 3
+          resolution: 256
+          in_channels: 3
+          out_ch: 3
+          ch: 128
+          ch_mult:
+          - 1
+          - 2
+          - 4
+          num_res_blocks: 2
+          attn_resolutions: []
+          dropout: 0.0
+        lossconfig:
+          target: torch.nn.Identity
+    cond_stage_config: __is_unconditional__
+data:
+  target: main.DataModuleFromConfig
+  params:
+    batch_size: 48
+    num_workers: 5
+    wrap: false
+    train:
+      target: ldm.data.lsun.LSUNBedroomsTrain
+      params:
+        size: 256
+    validation:
+      target: ldm.data.lsun.LSUNBedroomsValidation
+      params:
+        size: 256

+ 92 - 0
models/ldm/lsun_churches256/config.yaml

@@ -0,0 +1,92 @@
+model:
+  base_learning_rate: 5.0e-05
+  target: ldm.models.diffusion.ddpm.LatentDiffusion
+  params:
+    linear_start: 0.0015
+    linear_end: 0.0155
+    num_timesteps_cond: 1
+    log_every_t: 200
+    timesteps: 1000
+    loss_type: l1
+    first_stage_key: image
+    cond_stage_key: image
+    image_size: 32
+    channels: 4
+    cond_stage_trainable: false
+    concat_mode: false
+    scale_by_std: true
+    monitor: val/loss_simple_ema
+    scheduler_config:
+      target: ldm.lr_scheduler.LambdaLinearScheduler
+      params:
+        warm_up_steps:
+        - 10000
+        cycle_lengths:
+        - 10000000000000
+        f_start:
+        - 1.0e-06
+        f_max:
+        - 1.0
+        f_min:
+        - 1.0
+    unet_config:
+      target: ldm.modules.diffusionmodules.openaimodel.UNetModel
+      params:
+        image_size: 32
+        in_channels: 4
+        out_channels: 4
+        model_channels: 192
+        attention_resolutions:
+        - 1
+        - 2
+        - 4
+        - 8
+        num_res_blocks: 2
+        channel_mult:
+        - 1
+        - 2
+        - 2
+        - 4
+        - 4
+        num_heads: 8
+        use_scale_shift_norm: true
+        resblock_updown: true
+    first_stage_config:
+      target: ldm.models.autoencoder.AutoencoderKL
+      params:
+        embed_dim: 4
+        monitor: val/rec_loss
+        ddconfig:
+          double_z: true
+          z_channels: 4
+          resolution: 256
+          in_channels: 3
+          out_ch: 3
+          ch: 128
+          ch_mult:
+          - 1
+          - 2
+          - 4
+          - 4
+          num_res_blocks: 2
+          attn_resolutions: []
+          dropout: 0.0
+        lossconfig:
+          target: torch.nn.Identity
+
+    cond_stage_config: '__is_unconditional__'
+
+data:
+  target: main.DataModuleFromConfig
+  params:
+    batch_size: 96
+    num_workers: 5
+    wrap: false
+    train:
+      target: ldm.data.lsun.LSUNChurchesTrain
+      params:
+        size: 256
+    validation:
+      target: ldm.data.lsun.LSUNChurchesValidation
+      params:
+        size: 256

+ 78 - 0
models/ldm/semantic_synthesis512/config.yaml

@@ -0,0 +1,78 @@
+model:
+  base_learning_rate: 1.0e-06
+  target: ldm.models.diffusion.ddpm.LatentDiffusion
+  params:
+    linear_start: 0.0015
+    linear_end: 0.0205
+    log_every_t: 100
+    timesteps: 1000
+    loss_type: l1
+    first_stage_key: image
+    cond_stage_key: segmentation
+    image_size: 128
+    channels: 3
+    concat_mode: true
+    cond_stage_trainable: true
+    unet_config:
+      target: ldm.modules.diffusionmodules.openaimodel.UNetModel
+      params:
+        image_size: 128
+        in_channels: 6
+        out_channels: 3
+        model_channels: 128
+        attention_resolutions:
+        - 32
+        - 16
+        - 8
+        num_res_blocks: 2
+        channel_mult:
+        - 1
+        - 4
+        - 8
+        num_heads: 8
+    first_stage_config:
+      target: ldm.models.autoencoder.VQModelInterface
+      params:
+        embed_dim: 3
+        n_embed: 8192
+        monitor: val/rec_loss
+        ddconfig:
+          double_z: false
+          z_channels: 3
+          resolution: 256
+          in_channels: 3
+          out_ch: 3
+          ch: 128
+          ch_mult:
+          - 1
+          - 2
+          - 4
+          num_res_blocks: 2
+          attn_resolutions: []
+          dropout: 0.0
+        lossconfig:
+          target: torch.nn.Identity
+    cond_stage_config:
+      target: ldm.modules.encoders.modules.SpatialRescaler
+      params:
+        n_stages: 2
+        in_channels: 182
+        out_channels: 3
+data:
+  target: main.DataModuleFromConfig
+  params:
+    batch_size: 8
+    wrap: false
+    num_workers: 10
+    train:
+      target: ldm.data.landscapes.RFWTrain
+      params:
+        size: 768
+        crop_size: 512
+        segmentation_to_float32: true
+    validation:
+      target: ldm.data.landscapes.RFWValidation
+      params:
+        size: 768
+        crop_size: 512
+        segmentation_to_float32: true

+ 77 - 0
models/ldm/text2img256/config.yaml

@@ -0,0 +1,77 @@
+model:
+  base_learning_rate: 2.0e-06
+  target: ldm.models.diffusion.ddpm.LatentDiffusion
+  params:
+    linear_start: 0.0015
+    linear_end: 0.0195
+    num_timesteps_cond: 1
+    log_every_t: 200
+    timesteps: 1000
+    first_stage_key: image
+    cond_stage_key: caption
+    image_size: 64
+    channels: 3
+    cond_stage_trainable: true
+    conditioning_key: crossattn
+    monitor: val/loss_simple_ema
+    unet_config:
+      target: ldm.modules.diffusionmodules.openaimodel.UNetModel
+      params:
+        image_size: 64
+        in_channels: 3
+        out_channels: 3
+        model_channels: 192
+        attention_resolutions:
+        - 8
+        - 4
+        - 2
+        num_res_blocks: 2
+        channel_mult:
+        - 1
+        - 2
+        - 3
+        - 5
+        num_head_channels: 32
+        use_spatial_transformer: true
+        transformer_depth: 1
+        context_dim: 640
+    first_stage_config:
+      target: ldm.models.autoencoder.VQModelInterface
+      params:
+        embed_dim: 3
+        n_embed: 8192
+        ddconfig:
+          double_z: false
+          z_channels: 3
+          resolution: 256
+          in_channels: 3
+          out_ch: 3
+          ch: 128
+          ch_mult:
+          - 1
+          - 2
+          - 4
+          num_res_blocks: 2
+          attn_resolutions: []
+          dropout: 0.0
+        lossconfig:
+          target: torch.nn.Identity
+    cond_stage_config:
+      target: ldm.modules.encoders.modules.BERTEmbedder
+      params:
+        n_embed: 640
+        n_layer: 32
+data:
+  target: main.DataModuleFromConfig
+  params:
+    batch_size: 28
+    num_workers: 10
+    wrap: false
+    train:
+      target: ldm.data.previews.pytorch_dataset.PreviewsTrain
+      params:
+        size: 256
+    validation:
+      target: ldm.data.previews.pytorch_dataset.PreviewsValidation
+      params:
+        size: 256

+ 270 - 0
notebook_helpers.py

@@ -0,0 +1,270 @@
+from torchvision.datasets.utils import download_url
+from ldm.util import instantiate_from_config
+import torch
+import os
+# todo ?
+from google.colab import files
+from IPython.display import Image as ipyimg
+import ipywidgets as widgets
+from PIL import Image
+from numpy import asarray
+from einops import rearrange, repeat
+import torch, torchvision
+from ldm.models.diffusion.ddim import DDIMSampler
+from ldm.util import ismap
+import time
+from omegaconf import OmegaConf
+
+
+def download_models(mode):
+
+    if mode == "superresolution":
+        # this is the small bsr light model
+        url_conf = 'https://heibox.uni-heidelberg.de/f/31a76b13ea27482981b4/?dl=1'
+        url_ckpt = 'https://heibox.uni-heidelberg.de/f/578df07c8fc04ffbadf3/?dl=1'
+
+        path_conf = 'logs/diffusion/superresolution_bsr/configs/project.yaml'
+        path_ckpt = 'logs/diffusion/superresolution_bsr/checkpoints/last.ckpt'
+
+        download_url(url_conf, path_conf)
+        download_url(url_ckpt, path_ckpt)
+
+        path_conf = path_conf + '/?dl=1' # fix it
+        path_ckpt = path_ckpt + '/?dl=1' # fix it
+        return path_conf, path_ckpt
+
+    else:
+        raise NotImplementedError
+
+
+def load_model_from_config(config, ckpt):
+    print(f"Loading model from {ckpt}")
+    pl_sd = torch.load(ckpt, map_location="cpu")
+    global_step = pl_sd["global_step"]
+    sd = pl_sd["state_dict"]
+    model = instantiate_from_config(config.model)
+    m, u = model.load_state_dict(sd, strict=False)
+    model.cuda()
+    model.eval()
+    return {"model": model}, global_step
+
+
+def get_model(mode):
+    path_conf, path_ckpt = download_models(mode)
+    config = OmegaConf.load(path_conf)
+    model, step = load_model_from_config(config, path_ckpt)
+    return model
+
+
+def get_custom_cond(mode):
+    dest = "data/example_conditioning"
+
+    if mode == "superresolution":
+        uploaded_img = files.upload()
+        filename = next(iter(uploaded_img))
+        name, filetype = filename.split(".") # todo assumes just one dot in name !
+        os.rename(f"{filename}", f"{dest}/{mode}/custom_{name}.{filetype}")
+
+    elif mode == "text_conditional":
+        w = widgets.Text(value='A cake with cream!', disabled=True)
+        display(w)
+
+        with open(f"{dest}/{mode}/custom_{w.value[:20]}.txt", 'w') as f:
+            f.write(w.value)
+
+    elif mode == "class_conditional":
+        w = widgets.IntSlider(min=0, max=1000)
+        display(w)
+        with open(f"{dest}/{mode}/custom.txt", 'w') as f:
+            f.write(w.value)
+
+    else:
+        raise NotImplementedError(f"cond not implemented for mode{mode}")
+
+
+def get_cond_options(mode):
+    path = "data/example_conditioning"
+    path = os.path.join(path, mode)
+    onlyfiles = [f for f in sorted(os.listdir(path))]
+    return path, onlyfiles
+
+
+def select_cond_path(mode):
+    path = "data/example_conditioning"  # todo
+    path = os.path.join(path, mode)
+    onlyfiles = [f for f in sorted(os.listdir(path))]
+
+    selected = widgets.RadioButtons(
+        options=onlyfiles,
+        description='Select conditioning:',
+        disabled=False
+    )
+    display(selected)
+    selected_path = os.path.join(path, selected.value)
+    return selected_path
+
+
+def get_cond(mode, selected_path):
+    example = dict()
+    if mode == "superresolution":
+        up_f = 4
+        visualize_cond_img(selected_path)
+
+        c = Image.open(selected_path)
+        c = torch.unsqueeze(torchvision.transforms.ToTensor()(c), 0)
+        c_up = torchvision.transforms.functional.resize(c, size=[up_f * c.shape[2], up_f * c.shape[3]], antialias=True)
+        c_up = rearrange(c_up, '1 c h w -> 1 h w c')
+        c = rearrange(c, '1 c h w -> 1 h w c')
+        c = 2. * c - 1.
+
+        c = c.to(torch.device("cuda"))
+        example["LR_image"] = c
+        example["image"] = c_up
+
+    return example
+
+
+def visualize_cond_img(path):
+    display(ipyimg(filename=path))
+
+
+def run(model, selected_path, task, custom_steps, resize_enabled=False, classifier_ckpt=None, global_step=None):
+
+    example = get_cond(task, selected_path)
+
+    save_intermediate_vid = False
+    n_runs = 1
+    masked = False
+    guider = None
+    ckwargs = None
+    mode = 'ddim'
+    ddim_use_x0_pred = False
+    temperature = 1.
+    eta = 1.
+    make_progrow = True
+    custom_shape = None
+
+    height, width = example["image"].shape[1:3]
+    split_input = height >= 128 and width >= 128
+
+    if split_input:
+        ks = 128
+        stride = 64
+        vqf = 4  #
+        model.split_input_params = {"ks": (ks, ks), "stride": (stride, stride),
+                                    "vqf": vqf,
+                                    "patch_distributed_vq": True,
+                                    "tie_braker": False,
+                                    "clip_max_weight": 0.5,
+                                    "clip_min_weight": 0.01,
+                                    "clip_max_tie_weight": 0.5,
+                                    "clip_min_tie_weight": 0.01}
+    else:
+        if hasattr(model, "split_input_params"):
+            delattr(model, "split_input_params")
+
+    invert_mask = False
+
+    x_T = None
+    for n in range(n_runs):
+        if custom_shape is not None:
+            x_T = torch.randn(1, custom_shape[1], custom_shape[2], custom_shape[3]).to(model.device)
+            x_T = repeat(x_T, '1 c h w -> b c h w', b=custom_shape[0])
+
+        logs = make_convolutional_sample(example, model,
+                                         mode=mode, custom_steps=custom_steps,
+                                         eta=eta, swap_mode=False , masked=masked,
+                                         invert_mask=invert_mask, quantize_x0=False,
+                                         custom_schedule=None, decode_interval=10,
+                                         resize_enabled=resize_enabled, custom_shape=custom_shape,
+                                         temperature=temperature, noise_dropout=0.,
+                                         corrector=guider, corrector_kwargs=ckwargs, x_T=x_T, save_intermediate_vid=save_intermediate_vid,
+                                         make_progrow=make_progrow,ddim_use_x0_pred=ddim_use_x0_pred
+                                         )
+    return logs
+
+
+@torch.no_grad()
+def convsample_ddim(model, cond, steps, shape, eta=1.0, callback=None, normals_sequence=None,
+                    mask=None, x0=None, quantize_x0=False, img_callback=None,
+                    temperature=1., noise_dropout=0., score_corrector=None,
+                    corrector_kwargs=None, x_T=None, log_every_t=None
+                    ):
+
+    ddim = DDIMSampler(model)
+    bs = shape[0]  # dont know where this comes from but wayne
+    shape = shape[1:]  # cut batch dim
+    print(f"Sampling with eta = {eta}; steps: {steps}")
+    samples, intermediates = ddim.sample(steps, batch_size=bs, shape=shape, conditioning=cond, callback=callback,
+                                         normals_sequence=normals_sequence, quantize_x0=quantize_x0, eta=eta,
+                                         mask=mask, x0=x0, temperature=temperature, verbose=False,
+                                         score_corrector=score_corrector,
+                                         corrector_kwargs=corrector_kwargs, x_T=x_T)
+
+    return samples, intermediates
+
+
+@torch.no_grad()
+def make_convolutional_sample(batch, model, mode="vanilla", custom_steps=None, eta=1.0, swap_mode=False, masked=False,
+                              invert_mask=True, quantize_x0=False, custom_schedule=None, decode_interval=1000,
+                              resize_enabled=False, custom_shape=None, temperature=1., noise_dropout=0., corrector=None,
+                              corrector_kwargs=None, x_T=None, save_intermediate_vid=False, make_progrow=True,ddim_use_x0_pred=False):
+    log = dict()
+
+    z, c, x, xrec, xc = model.get_input(batch, model.first_stage_key,
+                                        return_first_stage_outputs=True,
+                                        force_c_encode=not (hasattr(model, 'split_input_params')
+                                                            and model.cond_stage_key == 'coordinates_bbox'),
+                                        return_original_cond=True)
+
+    log_every_t = 1 if save_intermediate_vid else None
+
+    if custom_shape is not None:
+        z = torch.randn(custom_shape)
+        print(f"Generating {custom_shape[0]} samples of shape {custom_shape[1:]}")
+
+    z0 = None
+
+    log["input"] = x
+    log["reconstruction"] = xrec
+
+    if ismap(xc):
+        log["original_conditioning"] = model.to_rgb(xc)
+        if hasattr(model, 'cond_stage_key'):
+            log[model.cond_stage_key] = model.to_rgb(xc)
+
+    else:
+        log["original_conditioning"] = xc if xc is not None else torch.zeros_like(x)
+        if model.cond_stage_model:
+            log[model.cond_stage_key] = xc if xc is not None else torch.zeros_like(x)
+            if model.cond_stage_key =='class_label':
+                log[model.cond_stage_key] = xc[model.cond_stage_key]
+
+    with model.ema_scope("Plotting"):
+        t0 = time.time()
+        img_cb = None
+
+        sample, intermediates = convsample_ddim(model, c, steps=custom_steps, shape=z.shape,
+                                                eta=eta,
+                                                quantize_x0=quantize_x0, img_callback=img_cb, mask=None, x0=z0,
+                                                temperature=temperature, noise_dropout=noise_dropout,
+                                                score_corrector=corrector, corrector_kwargs=corrector_kwargs,
+                                                x_T=x_T, log_every_t=log_every_t)
+        t1 = time.time()
+
+        if ddim_use_x0_pred:
+            sample = intermediates['pred_x0'][-1]
+
+    x_sample = model.decode_first_stage(sample)
+
+    try:
+        x_sample_noquant = model.decode_first_stage(sample, force_not_quantize=True)
+        log["sample_noquant"] = x_sample_noquant
+        log["sample_diff"] = torch.abs(x_sample_noquant - x_sample)
+    except:
+        pass
+
+    log["sample"] = x_sample
+    log["time"] = t1 - t0
+
+    return log

+ 41 - 0
scripts/download_first_stages.sh

@@ -0,0 +1,41 @@
+#!/bin/bash
+wget -O models/first_stage_models/kl-f4/model.zip https://ommer-lab.com/files/latent-diffusion/kl-f4.zip
+wget -O models/first_stage_models/kl-f8/model.zip https://ommer-lab.com/files/latent-diffusion/kl-f8.zip
+wget -O models/first_stage_models/kl-f16/model.zip https://ommer-lab.com/files/latent-diffusion/kl-f16.zip
+wget -O models/first_stage_models/kl-f32/model.zip https://ommer-lab.com/files/latent-diffusion/kl-f32.zip
+wget -O models/first_stage_models/vq-f4/model.zip https://ommer-lab.com/files/latent-diffusion/vq-f4.zip
+wget -O models/first_stage_models/vq-f4-noattn/model.zip https://heibox.uni-heidelberg.de/f/9c6681f64bb94338a069/?dl=1
+wget -O models/first_stage_models/vq-f8/model.zip https://ommer-lab.com/files/latent-diffusion/vq-f8.zip
+wget -O models/first_stage_models/vq-f8-n256/model.zip https://ommer-lab.com/files/latent-diffusion/vq-f8-n256.zip
+wget -O models/first_stage_models/vq-f16/model.zip https://heibox.uni-heidelberg.de/f/0e42b04e2e904890a9b6/?dl=1
+
+
+
+cd models/first_stage_models/kl-f4
+unzip -o model.zip
+
+cd ../kl-f8
+unzip -o model.zip
+
+cd ../kl-f16
+unzip -o model.zip
+
+cd ../kl-f32
+unzip -o model.zip
+
+cd ../vq-f4
+unzip -o model.zip
+
+cd ../vq-f4-noattn
+unzip -o model.zip
+
+cd ../vq-f8
+unzip -o model.zip
+
+cd ../vq-f8-n256
+unzip -o model.zip
+
+cd ../vq-f16
+unzip -o model.zip
+
+cd ../..

+ 45 - 0
scripts/download_models.sh

@@ -0,0 +1,45 @@
+#!/bin/bash
+wget -O models/ldm/celeba256/celeba-256.zip https://ommer-lab.com/files/latent-diffusion/celeba.zip
+wget -O models/ldm/ffhq256/ffhq-256.zip https://ommer-lab.com/files/latent-diffusion/ffhq.zip
+wget -O models/ldm/lsun_churches256/lsun_churches-256.zip https://ommer-lab.com/files/latent-diffusion/lsun_churches.zip
+wget -O models/ldm/lsun_beds256/lsun_beds-256.zip https://ommer-lab.com/files/latent-diffusion/lsun_bedrooms.zip
+wget -O models/ldm/text2img256/model.zip https://ommer-lab.com/files/latent-diffusion/text2img.zip
+wget -O models/ldm/cin256/model.zip https://ommer-lab.com/files/latent-diffusion/cin.zip
+wget -O models/ldm/semantic_synthesis512/model.zip https://ommer-lab.com/files/latent-diffusion/semantic_synthesis.zip
+wget -O models/ldm/bsr_sr/model.zip https://ommer-lab.com/files/latent-diffusion/sr_bsr.zip
+wget -O models/ldm/layout2img-openimages256/model.zip https://ommer-lab.com/files/latent-diffusion/layout2img_model.zip
+wget -O models/ldm/inpainting_big/model.zip #TODO @patrick add path
+
+
+
+cd models/ldm/celeba256
+unzip -o celeba-256.zip
+
+cd ../ffhq256
+unzip -o ffhq-256.zip
+
+cd ../lsun_churches256
+unzip -o lsun_churches-256.zip
+
+cd ../lsun_beds256
+unzip -o lsun_beds-256.zip
+
+cd ../text2img256
+unzip -o model.zip
+
+cd ../cin256
+unzip -o model.zip
+
+cd ../semantic_synthesis512
+unzip -o model.zip
+
+cd ../bsr_sr
+unzip -o model.zip
+
+cd ../layout2img-openimages256
+unzip -o model.zip
+
+cd ../inpainting_big
+unzip -o model.zip
+
+cd ../..

+ 98 - 0
scripts/inpaint.py

@@ -0,0 +1,98 @@
+import argparse, os, sys, glob
+from omegaconf import OmegaConf
+from PIL import Image
+from tqdm import tqdm
+import numpy as np
+import torch
+from main import instantiate_from_config
+from ldm.models.diffusion.ddim import DDIMSampler
+
+
+def make_batch(image, mask, device):
+    image = np.array(Image.open(image).convert("RGB"))
+    image = image.astype(np.float32)/255.0
+    image = image[None].transpose(0,3,1,2)
+    image = torch.from_numpy(image)
+
+    mask = np.array(Image.open(mask).convert("L"))
+    mask = mask.astype(np.float32)/255.0
+    mask = mask[None,None]
+    mask[mask < 0.5] = 0
+    mask[mask >= 0.5] = 1
+    mask = torch.from_numpy(mask)
+
+    masked_image = (1-mask)*image
+
+    batch = {"image": image, "mask": mask, "masked_image": masked_image}
+    for k in batch:
+        batch[k] = batch[k].to(device=device)
+        batch[k] = batch[k]*2.0-1.0
+    return batch
+
+
+if __name__ == "__main__":
+    parser = argparse.ArgumentParser()
+    parser.add_argument(
+        "--indir",
+        type=str,
+        nargs="?",
+        help="dir containing image-mask pairs (`example.png` and `example_mask.png`)",
+    )
+    parser.add_argument(
+        "--outdir",
+        type=str,
+        nargs="?",
+        help="dir to write results to",
+    )
+    parser.add_argument(
+        "--steps",
+        type=int,
+        default=50,
+        help="number of ddim sampling steps",
+    )
+    opt = parser.parse_args()
+
+    masks = sorted(glob.glob(os.path.join(opt.indir, "*_mask.png")))
+    images = [x.replace("_mask.png", ".png") for x in masks]
+    print(f"Found {len(masks)} inputs.")
+
+    config = OmegaConf.load("models/ldm/inpainting_big/config.yaml")
+    model = instantiate_from_config(config.model)
+    model.load_state_dict(torch.load("models/ldm/inpainting_big/last.ckpt")["state_dict"],
+                          strict=False)
+
+    device = torch.device("cuda") if torch.cuda.is_available() else torch.device("cpu")
+    model = model.to(device)
+    sampler = DDIMSampler(model)
+
+    os.makedirs(opt.outdir, exist_ok=True)
+    with torch.no_grad():
+        with model.ema_scope():
+            for image, mask in tqdm(zip(images, masks)):
+                outpath = os.path.join(opt.outdir, os.path.split(image)[1])
+                batch = make_batch(image, mask, device=device)
+
+                # encode masked image and concat downsampled mask
+                c = model.cond_stage_model.encode(batch["masked_image"])
+                cc = torch.nn.functional.interpolate(batch["mask"],
+                                                     size=c.shape[-2:])
+                c = torch.cat((c, cc), dim=1)
+
+                shape = (c.shape[1]-1,)+c.shape[2:]
+                samples_ddim, _ = sampler.sample(S=opt.steps,
+                                                 conditioning=c,
+                                                 batch_size=c.shape[0],
+                                                 shape=shape,
+                                                 verbose=False)
+                x_samples_ddim = model.decode_first_stage(samples_ddim)
+
+                image = torch.clamp((batch["image"]+1.0)/2.0,
+                                    min=0.0, max=1.0)
+                mask = torch.clamp((batch["mask"]+1.0)/2.0,
+                                   min=0.0, max=1.0)
+                predicted_image = torch.clamp((x_samples_ddim+1.0)/2.0,
+                                              min=0.0, max=1.0)
+
+                inpainted = (1-mask)*image+mask*predicted_image
+                inpainted = inpainted.cpu().numpy().transpose(0,2,3,1)[0]*255
+                Image.fromarray(inpainted.astype(np.uint8)).save(outpath)

+ 313 - 0
scripts/sample_diffusion.py

@@ -0,0 +1,313 @@
+import argparse, os, sys, glob, datetime, yaml
+import torch
+import time
+import numpy as np
+from tqdm import trange
+
+from omegaconf import OmegaConf
+from PIL import Image
+
+from ldm.models.diffusion.ddim import DDIMSampler
+from ldm.util import instantiate_from_config
+
+rescale = lambda x: (x + 1.) / 2.
+
+def custom_to_pil(x):
+    x = x.detach().cpu()
+    x = torch.clamp(x, -1., 1.)
+    x = (x + 1.) / 2.
+    x = x.permute(1, 2, 0).numpy()
+    x = (255 * x).astype(np.uint8)
+    x = Image.fromarray(x)
+    if not x.mode == "RGB":
+        x = x.convert("RGB")
+    return x
+
+
+def custom_to_np(x):
+    # saves the batch in adm style as in https://github.com/openai/guided-diffusion/blob/main/scripts/image_sample.py
+    sample = x.detach().cpu()
+    sample = ((sample + 1) * 127.5).clamp(0, 255).to(torch.uint8)
+    sample = sample.permute(0, 2, 3, 1)
+    sample = sample.contiguous()
+    return sample
+
+
+def logs2pil(logs, keys=["sample"]):
+    imgs = dict()
+    for k in logs:
+        try:
+            if len(logs[k].shape) == 4:
+                img = custom_to_pil(logs[k][0, ...])
+            elif len(logs[k].shape) == 3:
+                img = custom_to_pil(logs[k])
+            else:
+                print(f"Unknown format for key {k}. ")
+                img = None
+        except:
+            img = None
+        imgs[k] = img
+    return imgs
+
+
+@torch.no_grad()
+def convsample(model, shape, return_intermediates=True,
+               verbose=True,
+               make_prog_row=False):
+
+
+    if not make_prog_row:
+        return model.p_sample_loop(None, shape,
+                                   return_intermediates=return_intermediates, verbose=verbose)
+    else:
+        return model.progressive_denoising(
+            None, shape, verbose=True
+        )
+
+
+@torch.no_grad()
+def convsample_ddim(model, steps, shape, eta=1.0
+                    ):
+    ddim = DDIMSampler(model)
+    bs = shape[0]
+    shape = shape[1:]
+    samples, intermediates = ddim.sample(steps, batch_size=bs, shape=shape, eta=eta, verbose=False,)
+    return samples, intermediates
+
+
+@torch.no_grad()
+def make_convolutional_sample(model, batch_size, vanilla=False, custom_steps=None, eta=1.0,):
+
+
+    log = dict()
+
+    shape = [batch_size,
+             model.model.diffusion_model.in_channels,
+             model.model.diffusion_model.image_size,
+             model.model.diffusion_model.image_size]
+
+    with model.ema_scope("Plotting"):
+        t0 = time.time()
+        if vanilla:
+            sample, progrow = convsample(model, shape,
+                                         make_prog_row=True)
+        else:
+            sample, intermediates = convsample_ddim(model,  steps=custom_steps, shape=shape,
+                                                    eta=eta)
+
+        t1 = time.time()
+
+    x_sample = model.decode_first_stage(sample)
+
+    log["sample"] = x_sample
+    log["time"] = t1 - t0
+    log['throughput'] = sample.shape[0] / (t1 - t0)
+    print(f'Throughput for this batch: {log["throughput"]}')
+    return log
+
+def run(model, logdir, batch_size=50, vanilla=False, custom_steps=None, eta=None, n_samples=50000, nplog=None):
+    if vanilla:
+        print(f'Using Vanilla DDPM sampling with {model.num_timesteps} sampling steps.')
+    else:
+        print(f'Using DDIM sampling with {custom_steps} sampling steps and eta={eta}')
+
+
+    tstart = time.time()
+    n_saved = len(glob.glob(os.path.join(logdir,'*.png')))-1
+    # path = logdir
+    if model.cond_stage_model is None:
+        all_images = []
+
+        print(f"Running unconditional sampling for {n_samples} samples")
+        for _ in trange(n_samples // batch_size, desc="Sampling Batches (unconditional)"):
+            logs = make_convolutional_sample(model, batch_size=batch_size,
+                                             vanilla=vanilla, custom_steps=custom_steps,
+                                             eta=eta)
+            n_saved = save_logs(logs, logdir, n_saved=n_saved, key="sample")
+            all_images.extend([custom_to_np(logs["sample"])])
+            if n_saved >= n_samples:
+                print(f'Finish after generating {n_saved} samples')
+                break
+        all_img = np.concatenate(all_images, axis=0)
+        all_img = all_img[:n_samples]
+        shape_str = "x".join([str(x) for x in all_img.shape])
+        nppath = os.path.join(nplog, f"{shape_str}-samples.npz")
+        np.savez(nppath, all_img)
+
+    else:
+       raise NotImplementedError('Currently only sampling for unconditional models supported.')
+
+    print(f"sampling of {n_saved} images finished in {(time.time() - tstart) / 60.:.2f} minutes.")
+
+
+def save_logs(logs, path, n_saved=0, key="sample", np_path=None):
+    for k in logs:
+        if k == key:
+            batch = logs[key]
+            if np_path is None:
+                for x in batch:
+                    img = custom_to_pil(x)
+                    imgpath = os.path.join(path, f"{key}_{n_saved:06}.png")
+                    img.save(imgpath)
+                    n_saved += 1
+            else:
+                npbatch = custom_to_np(batch)
+                shape_str = "x".join([str(x) for x in npbatch.shape])
+                nppath = os.path.join(np_path, f"{n_saved}-{shape_str}-samples.npz")
+                np.savez(nppath, npbatch)
+                n_saved += npbatch.shape[0]
+    return n_saved
+
+
+def get_parser():
+    parser = argparse.ArgumentParser()
+    parser.add_argument(
+        "-r",
+        "--resume",
+        type=str,
+        nargs="?",
+        help="load from logdir or checkpoint in logdir",
+    )
+    parser.add_argument(
+        "-n",
+        "--n_samples",
+        type=int,
+        nargs="?",
+        help="number of samples to draw",
+        default=50000
+    )
+    parser.add_argument(
+        "-e",
+        "--eta",
+        type=float,
+        nargs="?",
+        help="eta for ddim sampling (0.0 yields deterministic sampling)",
+        default=1.0
+    )
+    parser.add_argument(
+        "-v",
+        "--vanilla_sample",
+        default=False,
+        action='store_true',
+        help="vanilla sampling (default option is DDIM sampling)?",
+    )
+    parser.add_argument(
+        "-l",
+        "--logdir",
+        type=str,
+        nargs="?",
+        help="extra logdir",
+        default="none"
+    )
+    parser.add_argument(
+        "-c",
+        "--custom_steps",
+        type=int,
+        nargs="?",
+        help="number of steps for ddim and fastdpm sampling",
+        default=50
+    )
+    parser.add_argument(
+        "--batch_size",
+        type=int,
+        nargs="?",
+        help="the bs",
+        default=10
+    )
+    return parser
+
+
+def load_model_from_config(config, sd):
+    model = instantiate_from_config(config)
+    model.load_state_dict(sd,strict=False)
+    model.cuda()
+    model.eval()
+    return model
+
+
+def load_model(config, ckpt, gpu, eval_mode):
+    if ckpt:
+        print(f"Loading model from {ckpt}")
+        pl_sd = torch.load(ckpt, map_location="cpu")
+        global_step = pl_sd["global_step"]
+    else:
+        pl_sd = {"state_dict": None}
+        global_step = None
+    model = load_model_from_config(config.model,
+                                   pl_sd["state_dict"])
+
+    return model, global_step
+
+
+if __name__ == "__main__":
+    now = datetime.datetime.now().strftime("%Y-%m-%d-%H-%M-%S")
+    sys.path.append(os.getcwd())
+    command = " ".join(sys.argv)
+
+    parser = get_parser()
+    opt, unknown = parser.parse_known_args()
+    ckpt = None
+
+    if not os.path.exists(opt.resume):
+        raise ValueError("Cannot find {}".format(opt.resume))
+    if os.path.isfile(opt.resume):
+        # paths = opt.resume.split("/")
+        try:
+            logdir = '/'.join(opt.resume.split('/')[:-1])
+            # idx = len(paths)-paths[::-1].index("logs")+1
+            print(f'Logdir is {logdir}')
+        except ValueError:
+            paths = opt.resume.split("/")
+            idx = -2  # take a guess: path/to/logdir/checkpoints/model.ckpt
+            logdir = "/".join(paths[:idx])
+        ckpt = opt.resume
+    else:
+        assert os.path.isdir(opt.resume), f"{opt.resume} is not a directory"
+        logdir = opt.resume.rstrip("/")
+        ckpt = os.path.join(logdir, "model.ckpt")
+
+    base_configs = sorted(glob.glob(os.path.join(logdir, "config.yaml")))
+    opt.base = base_configs
+
+    configs = [OmegaConf.load(cfg) for cfg in opt.base]
+    cli = OmegaConf.from_dotlist(unknown)
+    config = OmegaConf.merge(*configs, cli)
+
+    gpu = True
+    eval_mode = True
+
+    if opt.logdir != "none":
+        locallog = logdir.split(os.sep)[-1]
+        if locallog == "": locallog = logdir.split(os.sep)[-2]
+        print(f"Switching logdir from '{logdir}' to '{os.path.join(opt.logdir, locallog)}'")
+        logdir = os.path.join(opt.logdir, locallog)
+
+    print(config)
+
+    model, global_step = load_model(config, ckpt, gpu, eval_mode)
+    print(f"global step: {global_step}")
+    print(75 * "=")
+    print("logging to:")
+    logdir = os.path.join(logdir, "samples", f"{global_step:08}", now)
+    imglogdir = os.path.join(logdir, "img")
+    numpylogdir = os.path.join(logdir, "numpy")
+
+    os.makedirs(imglogdir)
+    os.makedirs(numpylogdir)
+    print(logdir)
+    print(75 * "=")
+
+    # write config out
+    sampling_file = os.path.join(logdir, "sampling_config.yaml")
+    sampling_conf = vars(opt)
+
+    with open(sampling_file, 'w') as f:
+        yaml.dump(sampling_conf, f, default_flow_style=False)
+    print(sampling_conf)
+
+
+    run(model, imglogdir, eta=opt.eta,
+        vanilla=opt.vanilla_sample,  n_samples=opt.n_samples, custom_steps=opt.custom_steps,
+        batch_size=opt.batch_size, nplog=numpylogdir)
+
+    print("done.")

+ 13 - 0
setup.py

@@ -0,0 +1,13 @@
+from setuptools import setup, find_packages
+
+setup(
+    name='latent-diffusion',
+    version='0.0.1',
+    description='',
+    packages=find_packages(),
+    install_requires=[
+        'torch',
+        'numpy',
+        'tqdm',
+    ],
+)