|
@@ -7,10 +7,8 @@
|
|
|
[Dominik Lorenz](https://github.com/qp-qp)\,
|
|
[Dominik Lorenz](https://github.com/qp-qp)\,
|
|
|
[Patrick Esser](https://github.com/pesser),
|
|
[Patrick Esser](https://github.com/pesser),
|
|
|
[Björn Ommer](https://hci.iwr.uni-heidelberg.de/Staff/bommer)<br/>
|
|
[Björn Ommer](https://hci.iwr.uni-heidelberg.de/Staff/bommer)<br/>
|
|
|
-
|
|
|
|
|
-**CVPR '22 Oral**
|
|
|
|
|
-
|
|
|
|
|
-which is available on [GitHub](https://github.com/CompVis/latent-diffusion). PDF at [arXiv](https://arxiv.org/abs/2112.10752). Please also visit our [Project page](https://ommer-lab.com/research/latent-diffusion-models/).
|
|
|
|
|
|
|
+_[CVPR '22 Oral](https://openaccess.thecvf.com/content/CVPR2022/html/Rombach_High-Resolution_Image_Synthesis_With_Latent_Diffusion_Models_CVPR_2022_paper.html) |
|
|
|
|
|
+[GitHub](https://github.com/CompVis/latent-diffusion) | [arXiv](https://arxiv.org/abs/2112.10752) | [Project page](https://ommer-lab.com/research/latent-diffusion-models/)_
|
|
|
|
|
|
|
|

|
|

|
|
|
[Stable Diffusion](#stable-diffusion-v1) is a latent text-to-image diffusion
|
|
[Stable Diffusion](#stable-diffusion-v1) is a latent text-to-image diffusion
|
|
@@ -35,7 +33,7 @@ You can also update an existing [latent diffusion](https://github.com/CompVis/la
|
|
|
|
|
|
|
|
```
|
|
```
|
|
|
conda install pytorch torchvision -c pytorch
|
|
conda install pytorch torchvision -c pytorch
|
|
|
-pip install transformers==4.19.2
|
|
|
|
|
|
|
+pip install transformers==4.19.2 diffusers invisible-watermark
|
|
|
pip install -e .
|
|
pip install -e .
|
|
|
```
|
|
```
|
|
|
|
|
|
|
@@ -49,23 +47,23 @@ then finetuned on 512x512 images.
|
|
|
|
|
|
|
|
*Note: Stable Diffusion v1 is a general text-to-image diffusion model and therefore mirrors biases and (mis-)conceptions that are present
|
|
*Note: Stable Diffusion v1 is a general text-to-image diffusion model and therefore mirrors biases and (mis-)conceptions that are present
|
|
|
in its training data.
|
|
in its training data.
|
|
|
-Details on the training procedure and data, as well as the intended use of the model can be found in the corresponding [model card](https://huggingface.co/CompVis/stable-diffusion).
|
|
|
|
|
-Research into the safe deployment of general text-to-image models is an ongoing effort. To prevent misuse and harm, we currently provide access to the checkpoints only for [academic research purposes upon request](https://stability.ai/academia-access-form).
|
|
|
|
|
-**This is an experiment in safe and community-driven publication of a capable and general text-to-image model. We are working on a public release with a more permissive license that also incorporates ethical considerations.***
|
|
|
|
|
|
|
+Details on the training procedure and data, as well as the intended use of the model can be found in the corresponding [model card](Stable_Diffusion_v1_Model_Card.md).*
|
|
|
|
|
|
|
|
-[Request access to Stable Diffusion v1 checkpoints for academic research](https://stability.ai/academia-access-form)
|
|
|
|
|
|
|
+The weights are available via [the CompVis organization at Hugging Face](https://huggingface.co/CompVis) under [a license which contains specific use-based restrictions to prevent misuse and harm as informed by the model card, but otherwise remains permissive](LICENSE). While commercial use is permitted under the terms of the license, **we do not recommend using the provided weights for services or products without additional safety mechanisms and considerations**, since there are [known limitations and biases](Stable_Diffusion_v1_Model_Card.md#limitations-and-bias) of the weights, and research on safe and ethical deployment of general text-to-image models is an ongoing effort. **The weights are research artifacts and should be treated as such.**
|
|
|
|
|
+
|
|
|
|
|
+[The CreativeML OpenRAIL M license](LICENSE) is an [Open RAIL M license](https://www.licenses.ai/blog/2022/8/18/naming-convention-of-responsible-ai-licenses), adapted from the work that [BigScience](https://bigscience.huggingface.co/) and [the RAIL Initiative](https://www.licenses.ai/) are jointly carrying in the area of responsible AI licensing. See also [the article about the BLOOM Open RAIL license](https://bigscience.huggingface.co/blog/the-bigscience-rail-license) on which our license is based.
|
|
|
|
|
|
|
|
### Weights
|
|
### Weights
|
|
|
|
|
|
|
|
-We currently provide three checkpoints, `sd-v1-1.ckpt`, `sd-v1-2.ckpt` and `sd-v1-3.ckpt`,
|
|
|
|
|
-which were trained as follows,
|
|
|
|
|
|
|
+We currently provide the following checkpoints:
|
|
|
|
|
|
|
|
- `sd-v1-1.ckpt`: 237k steps at resolution `256x256` on [laion2B-en](https://huggingface.co/datasets/laion/laion2B-en).
|
|
- `sd-v1-1.ckpt`: 237k steps at resolution `256x256` on [laion2B-en](https://huggingface.co/datasets/laion/laion2B-en).
|
|
|
194k steps at resolution `512x512` on [laion-high-resolution](https://huggingface.co/datasets/laion/laion-high-resolution) (170M examples from LAION-5B with resolution `>= 1024x1024`).
|
|
194k steps at resolution `512x512` on [laion-high-resolution](https://huggingface.co/datasets/laion/laion-high-resolution) (170M examples from LAION-5B with resolution `>= 1024x1024`).
|
|
|
- `sd-v1-2.ckpt`: Resumed from `sd-v1-1.ckpt`.
|
|
- `sd-v1-2.ckpt`: Resumed from `sd-v1-1.ckpt`.
|
|
|
- 515k steps at resolution `512x512` on "laion-improved-aesthetics" (a subset of laion2B-en,
|
|
|
|
|
-filtered to images with an original size `>= 512x512`, estimated aesthetics score `> 5.0`, and an estimated watermark probability `< 0.5`. The watermark estimate is from the LAION-5B metadata, the aesthetics score is estimated using an [improved aesthetics estimator](https://github.com/christophschuhmann/improved-aesthetic-predictor)).
|
|
|
|
|
-- `sd-v1-3.ckpt`: Resumed from `sd-v1-2.ckpt`. 195k steps at resolution `512x512` on "laion-improved-aesthetics" and 10\% dropping of the text-conditioning to improve [classifier-free guidance sampling](https://arxiv.org/abs/2207.12598).
|
|
|
|
|
|
|
+ 515k steps at resolution `512x512` on [laion-aesthetics v2 5+](https://laion.ai/blog/laion-aesthetics/) (a subset of laion2B-en with estimated aesthetics score `> 5.0`, and additionally
|
|
|
|
|
+filtered to images with an original size `>= 512x512`, and an estimated watermark probability `< 0.5`. The watermark estimate is from the [LAION-5B](https://laion.ai/blog/laion-5b/) metadata, the aesthetics score is estimated using the [LAION-Aesthetics Predictor V2](https://github.com/christophschuhmann/improved-aesthetic-predictor)).
|
|
|
|
|
+- `sd-v1-3.ckpt`: Resumed from `sd-v1-2.ckpt`. 195k steps at resolution `512x512` on "laion-aesthetics v2 5+" and 10\% dropping of the text-conditioning to improve [classifier-free guidance sampling](https://arxiv.org/abs/2207.12598).
|
|
|
|
|
+- `sd-v1-4.ckpt`: Resumed from `sd-v1-2.ckpt`. 225k steps at resolution `512x512` on "laion-aesthetics v2 5+" and 10\% dropping of the text-conditioning to improve [classifier-free guidance sampling](https://arxiv.org/abs/2207.12598).
|
|
|
|
|
|
|
|
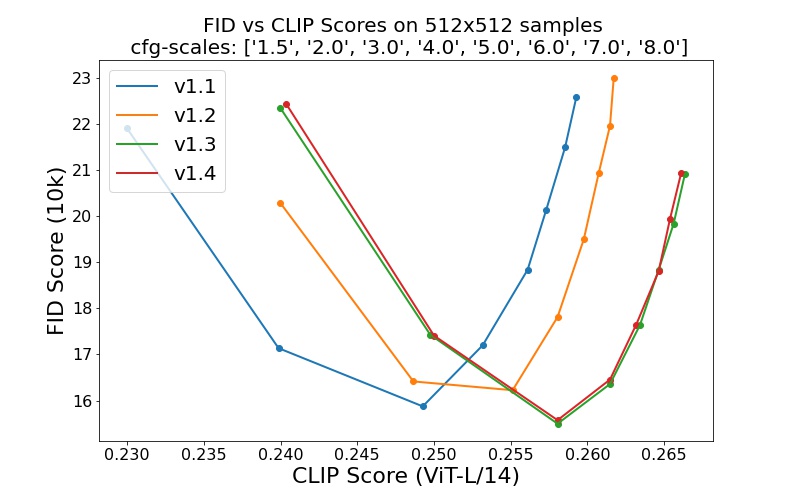
Evaluations with different classifier-free guidance scales (1.5, 2.0, 3.0, 4.0,
|
|
Evaluations with different classifier-free guidance scales (1.5, 2.0, 3.0, 4.0,
|
|
|
5.0, 6.0, 7.0, 8.0) and 50 PLMS sampling
|
|
5.0, 6.0, 7.0, 8.0) and 50 PLMS sampling
|
|
@@ -79,11 +77,20 @@ steps show the relative improvements of the checkpoints:
|
|
|

|
|

|
|
|
|
|
|
|
|
Stable Diffusion is a latent diffusion model conditioned on the (non-pooled) text embeddings of a CLIP ViT-L/14 text encoder.
|
|
Stable Diffusion is a latent diffusion model conditioned on the (non-pooled) text embeddings of a CLIP ViT-L/14 text encoder.
|
|
|
|
|
+We provide a [reference script for sampling](#reference-sampling-script), but
|
|
|
|
|
+there also exists a [diffusers integration](#diffusers-integration), which we
|
|
|
|
|
+expect to see more active community development.
|
|
|
|
|
+
|
|
|
|
|
+#### Reference Sampling Script
|
|
|
|
|
|
|
|
|
|
+We provide a reference sampling script, which incorporates
|
|
|
|
|
|
|
|
-#### Sampling Script
|
|
|
|
|
|
|
+- a [Safety Checker Module](https://github.com/CompVis/stable-diffusion/pull/36),
|
|
|
|
|
+ to reduce the probability of explicit outputs,
|
|
|
|
|
+- an [invisible watermarking](https://github.com/ShieldMnt/invisible-watermark)
|
|
|
|
|
+ of the outputs, to help viewers [identify the images as machine-generated](scripts/tests/test_watermark.py).
|
|
|
|
|
|
|
|
-After [obtaining the weights](#weights), link them
|
|
|
|
|
|
|
+After [obtaining the `stable-diffusion-v1-*-original` weights](#weights), link them
|
|
|
```
|
|
```
|
|
|
mkdir -p models/ldm/stable-diffusion-v1/
|
|
mkdir -p models/ldm/stable-diffusion-v1/
|
|
|
ln -s <path/to/model.ckpt> models/ldm/stable-diffusion-v1/model.ckpt
|
|
ln -s <path/to/model.ckpt> models/ldm/stable-diffusion-v1/model.ckpt
|
|
@@ -96,9 +103,11 @@ python scripts/txt2img.py --prompt "a photograph of an astronaut riding a horse"
|
|
|
By default, this uses a guidance scale of `--scale 7.5`, [Katherine Crowson's implementation](https://github.com/CompVis/latent-diffusion/pull/51) of the [PLMS](https://arxiv.org/abs/2202.09778) sampler,
|
|
By default, this uses a guidance scale of `--scale 7.5`, [Katherine Crowson's implementation](https://github.com/CompVis/latent-diffusion/pull/51) of the [PLMS](https://arxiv.org/abs/2202.09778) sampler,
|
|
|
and renders images of size 512x512 (which it was trained on) in 50 steps. All supported arguments are listed below (type `python scripts/txt2img.py --help`).
|
|
and renders images of size 512x512 (which it was trained on) in 50 steps. All supported arguments are listed below (type `python scripts/txt2img.py --help`).
|
|
|
|
|
|
|
|
|
|
+
|
|
|
```commandline
|
|
```commandline
|
|
|
-usage: txt2img.py [-h] [--prompt [PROMPT]] [--outdir [OUTDIR]] [--skip_grid] [--skip_save] [--ddim_steps DDIM_STEPS] [--plms] [--laion400m] [--fixed_code] [--ddim_eta DDIM_ETA] [--n_iter N_ITER] [--H H] [--W W] [--C C] [--f F] [--n_samples N_SAMPLES] [--n_rows N_ROWS]
|
|
|
|
|
- [--scale SCALE] [--from-file FROM_FILE] [--config CONFIG] [--ckpt CKPT] [--seed SEED] [--precision {full,autocast}]
|
|
|
|
|
|
|
+usage: txt2img.py [-h] [--prompt [PROMPT]] [--outdir [OUTDIR]] [--skip_grid] [--skip_save] [--ddim_steps DDIM_STEPS] [--plms] [--laion400m] [--fixed_code] [--ddim_eta DDIM_ETA]
|
|
|
|
|
+ [--n_iter N_ITER] [--H H] [--W W] [--C C] [--f F] [--n_samples N_SAMPLES] [--n_rows N_ROWS] [--scale SCALE] [--from-file FROM_FILE] [--config CONFIG] [--ckpt CKPT]
|
|
|
|
|
+ [--seed SEED] [--precision {full,autocast}]
|
|
|
|
|
|
|
|
optional arguments:
|
|
optional arguments:
|
|
|
-h, --help show this help message and exit
|
|
-h, --help show this help message and exit
|
|
@@ -128,7 +137,6 @@ optional arguments:
|
|
|
--seed SEED the seed (for reproducible sampling)
|
|
--seed SEED the seed (for reproducible sampling)
|
|
|
--precision {full,autocast}
|
|
--precision {full,autocast}
|
|
|
evaluate at this precision
|
|
evaluate at this precision
|
|
|
-
|
|
|
|
|
```
|
|
```
|
|
|
Note: The inference config for all v1 versions is designed to be used with EMA-only checkpoints.
|
|
Note: The inference config for all v1 versions is designed to be used with EMA-only checkpoints.
|
|
|
For this reason `use_ema=False` is set in the configuration, otherwise the code will try to switch from
|
|
For this reason `use_ema=False` is set in the configuration, otherwise the code will try to switch from
|
|
@@ -138,16 +146,16 @@ which contain both types of weights. For these, `use_ema=False` will load and us
|
|
|
|
|
|
|
|
#### Diffusers Integration
|
|
#### Diffusers Integration
|
|
|
|
|
|
|
|
-Another way to download and sample Stable Diffusion is by using the [diffusers library](https://github.com/huggingface/diffusers/tree/main#new--stable-diffusion-is-now-fully-compatible-with-diffusers)
|
|
|
|
|
|
|
+A simple way to download and sample Stable Diffusion is by using the [diffusers library](https://github.com/huggingface/diffusers/tree/main#new--stable-diffusion-is-now-fully-compatible-with-diffusers):
|
|
|
```py
|
|
```py
|
|
|
# make sure you're logged in with `huggingface-cli login`
|
|
# make sure you're logged in with `huggingface-cli login`
|
|
|
from torch import autocast
|
|
from torch import autocast
|
|
|
-from diffusers import StableDiffusionPipeline, LMSDiscreteScheduler
|
|
|
|
|
|
|
+from diffusers import StableDiffusionPipeline
|
|
|
|
|
|
|
|
pipe = StableDiffusionPipeline.from_pretrained(
|
|
pipe = StableDiffusionPipeline.from_pretrained(
|
|
|
- "CompVis/stable-diffusion-v1-3-diffusers",
|
|
|
|
|
|
|
+ "CompVis/stable-diffusion-v1-4",
|
|
|
use_auth_token=True
|
|
use_auth_token=True
|
|
|
-)
|
|
|
|
|
|
|
+).to("cuda")
|
|
|
|
|
|
|
|
prompt = "a photo of an astronaut riding a horse on mars"
|
|
prompt = "a photo of an astronaut riding a horse on mars"
|
|
|
with autocast("cuda"):
|
|
with autocast("cuda"):
|
|
@@ -157,7 +165,6 @@ image.save("astronaut_rides_horse.png")
|
|
|
```
|
|
```
|
|
|
|
|
|
|
|
|
|
|
|
|
-
|
|
|
|
|
### Image Modification with Stable Diffusion
|
|
### Image Modification with Stable Diffusion
|
|
|
|
|
|
|
|
By using a diffusion-denoising mechanism as first proposed by [SDEdit](https://arxiv.org/abs/2108.01073), the model can be used for different
|
|
By using a diffusion-denoising mechanism as first proposed by [SDEdit](https://arxiv.org/abs/2108.01073), the model can be used for different
|
|
@@ -203,7 +210,6 @@ Thanks for open-sourcing!
|
|
|
archivePrefix={arXiv},
|
|
archivePrefix={arXiv},
|
|
|
primaryClass={cs.CV}
|
|
primaryClass={cs.CV}
|
|
|
}
|
|
}
|
|
|
-
|
|
|
|
|
```
|
|
```
|
|
|
|
|
|
|
|
|
|
|